


[ad_1]
As machine studying practitioners, we make investments vital effort and time to enhance our fashions. You normally do it iteratively and experimentally by repeatedly altering your mannequin, operating an experiment, and analyzing the outcomes, then deciding whether or not the latest mannequin change was optimistic and needs to be stored or discarded.
Modifications in every iteration would possibly contain, for instance, altering a worth for a hyperparameter, including a brand new enter function, altering the underlying machine studying mannequin (for instance, by utilizing gradient boosting classification as an alternative of random forest classification), attempting a brand new heuristic, or attempting a completely new method.
Experimentation cycles could cause a substantial amount of confusion. It’s simple to get misplaced, forgetting what modifications you made within the latest experiments and whether or not the most recent outcomes are certainly higher than earlier than. A single experiment can take hours and even longer to finish. So, you attempt to optimize your time and execute a number of experiments concurrently. This makes it even much less manageable, and the confusion will get even worse.
On this weblog, I share classes and good practices that I discovered in my latest machine studying tasks. Though I name it a “Do it your self” method, some would possibly name it “The caveman means.” I’m absolutely conscious that these days there are numerous experiment monitoring and administration platforms, however it isn’t all the time attainable or handy to make use of them. Some platforms require that you simply execute your experiments on their platform. Generally you possibly can’t share delicate data exterior of your group, not simply the information units but in addition outcomes and code. Many platforms require a paid subscription, which will also be an issue in some circumstances. Generally you simply need full management of your experiment administration method and information.
The next practices are simple to implement and don’t require extra tooling. They’re principally appropriate for small to medium machine studying tasks with a single researcher or a small staff. Many of the artifacts are saved regionally, and variations could be required if you wish to use a shared storage. As a seasoned developer of manufacturing programs, I’m conscious that just a few of the information could be thought of ‘code-smells’ or unhealthy practices with regards to conventional improvement of such programs. Nevertheless, I consider that they’ve their place and are justified for short-term analysis tasks. I wish to emphasize that the information mirror my private journey and viewpoint, and never essentially any official views or practices.
Monitoring what you probably did
1. Use supply management
It goes with out saying that your experimentation code needs to be source-controlled. That mentioned, when utilizing trendy interactive environments like Jupyter Notebooks, it’s simple to be tempted to make fast experiments on-the-fly with out committing modifications to Git or another source-control system. Attempt to keep away from that as a lot as attainable. Possibly it’s only me, however I want utilizing a good IDE and plain Python scripts to run experiments. I’d use a pocket book for the preliminary information exploration, however quickly after an preliminary mannequin skeleton is prepared, I swap to a full-fledged Python script, which additionally permits debugging, refactoring, and so forth.
2. Use identifiable experiments
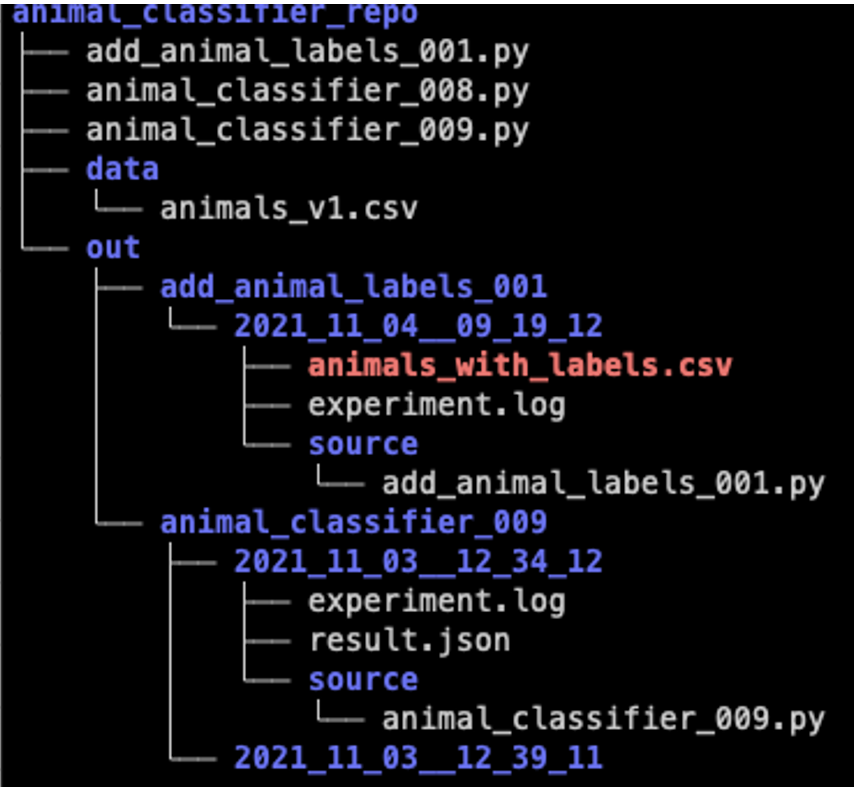
However what? Supply management isn’t sufficient. Even when every thing is source-controlled, it may be tedious to browse the repository’s historical past and to grasp what supply was used for operating an experiment 12 days in the past. I wish to recommend an extra observe that I name “Copy on Write.” Duplicate your newest experiment script file or folder earlier than every new experiment and make the modifications on the brand new file. Make your experiments identifiable by including a sequential quantity to every experiment within the supply file title. For instance, animal_classifier_009.py for experiment #9. And, sure, this works additionally for notebooks: you possibly can create a pocket book per experiment. Which means that you want solely a file diff to grasp what modified between experiment #9 and #12. Storage is affordable, and the dimensions of your whole experiments’ supply code might be dwarfed by the dimensions of your information.
3. Automated supply code snapshots
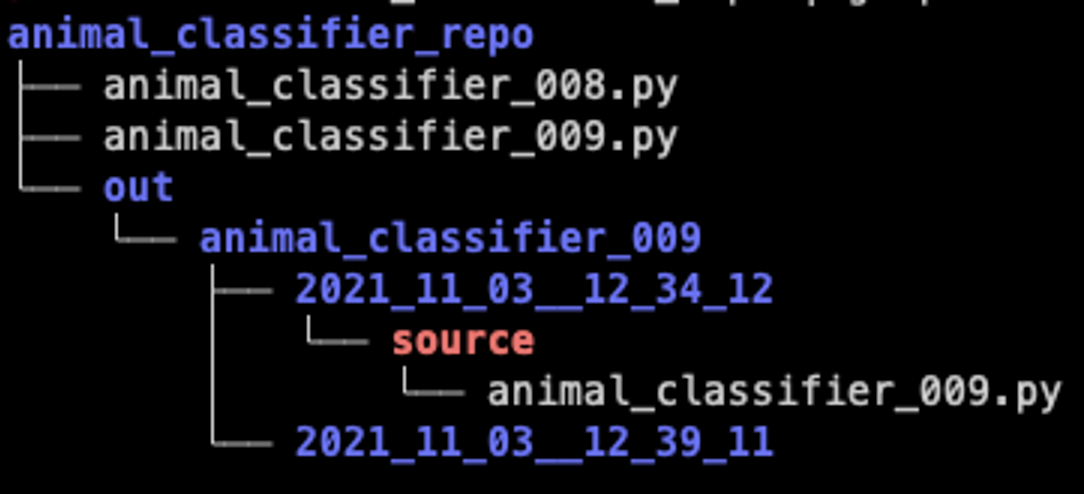
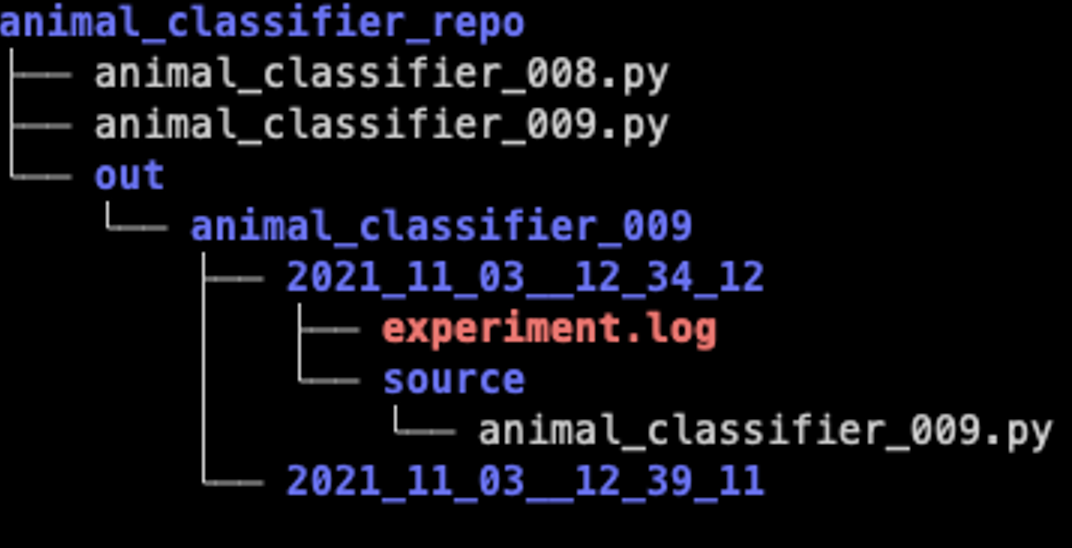
One other tip is to robotically take a snapshot of your experiment code for every run. You are able to do this simply contained in the experiment script itself, by bootstrapping code that copies the supply file or folder to a listing with the experiment begin timestamp in its title. This makes your experiment monitoring technique strong even should you had been tempted to make on-the-fly experiments with out committing or copy-on-write above (that’s, “Soiled Commits”). For instance, when operating the experiment animal_classifier_009.py, we create the folder out/animal_classifier_009/2021_11_03–12_34_12/supply and retailer a snapshot of the related supply code inside.
4. Deal with experiment configuration parameters the identical as supply code
Keep away from tuning experiment parameters or hyperparameters within the command-line, surroundings variables, or another exterior means that’s not a part of the supply code. In any other case, you threat shedding traceability for modifications should you overlook to log the parameter values.
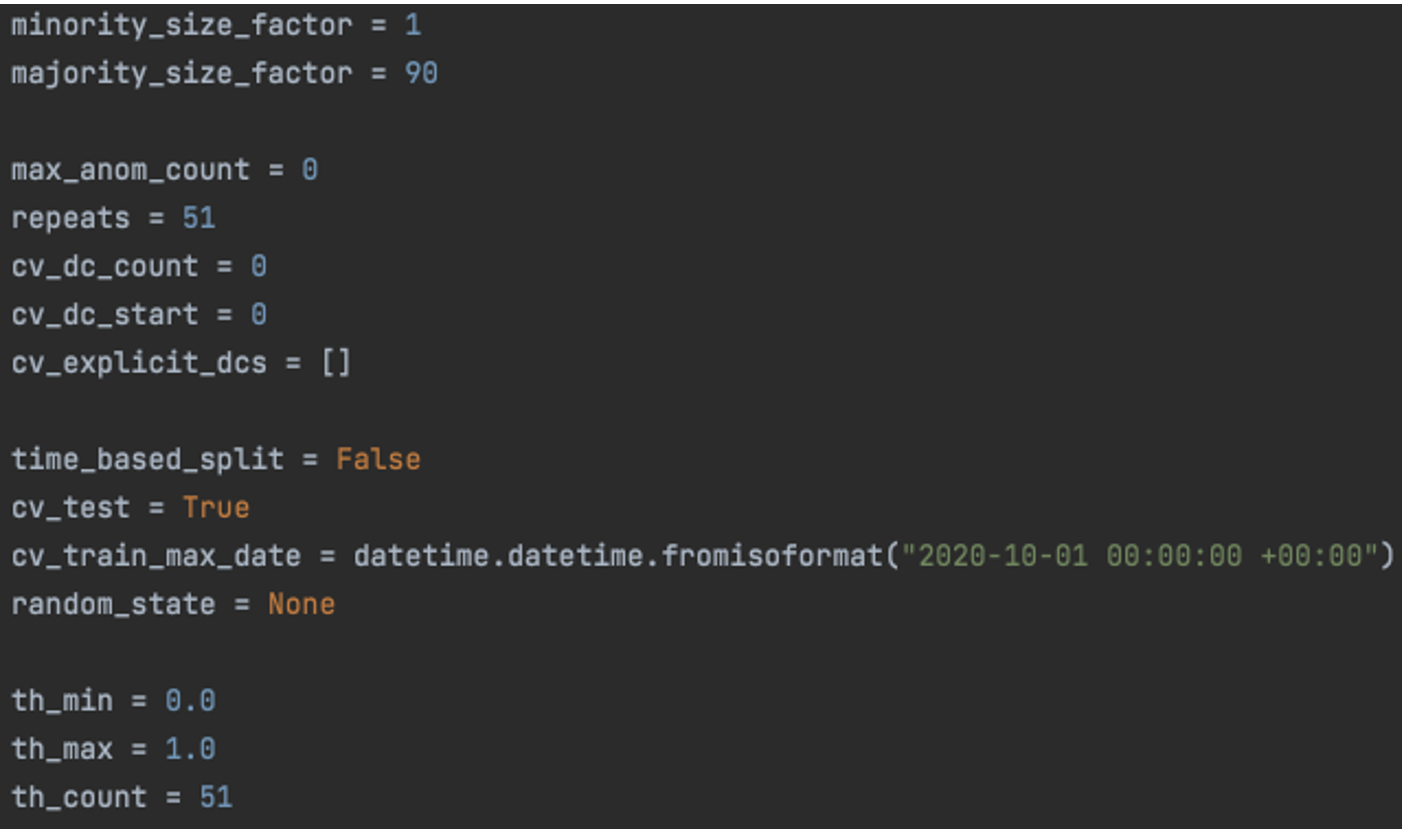
To embed experiment configuration, you should use both plain Python, dictionary, JSON, YAML, or another format that you simply discover handy. Simply ensure you commit the configuration recordsdata along with the experiment code. Does hardcoding stuff look like a code odor? Nicely, not on this case. If you happen to do settle for exterior runtime parameters, be sure you log their values!
Every configuration changeset needs to be handled as a novel experiment. It needs to be dedicated to supply management, configuration recordsdata shall be included within the experiment code snapshot, and it ought to get its personal experiment ID.
The benefit of embedding configuration as a part of the supply management is you can make certain you reproduced the identical experiment simply by operating this system file, not different shifting elements that you simply would possibly overlook to set.
5. Monitor experiment evolution tree
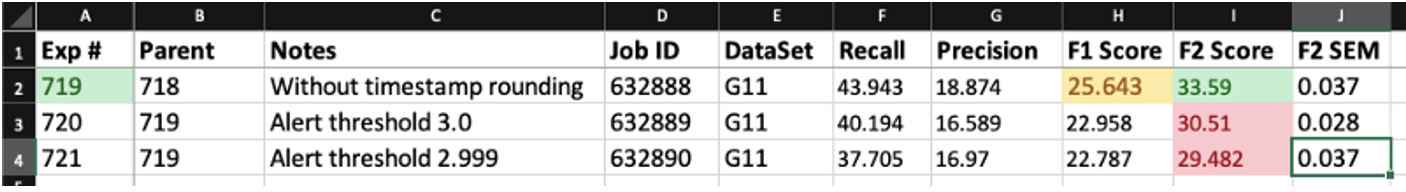
One of many issues that helps me loads is to maintain monitor of the reference experiment – the predecessor baseline that I’m attempting to enhance upon. That is simple to do in case your experiments are identifiable. Whenever you create a brand new experiment by duplicating, hold monitor of the guardian experiment ID plus the essence of what you’ve tried on this experiment that’s completely different from the guardian. This data helps you rapidly recall what you probably did, with out counting on code diffs. It additionally makes it attainable to traverse again within the experiment tree and rapidly get the total image. You’ll be able to monitor the guardian experiment contained in the supply code itself as a code remark.
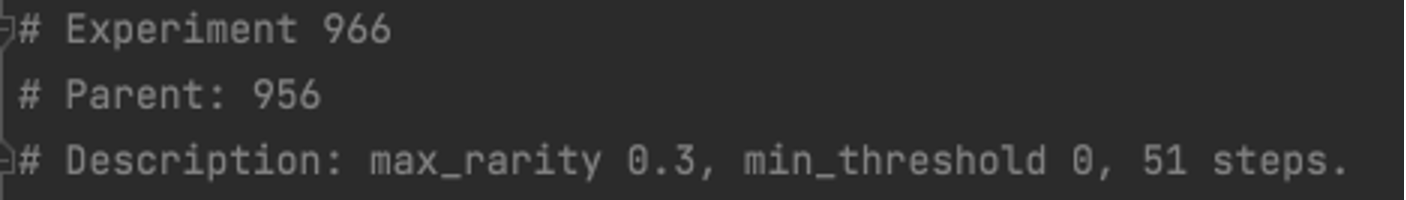
Nevertheless, this would possibly trigger an issue should you overlook to replace the notes earlier than operating the experiment. I recommend a easy spreadsheet.
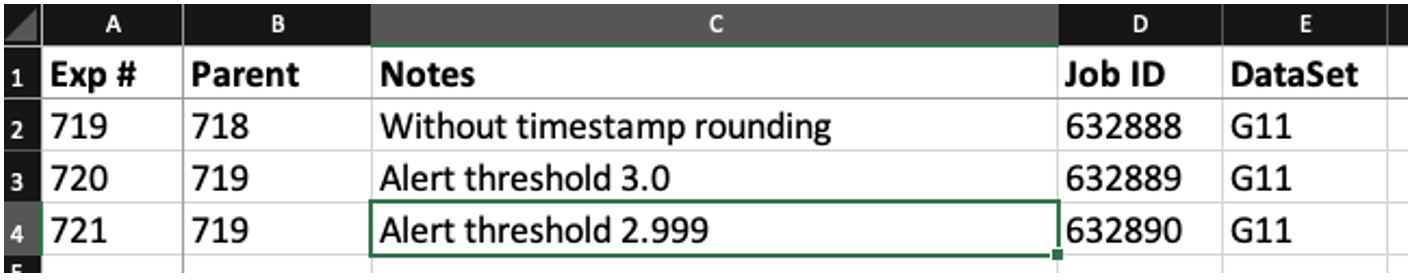
Within the spreadsheet, you can too seize different data or parameters that you simply used on this experiment, and, after all, experiment outcomes. However I’ll contact on that later.
Monitoring what occurred
6. Preserve console/log output
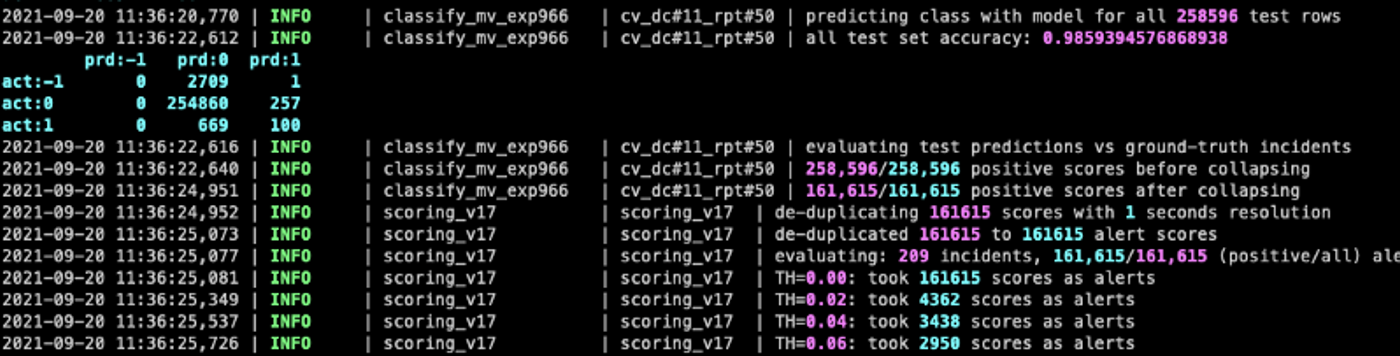
Be beneficiant with logging statements that monitor what occurred within the experiment. Monitor many metrics and varieties of data, like information set measurement, label depend, date ranges, experiment execution time, and extra. These may help you detect points and errors. Be paranoid! Each unexplained change in a metric could possibly be attributable to some mistake within the experiment setup. This helps you perceive its root trigger.
Any experiment output needs to be continued. I like to recommend utilizing the Python logging module as an alternative of plain console prints to be able to redirect logging messages to each stdout and a file. As well as, you get timestamps for every log occasion, which may help you to resolve efficiency bottlenecks. You’ll be able to retailer the log file below a folder that’s correlated to the experiment ID and execution time.
7. Monitor experiment outcomes
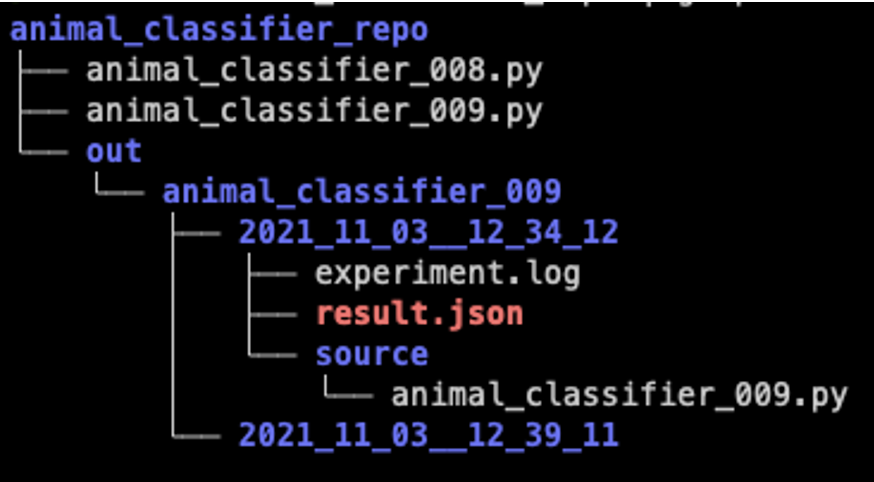
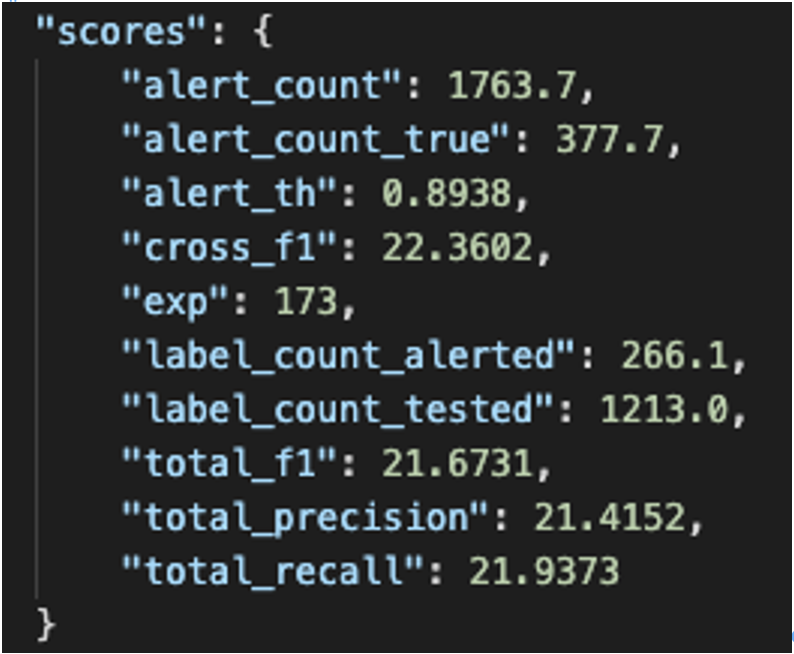
You would possibly use a number of metrics that quantify the standard of your mannequin. For instance, accuracy, precision, recall, F-score, and AUC. Just be sure you monitor these in a separate, structured outcomes file you can robotically course of later to indicate charts and extra.
It’s additionally a good suggestion to trace your most essential metrics within the experiment spreadsheet to be able to get the total image rapidly and resolve on future instructions. I like utilizing colours to mark outcomes (inexperienced=improved, pink=received worse, yellow=undecided).
8. Do a number of repeats for stochastic fashions
You need your outcomes to be reproducible, however nonetheless keep away from getting deceptive outcomes because of likelihood. The answer lies in repetition with random seeds. Keep away from utilizing fastened random seeds in case your fashions are stochastic. The identical applies when shuffling, down sampling, or any operation that comprises a random component. For instance, should you use scikit-learn, all the time run your fashions with random_state=none. Carry out a number of repeats in every experiment, and common the outcomes of your optimization goal metrics in all repeats so that you simply get steady numbers. You should use metrics like Customary Error of the Imply (SEM) to estimate how shut your repeats’ imply is to the true imply of the inhabitants (should you may run an infinite variety of repeats). The SEM metric worth decreases as you enhance the variety of repeats. This helps you acquire confidence and perceive in case your newest outcomes are certainly higher or if it was simply luck, and you need to enhance the repeat depend to make sure. Usually, when your mannequin will get extra mature/steady, your optimizations will most likely have a smaller impression, and also you would possibly want to extend the repeat depend.
9. Monitor enter information units
Keep in mind to model and title the information units which can be used as enter to your mannequin with the model identifier. Enter information units are typically massive, so I wouldn’t advocate duplicating them into every experiment’s monitoring folder. Simply be sure to log the file names/URIs of the enter information units that you simply used. You may also discover these file names within the supply code snapshots for the related experiment. You’ll be able to add one other security layer right here by computing and logging a hash/digest of the contents of every enter information set. Log additionally the essential traits of the information, akin to its dimensions and pattern counts for every class.
10. Keep away from or monitor intermediate information units
A few of your code would possibly carry out heavy preprocessing of information units. This may typically take a very long time, so that you would possibly do it as soon as after which use the output in later steps. In case your preprocessing has a stochastic nature, (shuffling, prepare/take a look at splitting, and so forth), attempt to keep away from creating intermediate information units except the processing can actually save numerous experiment time. In any other case, you might need an inherent bias in your information, just like when utilizing a hard and fast seed. As an alternative, you possibly can put money into optimizing the execution time of the preprocessing steps.
If you happen to do generate intermediate information units, deal with the supply code that you simply wrote for that objective similar to a standard experiment by utilizing the practices described to this point. Use model numbers for the supply file, monitor the supply code, and monitor the logs. It’s a good suggestion to avoid wasting the output intermediate information units within the out folder of every experiment. This makes the information units inherently identifiable.
Abstract
In brief, experiment administration is crucial and fairly simple to do should you undertake some easy strategies. Irrespective of whether or not you do it your self or use an experiment administration platform, simply do it!
[ad_2]

