


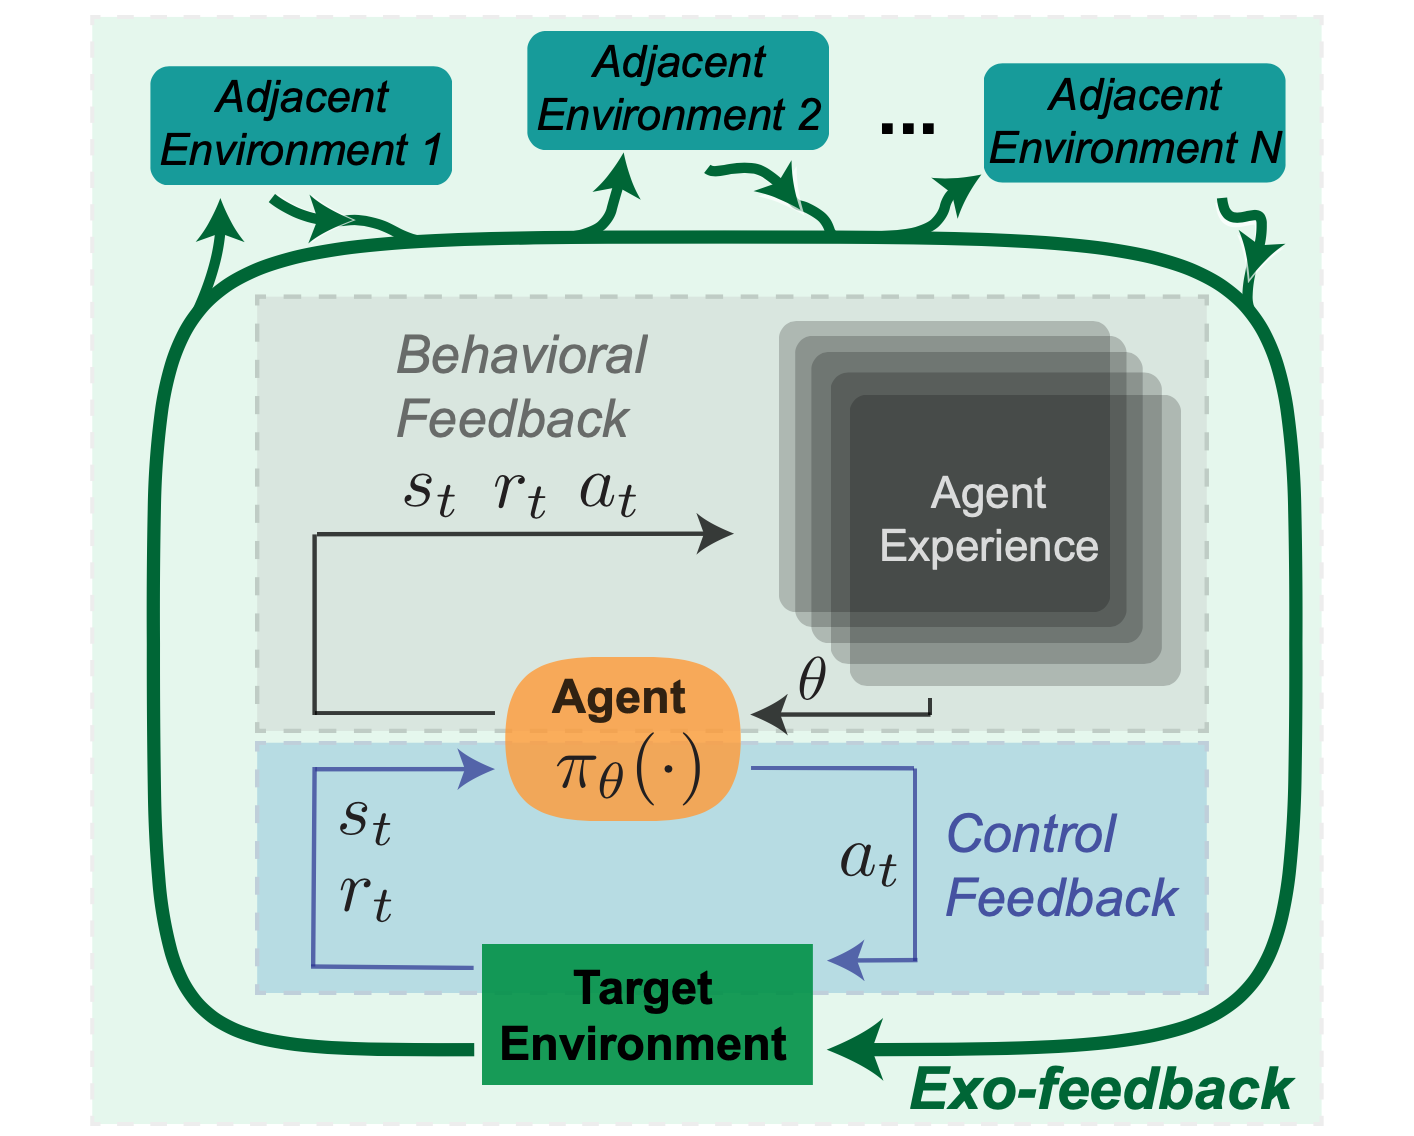
[ad_1]
Deep reinforcement studying (DRL) is transitioning from a analysis subject centered on sport taking part in to a know-how with real-world functions. Notable examples embody DeepMind’s work on controlling a nuclear reactor or on enhancing Youtube video compression, or Tesla trying to make use of a way impressed by MuZero for autonomous car conduct planning. However the thrilling potential for actual world functions of RL also needs to include a wholesome dose of warning – for instance RL insurance policies are well-known to be susceptible to exploitation, and strategies for secure and sturdy coverage growth are an lively space of analysis.
Similtaneously the emergence of highly effective RL methods in the true world, the general public and researchers are expressing an elevated urge for food for honest, aligned, and secure machine studying methods. The main focus of those analysis efforts to this point has been to account for shortcomings of datasets or supervised studying practices that may hurt people. Nevertheless the distinctive potential of RL methods to leverage temporal suggestions in studying complicates the kinds of dangers and security issues that may come up.
This submit expands on our current whitepaper and analysis paper, the place we goal as an instance the completely different modalities harms can take when augmented with the temporal axis of RL. To fight these novel societal dangers, we additionally suggest a brand new type of documentation for dynamic Machine Studying methods which goals to evaluate and monitor these dangers each earlier than and after deployment.
Reinforcement studying methods are sometimes spotlighted for his or her potential to behave in an setting, somewhat than passively make predictions. Different supervised machine studying methods, equivalent to pc imaginative and prescient, eat knowledge and return a prediction that can be utilized by some resolution making rule. In distinction, the attraction of RL is in its potential to not solely (a) straight mannequin the influence of actions, but additionally to (b) enhance coverage efficiency routinely. These key properties of appearing upon an setting, and studying inside that setting might be understood as by contemplating the various kinds of suggestions that come into play when an RL agent acts inside an setting. We classify these suggestions types in a taxonomy of (1) Management, (2) Behavioral, and (3) Exogenous suggestions. The primary two notions of suggestions, Management and Behavioral, are straight inside the formal mathematical definition of an RL agent whereas Exogenous suggestions is induced because the agent interacts with the broader world.
1. Management Suggestions
First is management suggestions – within the management methods engineering sense – the place the motion taken depends upon the present measurements of the state of the system. RL brokers select actions primarily based on an noticed state in line with a coverage, which generates environmental suggestions. For instance, a thermostat activates a furnace in line with the present temperature measurement. Management suggestions provides an agent the power to react to unexpected occasions (e.g. a sudden snap of chilly climate) autonomously.
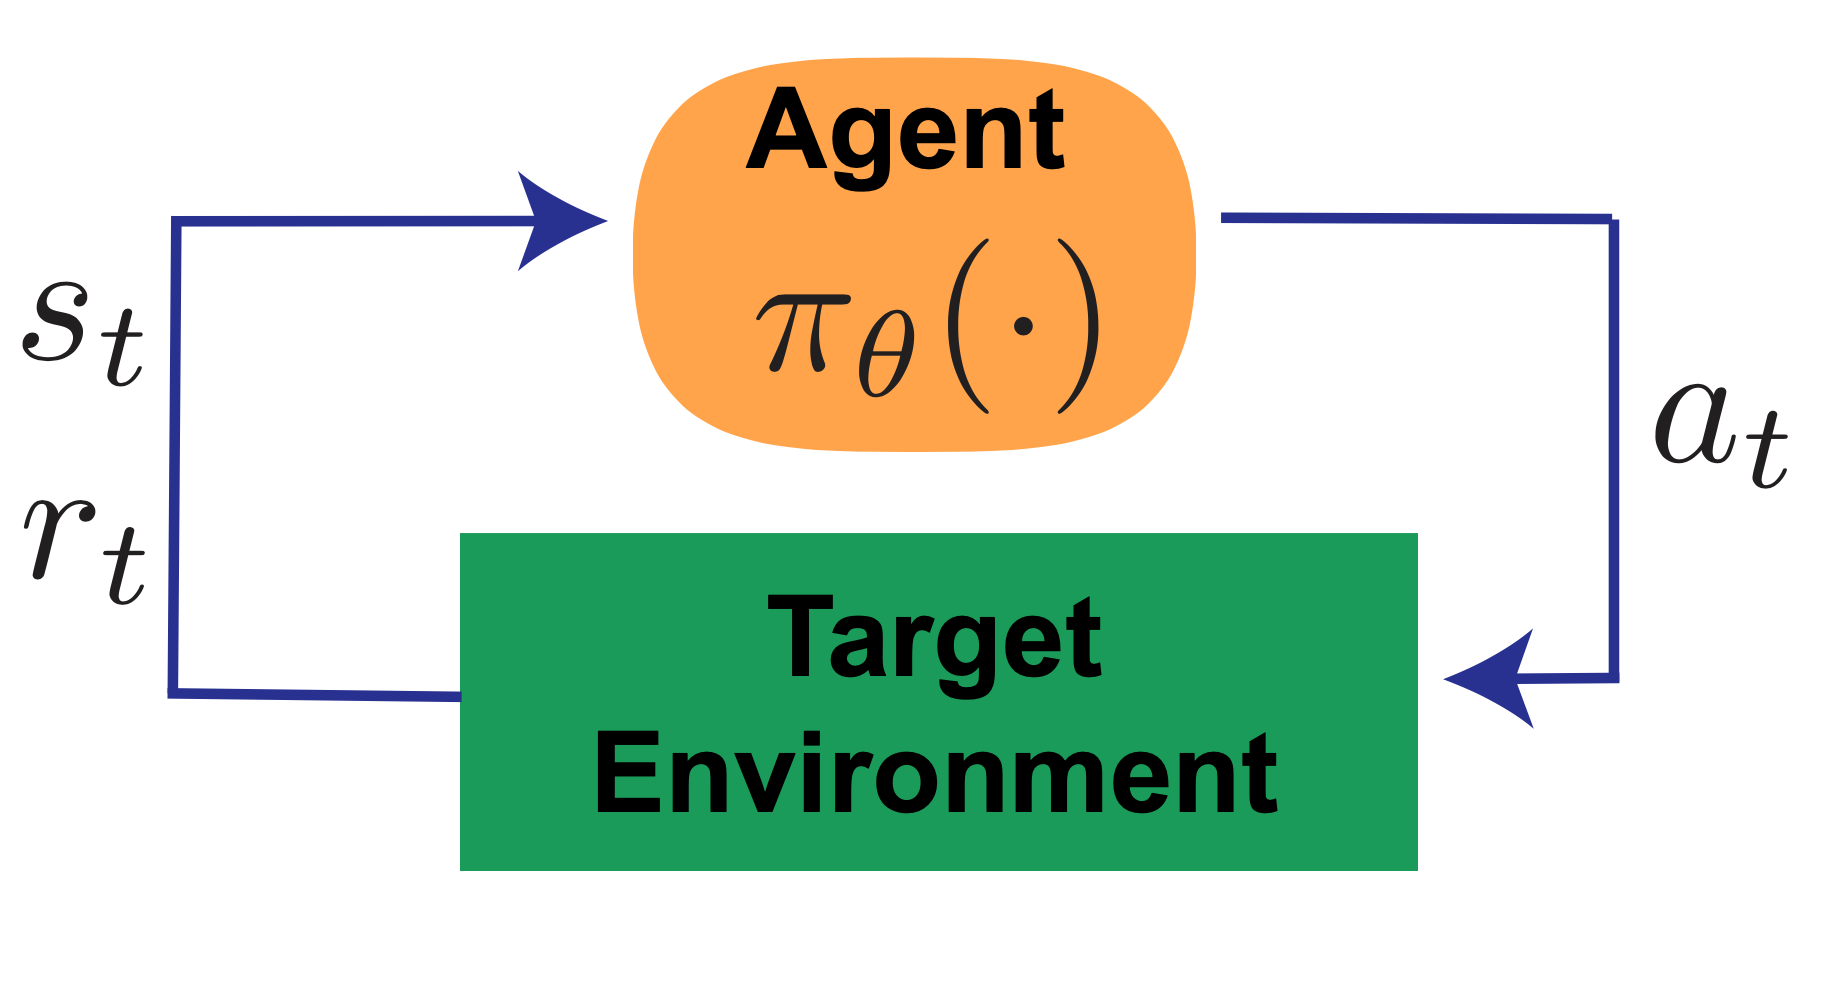
Determine 1: Management Suggestions.
2. Behavioral Suggestions
Subsequent in our taxonomy of RL suggestions is ‘behavioral suggestions’: the trial and error studying that permits an agent to enhance its coverage via interplay with the setting. This might be thought of the defining function of RL, as in comparison with e.g. ‘classical’ management principle. Insurance policies in RL might be outlined by a set of parameters that decide the actions the agent takes sooner or later. As a result of these parameters are up to date via behavioral suggestions, these are literally a mirrored image of the information collected from executions of previous coverage variations. RL brokers are usually not totally ‘memoryless’ on this respect–the present coverage depends upon saved expertise, and impacts newly collected knowledge, which in flip impacts future variations of the agent. To proceed the thermostat instance – a ‘sensible house’ thermostat would possibly analyze historic temperature measurements and adapt its management parameters in accordance with seasonal shifts in temperature, for example to have a extra aggressive management scheme throughout winter months.
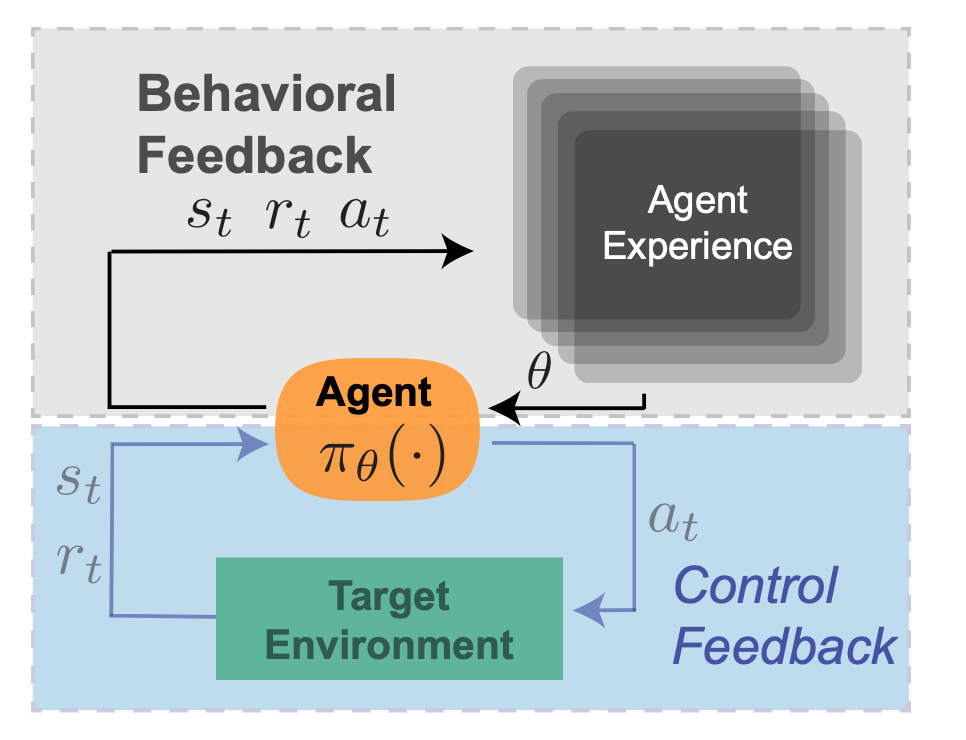
Determine 2: Behavioral Suggestions.
3. Exogenous Suggestions
Lastly, we will take into account a 3rd type of suggestions exterior to the desired RL setting, which we name Exogenous (or ‘exo’) suggestions. Whereas RL benchmarking duties could also be static environments, each motion in the true world impacts the dynamics of each the goal deployment setting, in addition to adjoining environments. For instance, a information advice system that’s optimized for clickthrough might change the best way editors write headlines in direction of attention-grabbing clickbait. On this RL formulation, the set of articles to be beneficial can be thought of a part of the setting and anticipated to stay static, however publicity incentives trigger a shift over time.
To proceed the thermostat instance, as a ‘sensible thermostat’ continues to adapt its conduct over time, the conduct of different adjoining methods in a family would possibly change in response – for example different home equipment would possibly eat extra electrical energy as a consequence of elevated warmth ranges, which might influence electrical energy prices. Family occupants may additionally change their clothes and conduct patterns as a consequence of completely different temperature profiles throughout the day. In flip, these secondary results might additionally affect the temperature which the thermostat displays, resulting in an extended timescale suggestions loop.
Unfavourable prices of those exterior results won’t be specified within the agent-centric reward operate, leaving these exterior environments to be manipulated or exploited. Exo-feedback is by definition troublesome for a designer to foretell. As an alternative, we suggest that it ought to be addressed by documenting the evolution of the agent, the focused setting, and adjoining environments.
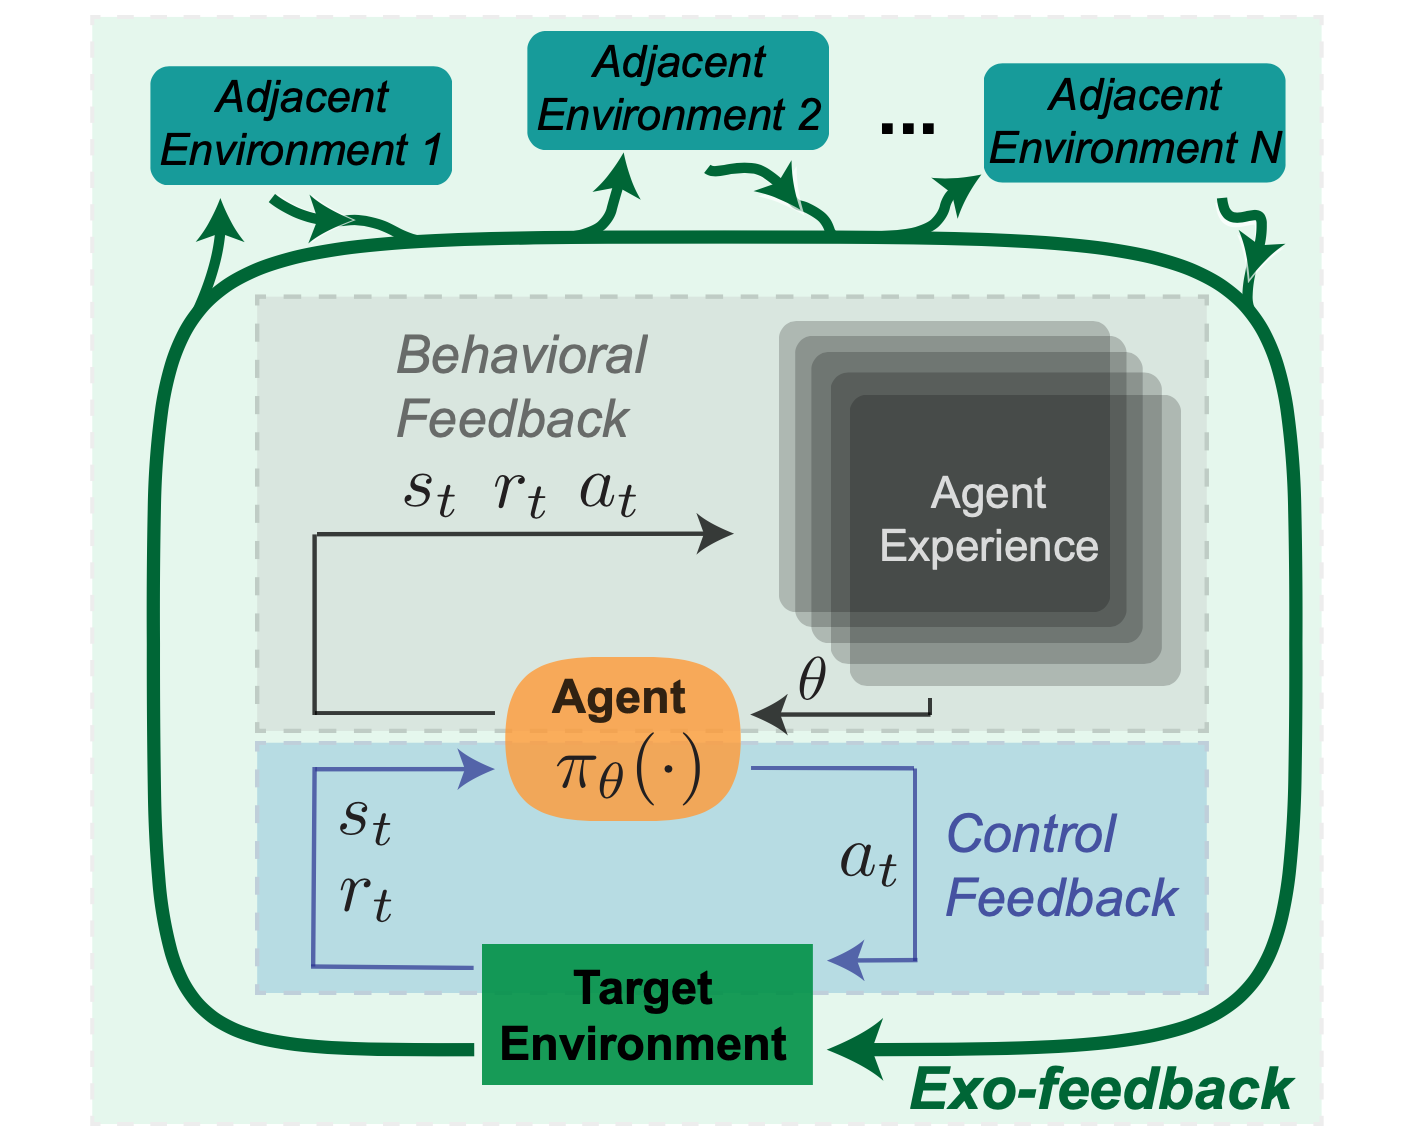
Determine 3: Exogenous (exo) Suggestions.
Let’s take into account how two key properties can result in failure modes particular to RL methods: direct motion choice (by way of management suggestions) and autonomous knowledge assortment (by way of behavioral suggestions).
First is decision-time security. One present apply in RL analysis to create secure choices is to enhance the agent’s reward operate with a penalty time period for sure dangerous or undesirable states and actions. For instance, in a robotics area we’d penalize sure actions (equivalent to extraordinarily giant torques) or state-action tuples (equivalent to carrying a glass of water over delicate tools). Nevertheless it’s troublesome to anticipate the place on a pathway an agent might encounter a vital motion, such that failure would lead to an unsafe occasion. This facet of how reward features work together with optimizers is very problematic for deep studying methods, the place numerical ensures are difficult.
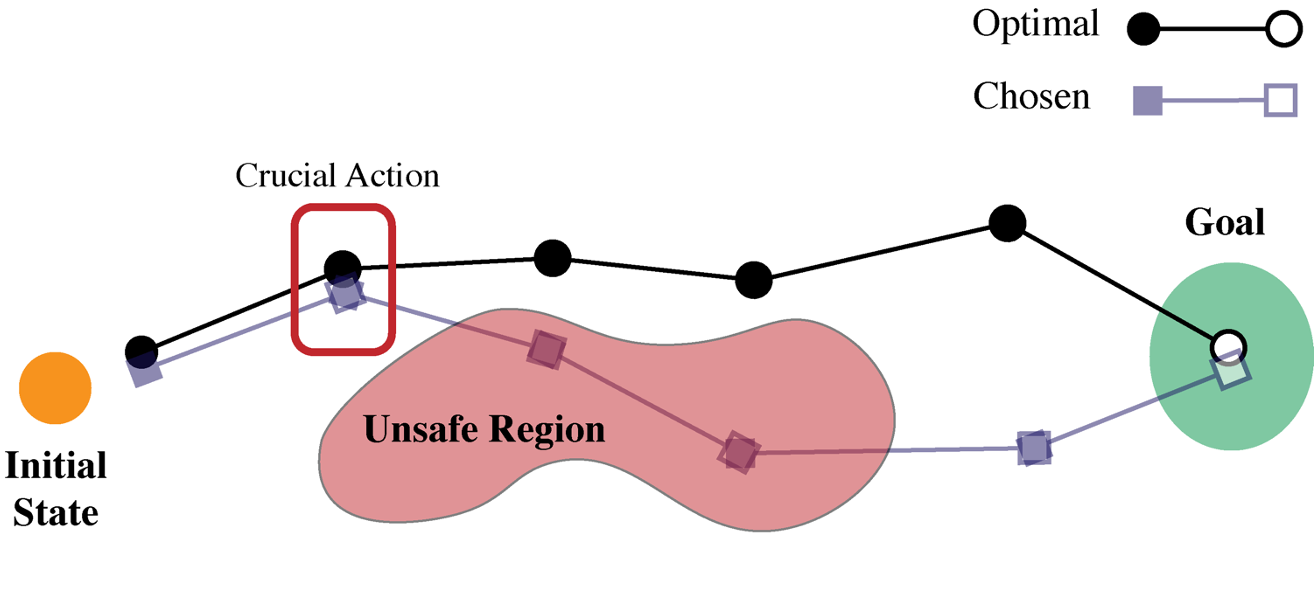
Determine 4: Choice time failure illustration.
As an RL agent collects new knowledge and the coverage adapts, there’s a advanced interaction between present parameters, saved knowledge, and the setting that governs evolution of the system. Altering any one in all these three sources of knowledge will change the long run conduct of the agent, and furthermore these three parts are deeply intertwined. This uncertainty makes it troublesome to again out the reason for failures or successes.
In domains the place many behaviors can presumably be expressed, the RL specification leaves plenty of elements constraining conduct unsaid. For a robotic studying locomotion over an uneven setting, it could be helpful to know what alerts within the system point out it’s going to study to search out a neater route somewhat than a extra advanced gait. In advanced conditions with much less well-defined reward features, these supposed or unintended behaviors will embody a much wider vary of capabilities, which can or might not have been accounted for by the designer.
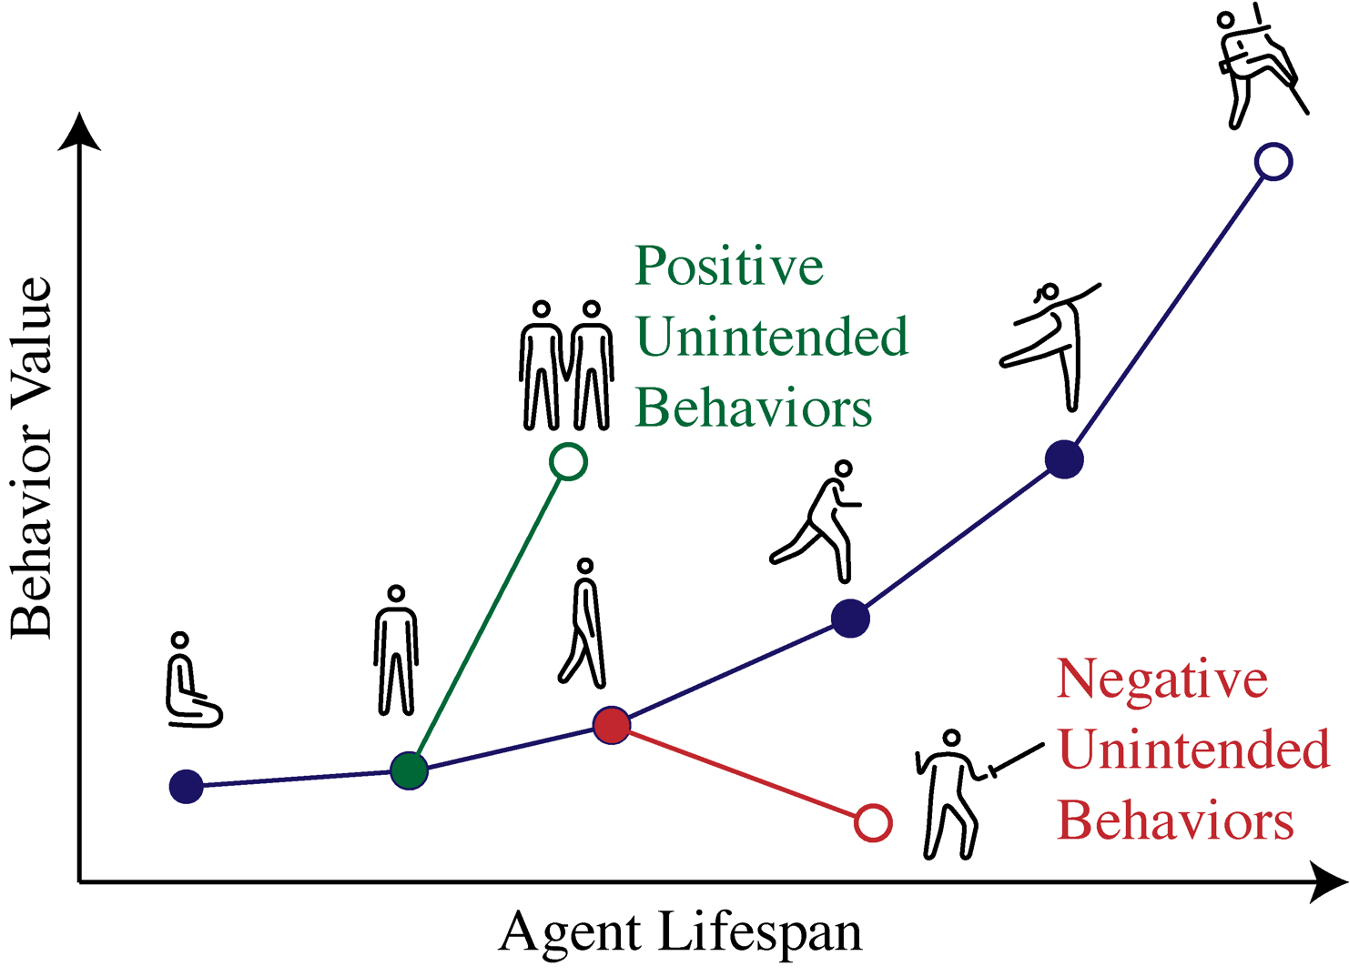
Determine 5: Habits estimation failure illustration.
Whereas these failure modes are intently associated to regulate and behavioral suggestions, Exo-feedback doesn’t map as clearly to at least one kind of error and introduces dangers that don’t match into easy classes. Understanding exo-feedback requires that stakeholders within the broader communities (machine studying, utility domains, sociology, and so on.) work collectively on actual world RL deployments.
Right here, we focus on 4 kinds of design decisions an RL designer should make, and the way these decisions can have an effect upon the socio-technical failures that an agent would possibly exhibit as soon as deployed.
Scoping the Horizon
Figuring out the timescale on which aRL agent can plan impacts the doable and precise conduct of that agent. Within the lab, it might be widespread to tune the horizon size till the specified conduct is achieved. However in actual world methods, optimizations will externalize prices relying on the outlined horizon. For instance, an RL agent controlling an autonomous car could have very completely different targets and behaviors if the duty is to remain in a lane, navigate a contested intersection, or route throughout a metropolis to a vacation spot. That is true even when the target (e.g. “reduce journey time”) stays the identical.
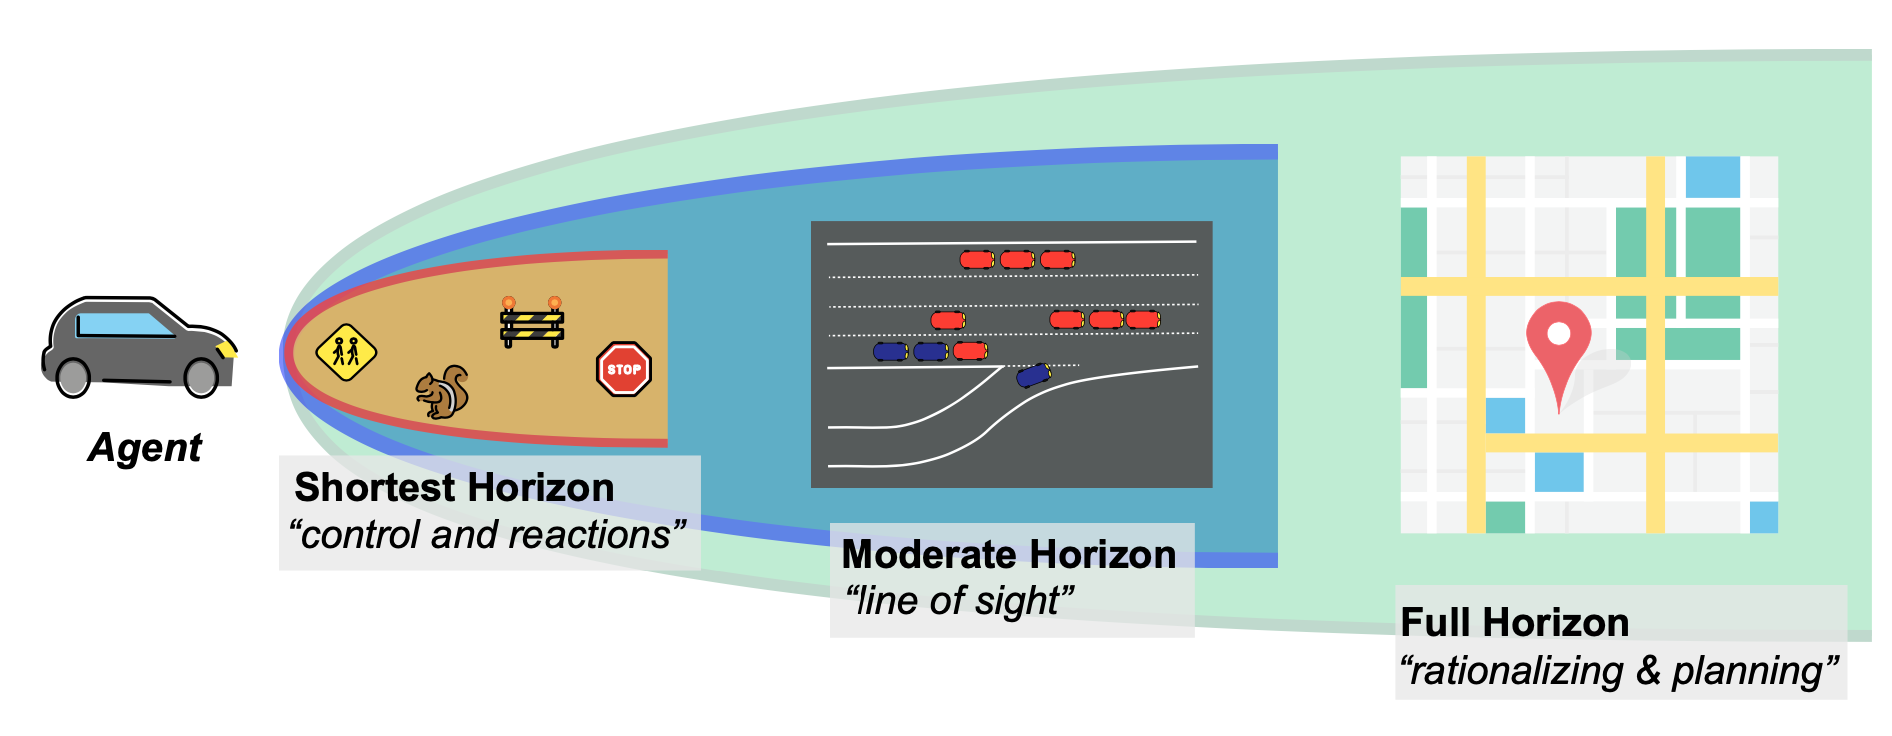
Determine 6: Scoping the horizon instance with an autonomous car.
Defining Rewards
A second design alternative is that of really specifying the reward operate to be maximized. This instantly raises the well-known threat of RL methods, reward hacking, the place the designer and agent negotiate behaviors primarily based on specified reward features. In a deployed RL system, this typically leads to surprising exploitative conduct – from weird online game brokers to inflicting errors in robotics simulators. For instance, if an agent is offered with the issue of navigating a maze to achieve the far facet, a mis-specified reward would possibly outcome within the agent avoiding the duty completely to attenuate the time taken.
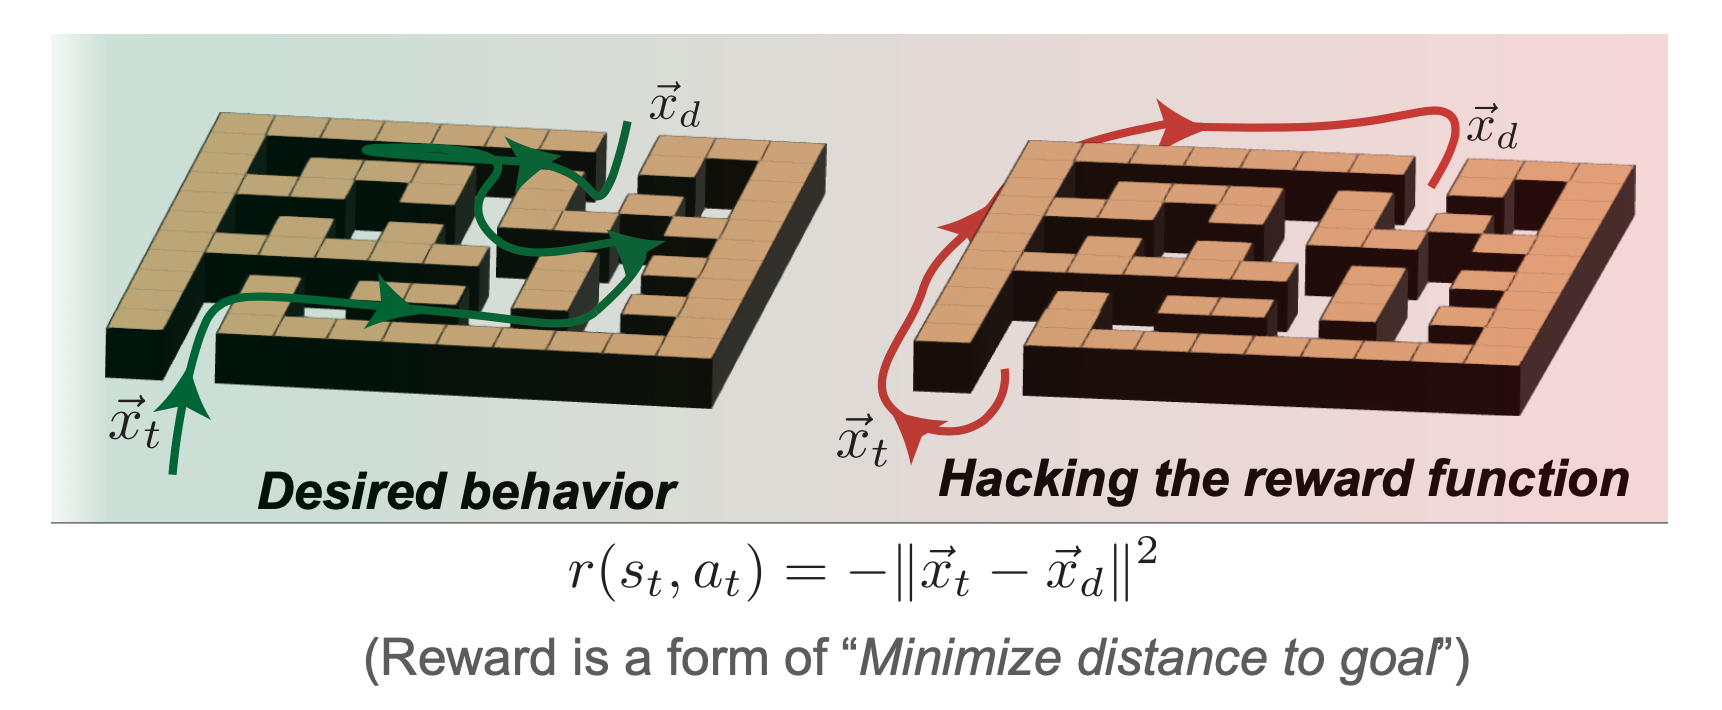
Determine 7: Defining rewards instance with maze navigation.
Pruning Info
A typical apply in RL analysis is to redefine the setting to suit one’s wants – RL designers make quite a few express and implicit assumptions to mannequin duties in a method that makes them amenable to digital RL brokers. In extremely structured domains, equivalent to video video games, this may be somewhat benign.Nevertheless, in the true world redefining the setting quantities to altering the methods data can circulate between the world and the RL agent. This will dramatically change the that means of the reward operate and offload threat to exterior methods. For instance, an autonomous car with sensors centered solely on the highway floor shifts the burden from AV designers to pedestrians. On this case, the designer is pruning out details about the encircling setting that’s truly essential to robustly secure integration inside society.
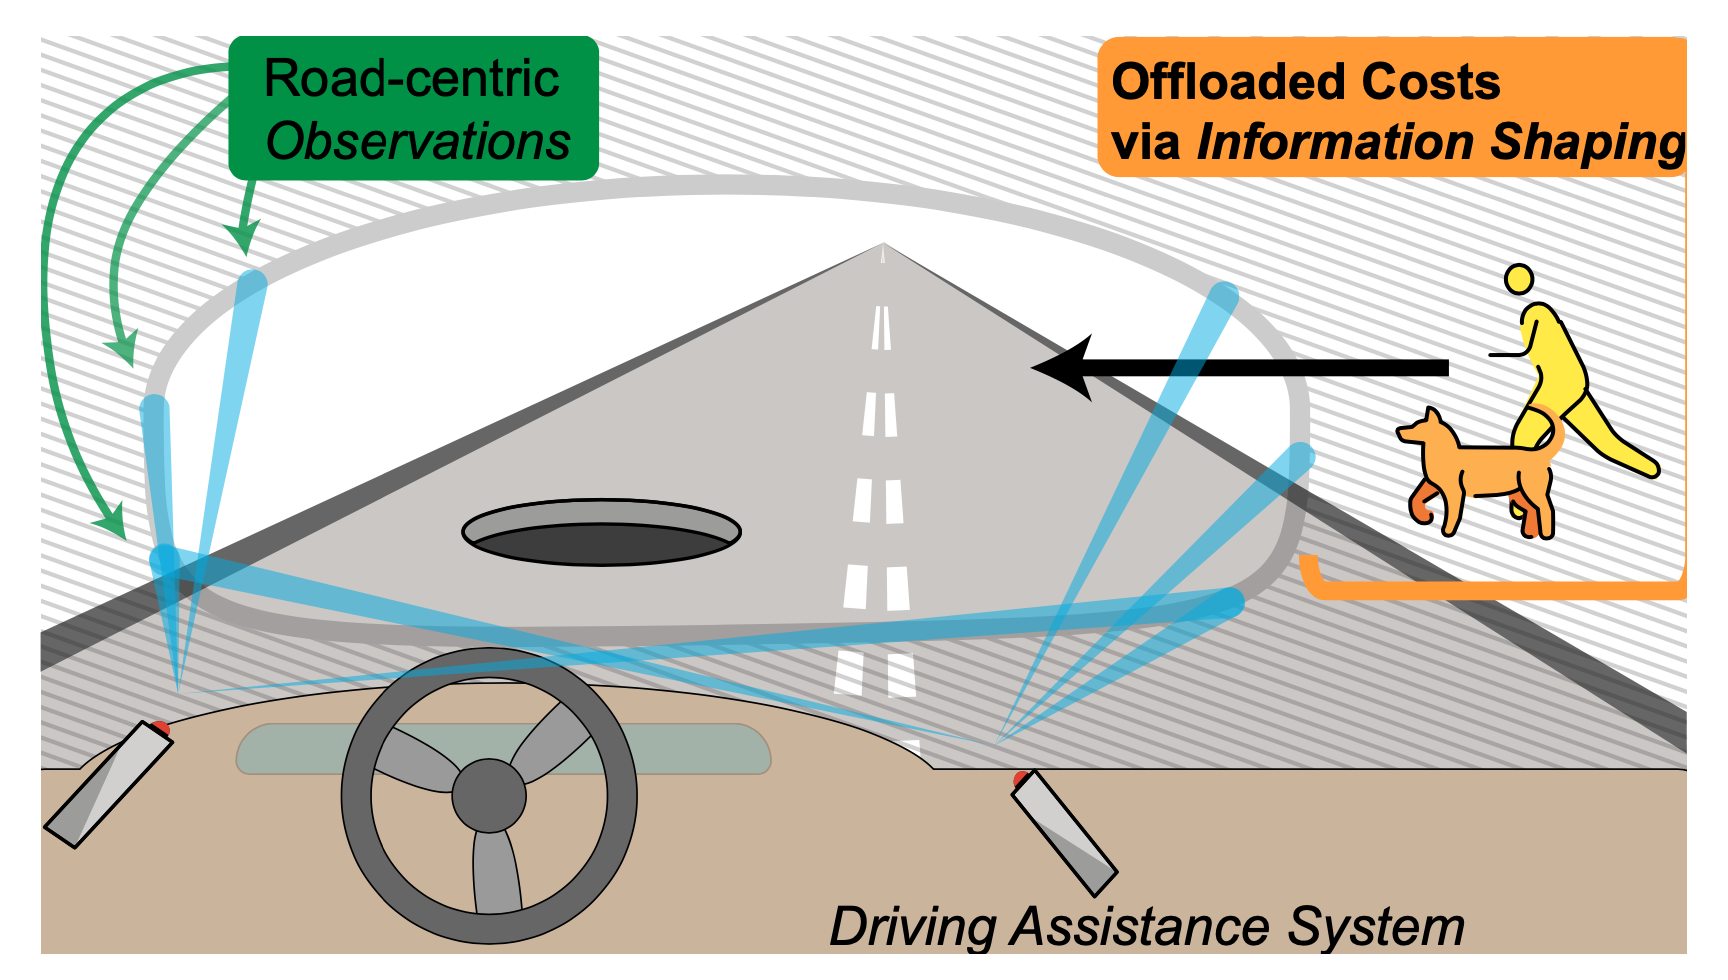
Determine 8: Info shaping instance with an autonomous car.
Coaching A number of Brokers
There may be rising curiosity in the issue of multi-agent RL, however as an rising analysis space, little is thought about how studying methods work together inside dynamic environments. When the relative focus of autonomous brokers will increase inside an setting, the phrases these brokers optimize for can truly re-wire norms and values encoded in that particular utility area. An instance can be the adjustments in conduct that may come if nearly all of automobiles are autonomous and speaking (or not) with one another. On this case, if the brokers have autonomy to optimize towards a purpose of minimizing transit time (for instance), they might crowd out the remaining human drivers and closely disrupt accepted societal norms of transit.
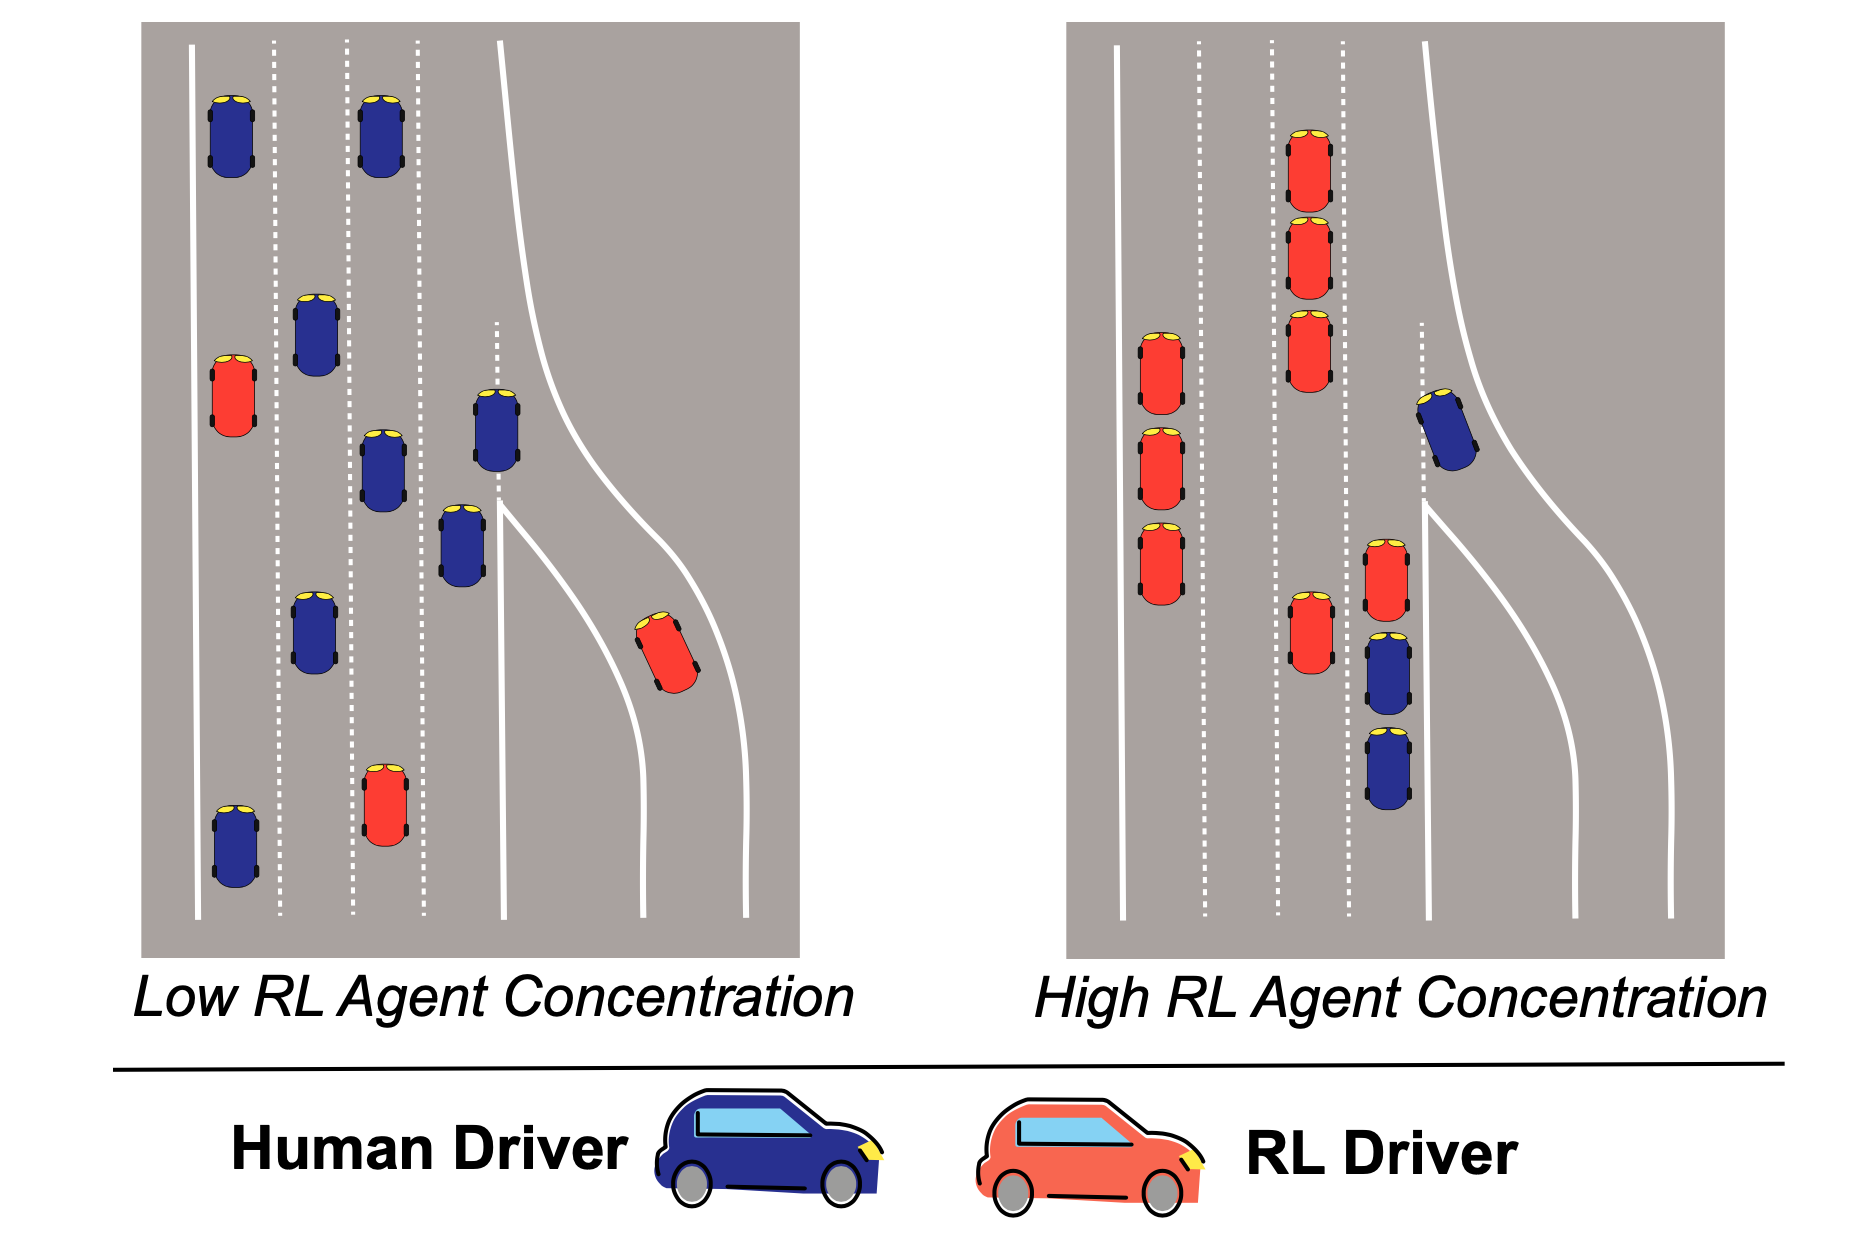
Determine 9: The dangers of multi-agency instance on autonomous automobiles.
In our current whitepaper and analysis paper, we proposed Reward Reviews, a brand new type of ML documentation that foregrounds the societal dangers posed by sequential data-driven optimization methods, whether or not explicitly constructed as an RL agent or implicitly construed by way of data-driven optimization and suggestions. Constructing on proposals to doc datasets and fashions, we deal with reward features: the target that guides optimization choices in feedback-laden methods. Reward Reviews comprise questions that spotlight the guarantees and dangers entailed in defining what’s being optimized in an AI system, and are supposed as dwelling paperwork that dissolve the excellence between ex-ante (design) specification and ex-post (after the actual fact) hurt. Consequently, Reward Reviews present a framework for ongoing deliberation and accountability earlier than and after a system is deployed.
Our proposed template for a Reward Reviews consists of a number of sections, organized to assist the reporter themselves perceive and doc the system. A Reward Report begins with (1) system particulars that include the knowledge context for deploying the mannequin. From there, the report paperwork (2) the optimization intent, which questions the targets of the system and why RL or ML could also be a useful gizmo. The designer then paperwork (3) how the system might have an effect on completely different stakeholders within the institutional interface. The subsequent two sections include technical particulars on (4) the system implementation and (5) analysis. Reward stories conclude with (6) plans for system upkeep as further system dynamics are uncovered.
Crucial function of a Reward Report is that it permits documentation to evolve over time, in keeping with the temporal evolution of a web based, deployed RL system! That is most evident within the change-log, which is we find on the finish of our Reward Report template:
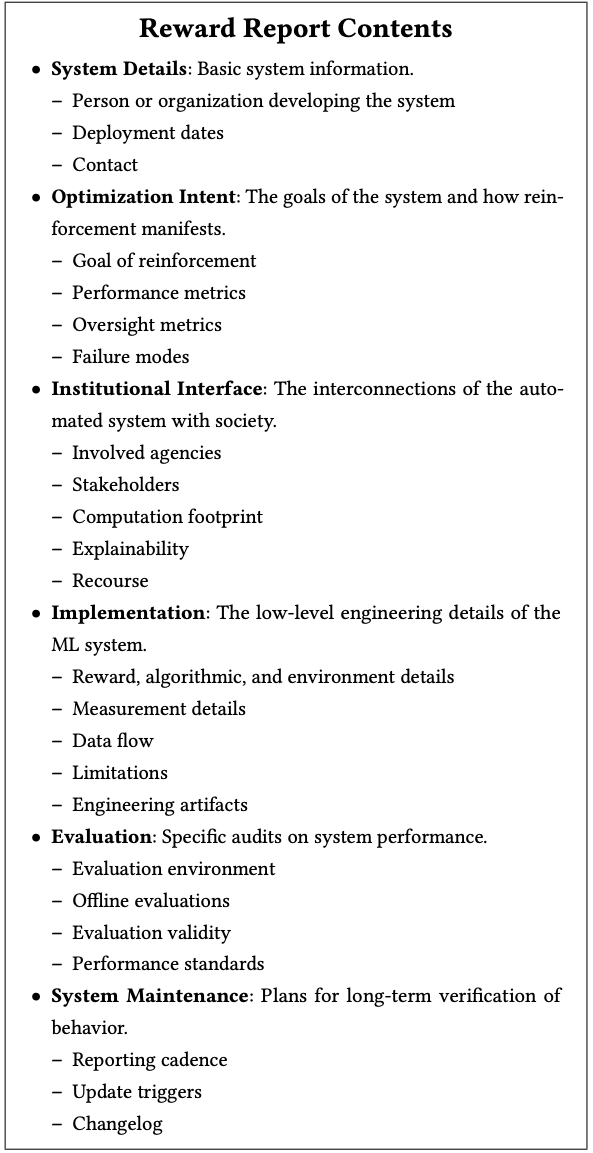
Determine 10: Reward Reviews contents.
What would this appear like in apply?
As a part of our analysis, we now have developed a reward report LaTeX template, in addition to a number of instance reward stories that goal as an instance the sorts of points that might be managed by this type of documentation. These examples embody the temporal evolution of the MovieLens recommender system, the DeepMind MuZero sport taking part in system, and a hypothetical deployment of an RL autonomous car coverage for managing merging visitors, primarily based on the Venture Move simulator.
Nevertheless, these are simply examples that we hope will serve to encourage the RL neighborhood–as extra RL methods are deployed in real-world functions, we hope the analysis neighborhood will construct on our concepts for Reward Reviews and refine the precise content material that ought to be included. To this finish, we hope that you’ll be part of us at our (un)-workshop.
Work with us on Reward Reviews: An (Un)Workshop!
We’re internet hosting an “un-workshop” on the upcoming convention on Reinforcement Studying and Choice Making (RLDM) on June eleventh from 1:00-5:00pm EST at Brown College, Windfall, RI. We name this an un-workshop as a result of we’re searching for the attendees to assist create the content material! We are going to present templates, concepts, and dialogue as our attendees construct out instance stories. We’re excited to develop the concepts behind Reward Reviews with real-world practitioners and cutting-edge researchers.
For extra data on the workshop, go to the web site or contact the organizers at geese-org@lists.berkeley.edu.
This submit is predicated on the next papers:
[ad_2]

