



[ad_1]
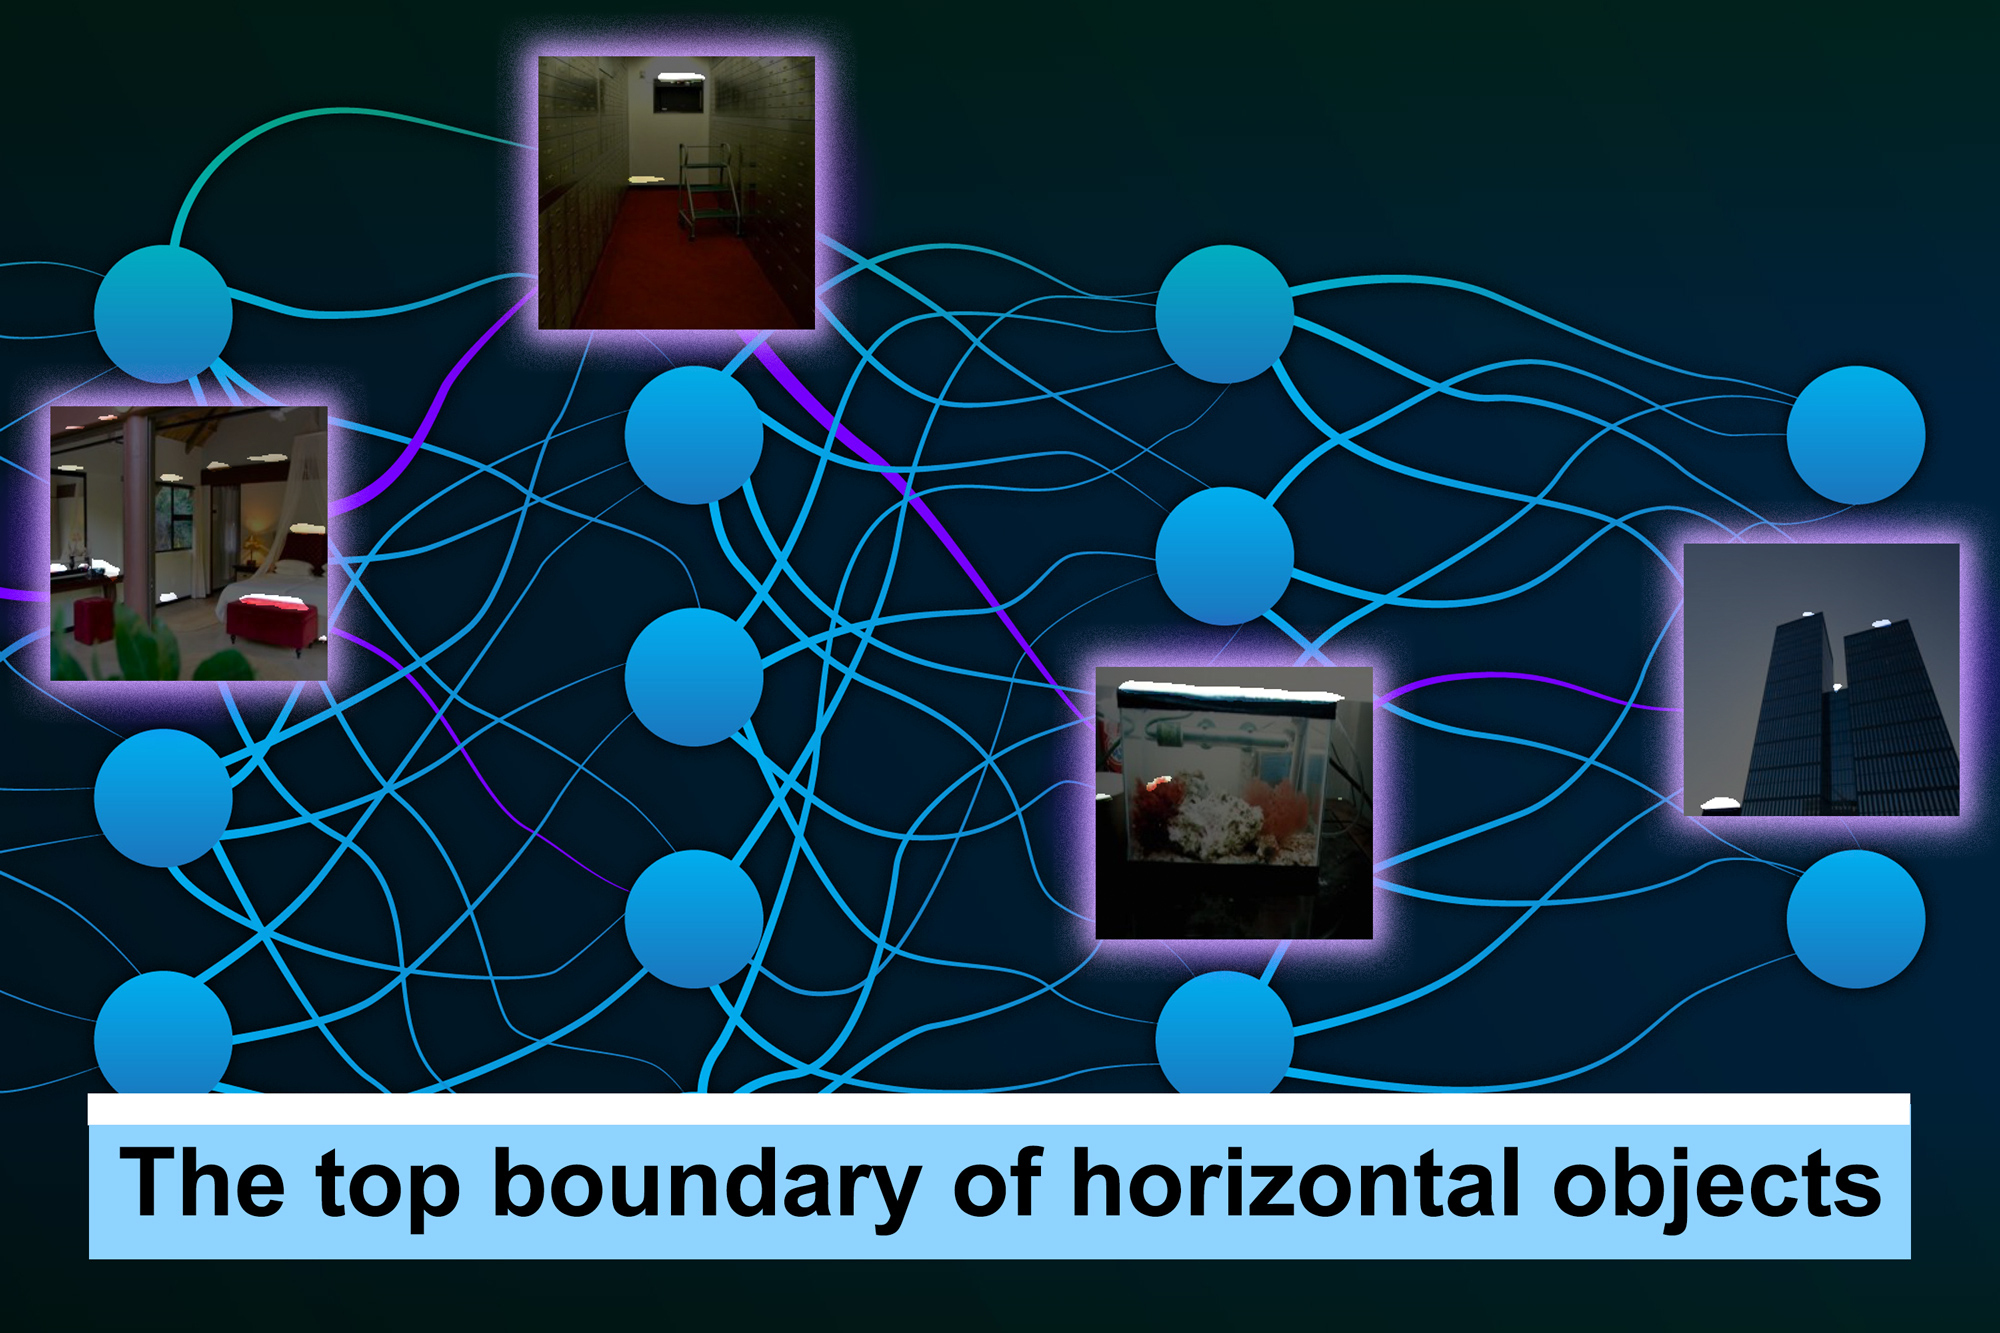
Neural networks are generally referred to as black bins as a result of, even though they will outperform people on sure duties, even the researchers who design them usually don’t perceive how or why they work so properly. But when a neural community is used outdoors the lab, maybe to categorise medical photographs that would assist diagnose coronary heart circumstances, realizing how the mannequin works helps researchers predict the way it will behave in follow.
MIT researchers have now developed a technique that sheds some gentle on the internal workings of black field neural networks. Modeled off the human mind, neural networks are organized into layers of interconnected nodes, or “neurons,” that course of knowledge. The brand new system can routinely produce descriptions of these particular person neurons, generated in English or one other pure language.
For example, in a neural community educated to acknowledge animals in photographs, their methodology may describe a sure neuron as detecting ears of foxes. Their scalable approach is ready to generate extra correct and particular descriptions for particular person neurons than different strategies.
In a new paper, the group exhibits that this methodology can be utilized to audit a neural community to find out what it has discovered, and even edit a community by figuring out after which switching off unhelpful or incorrect neurons.
“We wished to create a technique the place a machine-learning practitioner may give this method their mannequin and it’ll inform them every thing it is aware of about that mannequin, from the attitude of the mannequin’s neurons, in language. This helps you reply the essential query, ‘Is there one thing my mannequin is aware of about that I might not have anticipated it to know?’” says Evan Hernandez, a graduate scholar within the MIT Pc Science and Synthetic Intelligence Laboratory (CSAIL) and lead writer of the paper.
Co-authors embrace Sarah Schwettmann, a postdoc in CSAIL; David Bau, a current CSAIL graduate who’s an incoming assistant professor of pc science at Northeastern College; Teona Bagashvili, a former visiting scholar in CSAIL; Antonio Torralba, the Delta Electronics Professor of Electrical Engineering and Pc Science and a member of CSAIL; and senior writer Jacob Andreas, the X Consortium Assistant Professor in CSAIL. The analysis might be offered on the Worldwide Convention on Studying Representations.
Routinely generated descriptions
Most present strategies that assist machine-learning practitioners perceive how a mannequin works both describe your complete neural community or require researchers to determine ideas they assume particular person neurons may very well be specializing in.
The system Hernandez and his collaborators developed, dubbed MILAN (mutual-information guided linguistic annotation of neurons), improves upon these strategies as a result of it doesn’t require a listing of ideas prematurely and may routinely generate pure language descriptions of all of the neurons in a community. That is particularly essential as a result of one neural community can comprise lots of of 1000’s of particular person neurons.
MILAN produces descriptions of neurons in neural networks educated for pc imaginative and prescient duties like object recognition and picture synthesis. To explain a given neuron, the system first inspects that neuron’s conduct on 1000’s of photographs to seek out the set of picture areas through which the neuron is most lively. Subsequent, it selects a pure language description for every neuron to maximise a amount referred to as pointwise mutual info between the picture areas and descriptions. This encourages descriptions that seize every neuron’s distinctive position throughout the bigger community.
“In a neural community that’s educated to categorise photographs, there are going to be tons of various neurons that detect canine. However there are many various kinds of canine and plenty of completely different elements of canine. So though ‘canine’ could be an correct description of loads of these neurons, it isn’t very informative. We wish descriptions which are very particular to what that neuron is doing. This isn’t simply canine; that is the left aspect of ears on German shepherds,” says Hernandez.
The group in contrast MILAN to different fashions and located that it generated richer and extra correct descriptions, however the researchers have been extra fascinated about seeing the way it might help in answering particular questions on pc imaginative and prescient fashions.
Analyzing, auditing, and modifying neural networks
First, they used MILAN to investigate which neurons are most essential in a neural community. They generated descriptions for each neuron and sorted them primarily based on the phrases within the descriptions. They slowly eliminated neurons from the community to see how its accuracy modified, and located that neurons that had two very completely different phrases of their descriptions (vases and fossils, for example) have been much less essential to the community.
Additionally they used MILAN to audit fashions to see in the event that they discovered one thing sudden. The researchers took picture classification fashions that have been educated on datasets through which human faces have been blurred out, ran MILAN, and counted what number of neurons have been nonetheless delicate to human faces.
“Blurring the faces on this manner does cut back the variety of neurons which are delicate to faces, however removed from eliminates them. As a matter of reality, we hypothesize that a few of these face neurons are very delicate to particular demographic teams, which is kind of stunning. These fashions have by no means seen a human face earlier than, and but all types of facial processing occurs inside them,” Hernandez says.
In a 3rd experiment, the group used MILAN to edit a neural community by discovering and eradicating neurons that have been detecting unhealthy correlations within the knowledge, which led to a 5 p.c improve within the community’s accuracy on inputs exhibiting the problematic correlation.
Whereas the researchers have been impressed by how properly MILAN carried out in these three functions, the mannequin generally provides descriptions which are nonetheless too obscure, or it is going to make an incorrect guess when it doesn’t know the idea it’s purported to determine.
They’re planning to deal with these limitations in future work. Additionally they need to proceed enhancing the richness of the descriptions MILAN is ready to generate. They hope to use MILAN to different varieties of neural networks and use it to explain what teams of neurons do, since neurons work collectively to provide an output.
“That is an method to interpretability that begins from the underside up. The objective is to generate open-ended, compositional descriptions of perform with pure language. We need to faucet into the expressive energy of human language to generate descriptions which are much more pure and wealthy for what neurons do. Having the ability to generalize this method to various kinds of fashions is what I’m most enthusiastic about,” says Schwettmann.
“The final word check of any approach for explainable AI is whether or not it may assist researchers and customers make higher selections about when and tips on how to deploy AI techniques,” says Andreas. “We’re nonetheless a great distance off from with the ability to do this in a common manner. However I’m optimistic that MILAN — and the usage of language as an explanatory instrument extra broadly — might be a helpful a part of the toolbox.”
This work was funded, partly, by the MIT-IBM Watson AI Lab and the SystemsThatLearn@CSAIL initiative.
[ad_2]

