



[ad_1]
During the last a number of years, there was an elevated concentrate on creating differential privateness (DP) machine studying (ML) algorithms. DP has been the idea of a number of sensible deployments in trade — and has even been employed by the U.S. Census — as a result of it allows the understanding of system and algorithm privateness ensures. The underlying assumption of DP is that altering a single consumer’s contribution to an algorithm shouldn’t considerably change its output distribution.
In the usual supervised studying setting, a mannequin is educated to make a prediction of the label for every enter given a coaching set of instance pairs {[input1,label1], …, [inputn, labeln]}. Within the case of deep studying, earlier work launched a DP coaching framework, DP-SGD, that was built-in into TensorFlow and PyTorch. DP-SGD protects the privateness of every instance pair [input, label] by including noise to the stochastic gradient descent (SGD) coaching algorithm. But regardless of in depth efforts, most often, the accuracy of fashions educated with DP-SGD stays considerably decrease than that of non-private fashions.
DP algorithms embrace a privateness funds, ε, which quantifies the worst-case privateness loss for every consumer. Particularly, ε displays how a lot the chance of any explicit output of a DP algorithm can change if one replaces any instance of the coaching set with an arbitrarily totally different one. So, a smaller ε corresponds to higher privateness, because the algorithm is extra detached to adjustments of a single instance. Nonetheless, since smaller ε tends to harm mannequin utility extra, it’s not unusual to think about ε as much as 8 in deep studying purposes. Notably, for the broadly used multiclass picture classification dataset, CIFAR-10, the highest reported accuracy (with out pre-training) for DP fashions with ε = 3 is 69.3%, a end result that depends on handcrafted visible options. In distinction, non-private situations (ε = ∞) with discovered options have proven to realize >95% accuracy whereas utilizing fashionable neural community architectures. This efficiency hole stays a roadblock for a lot of real-world purposes to undertake DP. Furthermore, regardless of current advances, DP-SGD typically comes with elevated computation and reminiscence overhead resulting from slower convergence and the necessity to compute the norm of the per-example gradient.
In “Deep Studying with Label Differential Privateness”, offered at NeurIPS 2021, we take into account a extra relaxed, however vital, particular case referred to as label differential privateness (LabelDP), the place we assume the inputs (enter1, …, entern) are public, and solely the privateness of the coaching labels (label1, …, labeln) must be protected. With this relaxed assure, we are able to design novel algorithms that make the most of a previous understanding of the labels to enhance the mannequin utility. We exhibit that LabelDP achieves 20% larger accuracy than DP-SGD on the CIFAR-10 dataset. Our outcomes throughout a number of duties affirm that LabelDP may considerably slender the efficiency hole between non-public fashions and their non-private counterparts, mitigating the challenges in actual world purposes. We additionally current a multi-stage algorithm for coaching deep neural networks with LabelDP. Lastly, we’re excited to launch the code for this multi-stage coaching algorithm.
LabelDP
The notion of LabelDP has been studied within the Most likely Roughly Appropriate (PAC) studying setting, and captures a number of sensible situations. Examples embrace: (i) computational promoting, the place impressions are recognized to the advertiser and thus thought of non-sensitive, however conversions reveal consumer curiosity and are thus non-public; (ii) advice methods, the place the alternatives are recognized to a streaming service supplier, however the consumer rankings are thought of delicate; and (iii) consumer surveys and analytics, the place demographic data (e.g., age, gender) is non-sensitive, however earnings is delicate.
We make a number of key observations on this situation. (i) When solely the labels have to be protected, a lot less complicated algorithms will be utilized for information preprocessing to realize LabelDP with none modifications to the prevailing deep studying coaching pipeline. For instance, the traditional Randomized Response (RR) algorithm, designed to remove evasive reply biases in survey aggregation, achieves LabelDP by merely flipping the label to a random one with a chance that is determined by ε. (ii) Conditioned on the (public) enter, we are able to compute a previous chance distribution, which offers a previous perception of the probability of the category labels for the given enter. With a novel variant of RR, RR-with-prior, we are able to incorporate prior data to scale back the label noise whereas sustaining the identical privateness assure as classical RR.
The determine beneath illustrates how RR-with-prior works. Assume a mannequin is constructed to categorise an enter picture into 10 classes. Contemplate a coaching instance with the label “airplane”. To ensure LabelDP, classical RR returns a random label sampled in line with a given distribution (see the top-right panel of the determine beneath). The smaller the focused privateness funds ε is, the bigger the chance of sampling an incorrect label needs to be. Now assume now we have a previous chance exhibiting that the given enter is “possible an object that flies” (decrease left panel). With the prior, RR-with-prior will discard all labels with small prior and solely pattern from the remaining labels. By dropping these unlikely labels, the chance of returning the right label is considerably elevated, whereas sustaining the identical privateness funds ε (decrease proper panel).
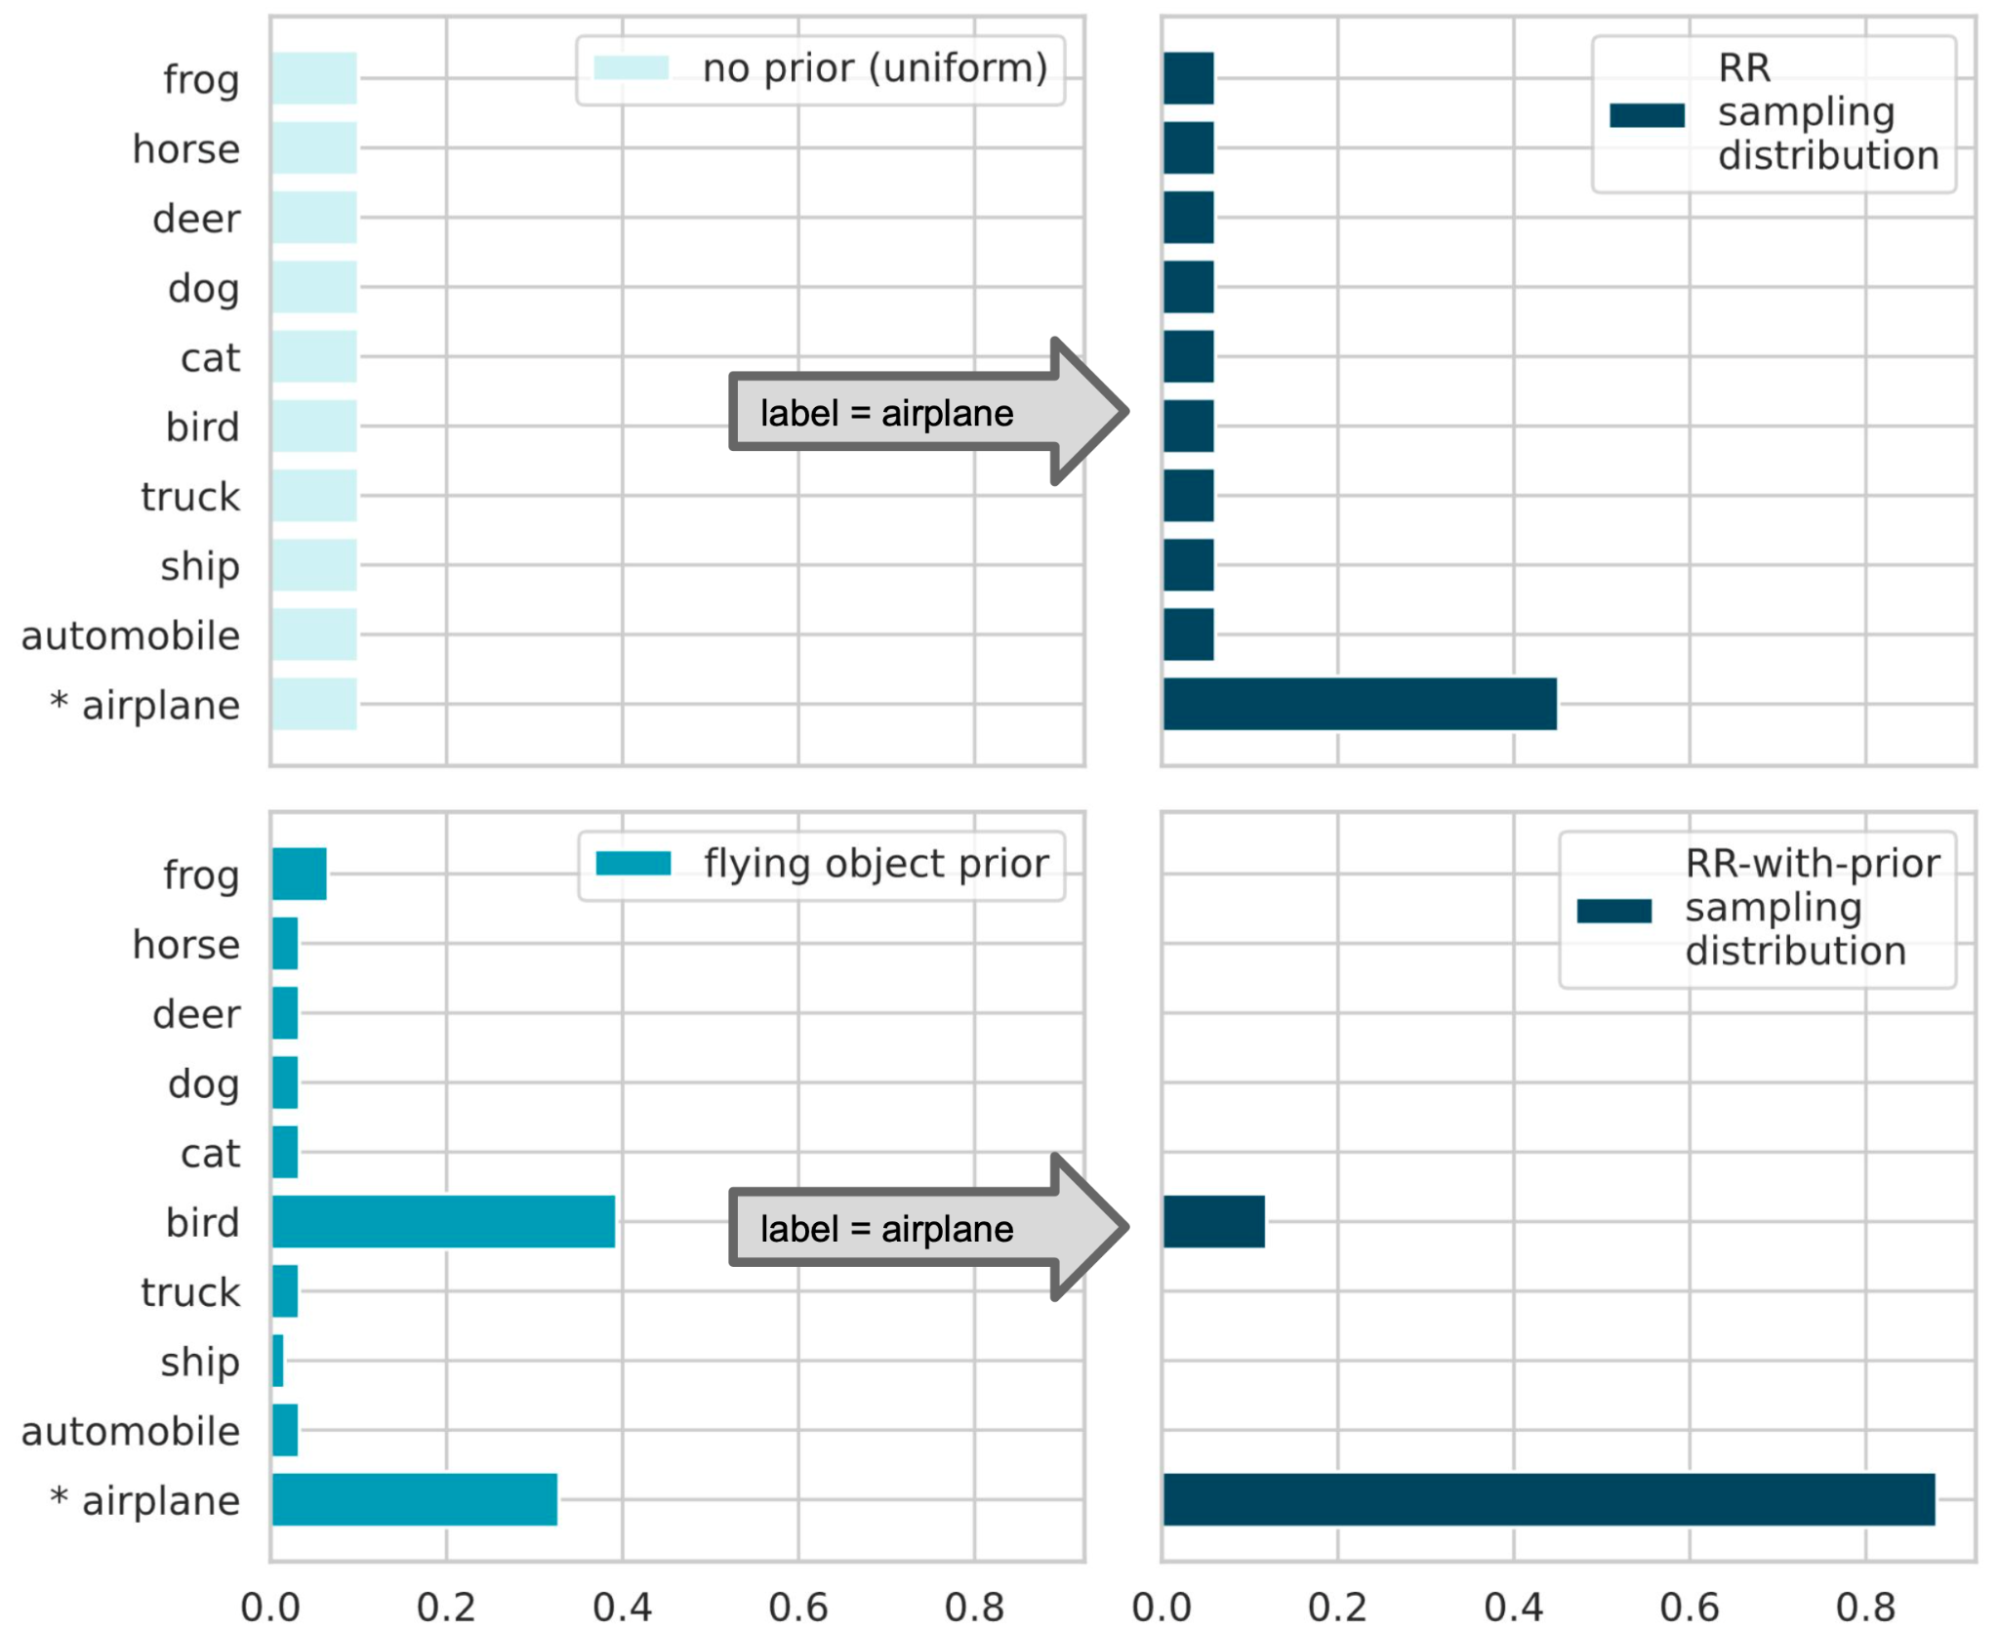 |
| Randomized response: If no prior data is given (top-left), all lessons are sampled with equal chance. The chance of sampling the true class (P[airplane] ≈ 0.5) is larger if the privateness funds is larger (top-right). RR-with-prior: Assuming a previous distribution (bottom-left), unlikely lessons are “suppressed” from the sampling distribution (bottom-right). So the chance of sampling the true class (P[airplane] ≈ 0.9) is elevated beneath the identical privateness funds. |
A Multi-stage Coaching Algorithm
Based mostly on the RR-with-prior observations, we current a multi-stage algorithm for coaching deep neural networks with LabelDP. First, the coaching set is randomly partitioned into a number of subsets. An preliminary mannequin is then educated on the primary subset utilizing classical RR. Lastly, the algorithm divides the information into a number of elements, and at every stage, a single half is used to coach the mannequin. The labels are produced utilizing RR-with-prior, and the priors are primarily based on the prediction of the mannequin educated thus far.
 |
| An illustration of the multi-stage coaching algorithm. The coaching set is partitioned into t disjoint subsets. An preliminary mannequin is educated on the primary subset utilizing classical RR. Then the educated mannequin is used to offer prior predictions within the RR-with-prior step and within the coaching of the later levels. |
Outcomes
We benchmark the multi-stage coaching algorithm’s empirical efficiency on a number of datasets, domains, and architectures. On the CIFAR-10 multi-class classification process for a similar privateness funds ε, the multi-stage coaching algorithm (blue within the determine beneath) guaranteeing LabelDP achieves 20% larger accuracy than DP-SGD. We emphasize that LabelDP protects solely the labels whereas DP-SGD protects each the inputs and labels, so this isn’t a strictly truthful comparability. Nonetheless, this end result demonstrates that for particular software situations the place solely the labels have to be protected, LabelDP may result in vital enhancements within the mannequin utility whereas narrowing the efficiency hole between non-public fashions and public baselines.
 |
| Comparability of the mannequin utility (take a look at accuracy) of various algorithms beneath totally different privateness budgets. |
In some domains, prior data is of course out there or will be constructed utilizing publicly out there information solely. For instance, many machine studying methods have historic fashions which might be evaluated on new information to offer label priors. In domains the place unsupervised or self-supervised studying algorithms work effectively, priors is also constructed from fashions pre-trained on unlabeled (due to this fact public with respect to LabelDP) information. Particularly, we exhibit two self-supervised studying algorithms in our CIFAR-10 analysis (orange and inexperienced traces within the determine above). We use self-supervised studying fashions to compute representations for the coaching examples and run k-means clustering on the representations. Then, we spend a small quantity of privateness funds (ε ≤ 0.05) to question a histogram of the label distribution of every cluster and use that because the label prior for the factors in every cluster. This prior considerably boosts the mannequin utility within the low privateness funds regime (ε < 1).
Comparable observations maintain throughout a number of datasets reminiscent of MNIST, Style-MNIST and non-vision domains, such because the MovieLens-1M film score process. Please see our paper for the complete report on the empirical outcomes.
The empirical outcomes recommend that defending the privateness of the labels will be considerably simpler than defending the privateness of each the inputs and labels. This may also be mathematically confirmed beneath particular settings. Specifically, we are able to present that for convex stochastic optimization, the pattern complexity of algorithms privatizing the labels is far smaller than that of algorithms privatizing each labels and inputs. In different phrases, to realize the identical degree of mannequin utility beneath the identical privateness funds, LabelDP requires fewer coaching examples.
Conclusion
We demonstrated that each empirical and theoretical outcomes recommend that LabelDP is a promising leisure of the complete DP assure. In purposes the place the privateness of the inputs doesn’t have to be protected, LabelDP may scale back the efficiency hole between a personal mannequin and the non-private baseline. For future work, we plan to design higher LabelDP algorithms for different duties past multi-class classification. We hope that the discharge of the multi-stage coaching algorithm code offers researchers with a helpful useful resource for DP analysis.
Acknowledgements
This work was carried out in collaboration with Badih Ghazi, Noah Golowich, and Ravi Kumar. We additionally thank Sami Torbey for beneficial suggestions on our work.
[ad_2]

