



[ad_1]
Picture matting is the method of extracting a exact alpha matte that separates foreground and background objects in a picture. This method has been historically used within the filmmaking and images trade for picture and video modifying functions, e.g., background alternative, artificial bokeh and different visible results. Picture matting assumes that a picture is a composite of foreground and background pictures, and therefore, the depth of every pixel is a linear mixture of the foreground and the background.
Within the case of conventional picture segmentation, the picture is segmented in a binary method, through which a pixel both belongs to the foreground or background. Any such segmentation, nonetheless, is unable to take care of pure scenes that comprise fantastic particulars, e.g., hair and fur, which require estimating a transparency worth for every pixel of the foreground object.
Alpha mattes, in contrast to segmentation masks, are often extraordinarily exact, preserving strand-level hair particulars and correct foreground boundaries. Whereas current deep studying strategies have proven their potential in picture matting, many challenges stay, similar to era of correct floor reality alpha mattes, bettering generalization on in-the-wild pictures and performing inference on cell gadgets treating high-resolution pictures.
With the Pixel 6, we now have considerably improved the looks of selfies taken in Portrait Mode by introducing a brand new method to estimate a high-resolution and correct alpha matte from a selfie picture. When synthesizing the depth-of-field impact, the utilization of the alpha matte permits us to extract a extra correct silhouette of the photographed topic and have a greater foreground-background separation. This enables customers with all kinds of hairstyles to take great-looking Portrait Mode pictures utilizing the selfie digital camera. On this put up, we describe the know-how we used to realize this enchancment and focus on how we tackled the challenges talked about above.
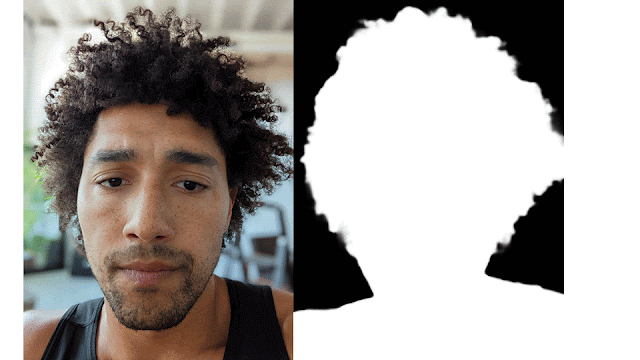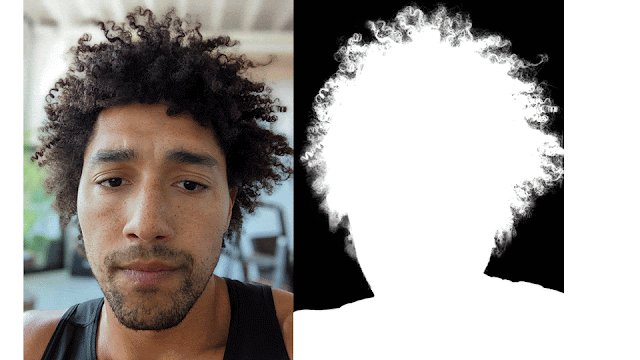 |
| Portrait Mode impact on a selfie shot utilizing a low-resolution and coarse alpha matte in comparison with utilizing the brand new high-quality alpha matte. |
Portrait Matting
In designing Portrait Matting, we skilled a totally convolutional neural community consisting of a sequence of encoder-decoder blocks to progressively estimate a high-quality alpha matte. We concatenate the enter RGB picture along with a rough alpha matte (generated utilizing a low-resolution individual segmenter) that’s handed as an enter to the community. The brand new Portrait Matting mannequin makes use of a MobileNetV3 spine and a shallow (i.e., having a low variety of layers) decoder to first predict a refined low-resolution alpha matte that operates on a low-resolution picture. Then we use a shallow encoder-decoder and a collection of residual blocks to course of a high-resolution picture and the refined alpha matte from the earlier step. The shallow encoder-decoder depends extra on lower-level options than the earlier MobileNetV3 spine, specializing in high-resolution structural options to foretell remaining transparency values for every pixel. On this method, the mannequin is ready to refine an preliminary foreground alpha matte and precisely extract very fantastic particulars like hair strands. The proposed neural community structure effectively runs on Pixel 6 utilizing Tensorflow Lite.
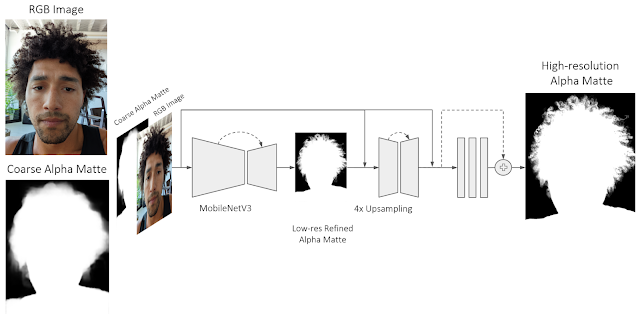 |
| The community predicts a high-quality alpha matte from a shade picture and an preliminary coarse alpha matte. We use a MobileNetV3 spine and a shallow decoder to first predict a refined low-resolution alpha matte. Then we use a shallow encoder-decoder and a collection of residual blocks to additional refine the initially estimated alpha matte. |
Most up-to-date deep studying work for picture matting depends on manually annotated per-pixel alpha mattes used to separate the foreground from the background which are generated with picture modifying instruments or inexperienced screens. This course of is tedious and doesn’t scale for the era of enormous datasets. Additionally, it typically produces inaccurate alpha mattes and foreground pictures which are contaminated (e.g., by mirrored mild from the background, or “inexperienced spill”). Furthermore, this does nothing to make sure that the lighting on the topic seems in step with the lighting within the new background setting.
To handle these challenges, Portrait Matting is skilled utilizing a high-quality dataset generated utilizing a customized volumetric seize system, Gentle Stage. In contrast with earlier datasets, that is extra sensible, as relighting permits the illumination of the foreground topic to match the background. Moreover, we supervise the coaching of the mannequin utilizing pseudo–floor reality alpha mattes from in-the-wild pictures to enhance mannequin generalization, defined under. This floor reality knowledge era course of is without doubt one of the key parts of this work.
Floor Reality Information Technology
To generate correct floor reality knowledge, Gentle Stage produces near-photorealistic fashions of individuals utilizing a geodesic sphere outfitted with 331 customized shade LED lights, an array of high-resolution cameras, and a set of customized high-resolution depth sensors. Along with Gentle Stage knowledge, we compute correct alpha mattes utilizing time-multiplexed lights and a beforehand recorded “clear plate”. This method is often known as ratio matting.
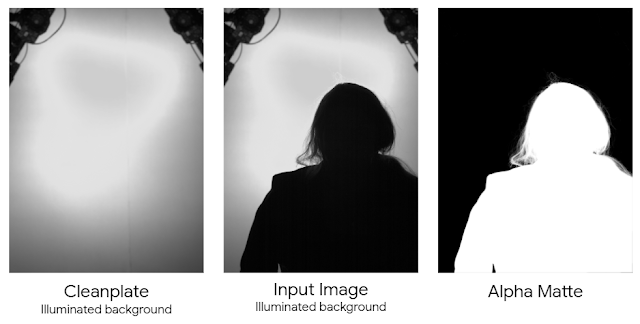 |
| This technique works by recording a picture of the topic silhouetted towards an illuminated background as one of many lighting circumstances. As well as, we seize a clear plate of the illuminated background. The silhouetted picture, divided by the clear plate picture, gives a floor reality alpha matte. |
Then, we extrapolate the recorded alpha mattes to all of the digital camera viewpoints in Gentle Stage utilizing a deep studying–primarily based matting community that leverages captured clear plates as an enter. This method permits us to increase the alpha mattes computation to unconstrained backgrounds with out the necessity for specialised time-multiplexed lighting or a clear background. This deep studying structure was solely skilled utilizing floor reality mattes generated utilizing the ratio matting method.
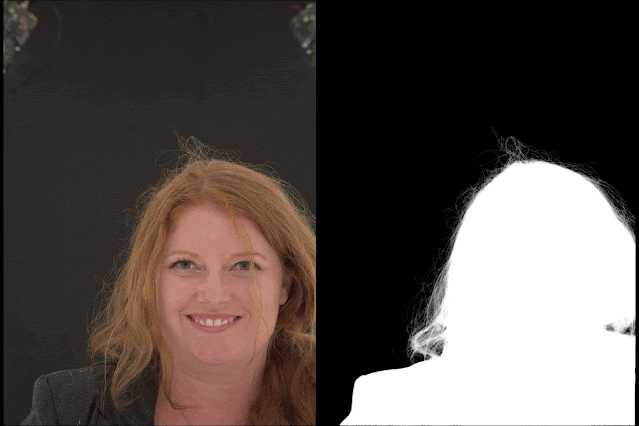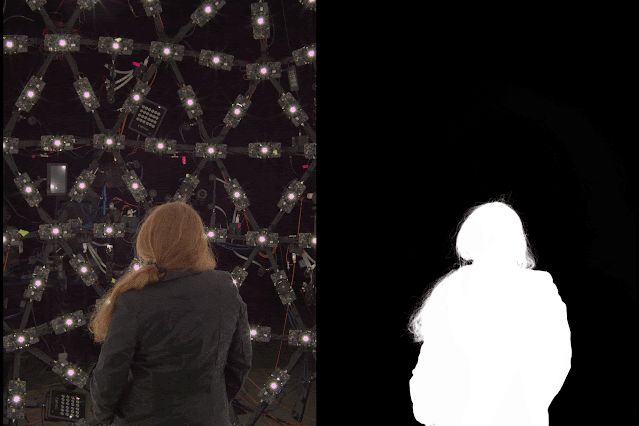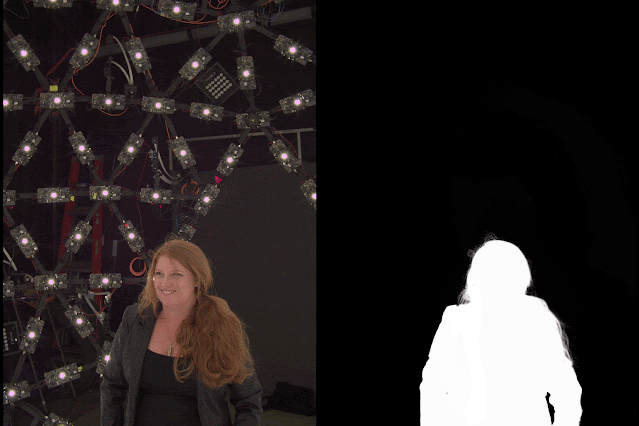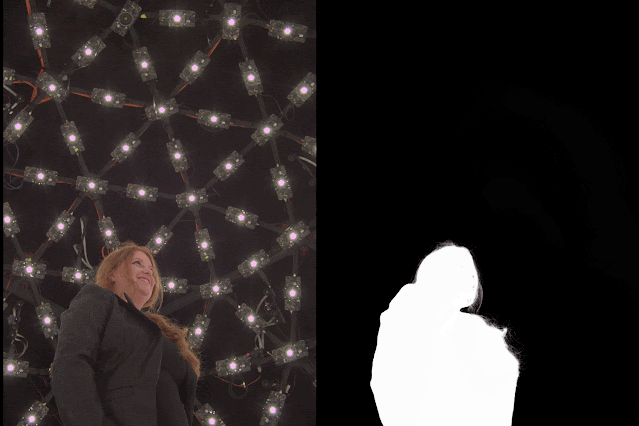 |
| Computed alpha mattes from all digital camera viewpoints on the Gentle Stage. |
Leveraging the reflectance area for every topic and the alpha matte generated with our floor reality matte era system, we are able to relight every portrait utilizing a given HDR lighting setting. We composite these relit topics into backgrounds equivalent to the goal illumination following the alpha mixing equation. The background pictures are then generated from the HDR panoramas by positioning a digital digital camera on the middle and ray-tracing into the panorama from the digital camera’s middle of projection. We be sure that the projected view into the panorama matches its orientation as used for relighting. We use digital cameras with totally different focal lengths to simulate the totally different fields-of-view of client cameras. This pipeline produces sensible composites by dealing with matting, relighting, and compositing in a single system, which we then use to coach the Portrait Matting mannequin.
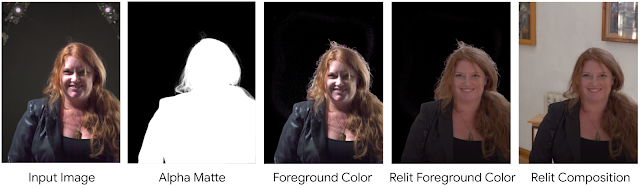 |
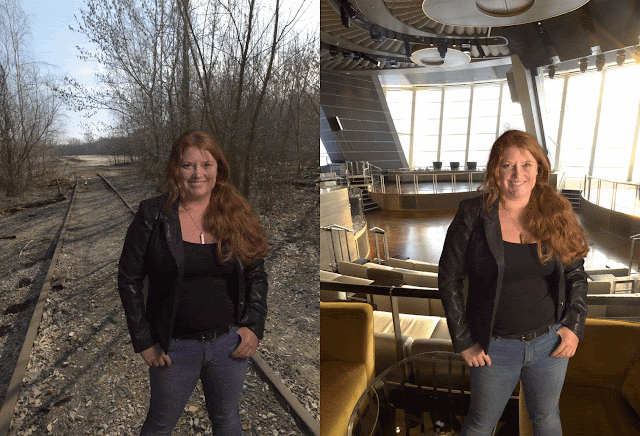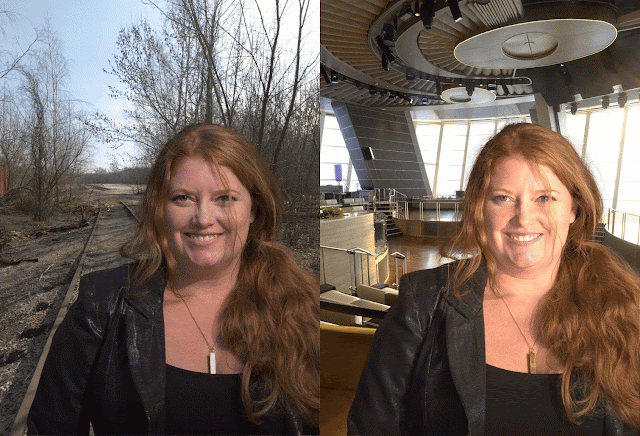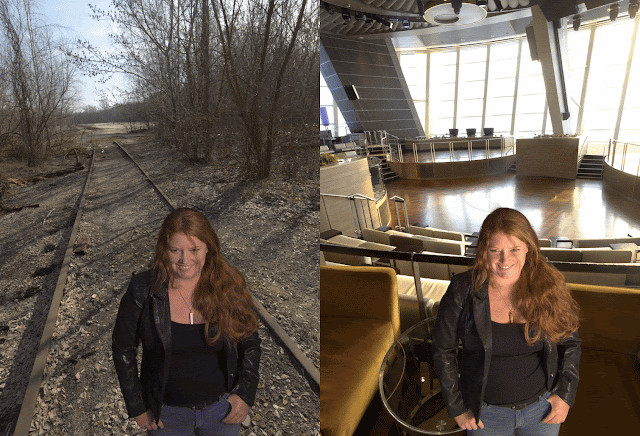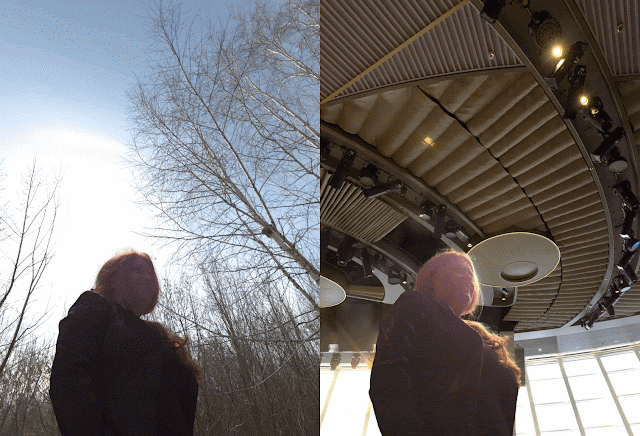 |
| Composited pictures on totally different backgrounds (high-resolution HDR maps) utilizing floor reality generated alpha mattes. |
Coaching Supervision Utilizing In-the-Wild Portraits
To bridge the hole between portraits generated utilizing Gentle Stage and in-the-wild portraits, we created a pipeline to routinely annotate in-the-wild images producing pseudo–floor reality alpha mattes. For this objective, we leveraged the Deep Matting mannequin proposed in Complete Relighting to create an ensemble of fashions that computes a number of high-resolution alpha mattes from in-the-wild pictures. We ran this pipeline on an in depth dataset of portrait images captured in-house utilizing Pixel telephones. Moreover, throughout this course of we carried out test-time augmentation by doing inference on enter pictures at totally different scales and rotations, and eventually aggregating per-pixel alpha values throughout all estimated alpha mattes.
Generated alpha mattes are visually evaluated with respect to the enter RGB picture. The alpha mattes which are perceptually right, i.e., following the topic’s silhouette and fantastic particulars (e.g., hair), are added to the coaching set. Throughout coaching, each datasets are sampled utilizing totally different weights. Utilizing the proposed supervision technique exposes the mannequin to a bigger number of scenes and human poses, bettering its predictions on images within the wild (mannequin generalization).
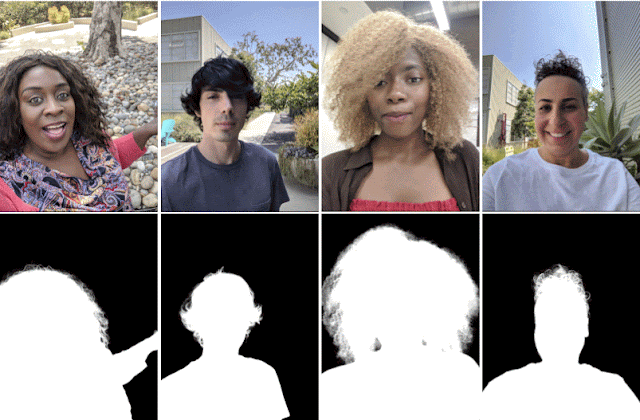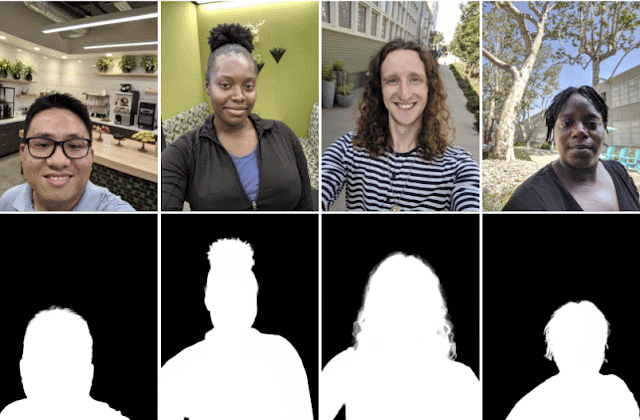 |
| Estimated pseudo–floor reality alpha mattes utilizing an ensemble of Deep Matting fashions and test-time augmentation. |
Portrait Mode Selfies
The Portrait Mode impact is especially delicate to errors across the topic boundary (see picture under). For instance, errors brought on by the utilization of a rough alpha matte maintain sharp concentrate on background areas close to the topic boundaries or hair space. The utilization of a high-quality alpha matte permits us to extract a extra correct silhouette of the photographed topic and enhance foreground-background separation.
 |
Strive It Out Your self
We have now made front-facing digital camera Portrait Mode on the Pixel 6 higher by bettering alpha matte high quality, leading to fewer errors within the remaining rendered picture and by bettering the look of the blurred background across the hair area and topic boundary. Moreover, our ML mannequin makes use of various coaching datasets that cowl all kinds of pores and skin tones and hair types. You may do that improved model of Portrait Mode by taking a selfie shot with the brand new Pixel 6 telephones.
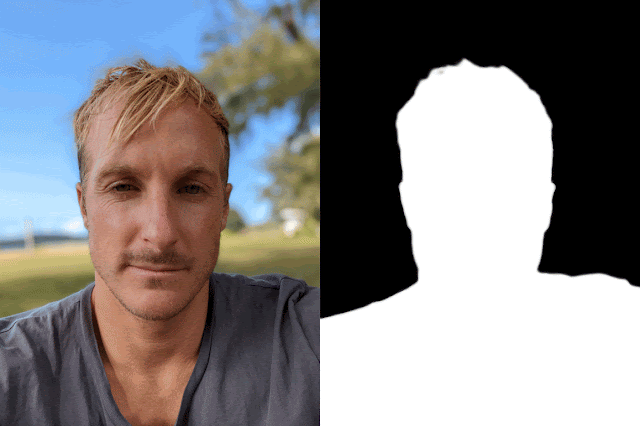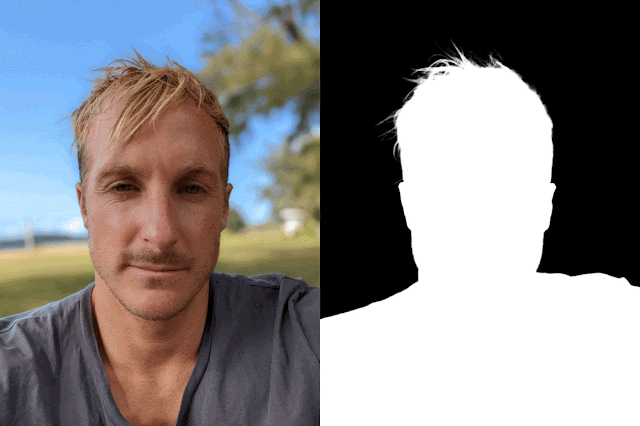 |
| Portrait Mode impact on a selfie shot utilizing a rough alpha matte in comparison with utilizing the brand new top quality alpha matte. |
Acknowledgments
This work wouldn’t have been potential with out Sergio Orts Escolano, Jana Ehmann, Sean Fanello, Christoph Rhemann, Junlan Yang, Andy Hsu, Hossam Isack, Rohit Pandey, David Aguilar, Yi Jinn, Christian Hane, Jay Busch, Cynthia Herrera, Matt Whalen, Philip Davidson, Jonathan Taylor, Peter Lincoln, Geoff Harvey, Nisha Masharani, Alexander Schiffhauer, Chloe LeGendre, Paul Debevec, Sofien Bouaziz, Adarsh Kowdle, Thabo Beeler, Chia-Kai Liang and Shahram Izadi. Particular due to our photographers James Adamson, Christopher Farro and Cort Muller who took quite a few take a look at images for us.
[ad_2]

