



[ad_1]
Over the previous a number of years, deep neural networks (DNNs) have been fairly profitable in driving spectacular efficiency positive factors in a number of real-world purposes, from picture recognition to genomics. Nevertheless, fashionable DNNs usually have way more trainable mannequin parameters than the variety of coaching examples and the ensuing overparameterized networks can simply overfit to noisy or corrupted labels (i.e., examples which might be assigned a fallacious class label). As a consequence, coaching with noisy labels usually results in degradation in accuracy of the educated mannequin on clear take a look at knowledge. Sadly, noisy labels can seem in a number of real-world eventualities resulting from a number of elements, akin to errors and inconsistencies in handbook annotation and the usage of inherently noisy label sources (e.g., the web or automated labels from an present system).
Earlier work has proven that representations discovered by pre-training giant fashions with noisy knowledge may be helpful for prediction when utilized in a linear classifier educated with clear knowledge. In precept, it’s doable to immediately prepare machine studying (ML) fashions on noisy knowledge with out resorting to this two-stage method. To achieve success, such various strategies ought to have the next properties: (i) they need to match simply into normal coaching pipelines with little computational or reminiscence overhead; (ii) they need to be relevant in “streaming” settings the place new knowledge is repeatedly added throughout coaching; and (iii) they need to not require knowledge with clear labels.
In “Constrained Occasion and Class Reweighting for Strong Studying below Label Noise”, we suggest a novel and principled technique, named Constrained Occasion reWeighting (CIW), with these properties that works by dynamically assigning significance weights each to particular person cases and to class labels in a mini-batch, with the objective of decreasing the impact of probably noisy examples. We formulate a household of constrained optimization issues that yield easy options for these significance weights. These optimization issues are solved per mini-batch, which avoids the necessity to retailer and replace the significance weights over the total dataset. This optimization framework additionally gives a theoretical perspective for present label smoothing heuristics that handle label noise, akin to label bootstrapping. We consider the strategy with various quantities of artificial noise on the usual CIFAR-10 and CIFAR-100 benchmarks and observe appreciable efficiency positive factors over a number of present strategies.
Technique
Coaching ML fashions entails minimizing a loss operate that signifies how effectively the present parameters match to the given coaching knowledge. In every coaching step, this loss is roughly calculated as a (weighted) sum of the losses of particular person cases within the mini-batch of knowledge on which it’s working. In normal coaching, every occasion is handled equally for the aim of updating the mannequin parameters, which corresponds to assigning uniform (i.e., equal) weights throughout the mini-batch.
Nevertheless, empirical observations made in earlier works reveal that noisy or mislabeled cases are likely to have larger loss values than these which might be clear, significantly throughout early to mid-stages of coaching. Thus, assigning uniform significance weights to all cases signifies that resulting from their larger loss values, the noisy cases can probably dominate the clear cases and degrade the accuracy on clear take a look at knowledge.
Motivated by these observations, we suggest a household of constrained optimization issues that remedy this drawback by assigning significance weights to particular person cases within the dataset to scale back the impact of these which might be more likely to be noisy. This method gives management over how a lot the weights deviate from uniform, as quantified by a divergence measure. It seems that for a number of kinds of divergence measures, one can receive easy formulae for the occasion weights. The ultimate loss is computed because the weighted sum of particular person occasion losses, which is used for updating the mannequin parameters. We name this the Constrained Occasion reWeighting (CIW) technique. This technique permits for controlling the smoothness or peakiness of the weights by way of the selection of divergence and a corresponding hyperparameter.
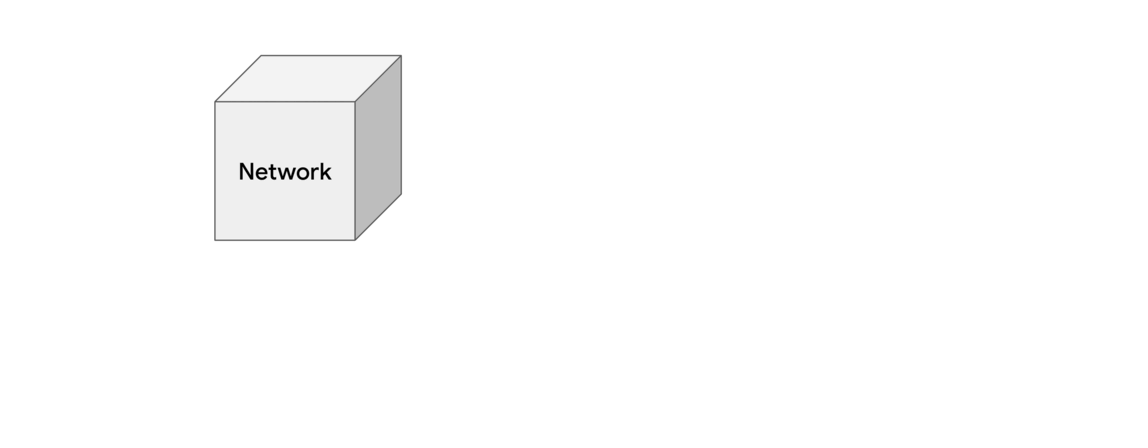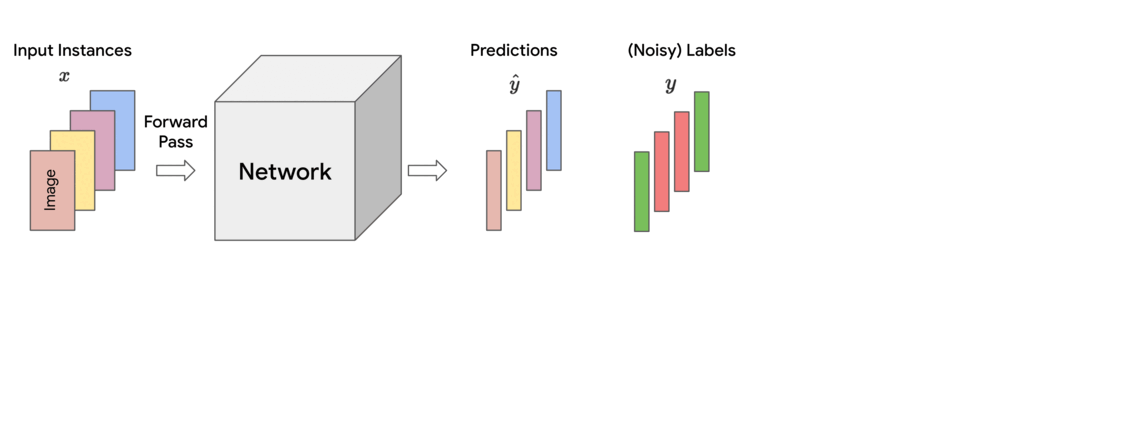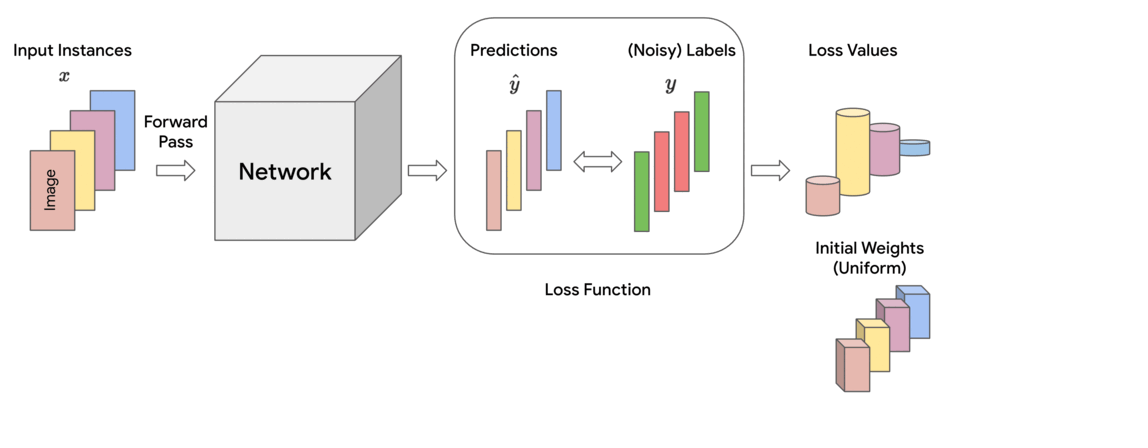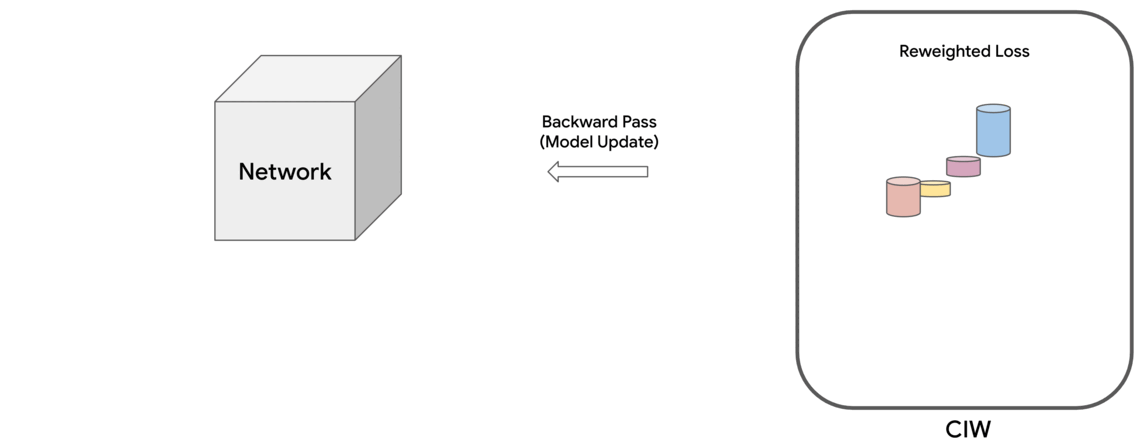 |
| Schematic of the proposed Constrained Occasion reWeighting (CIW) technique. |
Illustration with Resolution Boundary on a 2D Dataset
For instance for example the conduct of this technique, we take into account a loud model of the Two Moons dataset, which consists of randomly sampled factors from two lessons within the form of two half moons. We corrupt 30% of the labels and prepare a multilayer perceptron community on it for binary classification. We use the usual binary cross-entropy loss and an SGD with momentum optimizer to coach the mannequin. Within the determine under (left panel), we present the info factors and visualize a suitable resolution boundary separating the 2 lessons with a dotted line. The factors marked purple within the higher half-moon and people marked inexperienced within the decrease half-moon point out noisy knowledge factors.
The baseline mannequin educated with the binary cross-entropy loss assigns uniform weights to the cases in every mini-batch, thus finally overfitting to the noisy cases and leading to a poor resolution boundary (center panel within the determine under).
The CIW technique reweights the cases in every mini-batch based mostly on their corresponding loss values (proper panel within the determine under). It assigns bigger weights to the clear cases which might be situated on the proper facet of the choice boundary and damps the impact of noisy cases that incur the next loss worth. Smaller weights for noisy cases assist in stopping the mannequin from overfitting to them, thus permitting the mannequin educated with CIW to efficiently converge to a superb resolution boundary by avoiding the influence of label noise.
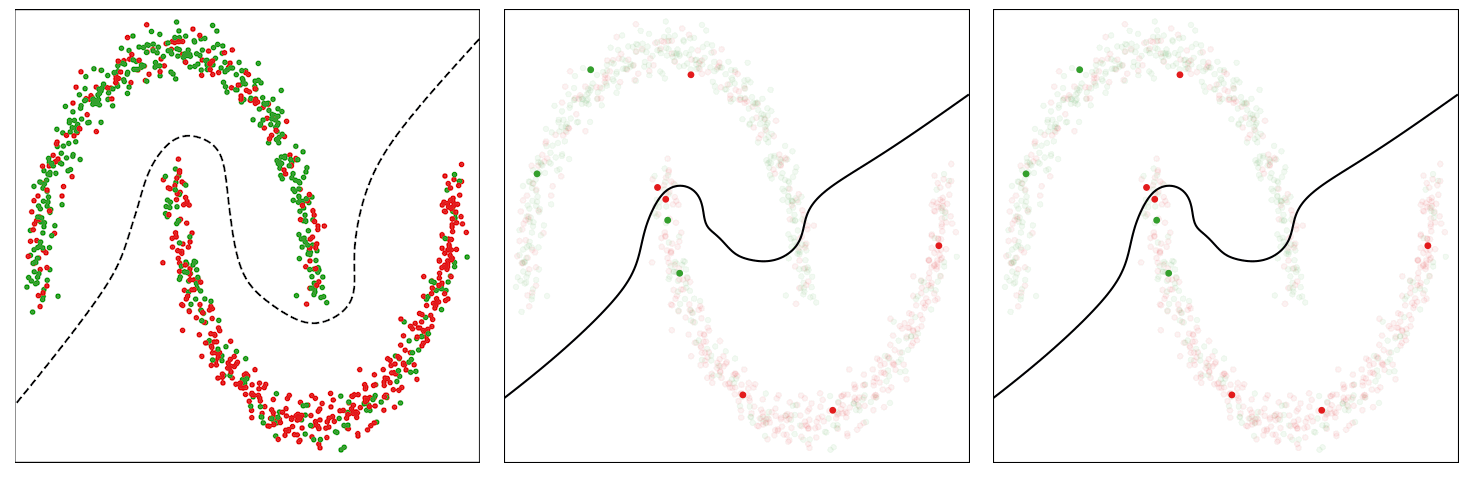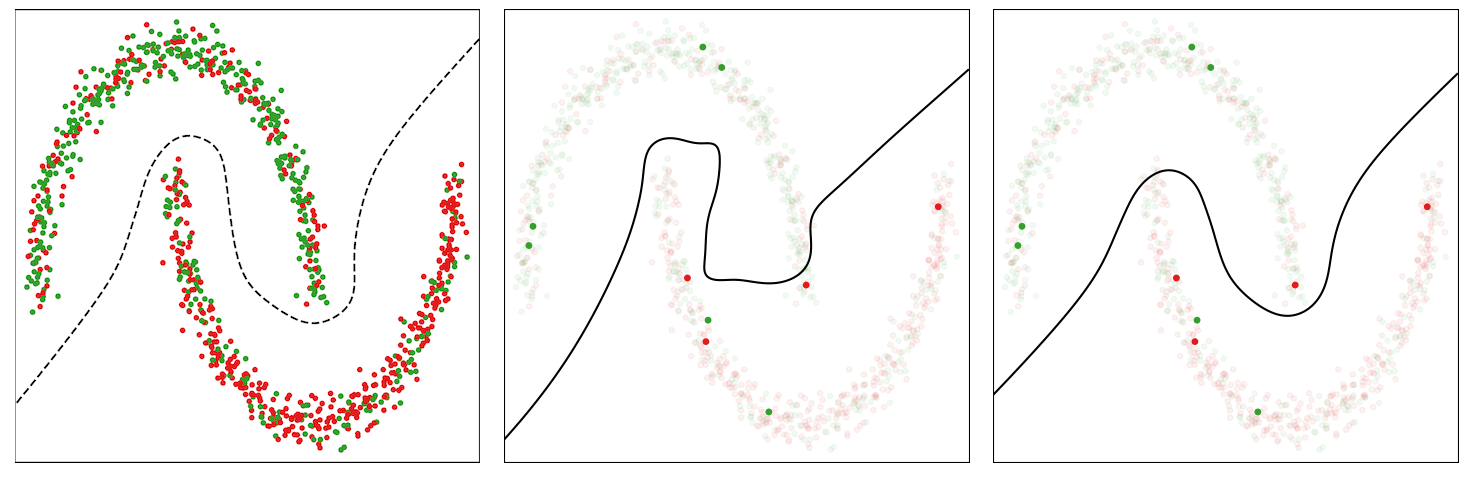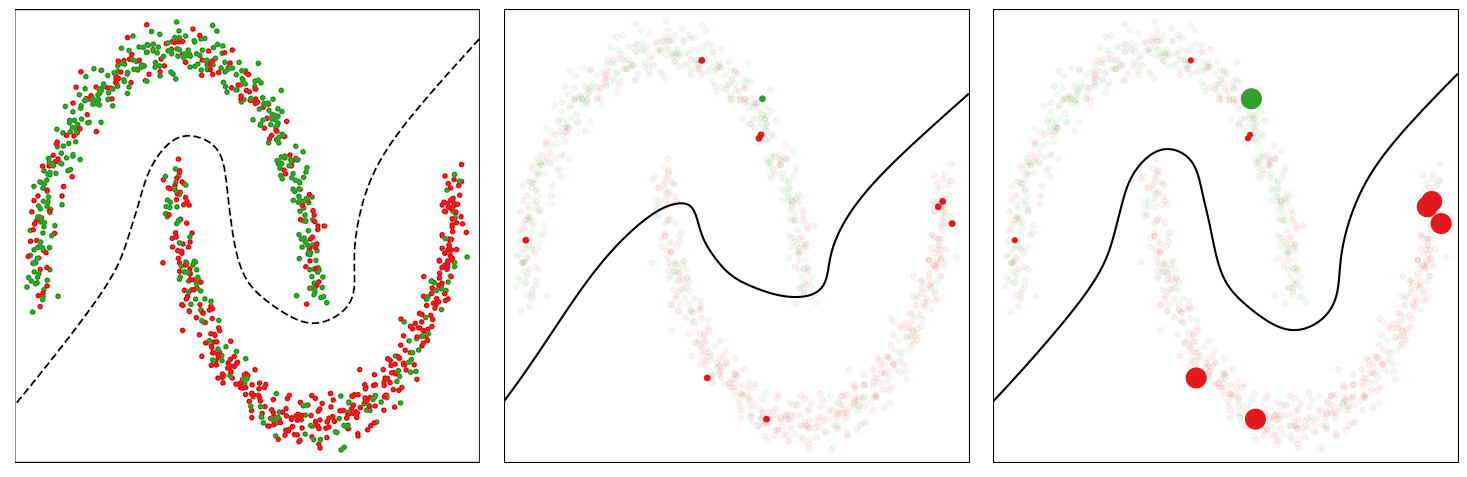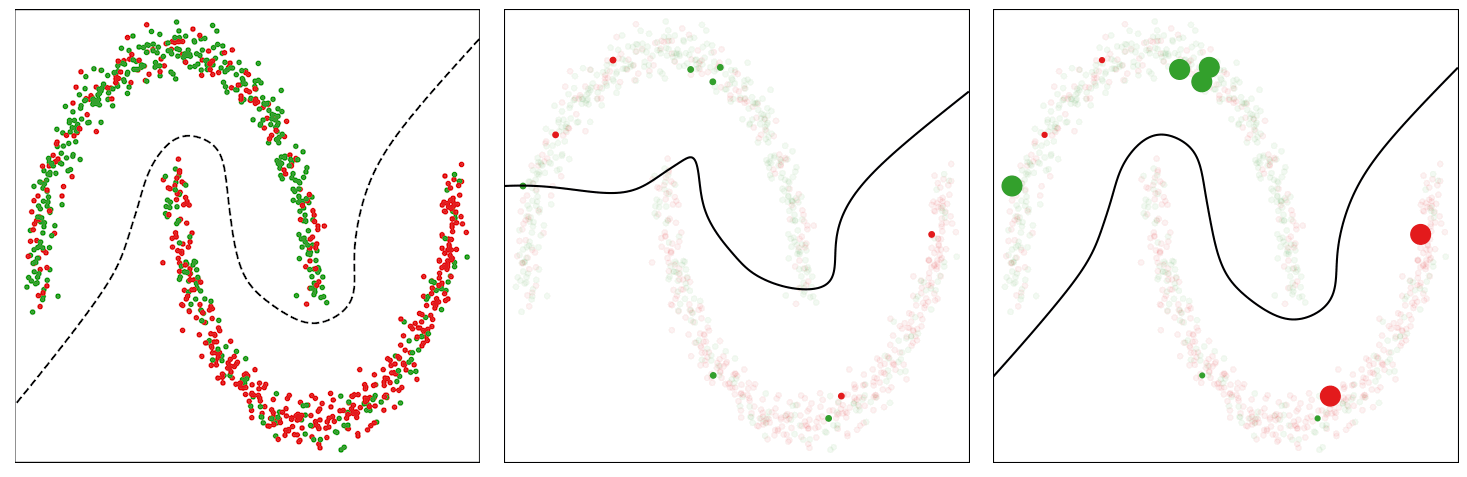 |
| Illustration of resolution boundary because the coaching proceeds for the baseline and the proposed CIW technique on the Two Moons dataset. Left: Noisy dataset with a fascinating resolution boundary. Center: Resolution boundary for normal coaching with cross-entropy loss. Proper: Coaching with the CIW technique. The dimensions of the dots in (center) and (proper) are proportional to the significance weights assigned to those examples within the minibatch. |
Constrained Class reWeighting
Occasion reweighting assigns decrease weights to cases with larger losses. We additional prolong this instinct to assign significance weights over all doable class labels. Customary coaching makes use of a one-hot label vector as the category weights, assigning a weight of 1 to the labeled class and 0 to all different lessons. Nevertheless, for the possibly mislabeled cases, it’s cheap to assign non-zero weights to lessons that could possibly be the true label. We receive these class weights as options to a household of constrained optimization issues the place the deviation of the category weights from the label one-hot distribution, as measured by a divergence of selection, is managed by a hyperparameter.
Once more, for a number of divergence measures, we will receive easy formulae for the category weights. We check with this as Constrained Occasion and Class reWeighting (CICW). The answer to this optimization drawback additionally recovers the earlier proposed strategies based mostly on static label bootstrapping (additionally referred as label smoothing) when the divergence is taken to be complete variation distance. This gives a theoretical perspective on the favored technique of static label bootstrapping.
Utilizing Occasion Weights with Mixup
We additionally suggest a means to make use of the obtained occasion weights with mixup, which is a common technique for regularizing fashions and bettering prediction efficiency. It really works by sampling a pair of examples from the unique dataset and producing a brand new synthetic instance utilizing a random convex mixture of those. The mannequin is educated by minimizing the loss on these mixed-up knowledge factors. Vanilla mixup is oblivious to the person occasion losses, which could be problematic for noisy knowledge as a result of mixup will deal with clear and noisy examples equally. Since a excessive occasion weight obtained with our CIW technique is extra more likely to point out a clear instance, we use our occasion weights to do a biased sampling for mixup and likewise use the weights in convex mixtures (as an alternative of random convex mixtures in vanilla mixup). This ends in biasing the mixed-up examples in the direction of clear knowledge factors, which we check with as CICW-Mixup.
We apply these strategies with various quantities of artificial noise (i.e., the label for every occasion is randomly flipped to different labels) on the usual CIFAR-10 and CIFAR-100 benchmark datasets. We present the take a look at accuracy on clear knowledge with symmetric artificial noise the place the noise charge is diverse between 0.2 and 0.8.
We observe that the proposed CICW outperforms a number of strategies and matches the outcomes of dynamic mixup, which maintains the significance weights over the total coaching set with mixup. Utilizing our significance weights with mixup in CICW-M, resulted in considerably improved efficiency vs these strategies, significantly for bigger noise charges (as proven by strains above and to the appropriate within the graphs under).
Abstract and Future Instructions
We formulate a novel household of constrained optimization issues for tackling label noise that yield easy mathematical formulae for reweighting the coaching cases and sophistication labels. These formulations additionally present a theoretical perspective on present label smoothing–based mostly strategies for studying with noisy labels. We additionally suggest methods for utilizing the occasion weights with mixup that ends in additional vital efficiency positive factors over occasion and sophistication reweighting. Our technique operates solely on the stage of mini-batches, which avoids the additional overhead of sustaining dataset-level weights as in a few of the current strategies.
As a route for future work, we wish to consider the strategy on practical noisy labels which might be encountered in giant scale sensible settings. We additionally imagine that finding out the interplay of our framework with label smoothing is an fascinating route that can lead to a loss adaptive model of label smoothing. We’re additionally excited to launch the code for CICW, now obtainable on Github.
Acknowledgements
We might wish to thank Kevin Murphy for offering constructive suggestions throughout the course of the venture.
[ad_2]

