



[ad_1]
In my final article, we analyzed our backlinks utilizing information from Ahrefs.
This time round, we’re together with the competitor backlinks in our evaluation utilizing the identical Ahrefs information supply for comparability.
Like final time, we outlined the worth of a website’s backlinks for search engine marketing as a product of high quality and amount.
High quality is area authority (or Ahrefs’ equal area score) and amount is the variety of referring domains.
Once more, we’ll consider the hyperlink high quality with the accessible information earlier than evaluating the amount.
Time to code.
import re
import time
import random
import pandas as pd
import numpy as np
import datetime
from datetime import timedelta
from plotnine import *
import matplotlib.pyplot as plt
from pandas.api.varieties import is_string_dtype
from pandas.api.varieties import is_numeric_dtype
import uritools

pd.set_option('show.max_colwidth', None)
%matplotlib inline
root_domain = 'johnsankey.co.uk'
hostdomain = 'www.johnsankey.co.uk'
hostname="johnsankey"
full_domain = 'https://www.johnsankey.co.uk'
target_name="John Sankey"
Knowledge Import & Cleansing
We arrange the file directories to learn a number of Ahrefs exported information recordsdata in a single folder, which is way sooner, much less boring, and extra environment friendly than studying every file individually.
Particularly when you’ve gotten greater than 10 of them!
ahrefs_path="information/"
The listdir( ) operate from the OS module permits us to listing all recordsdata in a subdirectory.
ahrefs_filenames = os.listdir(ahrefs_path)
ahrefs_filenames.take away('.DS_Store')
ahrefs_filenames

File names now listed beneath:

['www.davidsonlondon.com--refdomains-subdomain__2022-03-13_23-37-29.csv',
 'www.stephenclasper.co.uk--refdomains-subdoma__2022-03-13_23-47-28.csv',
 'www.touchedinteriors.co.uk--refdomains-subdo__2022-03-13_23-42-05.csv',
 'www.lushinteriors.co--refdomains-subdomains__2022-03-13_23-44-34.csv',
 'www.kassavello.com--refdomains-subdomains__2022-03-13_23-43-19.csv',
 'www.tulipinterior.co.uk--refdomains-subdomai__2022-03-13_23-41-04.csv',
 'www.tgosling.com--refdomains-subdomains__2022-03-13_23-38-44.csv',
 'www.onlybespoke.com--refdomains-subdomains__2022-03-13_23-45-28.csv',
 'www.williamgarvey.co.uk--refdomains-subdomai__2022-03-13_23-43-45.csv',
 'www.hadleyrose.co.uk--refdomains-subdomains__2022-03-13_23-39-31.csv',
 'www.davidlinley.com--refdomains-subdomains__2022-03-13_23-40-25.csv',
 'johnsankey.co.uk-refdomains-subdomains__2022-03-18_15-15-47.csv']
With the recordsdata listed, we’ll now learn each individually utilizing a for loop, and add these to a dataframe.
Whereas studying within the file we’ll use some string manipulation to create a brand new column with the positioning identify of the information we’re importing.
ahrefs_df_lst = listing()
ahrefs_colnames = listing()

for filename in ahrefs_filenames:
    df = pd.read_csv(ahrefs_path + filename)
    df['site'] = filename
    df['site'] = df['site'].str.change('www.', '', regex = False)
    df['site'] = df['site'].str.change('.csv', '', regex = False)
    df['site'] = df['site'].str.change('-.+', '', regex = True)
    ahrefs_colnames.append(df.columns)
    ahrefs_df_lst.append(df)

ahrefs_df_raw = pd.concat(ahrefs_df_lst)
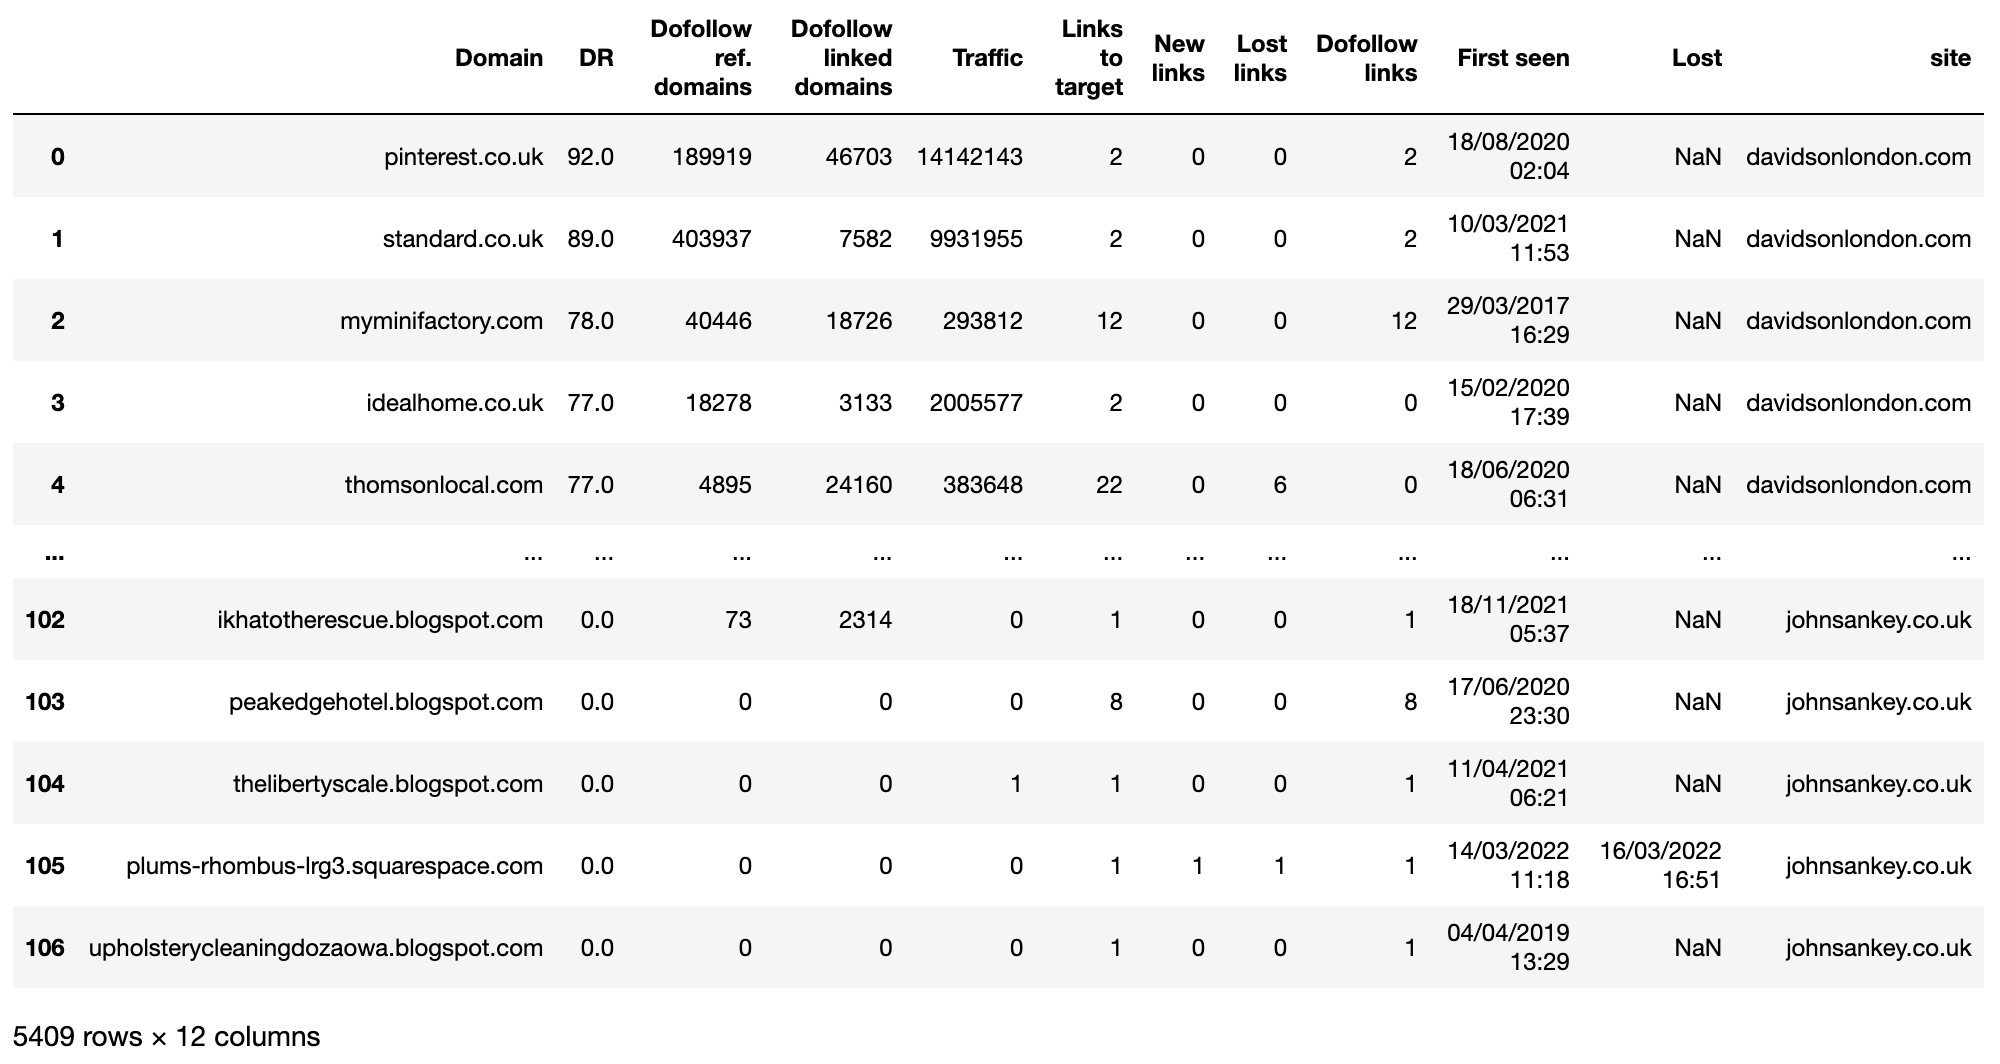
ahrefs_df_raw
Picture from Ahrefs, Could 2022
Now now we have the uncooked information from every website in a single dataframe. The subsequent step is to tidy up the column names and make them a bit friendlier to work with.
Though the repetition could possibly be eradicated with a customized operate or a listing comprehension, it’s good follow and simpler for newbie search engine marketing Pythonistas to see what’s occurring step-by-step. As they are saying, “repetition is the mom of mastery,” so get training!
competitor_ahrefs_cleancols = ahrefs_df_raw
competitor_ahrefs_cleancols.columns = [col.lower() for col in competitor_ahrefs_cleancols.columns]
competitor_ahrefs_cleancols.columns = [col.replace(' ','_') for col in competitor_ahrefs_cleancols.columns]
competitor_ahrefs_cleancols.columns = [col.replace('.','_') for col in competitor_ahrefs_cleancols.columns]
competitor_ahrefs_cleancols.columns = [col.replace('__','_') for col in competitor_ahrefs_cleancols.columns]
competitor_ahrefs_cleancols.columns = [col.replace('(','') for col in competitor_ahrefs_cleancols.columns]
competitor_ahrefs_cleancols.columns = [col.replace(')','') for col in competitor_ahrefs_cleancols.columns]
competitor_ahrefs_cleancols.columns = [col.replace('%','') for col in competitor_ahrefs_cleancols.columns]
The depend column and having a single worth column (‘mission’) are helpful for groupby and aggregation operations.
competitor_ahrefs_cleancols['rd_count'] = 1
competitor_ahrefs_cleancols['project'] = target_name

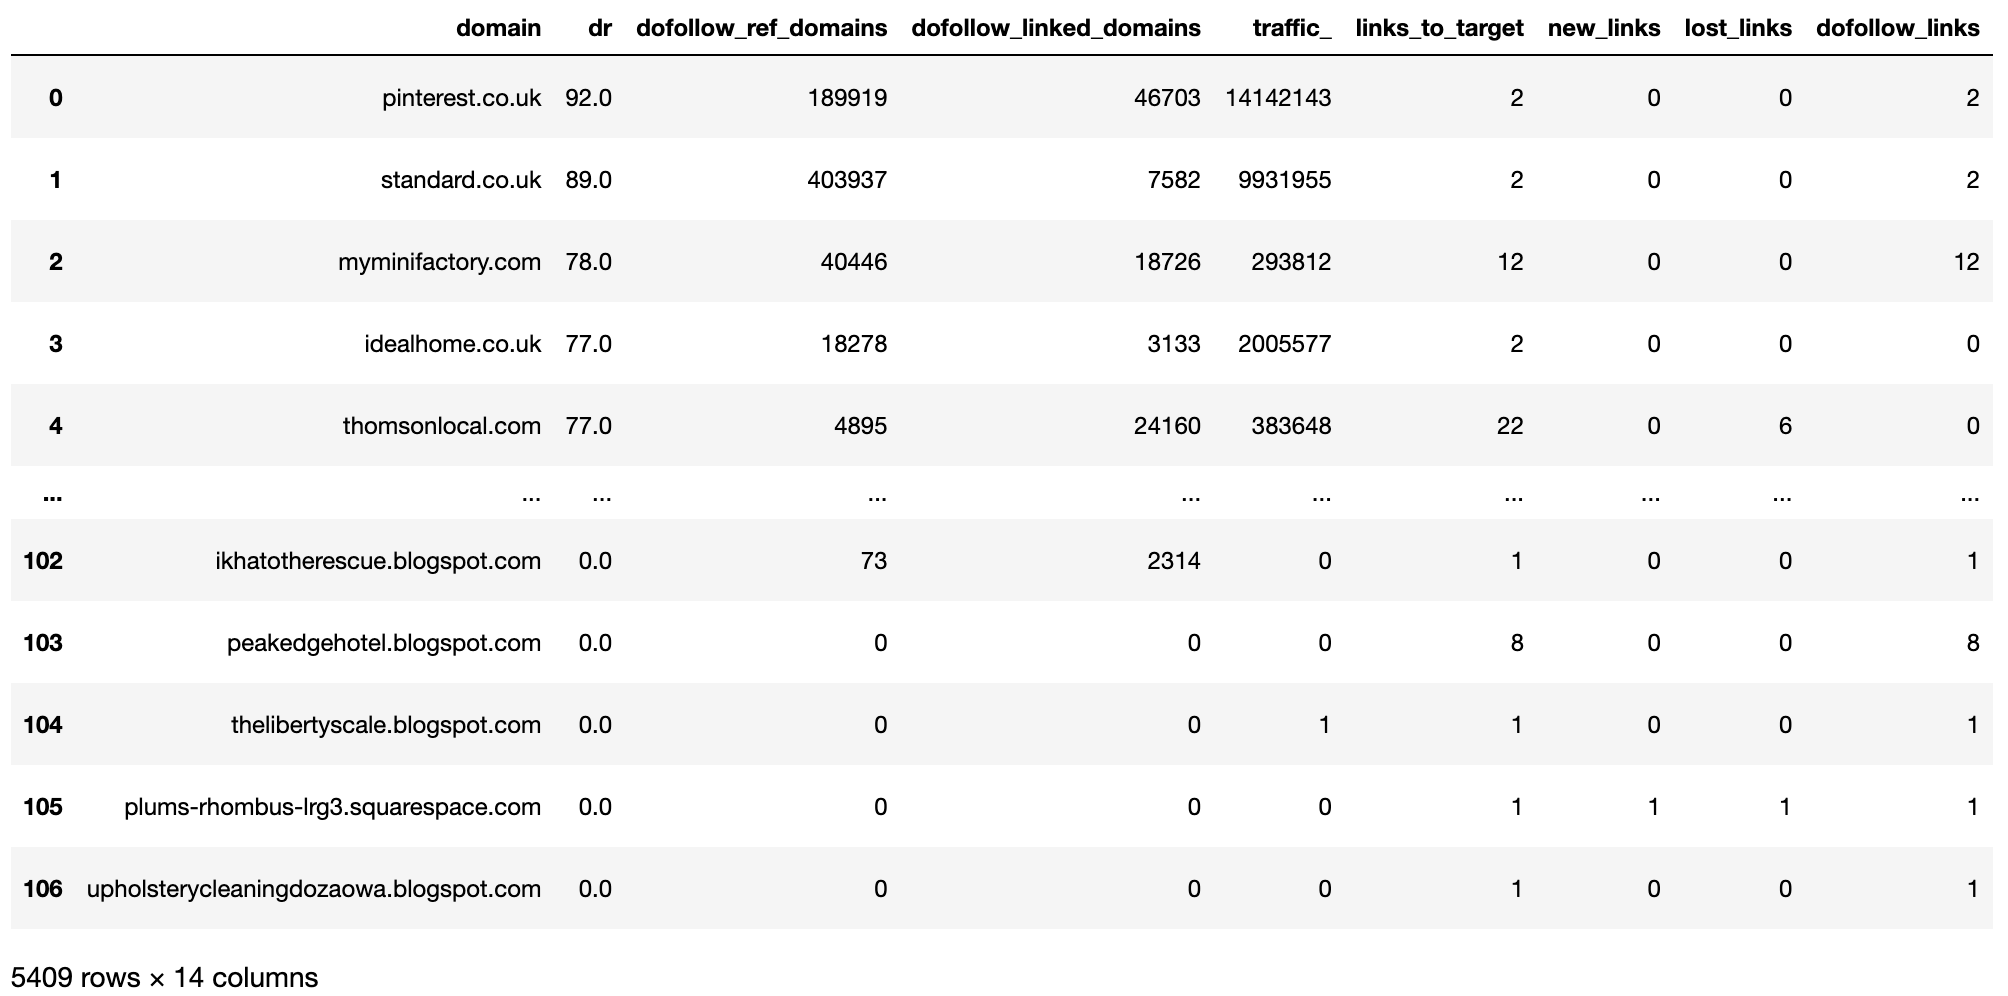
competitor_ahrefs_cleancols
 Picture from Ahrefs, Could 2022
The columns are cleaned up, so now we’ll clear up the row information.
competitor_ahrefs_clean_dtypes = competitor_ahrefs_cleancols
For referring domains, we’re changing hyphens with zero and setting the information kind as an integer (i.e., entire quantity).
This will probably be repeated for linked domains, additionally.
competitor_ahrefs_clean_dtypes['dofollow_ref_domains'] = np.the place(competitor_ahrefs_clean_dtypes['dofollow_ref_domains'] == '-',
                                                           0, competitor_ahrefs_clean_dtypes['dofollow_ref_domains'])
competitor_ahrefs_clean_dtypes['dofollow_ref_domains'] = competitor_ahrefs_clean_dtypes['dofollow_ref_domains'].astype(int)


# linked_domains

competitor_ahrefs_clean_dtypes['dofollow_linked_domains'] = np.the place(competitor_ahrefs_clean_dtypes['dofollow_linked_domains'] == '-',
                                                           0, competitor_ahrefs_clean_dtypes['dofollow_linked_domains'])
competitor_ahrefs_clean_dtypes['dofollow_linked_domains'] = competitor_ahrefs_clean_dtypes['dofollow_linked_domains'].astype(int)
First seen offers us a date level at which hyperlinks had been discovered, which we are able to use for time collection plotting and deriving the hyperlink age.
We’ll convert so far format utilizing the to_datetime operate.
# first_seen
competitor_ahrefs_clean_dtypes['first_seen'] = pd.to_datetime(competitor_ahrefs_clean_dtypes['first_seen'],
                                                              format="%d/%m/%Y %H:%M")
competitor_ahrefs_clean_dtypes['first_seen'] = competitor_ahrefs_clean_dtypes['first_seen'].dt.normalize()
competitor_ahrefs_clean_dtypes['month_year'] = competitor_ahrefs_clean_dtypes['first_seen'].dt.to_period('M')
To calculate the link_age we’ll merely deduct the primary seen date from right this moment’s date and convert the distinction right into a quantity.
# hyperlink age
competitor_ahrefs_clean_dtypes['link_age'] = dt.datetime.now() - competitor_ahrefs_clean_dtypes['first_seen']
competitor_ahrefs_clean_dtypes['link_age'] = competitor_ahrefs_clean_dtypes['link_age']
competitor_ahrefs_clean_dtypes['link_age'] = competitor_ahrefs_clean_dtypes['link_age'].astype(int)
competitor_ahrefs_clean_dtypes['link_age'] = (competitor_ahrefs_clean_dtypes['link_age']/(3600 * 24 * 1000000000)).spherical(0)
The goal column helps us distinguish the “consumer” website vs opponents which is helpful for visualization later.
competitor_ahrefs_clean_dtypes['target'] = np.the place(competitor_ahrefs_clean_dtypes['site'].str.accommodates('johns'),
                                                                                            1, 0)
competitor_ahrefs_clean_dtypes['target'] = competitor_ahrefs_clean_dtypes['target'].astype('class')

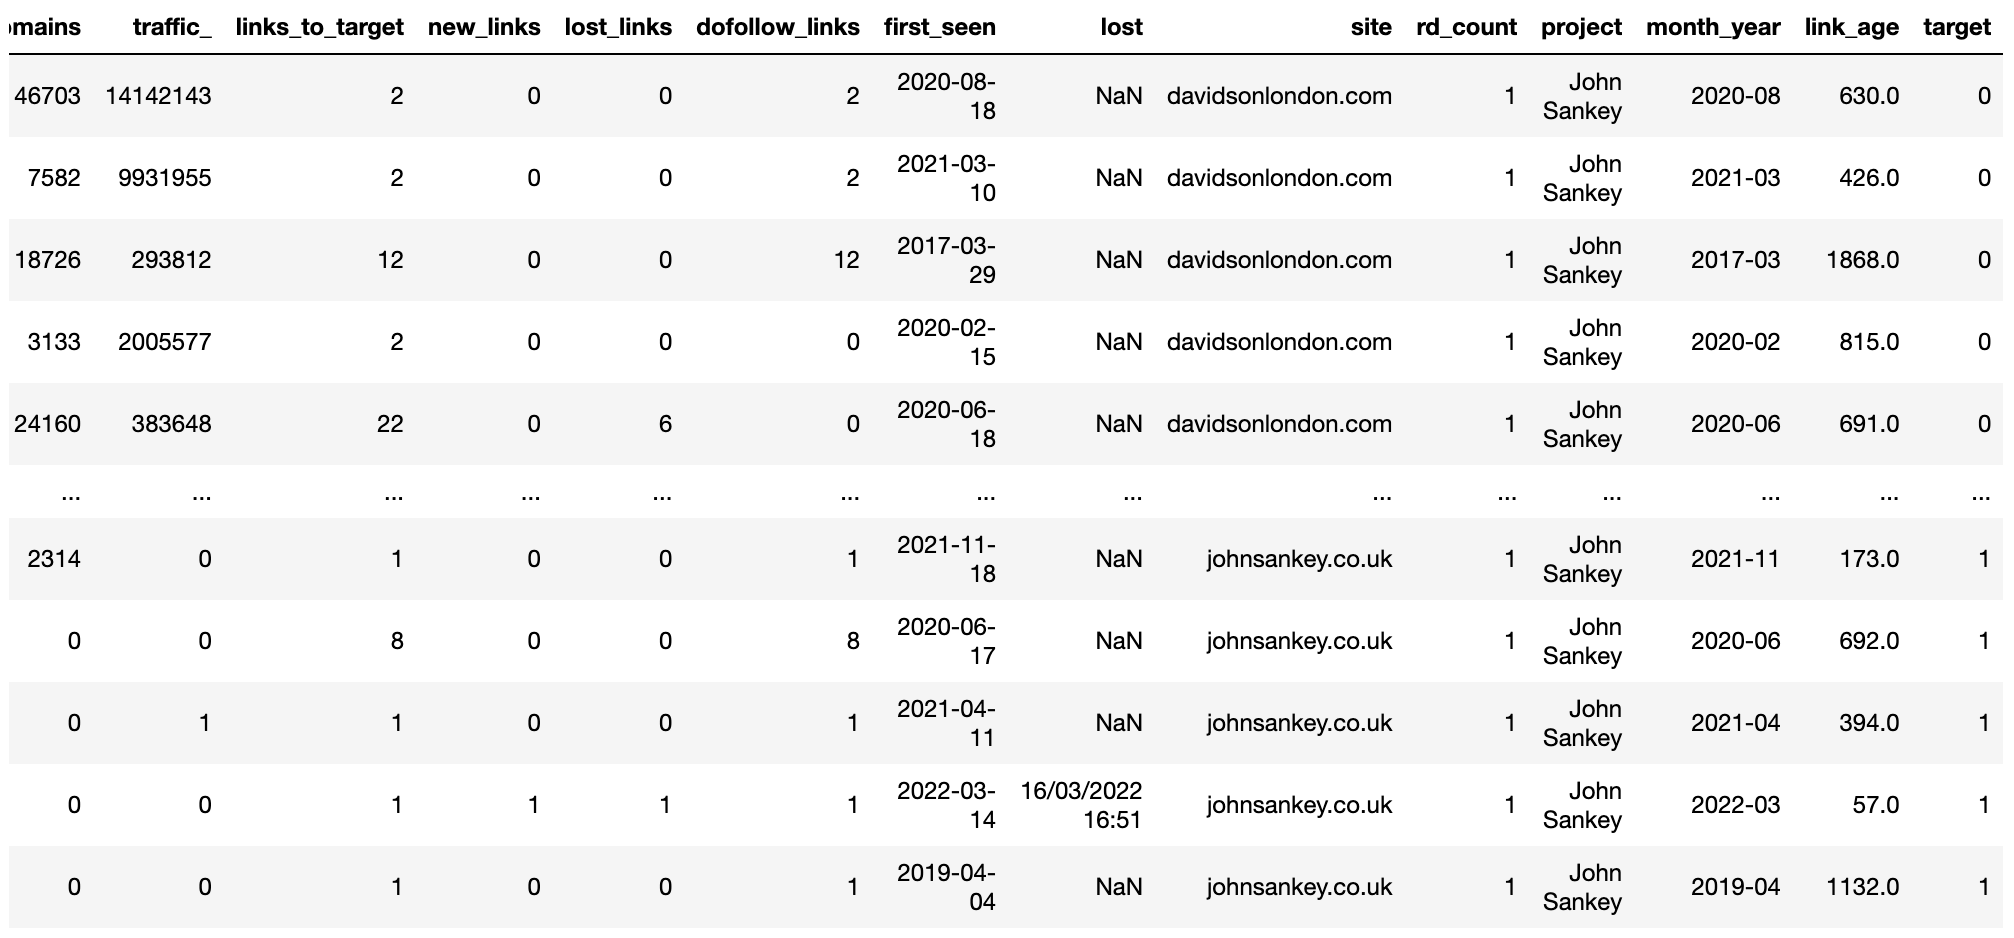
competitor_ahrefs_clean_dtypes
 Picture from Ahrefs, Could 2022
Now that the information is cleaned up each when it comes to column titles and row values we’re able to set forth and begin analyzing.
Hyperlink High quality
We begin with Hyperlink High quality which we’ll settle for Area Score (DR) because the measure.
Let’s begin by inspecting the distributive properties of DR by plotting their distribution utilizing the geom_bokplot operate.
comp_dr_dist_box_plt = (
    ggplot(competitor_ahrefs_analysis.loc[competitor_ahrefs_analysis['dr'] > 0],
           aes(x = 'reorder(website, dr)', y = 'dr', color="goal")) +
    geom_boxplot(alpha = 0.6) +
    scale_y_continuous() +
    theme(legend_position = 'none',
          axis_text_x=element_text(rotation=90, hjust=1)
         ))

comp_dr_dist_box_plt.save(filename="photos/4_comp_dr_dist_box_plt.png",
                           peak=5, width=10, items="in", dpi=1000)
comp_dr_dist_box_plt
 Picture from Ahrefs, Could 2022
The plot compares the positioning’s statistical properties aspect by aspect, and most notably, the interquartile vary exhibiting the place most referring domains fall when it comes to area score.
We additionally see that John Sankey has the fourth-highest median area score, which compares effectively with hyperlink high quality in opposition to different websites.
William Garvey has probably the most numerous vary of DR in contrast with different domains, indicating ever so barely extra relaxed standards for hyperlink acquisition. Who is aware of.
Hyperlink Volumes
That’s high quality. What concerning the quantity of hyperlinks from referring domains?
To deal with that, we’ll compute a operating sum of referring domains utilizing the groupby operate.
competitor_count_cumsum_df = competitor_ahrefs_analysis

competitor_count_cumsum_df = competitor_count_cumsum_df.groupby(['site', 'month_year'])['rd_count'].sum().reset_index()
The increasing operate permits the calculation window to develop with the variety of rows which is how we obtain our operating sum.
competitor_count_cumsum_df['count_runsum'] = competitor_count_cumsum_df['rd_count'].increasing().sum()

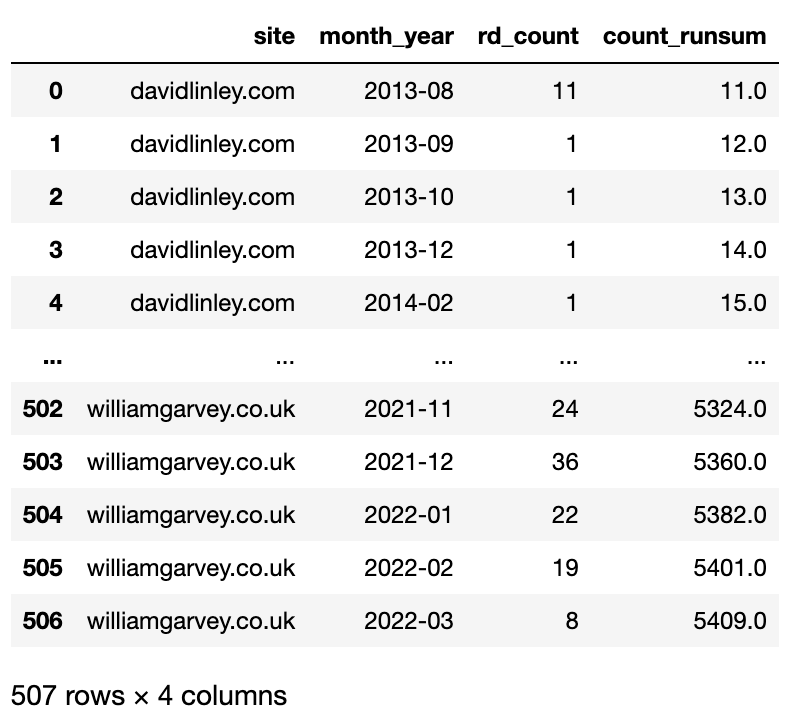
competitor_count_cumsum_df
 Picture from Ahrefs, Could 2022
The result’s a knowledge body with the positioning, month_year and count_runsum (the operating sum), which is within the excellent format to feed the graph.
competitor_count_cumsum_plt = (
    ggplot(competitor_count_cumsum_df, aes(x = 'month_year', y = 'count_runsum',
                                           group = 'website', color="website")) +
    geom_line(alpha = 0.6, dimension = 2) +
    labs(y = 'Working Sum of Referring Domains', x = 'Month 12 months') +
    scale_y_continuous() +
    scale_x_date() +
    theme(legend_position = 'proper',
          axis_text_x=element_text(rotation=90, hjust=1)
         ))
competitor_count_cumsum_plt.save(filename="photos/5_count_cumsum_smooth_plt.png",
                           peak=5, width=10, items="in", dpi=1000)

competitor_count_cumsum_plt
 Picture from Ahrefs, Could 2022
The plot reveals the variety of referring domains for every website since 2014.
I discover fairly attention-grabbing the totally different beginning positions for every website after they begin buying hyperlinks.
For instance, William Garvey began with over 5,000 domains. I’d like to know who their PR company is!
We will additionally see the speed of development. For instance, though Hadley Rose began hyperlink acquisition in 2018, issues actually took off round mid-2021.
Extra, Extra, And Extra
You may at all times do extra scientific evaluation.
For instance, one quick and pure extension of the above can be to mix each the standard (DR) and the amount (quantity) for a extra holistic view of how the websites examine when it comes to offsite search engine marketing.
Different extensions can be to mannequin the qualities of these referring domains for each your individual and your competitor websites to see which hyperlink options (such because the variety of phrases or relevance of the linking content material) might clarify the distinction in visibility between you and your opponents.
This mannequin extension can be a great software of these machine studying methods.
Extra sources:
Featured Picture: F8 studio/Shutterstock
[ad_2]

