


[ad_1]
Final Up to date on February 26, 2022
Engaged on a machine studying venture means we have to experiment. Having a approach to configure your script simply will provide help to transfer sooner. In Python, we have now a approach to adapt the code from command line. On this tutorial, we’re going to see how we are able to leverage the command line arguments to a Python script that will help you work higher in your machine studying venture.
After ending this tutorial, you’ll be taught
- Why we wish to management a Python script in command line
- How we are able to work in a command line effectively
Let’s get began.
Command line arguments to your Python script. Picture by insung yoon. Some rights reserved
Overview
This tutorial is in three components, they’re
- Operating a Python script in command line
- Engaged on the command line
- Various to command line arguments
Operating a Python script in command line
There are numerous methods to run a Python script. Somebody could run it as a part of a Jupyter pocket book. Somebody could run it in an IDE. However in all platforms, it’s at all times doable to run a Python script in command line. In Home windows, you may have the command immediate or PowerShell (and even higher, the Home windows Terminal). In macOS or Linux, you may have the Terminal or xterm. Operating a Python script in command line is highly effective as a result of you possibly can cross in extra parameter to the script.
The next script permits us to cross in values from the command line into Python:
|
import sys
n = int(sys.argv[1]) print(n+1) |
Once we save these few traces right into a file, and run it in command line with an argument:
|
$ python commandline.py 15 16 |
you will note it takes our argument, convert it into integer, add one into it and print. The checklist sys.argv comprises the identify of our script and all of the arguments (all strings), which within the above case, it’s ["commandline.py", "15"].
Once you run a command line with extra difficult set of arguments, it takes some effort to course of the checklist sys.argv. Subsequently Python offered the library argparse to assist. That is to imagine GNU-style, which will be defined utilizing the next instance:
|
rsync -a -v –exclude=”*.pyc” -B 1024 –ignore-existing 192.168.0.3:/tmp/ ./ |
The optionally available arguments are launched by “-” or “--“, which a single hyphen is to hold a single character “quick possibility” (resembling -a, -B and -v above), and two hyphens are for a number of characters “lengthy choices” (resembling --exclude and --ignore-existing above). The optionally available arguments could have extra parameters, resembling in -B 1024 or --exclude="*.pyc", the 1024 and "*.pyc" are parameters to -B and --exclude respectively. Moreover, we can also have obligatory arguments, which we simply put them into the command line. The half 192.168.0.3:/tmp/ and ./ above are examples. The order of obligatory arguments are necessary. For instance, the rsync command above will copy recordsdata from 192.168.0.3:/tmp/ to ./ as an alternative of the opposite manner spherical.
The next is to duplicate the above instance in Python utilizing argparse:
|
import argparse
parser = argparse.ArgumentParser(description=“Simply an instance”, formatter_class=argparse.ArgumentDefaultsHelpFormatter) parser.add_argument(“-a”, “–archive”, motion=“store_true”, assist=“archive mode”) parser.add_argument(“-v”, “–verbose”, motion=“store_true”, assist=“improve verbosity”) parser.add_argument(“-B”, “–block-size”, assist=“checksum blocksize”) parser.add_argument(“–ignore-existing”, motion=“store_true”, assist=“skip recordsdata that exist”) parser.add_argument(“–exclude”, assist=“recordsdata to exclude”) parser.add_argument(“src”, assist=“Supply location”) parser.add_argument(“dest”, assist=“Vacation spot location”) args = parser.parse_args() config = vars(args) print(config) |
For those who run the above script, you will note:
|
$ python argparse_example.py utilization: argparse_example.py [-h] [-a] [-v] [-B BLOCK_SIZE] [–ignore-existing] [–exclude EXCLUDE] src dest argparse_example.py: error: the next arguments are required: src, dest |
That is to imply you didn’t present the obligatory arguments for src and dest. Maybe the most effective cause to make use of argparse is to get a assist display screen totally free should you provded -h or --help because the argument, like the next:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 |
$ python argparse_example.py –help utilization: argparse_example.py [-h] [-a] [-v] [-B BLOCK_SIZE] [–ignore-existing] [–exclude EXCLUDE] src dest
Simply an instance
positional arguments: src Supply location dest Vacation spot location
optionally available arguments: -h, –help present this assist message and exit -a, –archive archive mode (default: False) -v, –verbose improve verbosity (default: False) -B BLOCK_SIZE, –block-size BLOCK_SIZE checksum blocksize (default: None) –ignore-existing skip recordsdata that exist (default: False) –exclude EXCLUDE recordsdata to exclude (default: None) |
Whereas the script did nothing actual, should you offered the arguments as required, you will note this:
|
$ python argparse_example.py -a –ignore-existing 192.168.0.1:/tmp/ /house {‘archive’: True, ‘verbose’: False, ‘block_size’: None, ‘ignore_existing’: True, ‘exclude’: None, ‘src’: ‘192.168.0.1:/tmp/’, ‘dest’: ‘/house’} |
The parser object created by ArgumentParser() has a parse_args() technique that reads sys.argv and returns a namespace object. That is an object that carries attributes and we are able to learn utilizing args.ignore_existing for instance. However often it’s simpler to deal with if it’s a Python dictionary. Therefore we are able to convert it into one utilizing vars(args).
Normally for all optionally available arguments, we offer the lengthy possibility and generally additionally the quick possibility. Then we are able to entry the worth offered from the command line utilizing the lengthy possibility as the important thing (with hyphen changed with underscore, or the single-character quick possibility as the important thing if we don’t have an extended model). The “positional arguments” will not be optionally available and their names are offered within the add_argument() perform.
There are a number of sorts of arguments. For the optionally available arguments, generally we use them as a boolean flags however generally we count on them to herald some knowledge. Within the above, we use motion="store_true" to make that possibility set to False by default and toggle to True whether it is specified. For the opposite possibility resembling -B above, by default it expects extra knowledge to go following it.
We are able to additional require an argument to be a particular kind. For instance the -B possibility above, we are able to make it to count on integer knowledge by including kind like the next
|
parser.add_argument(“-B”, “–block-size”, kind=int, assist=“checksum blocksize”) |
and if we offered the mistaken kind, argparse will assist terminate our program with an informative error message:
|
python argparse_example.py -a -B hi there –ignore-existing 192.168.0.1:/tmp/ /house utilization: argparse_example.py [-h] [-a] [-v] [-B BLOCK_SIZE] [–ignore-existing] [–exclude EXCLUDE] src dest argparse_example.py: error: argument -B/–block-size: invalid int worth: ‘hi there’ |
Engaged on the command line
Empowering your Python script with command line arguments can convey it to a brand new stage of reusability. First, let’s take a look at a easy instance on becoming an ARIMA mannequin to GDP time collection. World Financial institution collected historic GDP knowledge of many international locations. We are able to make use of the pandas_datareader bundle to learn the info. For those who haven’t put in it but, you need to use pip (or conda should you put in Anacronda) to put in the bundle:
|
pip set up pandas_datareader |
The code for the GDP knowledge that we use is NY.GDP.MKTP.CN, we are able to get the info of a rustic within the type of a pandas DataFrame by
|
from pandas_datareader.wb import WorldBankReader
gdp = WorldBankReader(“NY.GDP.MKTP.CN”, “SE”, begin=1960, finish=2020).learn() |
after which we are able to tidy up the DataFrame a bit utilizing the instruments offered by pandas:
|
import pandas as pd
# Drop nation identify from index gdp = gdp.droplevel(stage=0, axis=0) # Type knowledge in choronological order and set knowledge level at year-end gdp.index = pd.to_datetime(gdp.index) gdp = gdp.sort_index().resample(“y”).final() # Convert pandas DataFrame into pandas Sequence gdp = gdp[“NY.GDP.MKTP.CN”] |
then becoming an ARIMA mannequin and use the mannequin for prediction is just not troublesome. Within the following, we match utilizing the primary 40 knowledge factors and forecast for subsequent 3. Then evaluate the forecast with the precise by way of relative error:
|
import statsmodels.api as sm
mannequin = sm.tsa.ARIMA(endog=gdp[:40], order=(1,1,1)).match() forecast = mannequin.forecast(steps=3) evaluate = pd.DataFrame({“precise”:gdp, “forecast”:forecast}).dropna() evaluate[“rel error”] = (evaluate[“forecast”] – evaluate[“actual”])/evaluate[“actual”] print(evaluate) |
Placing all of it collectively, and just a little sprucing, the next is the entire code:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 |
import warnings warnings.simplefilter(“ignore”)
from pandas_datareader.wb import WorldBankReader import statsmodels.api as sm import pandas as pd
collection = “NY.GDP.MKTP.CN” nation = “SE” # Sweden size = 40 begin = 0 steps = 3 order = (1,1,1)
# Learn the GDP knowledge from WorldBank database gdp = WorldBankReader(collection, nation, begin=1960, finish=2020).learn() # Drop nation identify from index gdp = gdp.droplevel(stage=0, axis=0) # Type knowledge in choronological order and set knowledge level at year-end gdp.index = pd.to_datetime(gdp.index) gdp = gdp.sort_index().resample(“y”).final() # Convert pandas dataframe into pandas collection gdp = gdp[series] # Match arima mannequin consequence = sm.tsa.ARIMA(endog=gdp[start:start+length], order=order).match() # Forecast, and calculate the relative error forecast = consequence.forecast(steps=steps) df = pd.DataFrame({“Precise”:gdp, “Forecast”:forecast}).dropna() df[“Rel Error”] = (df[“Forecast”] – df[“Actual”]) / df[“Actual”] # Print consequence with pd.option_context(‘show.max_rows’, None, ‘show.max_columns’, 3): print(df) |
This script prints the next output
|
Precise Forecast Rel Error 2000-12-31 2408151000000 2.367152e+12 -0.017025 2001-12-31 2503731000000 2.449716e+12 -0.021574 2002-12-31 2598336000000 2.516118e+12 -0.031643 |
The above code is brief however we made it versatile sufficient by holding some parameters in variables. We are able to change the above code to make use of argparse so we are able to change some parameters from the command line, as follows:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 |
from argparse import ArgumentParser, ArgumentDefaultsHelpFormatter import warnings warnings.simplefilter(“ignore”)
from pandas_datareader.wb import WorldBankReader import statsmodels.api as sm import pandas as pd
# Parse command line arguments parser = ArgumentParser(formatter_class=ArgumentDefaultsHelpFormatter) parser.add_argument(“-c”, “–country”, default=“SE”, assist=“Two-letter nation code”) parser.add_argument(“-l”, “–length”, default=40, kind=int, assist=“Size of time collection to suit the ARIMA mannequin”) parser.add_argument(“-s”, “–start”, default=0, kind=int, assist=“Beginning offset to suit the ARIMA mannequin”) args = vars(parser.parse_args())
# Arrange parameters collection = “NY.GDP.MKTP.CN” nation = args[“country”] size = args[“length”] begin = args[“start”] steps = 3 order = (1,1,1)
# Learn the GDP knowledge from WorldBank database gdp = WorldBankReader(collection, nation, begin=1960, finish=2020).learn() # Drop nation identify from index gdp = gdp.droplevel(stage=0, axis=0) # Type knowledge in choronological order and set knowledge level at year-end gdp.index = pd.to_datetime(gdp.index) gdp = gdp.sort_index().resample(“y”).final() # Convert pandas dataframe into pandas collection gdp = gdp[series] # Match arima mannequin consequence = sm.tsa.ARIMA(endog=gdp[start:start+length], order=order).match() # Forecast, and calculate the relative error forecast = consequence.forecast(steps=steps) df = pd.DataFrame({“Precise”:gdp, “Forecast”:forecast}).dropna() df[“Rel Error”] = (df[“Forecast”] – df[“Actual”]) / df[“Actual”] # Print consequence with pd.option_context(‘show.max_rows’, None, ‘show.max_columns’, 3): print(df) |
If we run the code above in a command line, we are able to see it could now settle for arguments:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 |
$ python gdp_arima.py –help utilization: gdp_arima.py [-h] [-c COUNTRY] [-l LENGTH] [-s START]
optionally available arguments: -h, –help present this assist message and exit -c COUNTRY, –country COUNTRY Two-letter nation code (default: SE) -l LENGTH, –length LENGTH Size of time collection to suit the ARIMA mannequin (default: 40) -s START, –start START Beginning offset to suit the ARIMA mannequin (default: 0) $ python gdp_arima.py Precise Forecast Rel Error 2000-12-31 2408151000000 2.367152e+12 -0.017025 2001-12-31 2503731000000 2.449716e+12 -0.021574 2002-12-31 2598336000000 2.516118e+12 -0.031643 $ python gdp_arima.py -c NO Precise Forecast Rel Error 2000-12-31 1507283000000 1.337229e+12 -0.112821 2001-12-31 1564306000000 1.408769e+12 -0.099429 2002-12-31 1561026000000 1.480307e+12 -0.051709 |
Within the final command above, we cross in -c NO to use the identical mannequin to the GDP knowledge of Norway (NO) as an alternative of Sweden (SE). Therefore, with out the chance of messing up the code, we reused our code to a distinct dataset.
The ability of introducing command line argument is that we are able to check out our code with various parameters simply. For instance, we wish to see if ARIMA(1,1,1) mannequin is an efficient mannequin for predicting GDP and we wish to confirm with completely different time window of the nordic international locations:
- Denmark (DK)
- Finland (FI)
- Iceland (IS)
- Norway (NO)
- Sweden (SE)
We wish to verify for the window of 40 years however with completely different beginning factors (since 1960, 1965, 1970, 1975). Will depend on the OS, you possibly can construct a for loop in Linux and mac utilizing the bash shell syntax:
|
for C in DK FI IS NO SE; do for S in 0 5 10 15; do python gdp_arima.py –c $C –s $S carried out carried out |
or, because the shell syntax permits, we are able to put the whole lot in a single line:
|
for C in DK FI IS NO SE; do for S in 0 5 10 15; do python gdp_arima.py –c $C –s $S ; carried out ; carried out |
and even higher, give some info at every iteration of the loop, and we get our script run a number of occasions:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 |
$ for C in DK FI IS NO SE; do for S in 0 5 10 15; do echo $C $S; python gdp_arima.py -c $C -s $S ; carried out; carried out DK 0 Precise Forecast Rel Error 2000-12-31 1.326912e+12 1.290489e+12 -0.027449 2001-12-31 1.371526e+12 1.338878e+12 -0.023804 2002-12-31 1.410271e+12 1.386694e+12 -0.016718 DK 5 Precise Forecast Rel Error 2005-12-31 1.585984e+12 1.555961e+12 -0.018931 2006-12-31 1.682260e+12 1.605475e+12 -0.045644 2007-12-31 1.738845e+12 1.654548e+12 -0.048479 DK 10 Precise Forecast Rel Error 2010-12-31 1.810926e+12 1.762747e+12 -0.026605 2011-12-31 1.846854e+12 1.803335e+12 -0.023564 2012-12-31 1.895002e+12 1.843907e+12 -0.026963
…
SE 5 Precise Forecast Rel Error 2005-12-31 2931085000000 2.947563e+12 0.005622 2006-12-31 3121668000000 3.043831e+12 -0.024934 2007-12-31 3320278000000 3.122791e+12 -0.059479 SE 10 Precise Forecast Rel Error 2010-12-31 3573581000000 3.237310e+12 -0.094099 2011-12-31 3727905000000 3.163924e+12 -0.151286 2012-12-31 3743086000000 3.112069e+12 -0.168582 SE 15 Precise Forecast Rel Error 2015-12-31 4260470000000 4.086529e+12 -0.040827 2016-12-31 4415031000000 4.180213e+12 -0.053186 2017-12-31 4625094000000 4.273781e+12 -0.075958 |
For those who’re utilizing Home windows, you need to use the next syntax in command immediate:
|
for %C in (DK FI IS NO SE) do for %S in (0 5 10 15) do python gdp_arima.py -c $C -s $S |
or the next in PowerShell:
|
foreach ($C in “DK”,“FI”,“IS”,“NO”,“SE”) { foreach ($S in 0,5,10,15) { python gdp_arima.py -c $C -s $S } } |
each ought to produce the identical consequence.
Whereas we are able to put comparable loop inside our Python script, generally it’s simpler if we are able to do it on the command line. It could possibly be extra handy once we are exploring completely different choices. Furthermore, by taking the loop exterior of the Python code, we will be assured that each time we run the script is impartial as a result of we is not going to share any variables between iterations.
Utilizing command line arguments is just not the one approach to cross in knowledge to your Python script. Not less than, there are a number of different methods too:
- utilizing setting variables
- utilizing config recordsdata
Surroundings variables are options out of your OS to maintain small quantity of knowledge in reminiscence. We are able to learn setting variables in Python utilizing the next syntax:
|
import os print(os.environ[“MYVALUE”]) |
For instance, in Linux, the above two-line script will work with the shell as follows
|
$ export MYVALUE=”hi there” $ python show_env.py hi there |
and in Home windows, the syntax inside command immediate is analogous:
|
C:MLM> set MYVALUE=hi there
C:MLM> python show_env.py hi there |
You might also add or edit setting variables in Home windows utilizing the dialog in Management Panel:
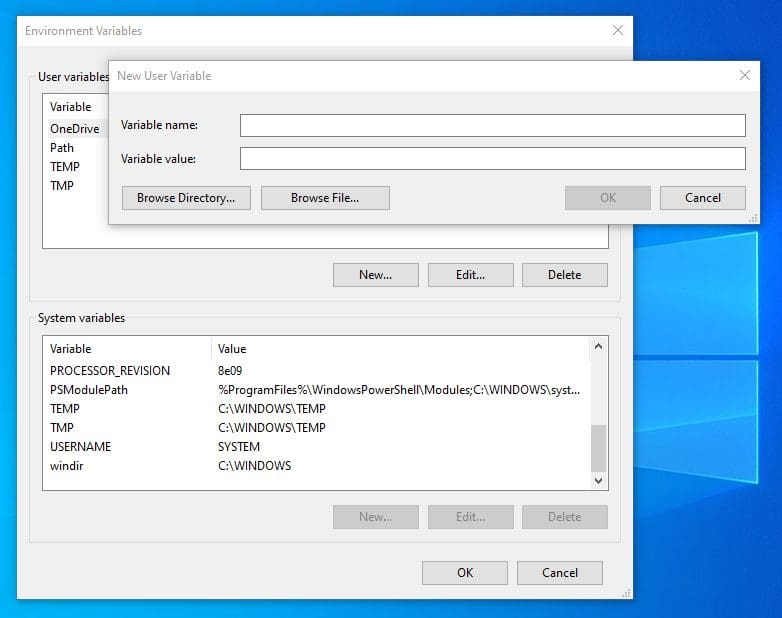
So we could maintain the parameters to the script in some setting variables and let the script adapt its conduct like establishing command line arguments.
In case we have now numerous choices to set, it’s higher to avoid wasting the choices to a file quite than overwhelming the command line. Will depend on the format we selected, we are able to use the configparser or json module from Python for studying Home windows INI format or JSON format respectively. We can also use the third occasion library PyYAML to learn YAML format.
For the above instance on operating ARIMA mannequin on GDP knowledge, we are able to modify the code to make use of YAML config file:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 |
import warnings warnings.simplefilter(“ignore”)
from pandas_datareader.wb import WorldBankReader import statsmodels.api as sm import pandas as pd import yaml
# Load config from YAML file with open(“config.yaml”, “r”) as fp: args = yaml.safe_load(fp)
# Arrange parameters collection = “NY.GDP.MKTP.CN” nation = args[“country”] size = args[“length”] begin = args[“start”] steps = 3 order = (1,1,1)
# Learn the GDP knowledge from WorldBank database gdp = WorldBankReader(collection, nation, begin=1960, finish=2020).learn() # Drop nation identify from index gdp = gdp.droplevel(stage=0, axis=0) # Type knowledge in choronological order and set knowledge level at year-end gdp.index = pd.to_datetime(gdp.index) gdp = gdp.sort_index().resample(“y”).final() # Convert pandas dataframe into pandas collection gdp = gdp[series] # Match arima mannequin consequence = sm.tsa.ARIMA(endog=gdp[start:start+length], order=order).match() # Forecast, and calculate the relative error forecast = consequence.forecast(steps=steps) df = pd.DataFrame({“Precise”:gdp, “Forecast”:forecast}).dropna() df[“Rel Error”] = (df[“Forecast”] – df[“Actual”]) / df[“Actual”] # Print consequence with pd.option_context(‘show.max_rows’, None, ‘show.max_columns’, 3): print(df) |
and the YAML config file is known as as config.yaml, which its content material is as follows:
|
nation: SE size: 40 begin: 0 |
Then we are able to run the above code and acquiring the identical consequence as earlier than. The JSON counterpart may be very comparable, which we use the load() perform from json module:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 |
import json import warnings warnings.simplefilter(“ignore”)
from pandas_datareader.wb import WorldBankReader import statsmodels.api as sm import pandas as pd
# Load config from JSON file with open(“config.json”, “r”) as fp: args = json.load(fp)
# Arrange parameters collection = “NY.GDP.MKTP.CN” nation = args[“country”] size = args[“length”] begin = args[“start”] steps = 3 order = (1,1,1)
# Learn the GDP knowledge from WorldBank database gdp = WorldBankReader(collection, nation, begin=1960, finish=2020).learn() # Drop nation identify from index gdp = gdp.droplevel(stage=0, axis=0) # Type knowledge in choronological order and set knowledge level at year-end gdp.index = pd.to_datetime(gdp.index) gdp = gdp.sort_index().resample(“y”).final() # Convert pandas dataframe into pandas collection gdp = gdp[series] # Match arima mannequin consequence = sm.tsa.ARIMA(endog=gdp[start:start+length], order=order).match() # Forecast, and calculate the relative error forecast = consequence.forecast(steps=steps) df = pd.DataFrame({“Precise”:gdp, “Forecast”:forecast}).dropna() df[“Rel Error”] = (df[“Forecast”] – df[“Actual”]) / df[“Actual”] # Print consequence with pd.option_context(‘show.max_rows’, None, ‘show.max_columns’, 3): print(df) |
and the JSON config file, config.json can be
|
{ “nation”: “SE”, “size”: 40, “begin”: 0 } |
It’s possible you’ll be taught extra in regards to the syntax of JSON and YAML to your venture. However the thought right here is that we are able to separate the info and algorithm for higher reusability of our code.
Additional studying
This part offers extra sources on the subject if you’re trying to go deeper.
Libraries
Articles
Books
Abstract
On this tutorial, you’ve see how we are able to make use of the command line for extra environment friendly management of our Python script. Particularly, you discovered
- How we are able to cross in parameters to your Python script utilizing the argparse module
- How we are able to effectively management the argparse-enabled Python script in a terminal underneath completely different OS
- We are able to additionally use setting variables, or config recordsdata to cross in parameters to a Python script
[ad_2]

