


[ad_1]
Final Up to date on March 16, 2022
Calculus for Machine Studying Crash Course.
Get accustomed to the calculus methods in machine studying in 7 days.
Calculus is a vital arithmetic approach behind many machine studying algorithms. You don’t at all times must comprehend it to make use of the algorithms. Whenever you go deeper, you will notice it’s ubiquitous in each dialogue on the speculation behind a machine studying mannequin.
As a practitioner, we’re most certainly not going to come across very onerous calculus issues. If we have to do one, there are instruments resembling pc algebra techniques to assist, or not less than, confirm our resolution. Nevertheless, what’s extra essential is knowing the thought behind calculus and relating the calculus phrases to its use in our machine studying algorithms.
On this crash course, you’ll uncover some widespread calculus concepts utilized in machine studying. You’ll study with workouts in Python in seven days.
This can be a huge and essential put up. You would possibly wish to bookmark it.
Let’s get began.
Calculus for Machine Studying (7-Day Mini-Course)
Picture by ArnoldReinhold, some rights reserved.
Who Is This Crash-Course For?
Earlier than we get began, let’s be sure to are in the proper place.
This course is for builders who might know some utilized machine studying. Perhaps you know the way to work by means of a predictive modeling downside finish to finish, or not less than a lot of the foremost steps, with widespread instruments.
The teachings on this course do assume a number of issues about you, resembling:
- You realize your manner round fundamental Python for programming.
- You might know some fundamental linear algebra.
- You might know some fundamental machine studying fashions.
You do NOT must be:
- A math wiz!
- A machine studying knowledgeable!
This crash course will take you from a developer who is aware of a bit of machine studying to a developer who can successfully speak concerning the calculus ideas in machine studying algorithms.
Notice: This crash course assumes you have got a working Python 3.7 surroundings with some libraries resembling SciPy and SymPy put in. For those who need assistance together with your surroundings, you possibly can observe the step-by-step tutorial right here:
Crash-Course Overview
This crash course is damaged down into seven classes.
You may full one lesson per day (really useful) or full the entire classes in sooner or later (hardcore). It actually is determined by the time you have got accessible and your degree of enthusiasm.
Beneath is an inventory of the seven classes that may get you began and productive with knowledge preparation in Python:
- Lesson 01: Differential calculus
- Lesson 02: Integration
- Lesson 03: Gradient of a vector perform
- Lesson 04: Jacobian
- Lesson 05: Backpropagation
- Lesson 06: Optimization
- Lesson 07: Assist vector machine
Every lesson might take you 5 minutes or as much as 1 hour. Take your time and full the teachings at your individual tempo. Ask questions, and even put up leads to the feedback under.
The teachings would possibly count on you to go off and learn how to do issues. I gives you hints, however a part of the purpose of every lesson is to pressure you to study the place to go to search for assist with and concerning the algorithms and the best-of-breed instruments in Python. (Trace: I’ve the entire solutions on this weblog; use the search field.)
Submit your leads to the feedback; I’ll cheer you on!
Dangle in there; don’t hand over.
Lesson 01: Differential Calculus
On this lesson, you’ll uncover what’s differential calculus or differentiation.
Differentiation is the operation of remodeling one mathematical perform to a different, referred to as the spinoff. The spinoff tells the slope, or the speed of change, of the unique perform.
For instance, if we’ve a perform $f(x)=x^2$, its spinoff is a perform that tells us the speed of change of this perform at $x$. The speed of change is outlined as: $$f'(x) = frac{f(x+delta x)-f(x)}{delta x}$$ for a small amount $delta x$.
Often we are going to outline the above within the type of a restrict, i.e.,
$$f'(x) = lim_{delta xto 0} frac{f(x+delta x)-f(x)}{delta x}$$
to imply $delta x$ ought to be as near zero as doable.
There are a number of guidelines of differentiation to assist us discover the spinoff simpler. One rule that matches the above instance is $frac{d}{dx} x^n = nx^{n-1}$. Therefore for $f(x)=x^2$, we’ve the spinoff $f'(x)=2x$.
We will affirm that is the case by plotting the perform $f'(x)$ computed in keeping with the speed of change along with that computed in keeping with the rule of differentiation. The next makes use of NumPy and matplotlib in Python:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 |
import numpy as np import matplotlib.pyplot as plt
# Outline perform f(x) def f(x): return x**2
# compute f(x) = x^2 for x=-10 to x=10 x = np.linspace(–10,10,500) y = f(x) # Plot f(x) on left half of the determine fig = plt.determine(figsize=(12,5)) ax = fig.add_subplot(121) ax.plot(x, y) ax.set_title(“y=f(x)”)
# f'(x) utilizing the speed of change delta_x = 0.0001 y1 = (f(x+delta_x) – f(x))/delta_x # f'(x) utilizing the rule y2 = 2 * x # Plot f'(x) on proper half of the determine ax = fig.add_subplot(122) ax.plot(x, y1, c=“r”, alpha=0.5, label=“price”) ax.plot(x, y2, c=“b”, alpha=0.5, label=“rule”) ax.set_title(“y=f'(x)”) ax.legend()
plt.present() |
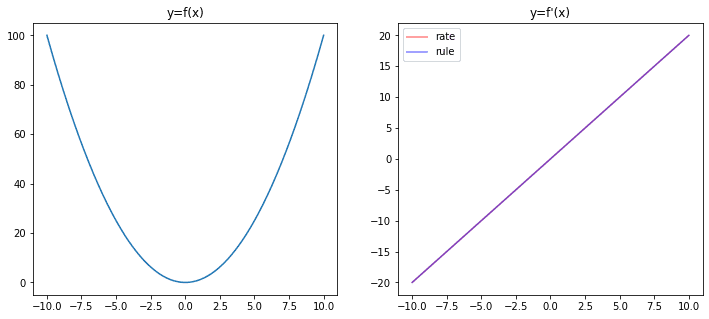
Within the plot above, we will see the spinoff perform discovered utilizing the speed of change after which utilizing the rule of differentiation coincide completely.
Your Activity
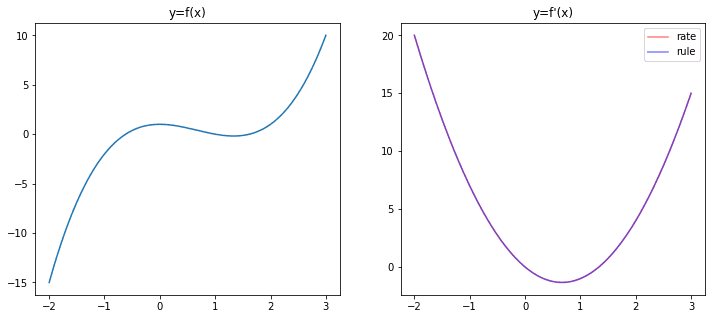
We will equally do a differentiation of different capabilities. For instance, $f(x)=x^3 – 2x^2 + 1$. Discover the spinoff of this perform utilizing the foundations of differentiation and evaluate your end result with the end result discovered utilizing the speed of limits. Confirm your end result with the plot above. For those who’re doing it accurately, it is best to see the next graph:
Within the subsequent lesson, you’ll uncover that integration is the reverse of differentiation.
Lesson 02: Integration
On this lesson, you’ll uncover integration is the reverse of differentiation.
If we think about a perform $f(x)=2x$ and at intervals of $delta x$ every step (e.g., $delta x = 0.1$), we will compute, say, from $x=-10$ to $x=10$ as:
$$
f(-10), f(-9.9), f(-9.8), cdots, f(9.8), f(9.9), f(10)
$$
Clearly, if we’ve a smaller step $delta x$, there are extra phrases within the above.
If we multiply every of the above with the step dimension after which add them up, i.e.,
$$
f(-10)occasions 0.1 + f(-9.9)occasions 0.1 + cdots + f(9.8)occasions 0.1 + f(9.9)occasions 0.1
$$
this sum is named the integral of $f(x)$. In essence, this sum is the space beneath the curve of $f(x)$, from $x=-10$ to $x=10$. A theorem in calculus says if we put the world beneath the curve as a perform, its spinoff is $f(x)$. Therefore we will see the mixing as a reverse operation of differentiation.
As we noticed in Lesson 01, the differentiation of $f(x)=x^2$ is $f'(x)=2x$. This implies for $f(x)=2x$, we will write $int f(x) dx = x^2$ or we will say the antiderivative of $f(x)=x$ is $x^2$. We will affirm this in Python by calculating the world instantly:
|
import numpy as np import matplotlib.pyplot as plt
def f(x): return 2*x
# Arrange x from -10 to 10 with small steps delta_x = 0.1 x = np.arange(–10, 10, delta_x) # Discover f(x) * delta_x fx = f(x) * delta_x # Compute the working sum y = fx.cumsum() # Plot plt.plot(x, y) plt.present() |
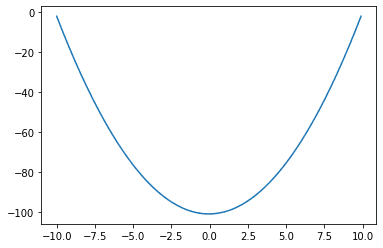
This plot has the identical form as $f(x)$ in Lesson 01. Certainly, all capabilities differ by a relentless (e.g., $f(x)$ and $f(x)+5$) which have the identical spinoff. Therefore the plot of the antiderivative computed would be the unique shifted vertically.
Your Activity
Think about $f(x)=3x^2-4x$, discover the antiderivative of this perform and plot it. Additionally, attempt to change the Python code above with this perform. For those who plot each collectively, it is best to see the next:
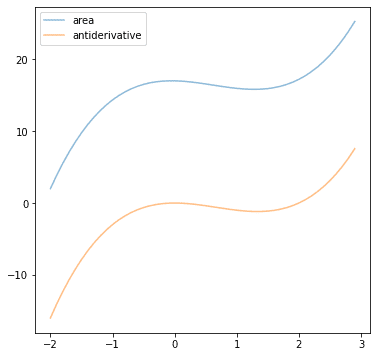
Submit your reply within the feedback under. I might like to see what you provide you with.
Lesson 03: Gradient of a vector perform
On this lesson, you’ll study the idea of gradient of a multivariate perform.
If we’ve a perform of not one variable however two or extra, the differentiation is prolonged naturally to be the differentiation of the perform with respect to every variable. For instance, if we’ve the perform $f(x,y) = x^2 + y^3$, we will write the differentiation in every variable as:
$$
start{aligned}
frac{partial f}{partial x} &= 2x
frac{partial f}{partial y} &= 3y^2
finish{aligned}
$$
Right here we launched the notation of a partial spinoff, that means to distinguish a perform on one variable whereas assuming the opposite variables are constants. Therefore within the above, after we compute $frac{partial f}{partial x}$, we ignored the $y^3$ half within the perform $f(x,y)$.
A perform with two variables will be visualized as a floor on a aircraft. The above perform $f(x,y)$ will be visualized utilizing matplotlib:
|
import numpy as np import matplotlib.pyplot as plt
# Outline the vary for x and y x = np.linspace(–10,10,1000) xv, yv = np.meshgrid(x, x, indexing=‘ij’)
# Compute f(x,y) = x^2 + y^3 zv = xv**2 + yv**3
# Plot the floor fig = plt.determine(figsize=(6,6)) ax = fig.add_subplot(projection=‘3d’) ax.plot_surface(xv, yv, zv, cmap=“viridis”) plt.present() |
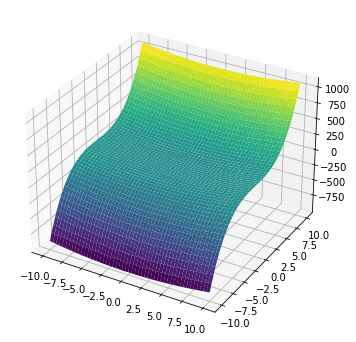
The gradient of this perform is denoted as:
$$nabla f(x,y) = Large(frac{partial f}{partial x},; frac{partial f}{partial y}Large) = (2x,;3y^2)$$
Subsequently, at every coordinate $(x,y)$, the gradient $nabla f(x,y)$ is a vector. This vector tells us two issues:
- The path of the vector factors to the place the perform $f(x,y)$ is rising the quickest
- The scale of the vector is the speed of change of the perform $f(x,y)$ on this path
One technique to visualize the gradient is to think about it as a vector discipline:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 |
import numpy as np import matplotlib.pyplot as plt
# Outline the vary for x and y x = np.linspace(–10,10,20) xv, yv = np.meshgrid(x, x, indexing=‘ij’)
# Compute the gradient of f(x,y) fx = 2*xv fy = 2*yv
# Convert the vector (fx,fy) into dimension and path dimension = np.sqrt(fx**2 + fy**2) dir_x = fx/dimension dir_y = fy/dimension
# Plot the floor plt.determine(figsize=(6,6)) plt.quiver(xv, yv, dir_x, dir_y, dimension, cmap=“viridis”) plt.present() |
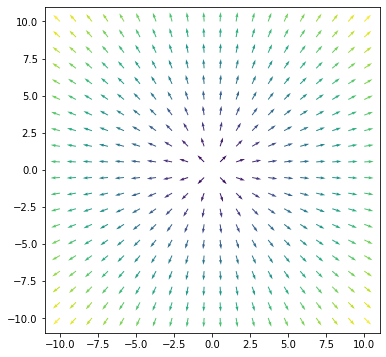
The viridis colour map in matplotlib will present a bigger worth in yellow and a decrease worth in purple. Therefore we see the gradient is “steeper” on the edges than within the heart within the above plot.
If we think about the coordinate (2,3), we will verify which path $f(x,y)$ will enhance the quickest utilizing the next:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 |
import numpy as np
def f(x, y): return x**2 + y**3
# 0 to 360 levels at 0.1-degree steps angles = np.arange(0, 360, 0.1)
# coordinate to verify x, y = 2, 3 # step dimension for differentiation step = 0.0001
# To maintain the dimensions and path of most price of change maxdf, maxangle = –np.inf, 0 for angle in angles: # convert diploma to radian rad = angle * np.pi / 180 # delta x and delta y for a set step dimension dx, dy = np.sin(rad)*step, np.cos(rad)*step # price of change at a small step df = (f(x+dx, y+dy) – f(x,y))/step # maintain the utmost price of change if df > maxdf: maxdf, maxangle = df, angle
# Report the end result dx, dy = np.sin(maxangle*np.pi/180), np.cos(maxangle*np.pi/180) gradx, grady = dx*maxdf, dy*maxdf print(f“Max price of change at {maxangle} levels”) print(f“Gradient vector at ({x},{y}) is ({dx*maxdf},{dy*maxdf})”) |
Its output is:
|
Max price of change at 8.4 levels Gradient vector at (2,3) is (3.987419245872443,27.002750276227097) |
The gradient vector in keeping with the system is (4,27), which the numerical end result above is shut sufficient.
Your Activity
Think about the perform $f(x,y)=x^2+y^2$, what’s the gradient vector at (1,1)? For those who get the reply from partial differentiation, are you able to modify the above Python code to verify it by checking the speed of change at totally different instructions?
Submit your reply within the feedback under. I might like to see what you provide you with.
Within the subsequent lesson, you’ll uncover the differentiation of a perform that takes vector enter and produces vector output.
Lesson 04: Jacobian
On this lesson, you’ll study Jacobian matrix.
The perform $f(x,y)=(p(x,y), q(x,y))=(2xy, x^2y)$ is one with two enter and two outputs. Typically we name this perform taking vector arguments and returning a vector worth. The differentiation of this perform is a matrix referred to as the Jacobian. The Jacobian of the above perform is:
$$
mathbf{J} =
start{bmatrix}
frac{partial p}{partial x} & frac{partial p}{partial y}
frac{partial q}{partial x} & frac{partial q}{partial y}
finish{bmatrix}
=
start{bmatrix}
2y & 2x
2xy & x^2
finish{bmatrix}
$$
Within the Jacobian matrix, every row has the partial differentiation of every factor of the output vector, and every column has the partial differentiation with respect to every factor of the enter vector.
We are going to see using Jacobian later. Since discovering a Jacobian matrix includes numerous partial differentiations, it could be nice if we might let a pc verify our math. In Python, we will confirm the above end result utilizing SymPy:
|
from sympy.abc import x, y from sympy import Matrix, pprint
f = Matrix([2*x*y, x**2*y]) variables = Matrix([x,y]) pprint(f.jacobian(variables)) |
Its output is:
|
⎡ 2⋅y 2⋅x⎤ ⎢ ⎥ ⎢ 2 ⎥ ⎣2⋅x⋅y x ⎦ |
We requested SymPy to outline the symbols x and y after which outlined the vector perform f. Afterward, the Jacobian will be discovered by calling the jacobian() perform.
Your Activity
Think about the perform
$$
f(x,y) = start{bmatrix}
frac{1}{1+e^{-(px+qy)}} & frac{1}{1+e^{-(rx+sy)}} & frac{1}{1+e^{-(tx+uy)}}
finish{bmatrix}
$$
the place $p,q,r,s,t,u$ are constants. What’s the Jacobian matrix of $f(x,y)$? Are you able to confirm it with SymPy?
Within the subsequent lesson, you’ll uncover the applying of the Jacobian matrix in a neural community’s backpropagation algorithm.
Lesson 05: Backpropagation
On this lesson, you will notice how the backpropagation algorithm makes use of the Jacobian matrix.
If we think about a neural community with one hidden layer, we will signify it as a perform:
$$
y = gBig(sum_{ok=1}^M u_k f_kbig(sum_{i=1}^N w_{ik}x_ibig)Large)
$$
The enter to the neural community is a vector $mathbf{x}=(x_1, x_2, cdots, x_N)$ and every $x_i$ will likely be multiplied with weight $w_{ik}$ and fed into the hidden layer. The output of neuron $ok$ within the hidden layer will likely be multiplied with weight $u_k$ and fed into the output layer. The activation perform of the hidden layer and output layer are $f$ and $g$, respectively.
If we think about
$$z_k = f_kbig(sum_{i=1}^N w_{ik}x_ibig)$$
then
$$
frac{partial y}{partial x_i} = sum_{ok=1}^M frac{partial y}{partial z_k}frac{partial z_k}{partial x_i}
$$
If we think about the complete layer without delay, we’ve $mathbf{z}=(z_1, z_2, cdots, z_M)$ after which
$$
frac{partial y}{partial mathbf{x}} = mathbf{W}^topfrac{partial y}{partial mathbf{z}}
$$
the place $mathbf{W}$ is the $Mtimes N$ Jacobian matrix, the place the factor on row $ok$ and column $i$ is $frac{partial z_k}{partial x_i}$.
That is how the backpropagation algorithm works in coaching a neural community! For a community with a number of hidden layers, we have to compute the Jacobian matrix for every layer.
Your Activity
The code under implements a neural community mannequin which you can strive your self. It has two hidden layers and a classification community to separate factors in 2-dimension into two lessons. Attempt to take a look at the perform backward() and establish which is the Jacobian matrix.
For those who play with this code, the category mlp shouldn’t be modified, however you possibly can change the parameters on how a mannequin is created.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 120 121 122 123 124 125 126 127 128 129 130 131 132 133 134 135 136 137 138 |
from sklearn.datasets import make_circles from sklearn.metrics import accuracy_score import numpy as np np.random.seed(0)
# Discover a small float to keep away from division by zero epsilon = np.finfo(float).eps
# Sigmoid perform and its differentiation def sigmoid(z): return 1/(1+np.exp(–z.clip(–500, 500))) def dsigmoid(z): s = sigmoid(z) return 2 * s * (1–s)
# ReLU perform and its differentiation def relu(z): return np.most(0, z) def drelu(z): return (z > 0).astype(float)
# Loss perform L(y, yhat) and its differentiation def cross_entropy(y, yhat): “”“Binary cross entropy perform L = – y log yhat – (1-y) log (1-yhat)
Args: y, yhat (np.array): nx1 matrices which n are the variety of knowledge situations Returns: common cross entropy worth of form 1×1, averaging over the n situations ““” return ( –(y.T @ np.log(yhat.clip(epsilon)) + (1–y.T) @ np.log((1–yhat).clip(epsilon)) ) / y.form[1] )
def d_cross_entropy(y, yhat): “”” dL/dyhat ““” return ( – np.divide(y, yhat.clip(epsilon)) + np.divide(1–y, (1–yhat).clip(epsilon)) )
class mlp: ”‘Multilayer perceptron utilizing numpy ‘” def __init__(self, layersizes, activations, derivatives, lossderiv): “”“keep in mind config, then initialize array to carry NN parameters with out init”“” # maintain NN config self.layersizes = tuple(layersizes) self.activations = tuple(activations) self.derivatives = tuple(derivatives) self.lossderiv = lossderiv # parameters, every is a 2D numpy array L = len(self.layersizes) self.z = [None] * L self.W = [None] * L self.b = [None] * L self.a = [None] * L self.dz = [None] * L self.dW = [None] * L self.db = [None] * L self.da = [None] * L
def initialize(self, seed=42): “”“initialize the worth of weight matrices and bias vectors with small random numbers.”“” np.random.seed(seed) sigma = 0.1 for l, (n_in, n_out) in enumerate(zip(self.layersizes, self.layersizes[1:]), 1): self.W[l] = np.random.randn(n_in, n_out) * sigma self.b[l] = np.random.randn(1, n_out) * sigma
def ahead(self, x): “”“Feed ahead utilizing present `W` and `b`, and overwrite the end result variables `a` and `z`
Args: x (numpy.ndarray): Enter knowledge to feed ahead ““” self.a[0] = x for l, func in enumerate(self.activations, 1): # z = W a + b, with `a` as output from earlier layer # `W` is of dimension rxs and `a` the dimensions sxn with n the variety of knowledge # situations, `z` the dimensions rxn, `b` is rx1 and broadcast to every # column of `z` self.z[l] = (self.a[l–1] @ self.W[l]) + self.b[l] # a = g(z), with `a` as output of this layer, of dimension rxn self.a[l] = func(self.z[l]) return self.a[–1]
def backward(self, y, yhat): “”“again propagation utilizing NN output yhat and the reference output y, generates dW, dz, db, da ““” # first `da`, on the output self.da[–1] = self.lossderiv(y, yhat) for l, func in reversed(listing(enumerate(self.derivatives, 1))): # compute the differentials at this layer self.dz[l] = self.da[l] * func(self.z[l]) self.dW[l] = self.a[l–1].T @ self.dz[l] self.db[l] = np.imply(self.dz[l], axis=0, keepdims=True) self.da[l–1] = self.dz[l] @ self.W[l].T
def replace(self, eta): “”“Updates W and b
Args: eta (float): Studying price ““” for l in vary(1, len(self.W)): self.W[l] -= eta * self.dW[l] self.b[l] -= eta * self.db[l]
# Make knowledge: Two circles on x-y aircraft as a classification downside X, y = make_circles(n_samples=1000, issue=0.5, noise=0.1) y = y.reshape(–1,1) # our mannequin expects a 2D array of (n_sample, n_dim)
# Construct a mannequin mannequin = mlp(layersizes=[2, 4, 3, 1], activations=[relu, relu, sigmoid], derivatives=[drelu, drelu, dsigmoid], lossderiv=d_cross_entropy) mannequin.initialize() yhat = mannequin.ahead(X) loss = cross_entropy(y, yhat) rating = accuracy_score(y, (yhat > 0.5)) print(f“Earlier than coaching – loss worth {loss} accuracy {rating}”)
# practice for every epoch n_epochs = 150 learning_rate = 0.005 for n in vary(n_epochs): mannequin.ahead(X) yhat = mannequin.a[–1] mannequin.backward(y, yhat) mannequin.replace(learning_rate) loss = cross_entropy(y, yhat) rating = accuracy_score(y, (yhat > 0.5)) print(f“Iteration {n} – loss worth {loss} accuracy {rating}”) |
Within the subsequent lesson, you’ll uncover using differentiation to search out the optimum worth of a perform.
Lesson 06: Optimization
On this lesson, you’ll study an essential use of differentiation.
As a result of the differentiation of a perform is the speed of change, we will make use of differentiation to search out the optimum level of a perform.
If a perform attained its most, we’d count on it to maneuver from a decrease level to the utmost, and if we transfer additional, it falls to a different decrease level. Therefore on the level of most, the speed of change of a perform is zero. And vice versa for the minimal.
For example, think about $f(x)=x^3-2x^2+1$. The spinoff is $f'(x) = 3x^2-4x$ and $f'(x)=0$ at $x=0$ and $x=4/3$. Therefore these positions of $x$ are the place $f(x)$ is at its most or minimal. We will visually affirm it by plotting $f(x)$ (see the plot in Lesson 01).
Your process
Think about the perform $f(x)=log x$ and discover its spinoff. What would be the worth of $x$ when $f'(x)=0$? What does it let you know concerning the most or minimal of the log perform? Attempt to plot the perform of $log x$ to visually affirm your reply.
Within the subsequent lesson, you’ll uncover the applying of this method find the assist vector.
Lesson 07: Assist vector machine
On this lesson, you’ll learn the way we will convert assist vector machine into an optimization downside.
In a two-dimensional aircraft, any straight line will be represented by the equation:
$$ax+by+c=0$$
within the $xy$-coordinate system. A end result from the research of coordinate geometry says that for any level $(x_0,y_0)$, its distance to the road $ax+by+c=0$ is:
$$
frac{vert ax_0+by_0+c vert}{sqrt{a^2+b^2}}
$$
Think about the factors (0,0), (1,2), and (2,1) within the $xy$-plane, wherein the primary level and the latter two factors are in several lessons. What’s the line that greatest separates these two lessons? That is the premise of a assist vector machine classifier. The assist vector is the road of most separation on this case.
To seek out such a line, we’re on the lookout for:
$$
start{aligned}
textual content{decrease} && a^2 + b^2
textual content{topic to} && -1(0a+0b+c) &ge 1
&& +1(1a+2b+c) &ge 1
&& +1(2a+1b+c) &ge 1
finish{aligned}
$$
The target $a^2+b^2$ is to be minimized in order that the distances from every knowledge level to the road are maximized. The situation $-1(0a+0b+c)ge 1$ means the purpose (0,0) is of sophistication $-1$; equally for the opposite two factors, they’re of sophistication $+1$. The straight line ought to put these two lessons in several sides of the aircraft.
This can be a constrained optimization downside, and the way in which to unravel it’s to make use of the Lagrange multiplier strategy. Step one in utilizing the Lagrange multiplier strategy is to search out the partial differentials of the next Lagrange perform:
$$
L = a^2+b^2 + lambda_1(-c-1) + lambda_2 (a+2b+c-1) + lambda_3 (2a+b+c-1)
$$
and set the partial differentials to zero, then remedy for $a$, $b$, and $c$. It will be too prolonged to reveal right here, however we will use SciPy to search out the answer to the above numerically:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 |
import numpy as np from scipy.optimize import decrease
def goal(w): return w[0]**2 + w[1]**2
def constraint1(w): “Inequality for level (0,0)” return –1*w[2] – 1
def constraint2(w): “Inequality for level (1,2)” return w[0] + 2*w[1] + w[2] – 1
def constraint3(w): “Inequality for level (2,1)” return 2*w[0] + w[1] + w[2] – 1
# preliminary guess w0 = np.array([1, 1, 1])
# optimize bounds = ((–10,10), (–10,10), (–10,10)) constraints = [ {“type”:“ineq”, “fun”:constraint1}, {“type”:“ineq”, “fun”:constraint2}, {“type”:“ineq”, “fun”:constraint3}, ] resolution = decrease(goal, w0, methodology=“SLSQP”, bounds=bounds, constraints=constraints) w = resolution.x print(“Goal:”, goal(w)) print(“Resolution:”, w) |
It would print:
|
Goal: 0.8888888888888942 Resolution: [ 0.66666667 0.66666667 -1. ] |
The above means the road to separate these three factors is $0.67x + 0.67y – 1 = 0$. Notice that should you offered $N$ knowledge factors, there can be $N$ constraints to be outlined.
Your Activity
Let’s think about the factors (-1,-1) and (-3,-1) to be the primary class along with (0,0) and level (3,3) to be the second class along with factors (1,2) and (2,1). On this downside of six factors, are you able to modify the above program and discover the road that separates the 2 lessons? Don’t be stunned to see the answer stay the identical as above. There’s a motive for it. Are you able to inform?
Submit your reply within the feedback under. I might like to see what you provide you with.
This was the ultimate lesson.
The Finish!
(Look How Far You Have Come)
You made it. Nicely executed!
Take a second and look again at how far you have got come.
You found:
- What’s differentiation, and what it means to a perform
- What’s integration
- Methods to lengthen differentiation to a perform of vector argument
- Methods to do differentiation on a vector-valued perform
- The position of Jacobian within the backpropagation algorithm in neural networks
- Methods to use differentiation to search out the optimum factors of a perform
- Assist vector machine is a constrained optimization downside, which would wish differentiation to unravel
Abstract
How did you do with the mini-course?
Did you take pleasure in this crash course?
Do you have got any questions? Have been there any sticking factors?
Let me know. Go away a remark under.
Get a Deal with on Calculus for Machine Studying!

Really feel Smarter with Calculus Ideas
…by getting a greater sense on the calculus symbols and phrases
Uncover how in my new E book:
Calculus for Machine Studying
It gives self-study tutorials with full working code on:
differntiation, gradient, Lagrangian mutiplier strategy, Jacobian matrix,
and rather more…
Convey Simply Sufficient Calculus Data to
Your Machine Studying Tasks
[ad_2]


