



[ad_1]
For many people, it may be difficult to maintain up with the amount of paperwork that arrive in our inboxes every single day: stories, critiques, briefs, insurance policies and the checklist goes on. When a brand new doc is obtained, readers typically want it included a short abstract of the details in an effort to successfully prioritize it. Nonetheless, composing a doc abstract could be cognitively difficult and time-consuming, particularly when a doc author is ranging from scratch.
To assist with this, we lately introduced that Google Docs now routinely generates solutions to assist doc writers in creating content material summaries, when they’re accessible. Right this moment we describe how this was enabled utilizing a machine studying (ML) mannequin that comprehends doc textual content and, when assured, generates a 1-2 sentence pure language description of the doc content material. Nonetheless, the doc author maintains full management — accepting the suggestion as-is, making mandatory edits to higher seize the doc abstract or ignoring the suggestion altogether. Readers also can use this part, together with the define, to grasp and navigate the doc at a excessive degree. Whereas all customers can add summaries, auto-generated solutions are presently solely accessible to Google Workspace enterprise clients. Constructing on grammar solutions, Good Compose, and autocorrect, we see this as one other worthwhile step towards enhancing written communication within the office.
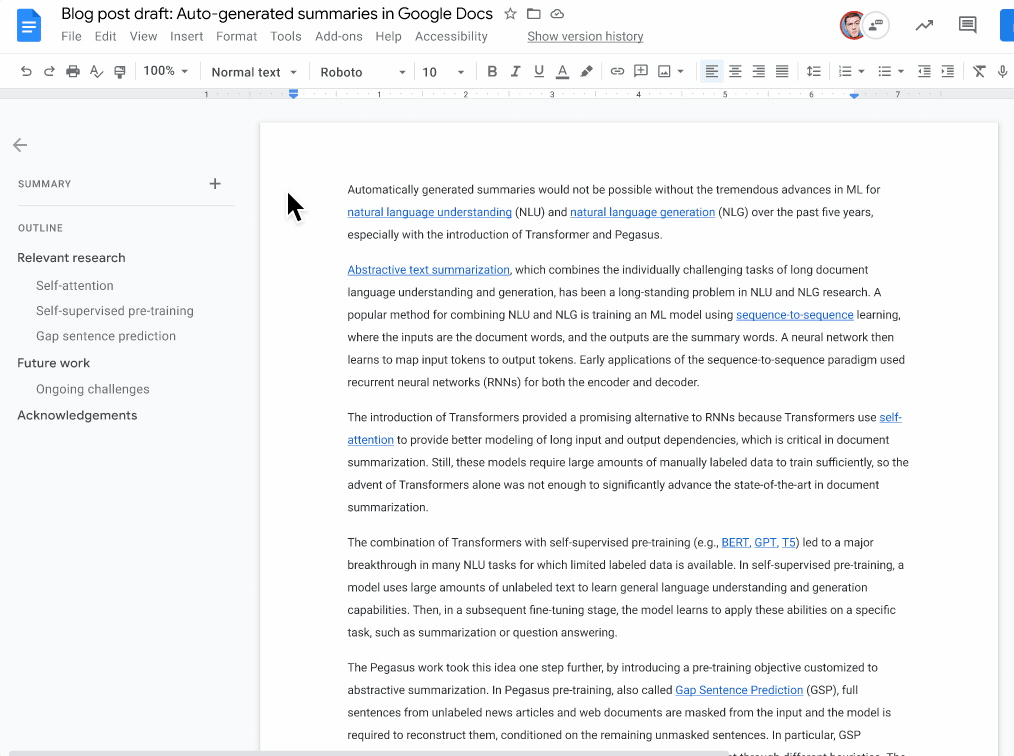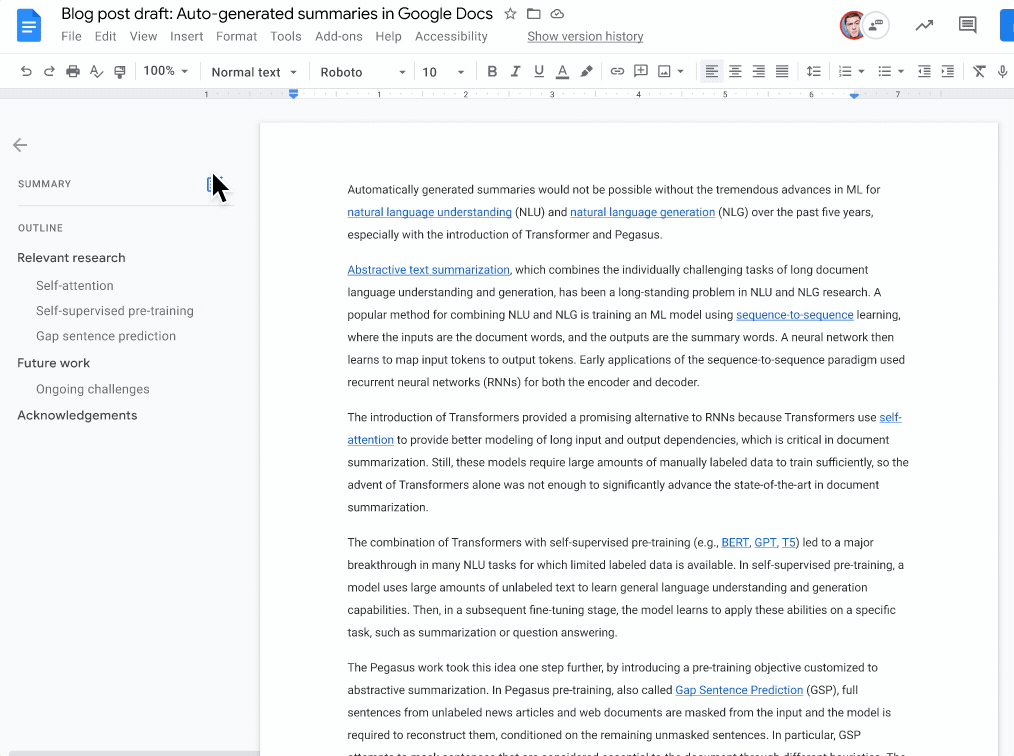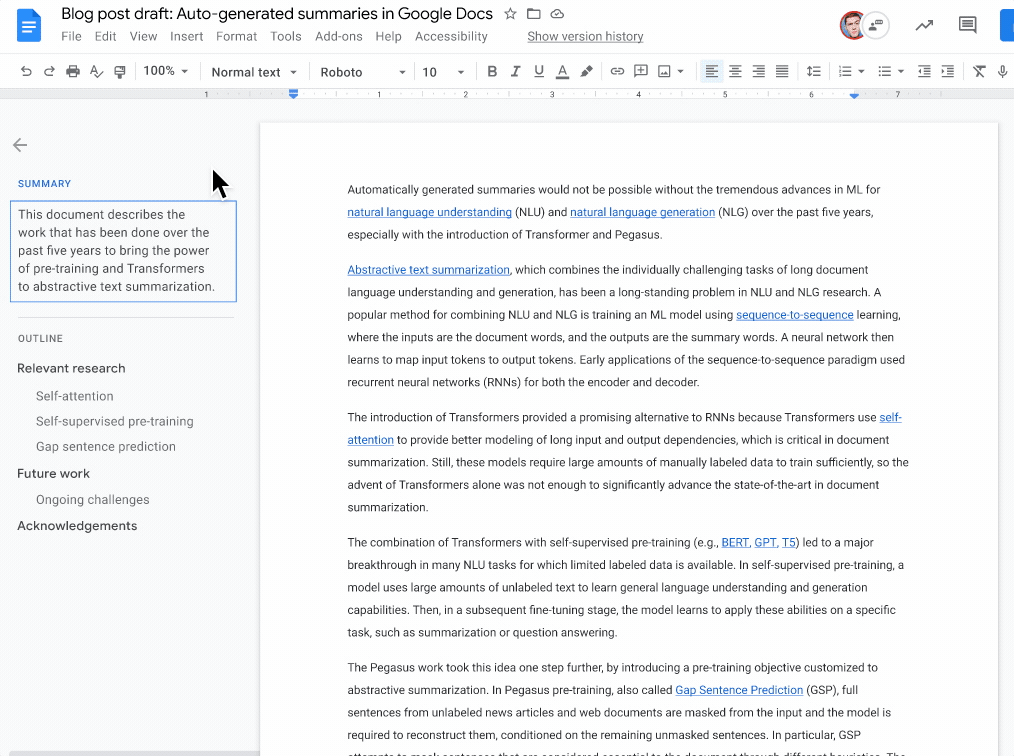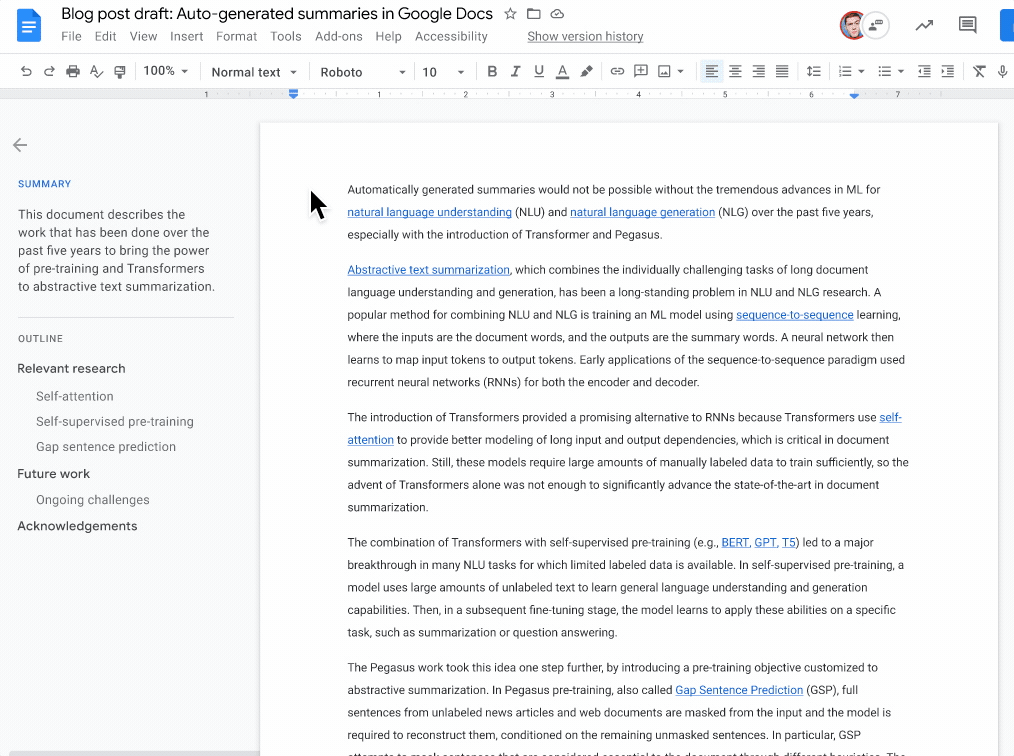 |
| A blue abstract icon seems within the high left nook when a doc abstract suggestion is accessible. Doc writers can then view, edit, or ignore the instructed doc abstract. |
Mannequin Particulars
Robotically generated summaries wouldn’t be potential with out the large advances in ML for pure language understanding (NLU) and pure language era (NLG) over the previous 5 years, particularly with the introduction of Transformer and Pegasus.
Abstractive textual content summarization, which mixes the individually difficult duties of lengthy doc language understanding and era, has been a long-standing downside in NLU and NLG analysis. A preferred technique for combining NLU and NLG is coaching an ML mannequin utilizing sequence-to-sequence studying, the place the inputs are the doc phrases, and the outputs are the abstract phrases. A neural community then learns to map enter tokens to output tokens. Early functions of the sequence-to-sequence paradigm used recurrent neural networks (RNNs) for each the encoder and decoder.
The introduction of Transformers supplied a promising different to RNNs as a result of Transformers use self-attention to supply higher modeling of lengthy enter and output dependencies, which is crucial in doc summarization. Nonetheless, these fashions require massive quantities of manually labeled information to coach sufficiently, so the arrival of Transformers alone was not sufficient to considerably advance the state-of-the-art in doc summarization.
The mixture of Transformers with self-supervised pre-training (e.g., BERT, GPT, T5) led to a serious breakthrough in lots of NLU duties for which restricted labeled information is accessible. In self-supervised pre-training, a mannequin makes use of massive quantities of unlabeled textual content to be taught common language understanding and era capabilities. Then, in a subsequent fine-tuning stage, the mannequin learns to use these skills on a particular process, similar to summarization or query answering.
The Pegasus work took this concept one step additional, by introducing a pre-training goal personalized to abstractive summarization. In Pegasus pre-training, additionally referred to as Hole Sentence Prediction (GSP), full sentences from unlabeled information articles and internet paperwork are masked from the enter and the mannequin is required to reconstruct them, conditioned on the remaining unmasked sentences. Particularly, GSP makes an attempt to masks sentences which might be thought-about important to the doc by completely different heuristics. The instinct is to make the pre-training as shut as potential to the summarization process. Pegasus achieved state-of-the-art outcomes on a diverse set of summarization datasets. Nonetheless, a variety of challenges remained to use this analysis development right into a product.
Making use of Current Analysis Advances to Google Docs
- Knowledge
Self-supervised pre-training leads to an ML mannequin that has common language understanding and era capabilities, however a subsequent fine-tuning stage is crucial for the mannequin to adapt to the applying area. We fine-tuned early variations of our mannequin on a corpus of paperwork with manually-generated summaries that have been per typical use instances.
Nonetheless, early variations of this corpus suffered from inconsistencies and excessive variation as a result of they included many varieties of paperwork, in addition to some ways to jot down a abstract — e.g., educational abstracts are sometimes lengthy and detailed, whereas govt summaries are temporary and punchy. This led to a mannequin that was simply confused as a result of it had been skilled on so many several types of paperwork and summaries that it struggled to be taught the relationships between any of them.
Fortuitously, one of many key findings within the Pegasus work was that an efficient pre-training section required much less supervised information within the fine-tuning stage. Some summarization benchmarks required as few as 1,000 fine-tuning examples for Pegasus to match the efficiency of Transformer baselines that noticed 10,000+ supervised examples — suggesting that one may concentrate on high quality reasonably than amount.
We fastidiously cleaned and filtered the fine-tuning information to comprise coaching examples that have been extra constant and represented a coherent definition of summaries. Even though we decreased the quantity of coaching information, this led to the next high quality mannequin. The important thing lesson, per latest work in domains like dataset distillation, was that it was higher to have a smaller, prime quality dataset, than a bigger, high-variance dataset.


- Serving
As soon as we skilled the prime quality mannequin, we turned to the problem of serving the mannequin in manufacturing. Whereas the Transformer model of the encoder-decoder structure is the dominant method to coach fashions for sequence-to-sequence duties like abstractive summarization, it may be inefficient and impractical to serve in real-world functions. The principle inefficiency comes from the Transformer decoder the place we generate the output abstract token by token by autoregressive decoding. The decoding course of turns into noticeably gradual when summaries get longer for the reason that decoder attends to all beforehand generated tokens at every step. RNNs are a extra environment friendly structure for decoding since there isn’t a self-attention with earlier tokens as in a Transformer mannequin.
We used data distillation, which is the method of transferring data from a big mannequin to a smaller extra environment friendly mannequin, to distill the Pegasus mannequin right into a hybrid structure of a Transformer encoder and an RNN decoder. To enhance effectivity we additionally decreased the variety of RNN decoder layers. The ensuing mannequin had important enhancements in latency and reminiscence footprint whereas the standard was nonetheless on par with the unique mannequin. To additional enhance the latency and person expertise, we serve the summarization mannequin utilizing TPUs, which offer important velocity ups and permit extra requests to be dealt with by a single machine.
Ongoing Challenges and Subsequent Steps
Whereas we’re excited by the progress to this point, there are a couple of challenges we’re persevering with to sort out:
- Doc protection: Creating a set of paperwork for the fine-tuning stage was tough because of the large selection that exists amongst paperwork, and the identical problem is true at inference time. A few of the paperwork our customers create (e.g., assembly notes, recipes, lesson plans and resumes) usually are not appropriate for summarization or could be tough to summarize. At present, our mannequin solely suggests a abstract for paperwork the place it’s most assured, however we hope to proceed broadening this set as our mannequin improves.
- Analysis: Abstractive summaries must seize the essence of a doc whereas being fluent and grammatically right. A particular doc could have many summaries that may be thought-about right, and completely different readers could desire completely different ones. This makes it exhausting to judge summaries with computerized metrics solely, person suggestions and utilization statistics can be crucial for us to grasp and maintain enhancing high quality.
- Lengthy paperwork: Lengthy paperwork are a few of the hardest paperwork for the mannequin to summarize as a result of it’s more durable to seize all of the factors and summary them in a single abstract, and it may well additionally considerably enhance reminiscence utilization throughout coaching and serving. Nonetheless, lengthy paperwork are maybe most helpful for the mannequin to routinely summarize as a result of it may well assist doc writers get a head begin on this tedious process. We hope we will apply the most recent ML developments to higher tackle this problem.
Conclusion
Total, we’re thrilled that we will apply latest progress in NLU and NLG to proceed helping customers with studying and writing. We hope the automated solutions now supplied in Google Workspace make it simpler for writers to annotate their paperwork with summaries, and assist readers comprehend and navigate paperwork extra simply.
Acknowledgements
The authors want to thank the many individuals throughout Google that contributed to this work: AJ Motika, Matt Pearson-Beck, Mia Chen, Mahdis Mahdieh, Halit Erdogan, Benjamin Lee, Ali Abdelhadi, Michelle Danoff, Vishnu Sivaji, Sneha Keshav, Aliya Baptista, Karishma Damani, DJ Lick, Yao Zhao, Peter Liu, Aurko Roy, Yonghui Wu, Shubhi Sareen, Andrew Dai, Mekhola Mukherjee, Yinan Wang, Mike Colagrosso, and Behnoosh Hariri.
.
[ad_2]

