



[ad_1]
It’s not obscure why entanglement is an issue in picture synthesis, as a result of it’s usually an issue in different areas of life; as an illustration, it’s far more durable to take away turmeric from a curry than it’s to discard the pickle in a burger, and it’s virtually not possible to de-sweeten a cup of espresso. Some issues simply come bundled.
Likewise entanglement is a stumbling block for picture synthesis architectures that will ideally prefer to separate out totally different options and ideas when utilizing machine studying to create or edit faces (or canine, boats, or another area).
For those who may separate out strands equivalent to age, gender, hair coloration, pores and skin tone, emotion, and so forth, you’d have the beginnings of actual instrumentality and adaptability in a framework that might create and edit face photographs at a very granular stage, with out dragging undesirable ‘passengers’ into these conversions.

At most entanglement (above left), all you are able to do is change the picture of a discovered GAN community to the picture of one other individual.
That is successfully utilizing the newest AI pc imaginative and prescient know-how to attain one thing that was solved by different means over thirty years in the past.
With some extent of separation (‘Medium Separation’ in earlier above picture), it’s doable to carry out style-based adjustments equivalent to hair coloration, expression, beauty software, and restricted head rotation, amongst others.

Supply: FEAT: Face Enhancing with Consideration, February 2022, https://arxiv.org/pdf/2202.02713.pdf
There was a variety of makes an attempt within the final two years to create interactive face-editing environments that enable a consumer to vary facial traits with sliders and different conventional UI interactions, whereas holding core options of the goal face intact when making additions or adjustments. Nevertheless, this has proved a problem as a result of underlying characteristic/type entanglement within the latent area of the GAN.
As an example, the glasses trait is ceaselessly enmeshed with the aged trait, which means that including glasses may also ‘age’ the face, whereas ageing the face may add glasses, relying on the diploma of utilized separation of high-level options (see ‘Testing’ beneath for examples).
Most notably, it has been nearly not possible to change hair coloration and different hair aspects with out the hair strands and disposition being recalculated, which supplies a ‘scorching’, transitional impact.

Supply: InterFaceGAN Demo (CVPR 2020), https://www.youtube.com/watch?v=uoftpl3Bj6w
Latent-to-Latent GAN Traversal
A brand new Adobe-led paper entered for WACV 2022 gives a novel strategy to those underlying points in a paper entitled Latent to Latent: A Discovered Mapper for Id Preserving Enhancing of A number of Face Attributes in StyleGAN-generated Photographs.
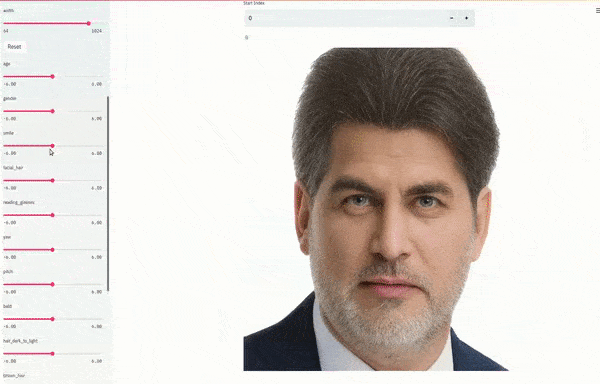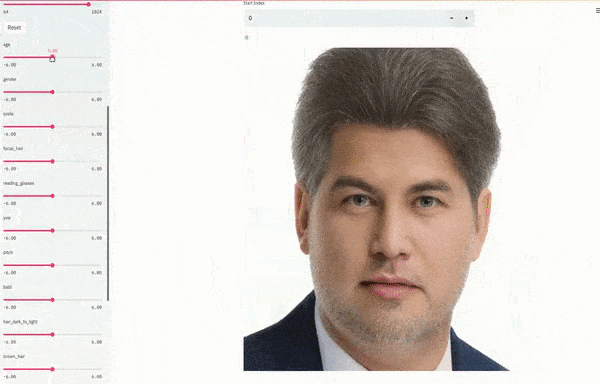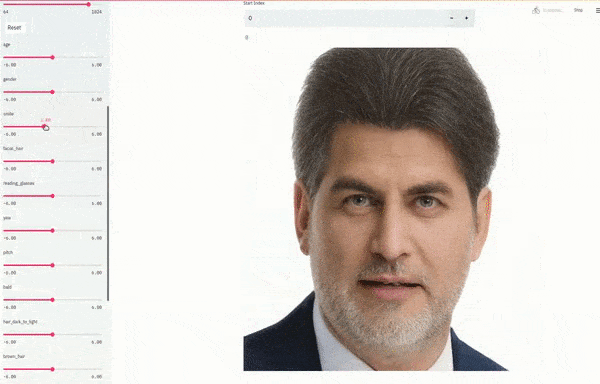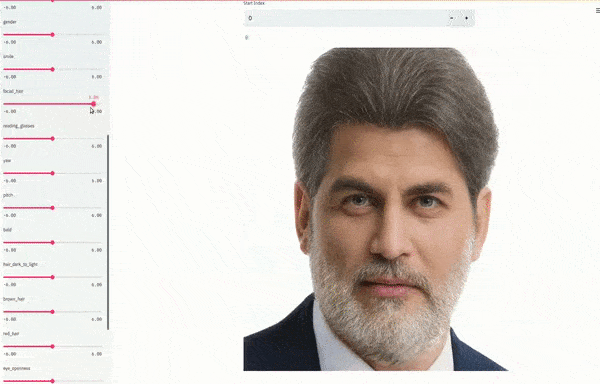
Supplemental materials from the paper Latent to Latent: A Discovered Mapper for Id Preserving Enhancing of A number of Face Attributes in StyleGAN-generated Photographs. Right here we see that base traits within the discovered face should not dragged into unrelated adjustments. See full video embed at finish of article for higher element and determination. Supply: https://www.youtube.com/watch?v=rf_61llRH0Q
The paper is led by Adobe Utilized Scientist Siavash Khodadadeh, along with 4 different Adobe researchers, and a researcher from the Division of Pc Science on the College of Central Florida.
The piece is attention-grabbing partly as a result of Adobe has been working on this area for a while, and it’s tempting to think about this performance getting into a Inventive Suite mission within the subsequent few years; however primarily as a result of the structure created for the mission takes a distinct strategy to sustaining visible integrity in a GAN face editor whereas adjustments are being utilized.
The authors declare:
‘[We] practice a neural community to carry out a latent-to-latent transformation which finds the latent encoding equivalent to the picture with the modified attribute. Because the approach is one-shot, it doesn’t depend on a linear or non-linear trajectory of the gradual change of the attributes.
‘By coaching the community end-to-end over the total era pipeline, the system can adapt to the latent areas of off-the-shelf generator architectures. Conservation properties, equivalent to sustaining the identification of the individual will be encoded within the type of coaching losses.
‘As soon as the latent-to-latent community was skilled, it may be reused for arbitrary photographs with out retraining.’
This final half signifies that the proposed structure arrives with the end-user in a completed state. It nonetheless must run a neural community on native sources, however new photographs will be ‘dropped in’ and be prepared for altering nearly instantly, for the reason that framework is decoupled sufficient to not want additional image-specific coaching.
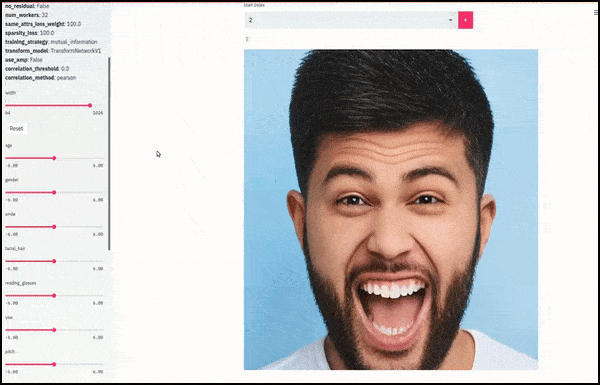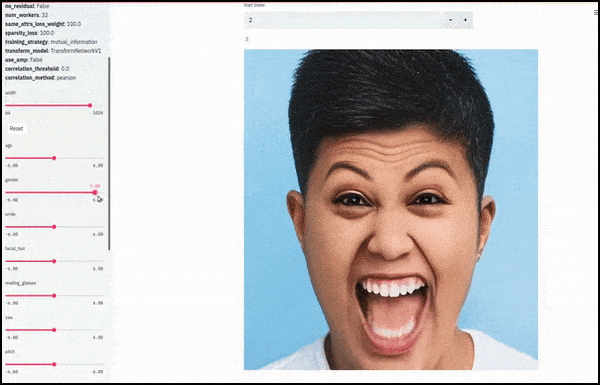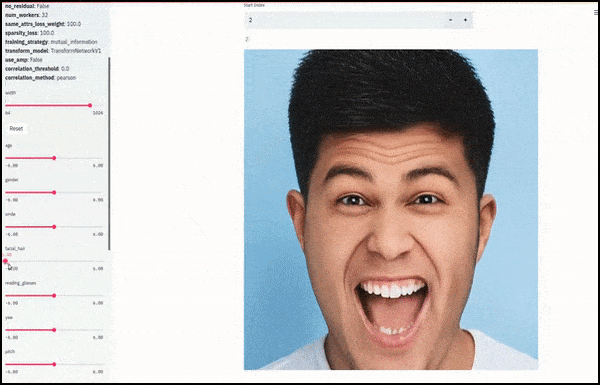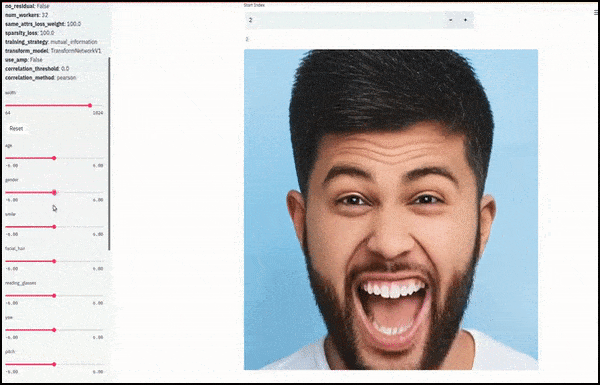
Gender and facial hair modified as sliders plot random and arbitrary paths by means of the latent area, not simply ‘scrubbing between endpoints’. See video embedded at finish of article for extra transformations at higher decision.
Among the many foremost achievements within the work is the community’s capacity to ‘freeze’ identities within the latent area by altering solely the attribute in a goal vector, and offering ‘correction phrases’ that preserve identities being reworked.
Primarily, the proposed community is embedded in a broader structure that orchestrates all of the processed components, which move by means of pre-trained elements with frozen weights that won’t produce undesirable lateral results on transformations.
For the reason that coaching course of depends on triplets that may be generated both by a seed picture (below GAN inversion) or an current preliminary latent encoding, your entire coaching course of is unsupervised, with the tacit actions of the customary vary of labeling and curation methods in such methods successfully baked into the structure. In actual fact, the brand new system makes use of off-the-shelf attribute regressors:
‘[The] variety of attributes that our community can independently management is just restricted by the capabilities of the recognizer(s) – if one has a recognizer for an attribute, we will add it to arbitrary faces. In our experiments, we skilled the latent-to-latent community to permit the adjustment of 35 totally different facial attributes, greater than any earlier strategy.’
The system incorporates an extra safeguard towards undesired ‘side-effect’ transformations: within the absence of a request for an attribute change, the latent-to-latent community will map a latent vector to itself, additional growing secure persistence of the goal identification.
Facial Recognition
One recurring challenge with GAN and encoder/decoder-based face editors of the previous few years has been that utilized transformations are likely to degrade resemblance. To fight this, the Adobe mission makes use of an embedded facial recognition community referred to as FaceNet as a discriminator.

Venture structure, see decrease mid-left for inclusion of FaceNet. Supply: Latent to Latent: A Discovered Mapper for Id Preserving Enhancing of A number of Face Attributes in StyleGAN-generated Photographs, OpenAccess.
(On a private word, this appears an encouraging transfer towards the combination of ordinary facial identification and even expression recognition methods into generative networks, arguably one of the best ways ahead for overcoming the blind pixel>pixel mapping that dominates present deepfake architectures on the expense of expression constancy and different necessary domains within the face era sector.)
Entry All Areas within the Latent House
One other spectacular characteristic of the framework is its capacity to journey arbitrarily between potential transformations within the latent area, at consumer whim. A number of prior methods that offered exploratory interfaces usually left the consumer primarily ‘scrubbing’ between mounted characteristic transformation timelines – spectacular, however usually fairly a linear or proscriptive expertise.
From Bettering GAN Equilibrium by Elevating Spatial Consciousness: right here the consumer scrubs by means of a spread of potential transition factors between two latent area places, however inside the confines of pre-trained places within the latent area. To use other forms of transformation primarily based on the identical materials, reconfiguration and/or retraining is important. Supply: https://genforce.github.io/eqgan/
Along with being receptive to thoroughly novel consumer photographs, the consumer may also manually ‘freeze’ components that they wish to be conserved throughout the transformation course of. On this method the consumer can be certain that (as an illustration) backgrounds don’t shift, or that eyes are stored open or closed.
Information
The attribute regression community was skilled on three networks: FFHQ, CelebAMask-HQ, and an area, GAN-generated community obtained by sampling 400,000 vectors from the Z area of StyleGAN-V2.
Out-of-distribution (OOD) photographs have been filtered away, and attributes extracted utilizing Microsoft’s Face API, with the ensuing image-set cut up 90/10, leaving 721,218 coaching photographs and 72,172 check photographs to match towards.
Testing
Although the experimental community was initially configured to accommodate 35 potential transformations, these have been slimmed right down to eight with the intention to undertake analogous testing towards the comparable frameworks InterFaceGAN, GANSpace, and StyleFlow.
The eight chosen attributes have been Age, Baldness, Beard, Expression, Gender, Glasses, Pitch, and Yaw. It was essential to retool the competing frameworks for sure of the eight attributes that weren’t provisioned within the unique distribution, equivalent to including baldness and beard to InterFaceGAN.
As anticipated, a better stage of entanglement occurred within the rival architectures. As an example, in a single check, InterFaceGAN and StyleFlow each modified the gender of the topic when requested to use age:

Two of the competing frameworks rolled a gender develop into the ‘age’ transformation, additionally altering hair coloration with out direct bidding of the consumer.
Moreover, two of the rivals discovered that glasses and age are inseparable aspects:

Glasses and hair coloration change thrown in at no further cost!
It’s not a uniform victory for the analysis: as will be seen within the accompanying video embedded on the finish of the article, the framework is the least efficient when making an attempt to extrapolate various angles (yaw), whereas GANSpace has a greater normal outcome for age and the imposition of glasses. The latent-to-latent framework tied with GANSpace and StyleFlow concerning the including of pitch (angle of head).

Outcomes calculated primarily based on a calibration of the MTCNN face detector. Decrease outcomes are higher.
For additional particulars and higher decision of examples, try the paper’s accompanying video beneath.
First revealed sixteenth February 2022.
[ad_2]

