


[ad_1]
In comparison with different programming workout routines, a machine studying undertaking is a mix of code and knowledge. You want each to realize the outcome and do one thing helpful. Through the years, many well-known datasets have been created, and plenty of have develop into requirements or benchmarks. On this tutorial, we’re going to see how we will acquire these well-known public datasets simply. We may even learn to make an artificial dataset if not one of the current datasets suits our wants.
After ending this tutorial, you’ll know:
- The place to search for freely out there datasets for machine studying tasks
- obtain datasets utilizing libraries in Python
- generate artificial datasets utilizing scikit-learn
Let’s get began.
A Information to Getting Datasets for Machine Studying in Python
Photograph by Olha Ruskykh. Some rights reserved.
Tutorial Overview
This tutorial is split into 4 elements; they’re:
- Dataset repositories
- Retrieving dataset in scikit-learn and Seaborn
- Retrieving dataset in TensorFlow
- Producing dataset in scikit-learn
Dataset Repositories
Machine studying has been developed for many years, and due to this fact there are some datasets of historic significance. One of the vital well-known repositories for these datasets is the UCI Machine Studying Repository. A lot of the datasets over there are small in dimension as a result of the know-how on the time was not superior sufficient to deal with bigger dimension knowledge. Some well-known datasets situated on this repository are the iris flower dataset (launched by Ronald Fisher in 1936) and the 20 newsgroups dataset (textual knowledge often referred to by data retrieval literature).
Newer datasets are often bigger in dimension. For instance, the ImageNet dataset is over 160 GB. These datasets are generally present in Kaggle, and we will search them by identify. If we have to obtain them, it’s endorsed to make use of Kaggle’s command line instrument after registering for an account.
OpenML is a more moderen repository that hosts a whole lot of datasets. It’s handy as a result of you may seek for the dataset by identify, but it surely additionally has a standardized internet API for customers to retrieve knowledge. It might be helpful if you wish to use Weka because it supplies information in ARFF format.
However nonetheless, many datasets are publicly out there however not in these repositories for varied causes. You might also need to try the “Checklist of datasets for machine-learning analysis” web page Checklist of datasets for machine-learning analysis” on Wikipedia. That web page incorporates an extended listing of datasets attributed to completely different classes, with hyperlinks to obtain them.
Retrieving Datasets in scikit-learn and Seaborn
Trivially, you might acquire these datasets by downloading them from the net, both by means of the browser, through command line, utilizing the wget instrument, or utilizing community libraries reminiscent of requests in Python. Since a few of these datasets have develop into a regular or benchmark, many machine studying libraries have created capabilities to assist retrieve them. For sensible causes, usually, the datasets should not shipped with the libraries however downloaded in actual time if you invoke the capabilities. Due to this fact, it is advisable to have a gentle web connection to make use of them.
Scikit-learn is an instance the place you may obtain the dataset utilizing its API. The associated capabilities are outlined beneath sklearn.datasets,and you might even see the listing of capabilities at:
For instance, you should utilize the operate load_iris() to get the iris flower dataset as follows:
|
import sklearn.datasets
knowledge, goal = sklearn.datasets.load_iris(return_X_y=True, as_frame=True) knowledge[“target”] = goal print(knowledge) |
The load_iris() operate would return numpy arrays (i.e., doesn’t have column headers) as an alternative of pandas DataFrame except the argument as_frame=True is specified. Additionally, we cross return_X_y=True to the operate, so solely the machine studying options and targets are returned, fairly than some metadata reminiscent of the outline of the dataset. The above code prints the next:
|
sepal size (cm) sepal width (cm) petal size (cm) petal width (cm) goal 0 5.1 3.5 1.4 0.2 0 1 4.9 3.0 1.4 0.2 0 2 4.7 3.2 1.3 0.2 0 3 4.6 3.1 1.5 0.2 0 4 5.0 3.6 1.4 0.2 0 .. … … … … … 145 6.7 3.0 5.2 2.3 2 146 6.3 2.5 5.0 1.9 2 147 6.5 3.0 5.2 2.0 2 148 6.2 3.4 5.4 2.3 2 149 5.9 3.0 5.1 1.8 2
[150 rows x 5 columns] |
Separating the options and targets is handy for coaching a scikit-learn mannequin, however combining them could be useful for visualization. For instance, we could mix the DataFrame as above after which visualize the correlogram utilizing Seaborn:
|
import sklearn.datasets import matplotlib.pyplot as plt import seaborn as sns
knowledge, goal = sklearn.datasets.load_iris(return_X_y=True, as_frame=True) knowledge[“target”] = goal sns.pairplot(knowledge, variety=“scatter”, diag_kind=“kde”, hue=“goal”, palette=“muted”, plot_kws={‘alpha’:0.7}) plt.present() |
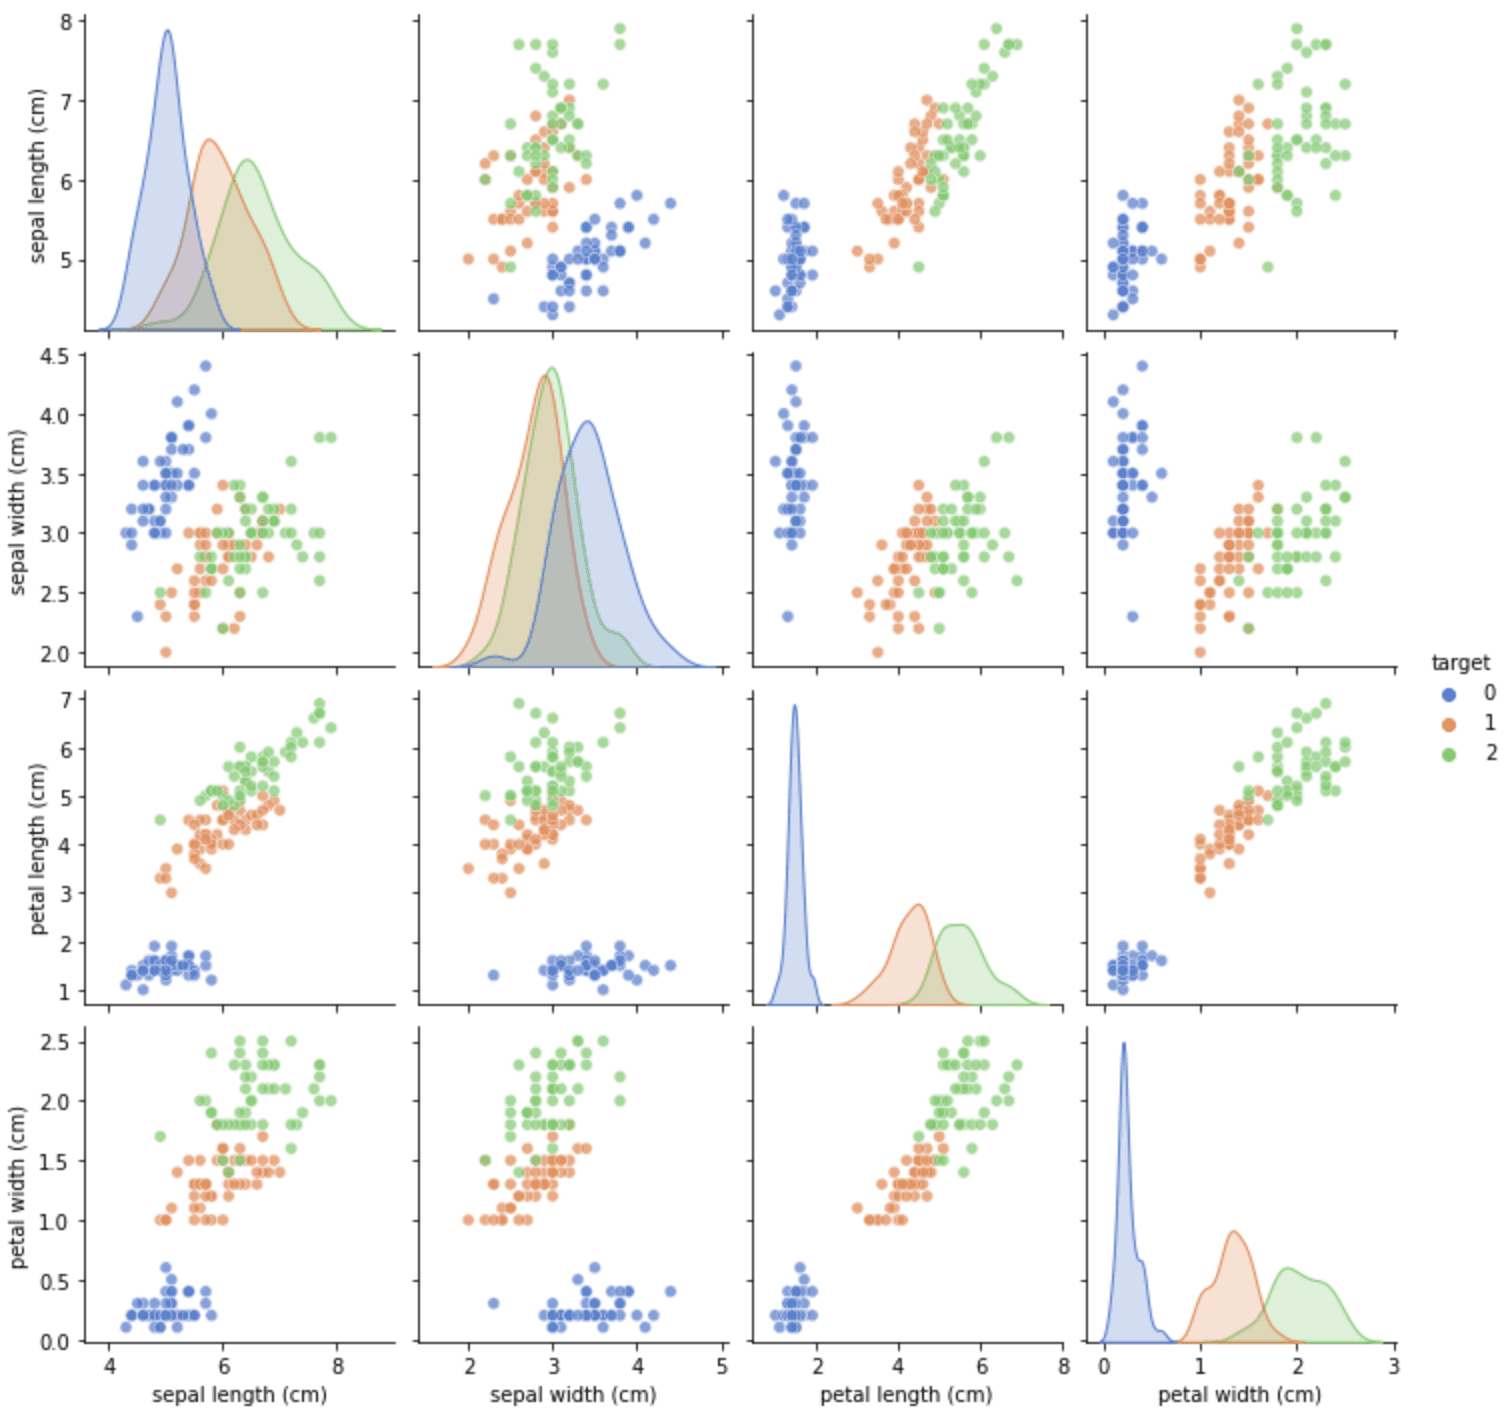
From the correlogram, we will see that focus on 0 is straightforward to differentiate, however targets 1 and a pair of often have some overlap. As a result of this dataset can be helpful to show plotting capabilities, we will discover the equal knowledge loading operate from Seaborn. We will rewrite the above into the next:
|
import matplotlib.pyplot as plt import seaborn as sns knowledge = sns.load_dataset(“iris”) sns.pairplot(knowledge, variety=“scatter”, diag_kind=“kde”, hue=“species”, palette=“muted”, plot_kws={‘alpha’:0.7}) plt.present() |
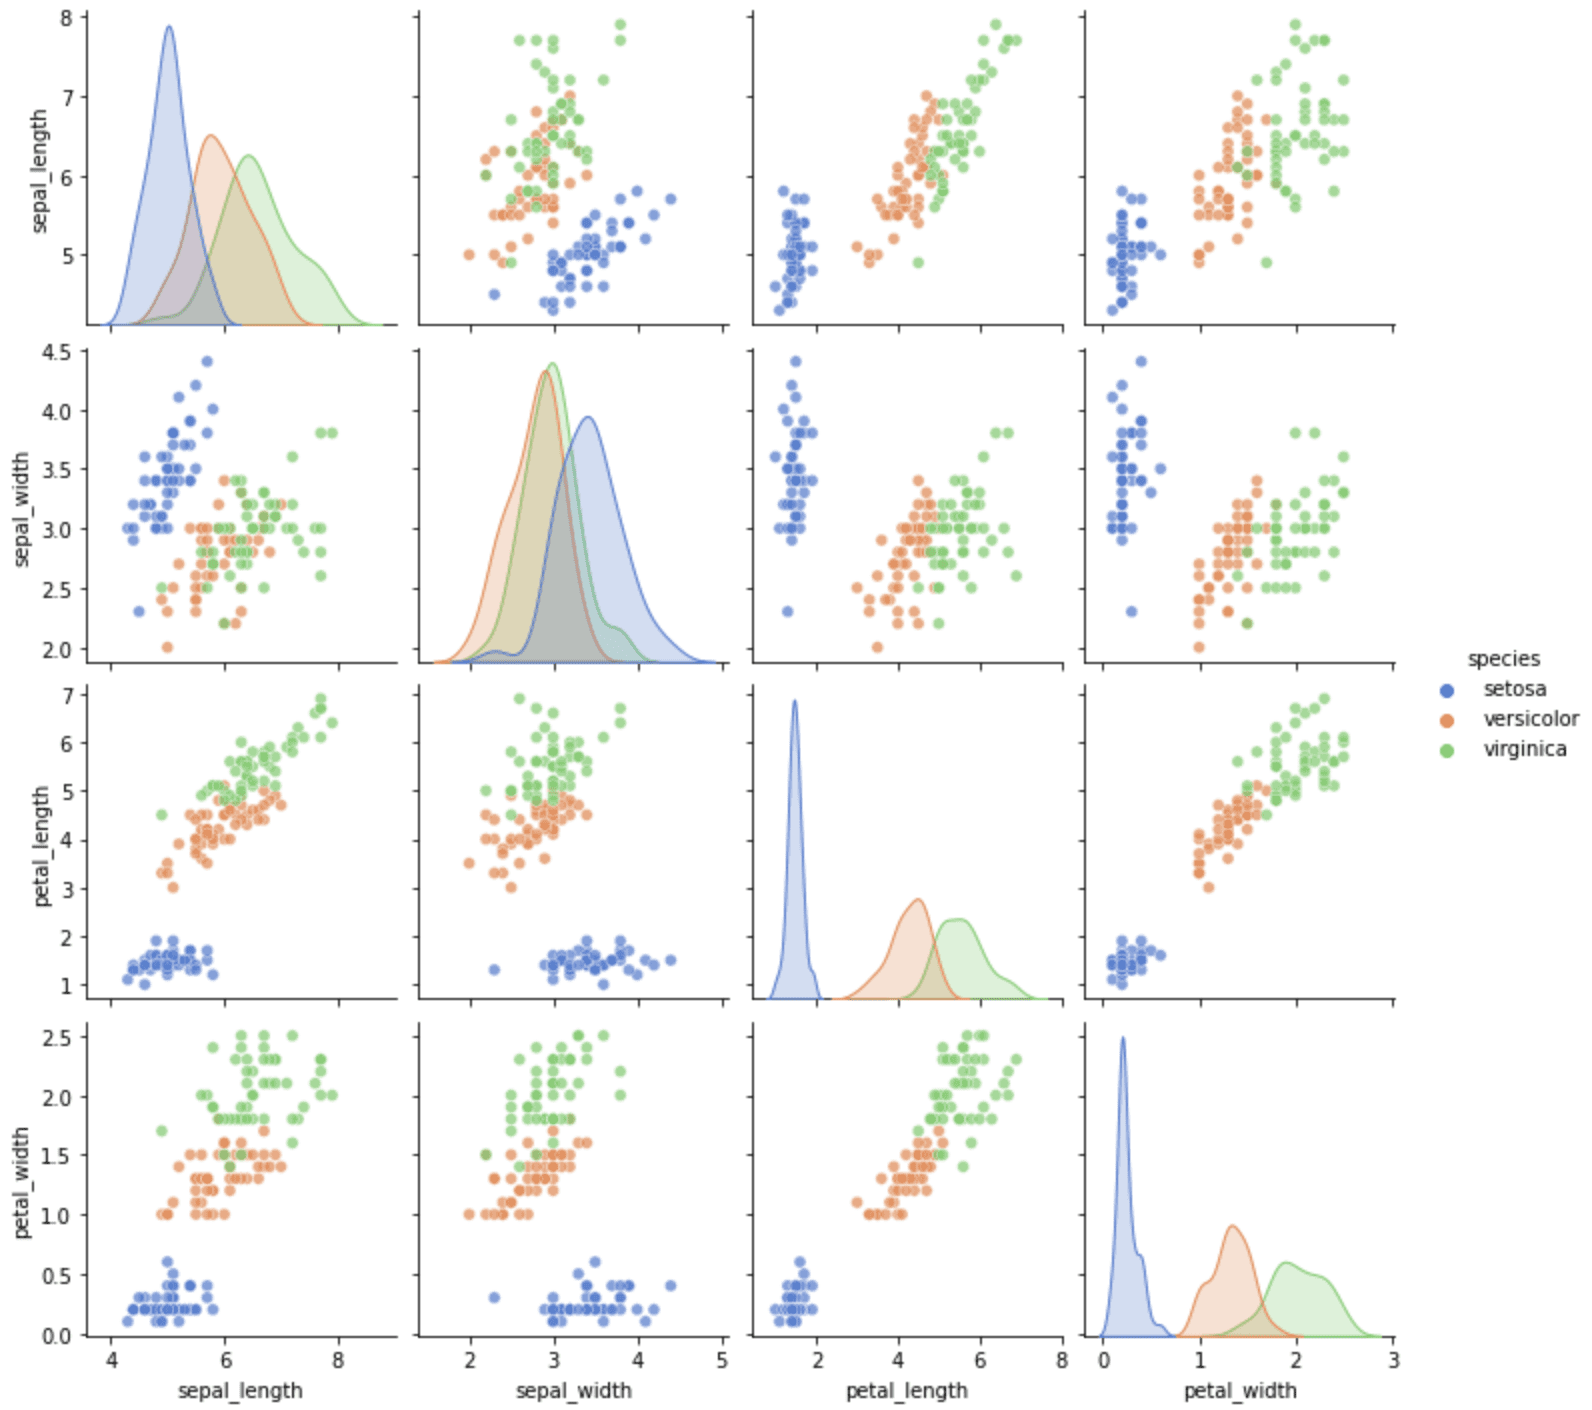
The dataset supported by Seaborn is extra restricted. We will see the names of all supported datasets by operating:
|
import seaborn as sns print(sns.get_dataset_names()) |
the place the next is all of the datasets from Seaborn:
|
[‘anagrams’, ‘anscombe’, ‘attention’, ‘brain_networks’, ‘car_crashes’, ‘diamonds’, ‘dots’, ‘exercise’, ‘flights’, ‘fmri’, ‘gammas’, ‘geyser’, ‘iris’, ‘mpg’, ‘penguins’, ‘planets’, ‘taxis’, ‘tips’, ‘titanic’] |
There are a handful of comparable capabilities to load the “toy datasets” from scikit-learn. For instance, we’ve load_wine() and load_diabetes() outlined in comparable style.
Bigger datasets are additionally comparable. We now have fetch_california_housing(), for instance, that should obtain the dataset from the web (therefore the “fetch” within the operate identify). Scikit-learn documentation calls these the “real-world datasets,” however, the truth is, the toy datasets are equally actual.
|
import sklearn.datasets
knowledge = sklearn.datasets.fetch_california_housing(return_X_y=False, as_frame=True) knowledge = knowledge[“frame”] print(knowledge) |
|
MedInc HouseAge AveRooms AveBedrms Inhabitants AveOccup Latitude Longitude MedHouseVal 0 8.3252 41.0 6.984127 1.023810 322.0 2.555556 37.88 -122.23 4.526 1 8.3014 21.0 6.238137 0.971880 2401.0 2.109842 37.86 -122.22 3.585 2 7.2574 52.0 8.288136 1.073446 496.0 2.802260 37.85 -122.24 3.521 3 5.6431 52.0 5.817352 1.073059 558.0 2.547945 37.85 -122.25 3.413 4 3.8462 52.0 6.281853 1.081081 565.0 2.181467 37.85 -122.25 3.422 … … … … … … … … … … 20635 1.5603 25.0 5.045455 1.133333 845.0 2.560606 39.48 -121.09 0.781 20636 2.5568 18.0 6.114035 1.315789 356.0 3.122807 39.49 -121.21 0.771 20637 1.7000 17.0 5.205543 1.120092 1007.0 2.325635 39.43 -121.22 0.923 20638 1.8672 18.0 5.329513 1.171920 741.0 2.123209 39.43 -121.32 0.847 20639 2.3886 16.0 5.254717 1.162264 1387.0 2.616981 39.37 -121.24 0.894
[20640 rows x 9 columns] |
If we want greater than these, scikit-learn supplies a helpful operate to learn any dataset from OpenML. For instance,
|
import sklearn.datasets
knowledge = sklearn.datasets.fetch_openml(“diabetes”, model=1, as_frame=True, return_X_y=False) knowledge = knowledge[“frame”] print(knowledge) |
|
preg plas pres pores and skin insu mass pedi age class 0 6.0 148.0 72.0 35.0 0.0 33.6 0.627 50.0 tested_positive 1 1.0 85.0 66.0 29.0 0.0 26.6 0.351 31.0 tested_negative 2 8.0 183.0 64.0 0.0 0.0 23.3 0.672 32.0 tested_positive 3 1.0 89.0 66.0 23.0 94.0 28.1 0.167 21.0 tested_negative 4 0.0 137.0 40.0 35.0 168.0 43.1 2.288 33.0 tested_positive .. … … … … … … … … … 763 10.0 101.0 76.0 48.0 180.0 32.9 0.171 63.0 tested_negative 764 2.0 122.0 70.0 27.0 0.0 36.8 0.340 27.0 tested_negative 765 5.0 121.0 72.0 23.0 112.0 26.2 0.245 30.0 tested_negative 766 1.0 126.0 60.0 0.0 0.0 30.1 0.349 47.0 tested_positive 767 1.0 93.0 70.0 31.0 0.0 30.4 0.315 23.0 tested_negative
[768 rows x 9 columns] |
Generally, we must always not use the identify to determine a dataset in OpenML as there could also be a number of datasets of the identical identify. We will seek for the info ID on OpenML and use it within the operate as follows:
|
import sklearn.datasets
knowledge = sklearn.datasets.fetch_openml(data_id=42437, return_X_y=False, as_frame=True) knowledge = knowledge[“frame”] print(knowledge) |
The info ID within the code above refers back to the titanic dataset. We will lengthen the code into the next to indicate how we will acquire the titanic dataset after which run the logistic regression:
|
from sklearn.linear_model import LogisticRegression from sklearn.datasets import fetch_openml
X, y = fetch_openml(data_id=42437, return_X_y=True, as_frame=False) clf = LogisticRegression(random_state=0).match(X, y) print(clf.rating(X,y)) # accuracy print(clf.coef_) # coefficient in logistic regression |
|
0.8114478114478114 [[-0.7551392 2.24013347 -0.20761281 0.28073571 0.24416706 -0.36699113 0.4782924 ]] |
Retrieving Datasets in TensorFlow
In addition to scikit-learn, TensorFlow is one other instrument that we will use for machine studying tasks. For comparable causes, there’s additionally a dataset API for TensorFlow that offers you the dataset in a format that works greatest with TensorFlow. Not like scikit-learn, the API isn’t a part of the usual TensorFlow package deal. You should set up it utilizing the command:
|
pip set up tensorflow–datasets |
The listing of all datasets is obtainable on the catalog:
All datasets are recognized by a reputation. The names may be discovered within the catalog above. You might also get a listing of names utilizing the next:
|
import tensorflow_datasets as tfds print(tfds.list_builders()) |
which prints greater than 1,000 names.
For example, let’s choose the MNIST handwritten digits dataset for instance. We will obtain the info as follows:
|
import tensorflow_datasets as tfds ds = tfds.load(“mnist”, cut up=“prepare”, shuffle_files=True) print(ds) |
This reveals us that tfds.load() offers us an object of sort tensorflow.knowledge.OptionsDataset:
|
<_OptionsDataset shapes: {picture: (28, 28, 1), label: ()}, sorts: {picture: tf.uint8, label: tf.int64}> |
Specifically, this dataset has the info situations (photographs) in a numpy array of shapes (28,28,1), and the targets (labels) are scalars.
With minor sprucing, the info is prepared to be used within the Keras match() operate. An instance is as follows:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 |
import tensorflow as tf import tensorflow_datasets as tfds from tensorflow.keras.fashions import Sequential from tensorflow.keras.layers import Conv2D, Dense, AveragePooling2D, Dropout, Flatten from tensorflow.keras.callbacks import EarlyStopping
# Learn knowledge with train-test cut up ds_train, ds_test = tfds.load(“mnist”, cut up=[‘train’, ‘test’], shuffle_files=True, as_supervised=True)
# Arrange BatchDataset from the OptionsDataset object ds_train = ds_train.batch(32) ds_test = ds_test.batch(32)
# Construct LeNet5 mannequin and match mannequin = Sequential([ Conv2D(6, (5,5), input_shape=(28,28,1), padding=“same”, activation=“tanh”), AveragePooling2D((2,2), strides=2), Conv2D(16, (5,5), activation=“tanh”), AveragePooling2D((2,2), strides=2), Conv2D(120, (5,5), activation=“tanh”), Flatten(), Dense(84, activation=“tanh”), Dense(10, activation=“softmax”) ]) mannequin.compile(loss=“sparse_categorical_crossentropy”, optimizer=“adam”, metrics=[“sparse_categorical_accuracy”]) earlystopping = EarlyStopping(monitor=“val_loss”, persistence=2, restore_best_weights=True) mannequin.match(ds_train, validation_data=ds_test, epochs=100, callbacks=[earlystopping]) |
If we offered as_supervised=True, the dataset could be information of tuples (options, targets) as an alternative of the dictionary. It’s required for Keras. Furthermore, to make use of the dataset within the match() operate, we have to create an iterable of batches. That is achieved by establishing the batch dimension of the dataset to transform it from OptionsDataset object into BatchDataset object.
We utilized the LeNet5 mannequin for the picture classification. However because the goal within the dataset is a numerical worth (0 to 9) fairly than a Boolean vector, we ask Keras to transform the softmax output vector right into a quantity earlier than computing accuracy and loss by specifying sparse_categorical_accuracy and sparse_categorical_crossentropy within the compile() operate.
The important thing right here is to grasp each dataset is in a unique form. If you use it along with your TensorFlow mannequin, it is advisable to adapt your mannequin to suit the dataset.
Producing Datasets in scikit-learn
In scikit-learn, there’s a set of very helpful capabilities to generate a dataset with specific properties. As a result of we will management the properties of the artificial dataset, it’s useful to judge the efficiency of our fashions in a particular scenario that isn’t generally seen in different datasets.
Scikit-learn documentation calls these capabilities the samples generator. It’s simple to make use of; for instance:
|
from sklearn.datasets import make_circles import matplotlib.pyplot as plt
knowledge, goal = make_circles(n_samples=500, shuffle=True, issue=0.7, noise=0.1) plt.determine(figsize=(6,6)) plt.scatter(knowledge[:,0], knowledge[:,1], c=goal, alpha=0.8, cmap=“Set1”) plt.present() |
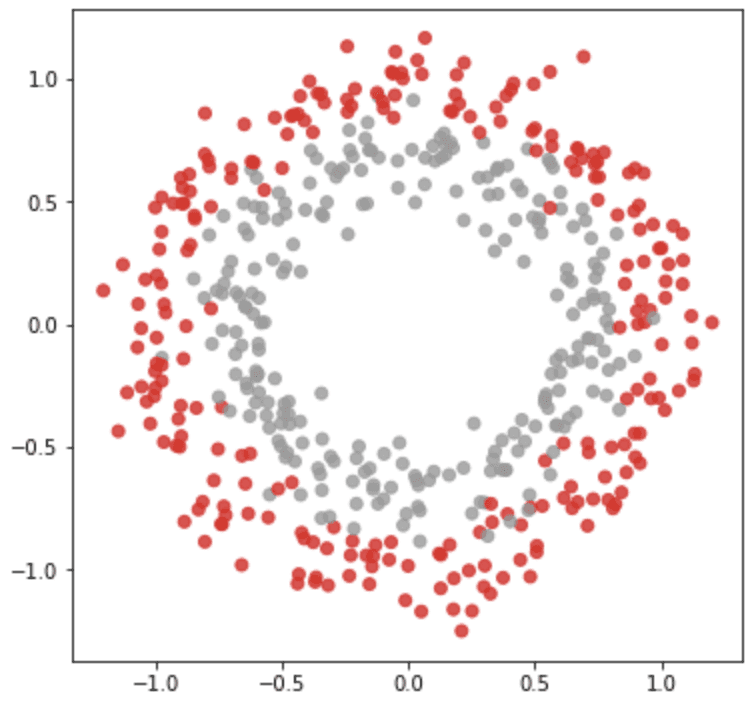
The make_circles() operate generates coordinates of scattered factors in a 2D airplane such that there are two lessons positioned within the type of concentric circles. We will management the scale and overlap of the circles with the parameters issue and noise within the argument. This artificial dataset is useful to judge classification fashions reminiscent of a assist vector machine since there is no such thing as a linear separator out there.
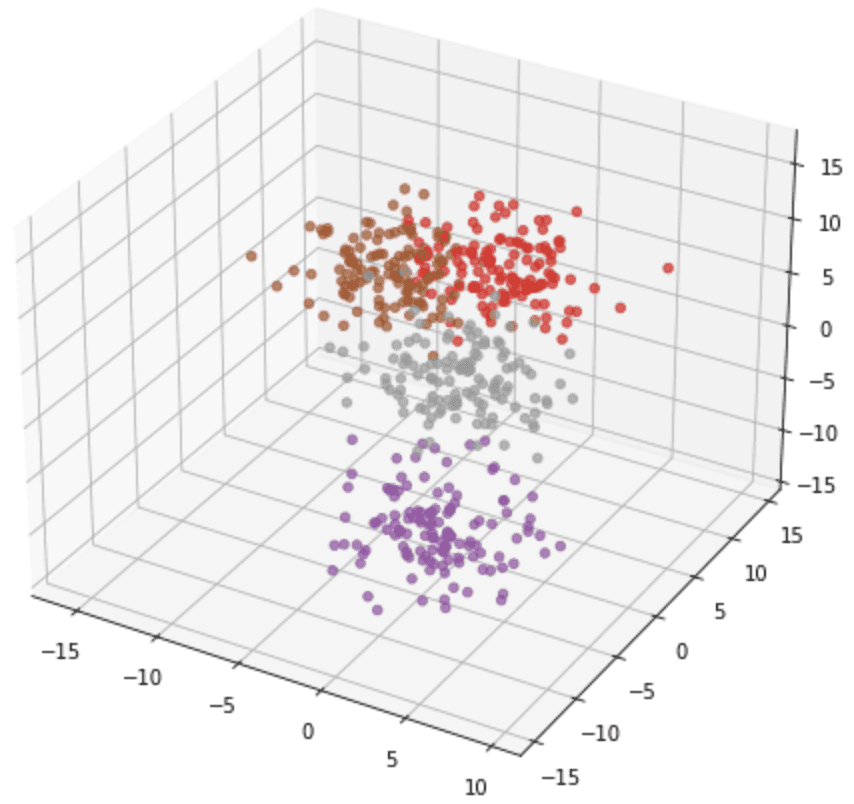
The output from make_circles() is at all times in two lessons, and the coordinates are at all times in 2D. However another capabilities can generate factors of extra lessons or in larger dimensions, reminiscent of make_blob(). Within the instance under, we generate a dataset in 3D with 4 lessons:
|
from sklearn.datasets import make_blobs import matplotlib.pyplot as plt
knowledge, goal = make_blobs(n_samples=500, n_features=3, facilities=4, shuffle=True, random_state=42, cluster_std=2.5)
fig = plt.determine(figsize=(8,8)) ax = fig.add_subplot(projection=‘3d’) ax.scatter(knowledge[:,0], knowledge[:,1], knowledge[:,2], c=goal, alpha=0.7, cmap=“Set1”) plt.present() |
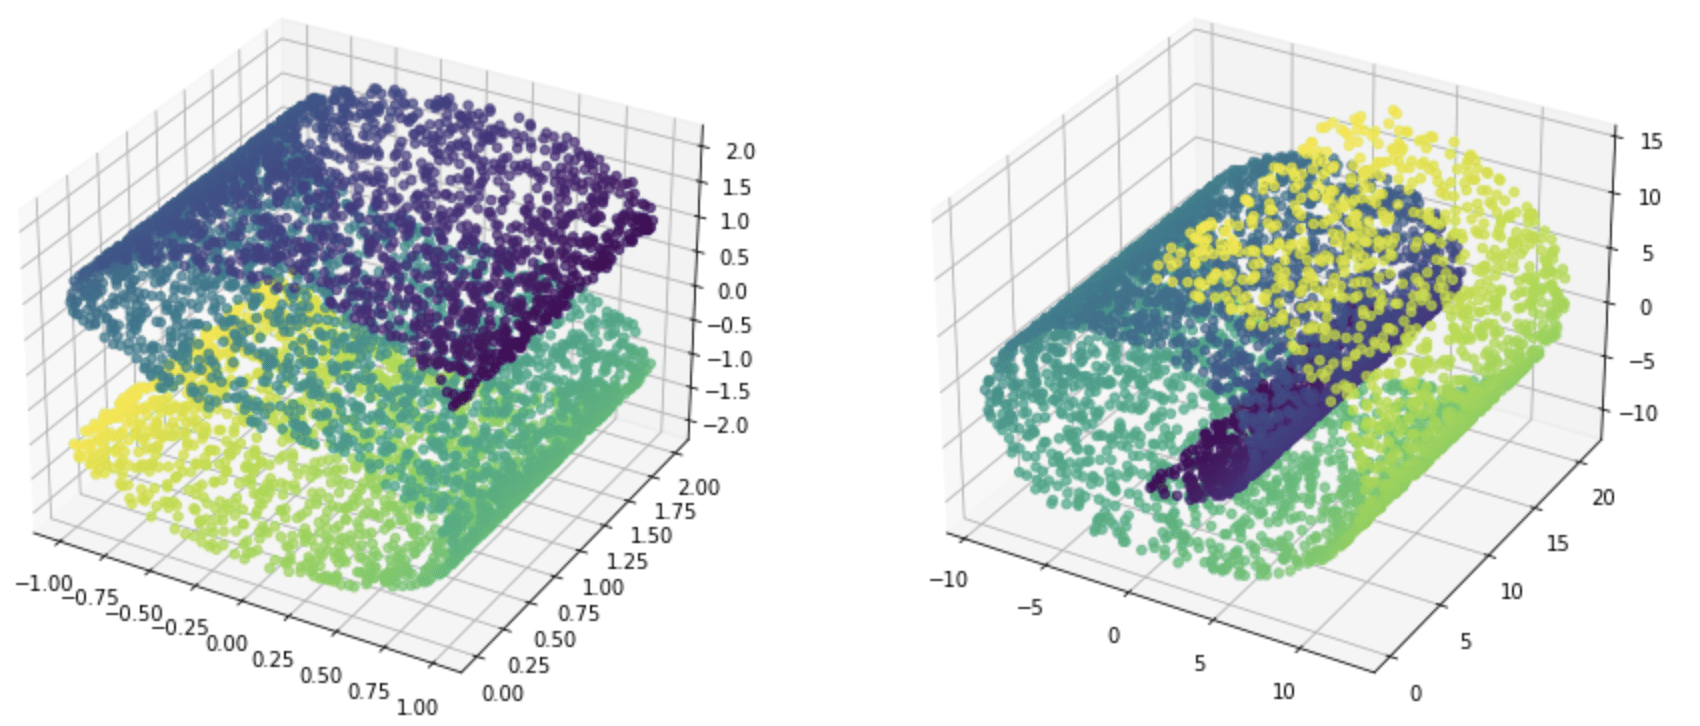
There are additionally some capabilities to generate a dataset for regression issues. For instance, make_s_curve() and make_swiss_roll() will generate coordinates in 3D with targets as steady values.
|
from sklearn.datasets import make_s_curve, make_swiss_roll import matplotlib.pyplot as plt
knowledge, goal = make_s_curve(n_samples=5000, random_state=42)
fig = plt.determine(figsize=(15,8)) ax = fig.add_subplot(121, projection=‘3d’) ax.scatter(knowledge[:,0], knowledge[:,1], knowledge[:,2], c=goal, alpha=0.7, cmap=“viridis”)
knowledge, goal = make_swiss_roll(n_samples=5000, random_state=42) ax = fig.add_subplot(122, projection=‘3d’) ax.scatter(knowledge[:,0], knowledge[:,1], knowledge[:,2], c=goal, alpha=0.7, cmap=“viridis”)
plt.present() |
If we desire not to take a look at the info from a geometrical perspective, there are additionally make_classification() and make_regression(). In comparison with the opposite capabilities, these two present us extra management over the function units, reminiscent of introducing some redundant or irrelevant options.
Under is an instance of utilizing make_regression() to generate a dataset and run linear regression with it:
|
from sklearn.datasets import make_regression from sklearn.linear_model import LinearRegression import numpy as np
# Generate 10-dimensional options and 1-dimensional targets X, y = make_regression(n_samples=500, n_features=10, n_targets=1, n_informative=4, noise=0.5, bias=–2.5, random_state=42)
# Run linear regression on the info reg = LinearRegression() reg.match(X, y)
# Print the coefficient and intercept discovered with np.printoptions(precision=5, linewidth=100, suppress=True): print(np.array(reg.coef_)) print(reg.intercept_) |
Within the instance above, we created 10-dimensional options, however solely 4 of them are informative. Therefore from the results of the regression, we discovered solely 4 of the coefficients are considerably non-zero.
|
[-0.00435 -0.02232 19.0113 0.04391 46.04906 -0.02882 -0.05692 28.61786 -0.01839 16.79397] -2.5106367126731413 |
An instance of utilizing make_classification() equally is as follows. A assist vector machine classifier is used on this case:
|
from sklearn.datasets import make_classification from sklearn.svm import SVC import numpy as np
# Generate 10-dimensional options and 3-class targets X, y = make_classification(n_samples=1000, n_features=10, n_classes=3, n_informative=4, n_redundant=2, n_repeated=1, random_state=42)
# Run SVC on the info clf = SVC(kernel=“rbf”) clf.match(X, y)
# Print the accuracy print(clf.rating(X, y)) |
Additional Studying
This part supplies extra assets on the subject in case you are trying to go deeper.
Repositories
Articles
APIs
Abstract
On this tutorial, you found varied choices for loading a typical dataset or producing one in Python.
Particularly, you discovered:
- use the dataset API in scikit-learn, Seaborn, and TensorFlow to load frequent machine studying datasets
- The small variations within the format of the dataset returned by completely different APIs and the best way to use them
- generate a dataset utilizing scikit-learn
[ad_2]

