


[ad_1]
Final Up to date on March 29, 2022
Datasets from real-world situations are essential for constructing and testing machine studying fashions. You could simply need to have some information to experiment with an algorithm. You may additionally need to consider your mannequin by establishing a benchmark or figuring out its weaknesses utilizing totally different units of information. Typically, you may additionally need to create artificial datasets, the place you may take a look at your algorithms underneath managed circumstances by including noise, correlations, or redundant data to the info.
On this publish, we’ll illustrate how you should utilize Python to fetch some real-world time-series information from totally different sources. We’ll additionally create artificial time-series information utilizing Python’s libraries.
After finishing this tutorial, you’ll know:
- How one can use the
pandas_datareader - How one can name an online information server’s APIs utilizing the
requestslibrary - How one can generate artificial time-series information
Let’s get began.

A Information to Working With Datasets in Python
Picture by Mehreen Saeed, some rights reserved
Tutorial Overview
This tutorial is split into three elements; they’re:
- Utilizing
pandas_datareader - Utilizing the
requestslibrary to fetch information utilizing the distant server’s APIs - Generate artificial time-series information
Loading Knowledge Utilizing pandas-datareader
This publish will rely on a couple of libraries. In case you haven’t put in them in your system, you might set up them utilizing pip:
|
pip set up pandas_datareader requests |
The pandas_datareader library lets you fetch information from totally different sources, together with Yahoo Finance for monetary market information, World Financial institution for world improvement information, and St. Louis Fed for financial information. On this part, we’ll present how one can load information from totally different sources.
Behind the scene, pandas_datareader pulls the info you need from the net in actual time and assembles it right into a pandas DataFrame. Due to the vastly totally different construction of net pages, every information supply wants a special reader. Therefore, pandas_datareader solely helps studying from a restricted variety of sources, largely associated to monetary and financial time sequence.
Fetching information is easy. For instance, we all know that the inventory ticker for Apple is AAPL, so we are able to get the day by day historic costs of Apple inventory from Yahoo Finance as follows:
|
import pandas_datareader as pdr
# Studying Apple shares from yahoo finance server shares_df = pdr.DataReader(‘AAPL’, ‘yahoo’, begin=‘2021-01-01’, finish=‘2021-12-31’) # Take a look at the info learn print(shares_df) |
The decision to DataReader() requires the primary argument to specify the ticker and the second argument the info supply. The above code prints the DataFrame:
|
Excessive Low Open Shut Quantity Adj Shut Date 2021-01-04 133.610001 126.760002 133.520004 129.410004 143301900.0 128.453461 2021-01-05 131.740005 128.429993 128.889999 131.009995 97664900.0 130.041611 2021-01-06 131.050003 126.379997 127.720001 126.599998 155088000.0 125.664215 2021-01-07 131.630005 127.860001 128.360001 130.919998 109578200.0 129.952271 2021-01-08 132.630005 130.229996 132.429993 132.050003 105158200.0 131.073914 … … … … … … … 2021-12-27 180.419998 177.070007 177.089996 180.330002 74919600.0 180.100540 2021-12-28 181.330002 178.529999 180.160004 179.289993 79144300.0 179.061859 2021-12-29 180.630005 178.139999 179.330002 179.380005 62348900.0 179.151749 2021-12-30 180.570007 178.089996 179.470001 178.199997 59773000.0 177.973251 2021-12-31 179.229996 177.259995 178.089996 177.570007 64062300.0 177.344055
[252 rows x 6 columns] |
We can also fetch the inventory value historical past from a number of corporations with the tickers in a listing:
|
corporations = [‘AAPL’, ‘MSFT’, ‘GE’] shares_multiple_df = pdr.DataReader(corporations, ‘yahoo’, begin=‘2021-01-01’, finish=‘2021-12-31’) print(shares_multiple_df.head()) |
and the outcome could be a DataFrame with multi-level columns:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 |
Attributes Adj Shut Shut Symbols AAPL MSFT GE AAPL MSFT Date 2021-01-04 128.453461 215.434982 83.421600 129.410004 217.690002 2021-01-05 130.041611 215.642776 85.811905 131.009995 217.899994 2021-01-06 125.664223 210.051315 90.512833 126.599998 212.250000 2021-01-07 129.952286 216.028732 89.795753 130.919998 218.289993 2021-01-08 131.073944 217.344986 90.353485 132.050003 219.619995
…
Attributes Quantity Symbols AAPL MSFT GE Date 2021-01-04 143301900.0 37130100.0 9993688.0 2021-01-05 97664900.0 23823000.0 10462538.0 2021-01-06 155088000.0 35930700.0 16448075.0 2021-01-07 109578200.0 27694500.0 9411225.0 2021-01-08 105158200.0 22956200.0 9089963.0 |
Due to the construction of DataFrames, it’s handy to extract a part of the info. For instance, we are able to plot solely the day by day shut value on some dates utilizing the next:
|
import matplotlib.pyplot as plt import matplotlib.ticker as ticker
# Common routine for plotting time sequence information def plot_timeseries_df(df, attrib, ticker_loc=1, title=‘Timeseries’, legend=”): fig = plt.determine(figsize=(15,7)) plt.plot(df[attrib], ‘o-‘) _ = plt.xticks(rotation=90) plt.gca().xaxis.set_major_locator(ticker.MultipleLocator(ticker_loc)) plt.title(title) plt.gca().legend(legend) plt.present()
plot_timeseries_df(shares_multiple_df.loc[“2021-04-01”:“2021-06-30”], “Shut”, ticker_loc=3, title=“Shut value”, legend=corporations) |
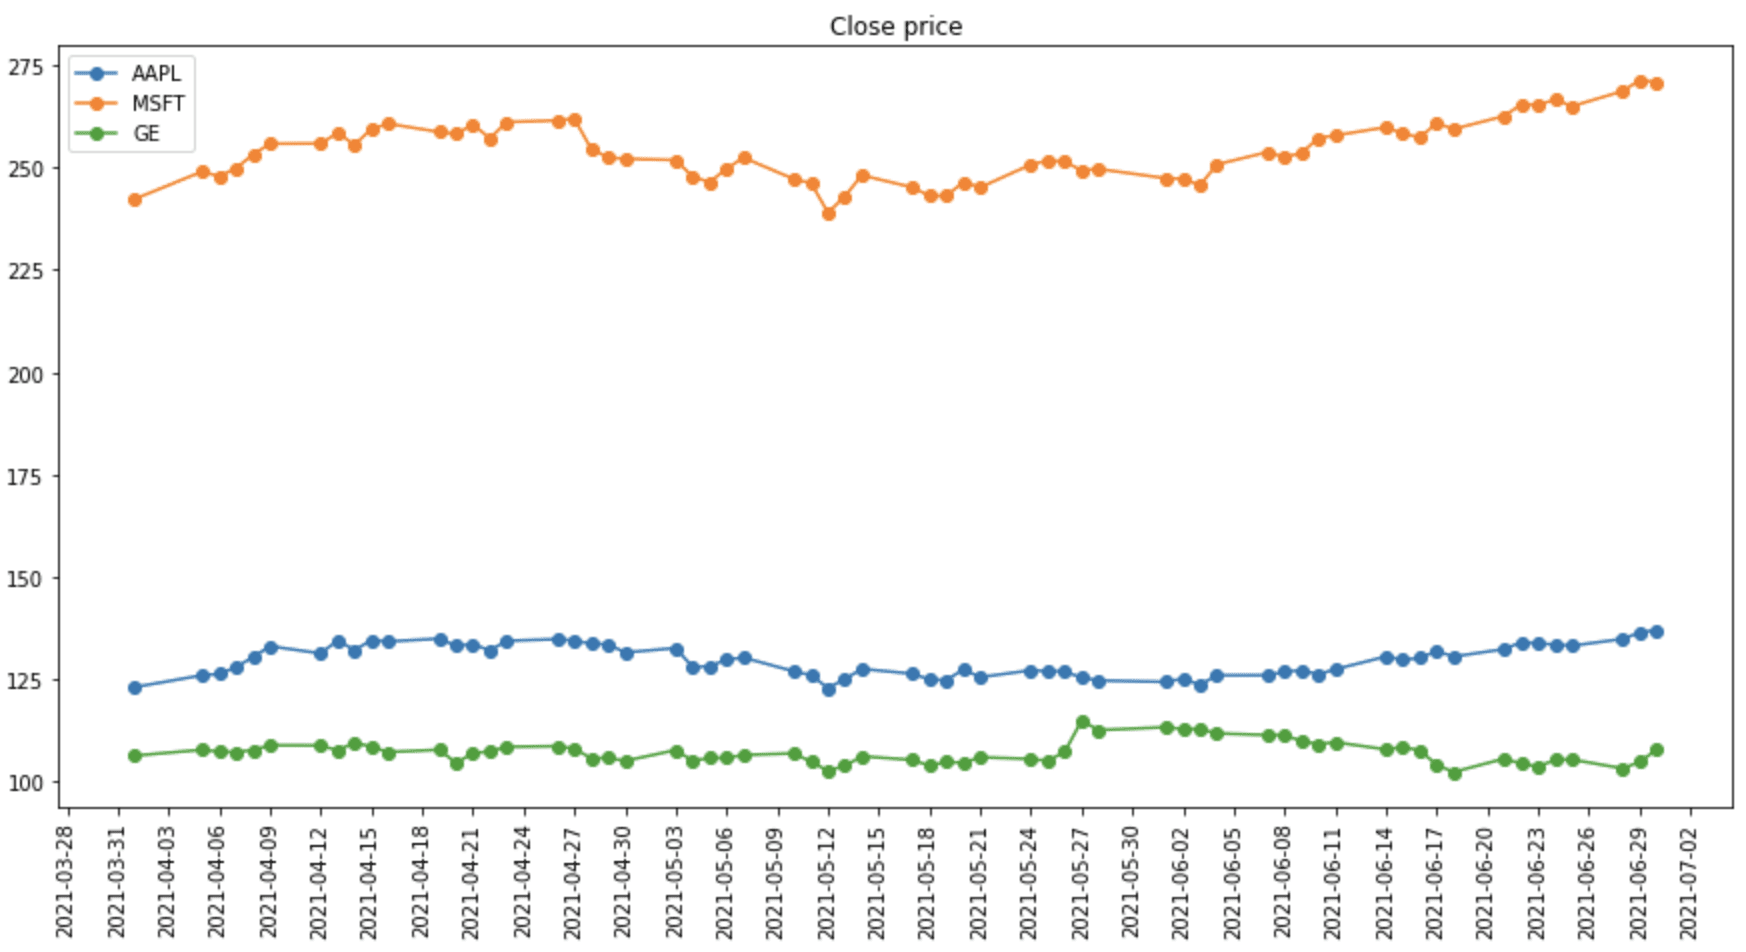
A number of shares fetched from Yahoo Finance
The whole code is as follows:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 |
import pandas_datareader as pdr import matplotlib.pyplot as plt import matplotlib.ticker as ticker
corporations = [‘AAPL’, ‘MSFT’, ‘GE’] shares_multiple_df = pdr.DataReader(corporations, ‘yahoo’, begin=‘2021-01-01’, finish=‘2021-12-31’) print(shares_multiple_df)
def plot_timeseries_df(df, attrib, ticker_loc=1, title=‘Timeseries’, legend=”): “Common routine for plotting time sequence information” fig = plt.determine(figsize=(15,7)) plt.plot(df[attrib], ‘o-‘) _ = plt.xticks(rotation=90) plt.gca().xaxis.set_major_locator(ticker.MultipleLocator(ticker_loc)) plt.title(title) plt.gca().legend(legend) plt.present()
plot_timeseries_df(shares_multiple_df.loc[“2021-04-01”:“2021-06-30”], “Shut”, ticker_loc=3, title=“Shut value”, legend=corporations) |
The syntax for studying from one other information supply utilizing pandas-datareader is comparable. For instance, we are able to learn an financial time sequence from the Federal Reserve Financial Knowledge (FRED). Each time sequence in FRED is recognized by a logo. For instance, the buyer value index for all city customers is CPIAUCSL, the buyer value index for all objects much less meals and power is CPILFESL, and private consumption expenditure is PCE. You’ll be able to search and search for the symbols from FRED’s webpage.
Beneath is how we are able to receive two client value indices, CPIAUCSL and CPILFESL, and present them in a plot:
|
import pandas_datareader as pdr import matplotlib.pyplot as plt
# Learn information from FRED and print fred_df = pdr.DataReader([‘CPIAUCSL’,‘CPILFESL’], ‘fred’, “2010-01-01”, “2021-12-31”) print(fred_df)
# Present in plot the info of 2019-2021 fig = plt.determine(figsize=(15,7)) plt.plot(fred_df.loc[“2019”:], ‘o-‘) plt.xticks(rotation=90) plt.legend(fred_df.columns) plt.title(“Client Value Index”) plt.present() |
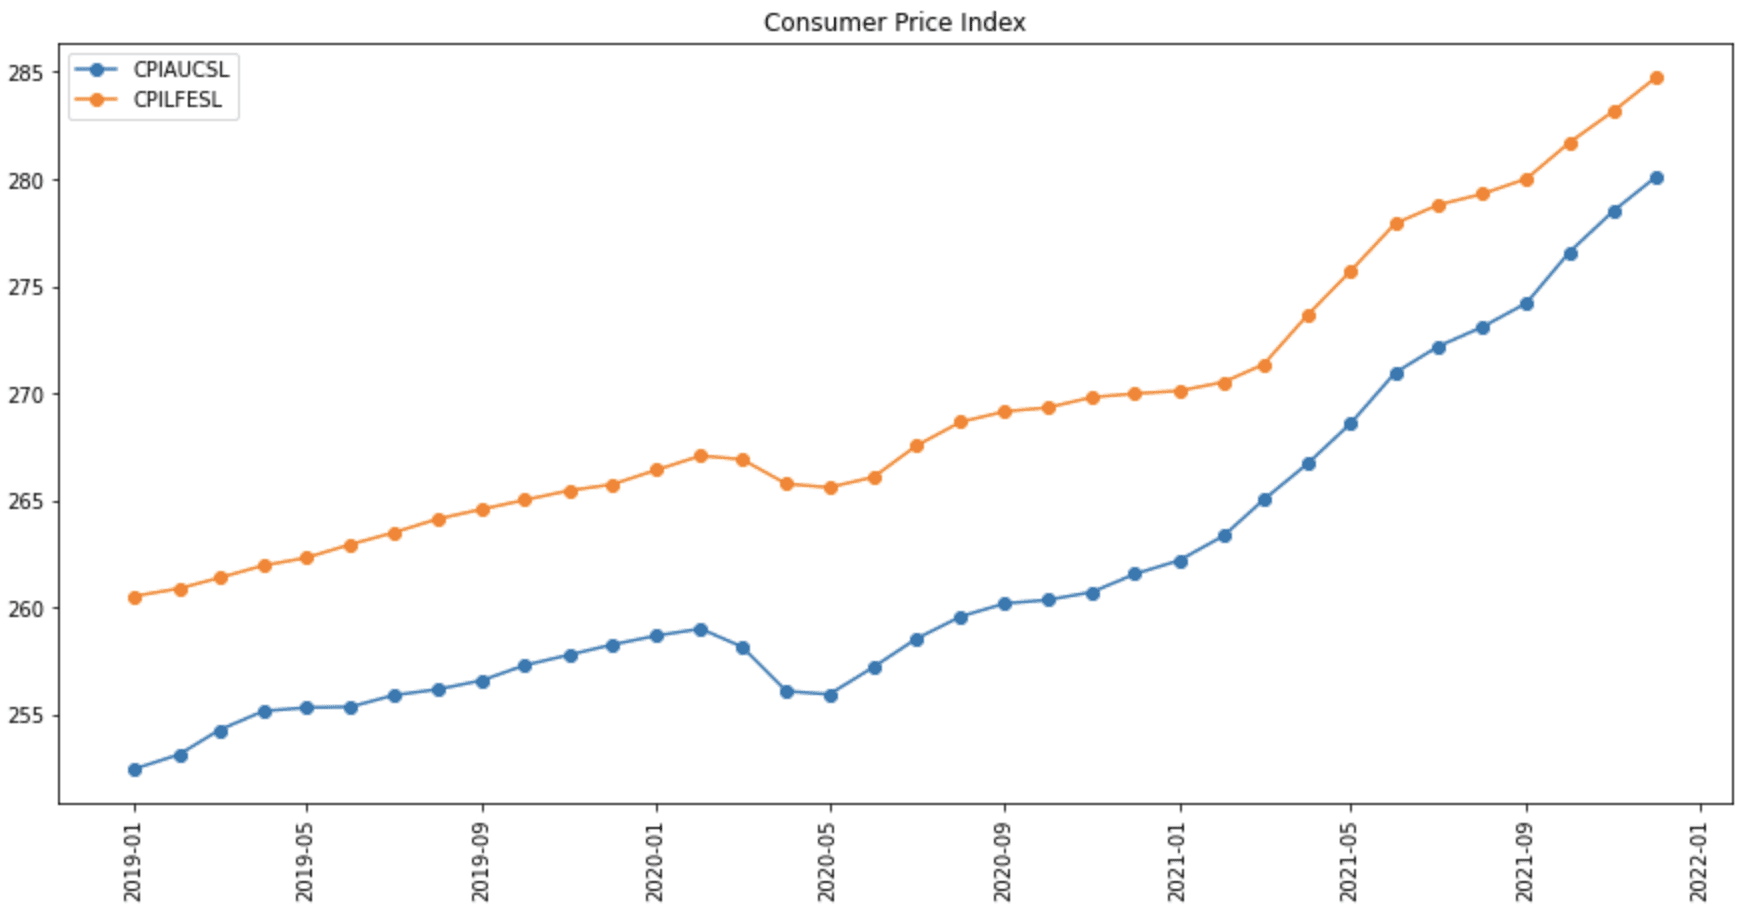
Plot of Client Value Index
Acquiring information from World Financial institution can be related, however we’ve to grasp that the info from World Financial institution is extra difficult. Often, a knowledge sequence, reminiscent of inhabitants, is introduced as a time sequence and likewise has the international locations dimension. Subsequently, we have to specify extra parameters to acquire the info.
Utilizing pandas_datareader, we’ve a particular set of APIs for the World Financial institution. The image for an indicator may be seemed up from World Financial institution Open Knowledge or searched utilizing the next:
|
from pandas_datareader import wb
matches = wb.search(‘complete.*inhabitants’) print(matches[[“id”,“name”]]) |
The search() perform accepts an everyday expression string (e.g., .* above means string of any size). It will print:
|
id title 24 1.1_ACCESS.ELECTRICITY.TOT Entry to electrical energy (% of complete inhabitants) 164 2.1_ACCESS.CFT.TOT Entry to Clear Fuels and Applied sciences for coo... 1999 CC.AVPB.PTPI.AI Further folks beneath $1.90 as % of complete po... 2000 CC.AVPB.PTPI.AR Further folks beneath $1.90 as % of complete po... 2001 CC.AVPB.PTPI.DI Further folks beneath $1.90 as % of complete po... ... ... ... 13908 SP.POP.TOTL.FE.ZS Inhabitants, feminine (% of complete inhabitants) 13912 SP.POP.TOTL.MA.ZS Inhabitants, male (% of complete inhabitants) 13938 SP.RUR.TOTL.ZS Rural inhabitants (% of complete inhabitants) 13958 SP.URB.TOTL.IN.ZS City inhabitants (% of complete inhabitants) 13960 SP.URB.TOTL.ZS Proportion of Inhabitants in City Areas (in % ...
[137 rows x 2 columns] |
the place the id column is the image for the time sequence.
We will learn information for particular international locations by specifying the ISO-3166-1 nation code. However World Financial institution additionally accommodates non-country aggregates (e.g., South Asia), so whereas pandas_datareader permits us to make use of the string “all” for all international locations, often we don’t need to use it. Beneath is how we are able to get a listing of all international locations and aggregates from the World Financial institution:
|
import pandas_datareader.wb as wb
international locations = wb.get_countries() print(international locations) |
|
iso3c iso2c title area adminregion incomeLevel lendingType capitalCity longitude latitude 0 ABW AW Aruba Latin America & … Excessive revenue Not categorised Oranjestad -70.0167 12.5167 1 AFE ZH Africa Jap a… Aggregates Aggregates Aggregates NaN NaN 2 AFG AF Afghanistan South Asia South Asia Low revenue IDA Kabul 69.1761 34.5228 3 AFR A9 Africa Aggregates Aggregates Aggregates NaN NaN 4 AFW ZI Africa Western a… Aggregates Aggregates Aggregates NaN NaN .. … … … … … … … … … … 294 XZN A5 Sub-Saharan Afri… Aggregates Aggregates Aggregates NaN NaN 295 YEM YE Yemen, Rep. Center East & No… Center East & No… Low revenue IDA Sana’a 44.2075 15.3520 296 ZAF ZA South Africa Sub-Saharan Africa Sub-Saharan Afri… Higher center revenue IBRD Pretoria 28.1871 -25.7460 297 ZMB ZM Zambia Sub-Saharan Africa Sub-Saharan Afri… Decrease center revenue IDA Lusaka 28.2937 -15.3982 298 ZWE ZW Zimbabwe Sub-Saharan Africa Sub-Saharan Afri… Decrease center revenue Mix Harare 31.0672 -17.8312 |
Beneath is how we are able to get the inhabitants of all international locations in 2020 and present the highest 25 international locations in a bar chart. Definitely, we are able to additionally get the inhabitants information throughout years by specifying a special begin and finish yr:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 |
import pandas_datareader.wb as wb import pandas as pd import matplotlib.pyplot as plt
# Get a listing of 2-letter nation code excluding aggregates international locations = wb.get_countries() international locations = record(international locations[countries.region != “Aggregates”][“iso2c”])
# Learn international locations’ complete inhabitants information (SP.POP.TOTL) in yr 2020 population_df = wb.obtain(indicator=“SP.POP.TOTL”, nation=international locations, begin=2020, finish=2020)
# Type by inhabitants, then take high 25 international locations, and make the index (i.e., international locations) as a column population_df = (population_df.dropna() .sort_values(“SP.POP.TOTL”) .iloc[–25:] .reset_index())
# Plot the inhabitants, in tens of millions fig = plt.determine(figsize=(15,7)) plt.bar(population_df[“country”], population_df[“SP.POP.TOTL”]/1e6) plt.xticks(rotation=90) plt.ylabel(“Million Inhabitants”) plt.title(“Inhabitants”) plt.present() |
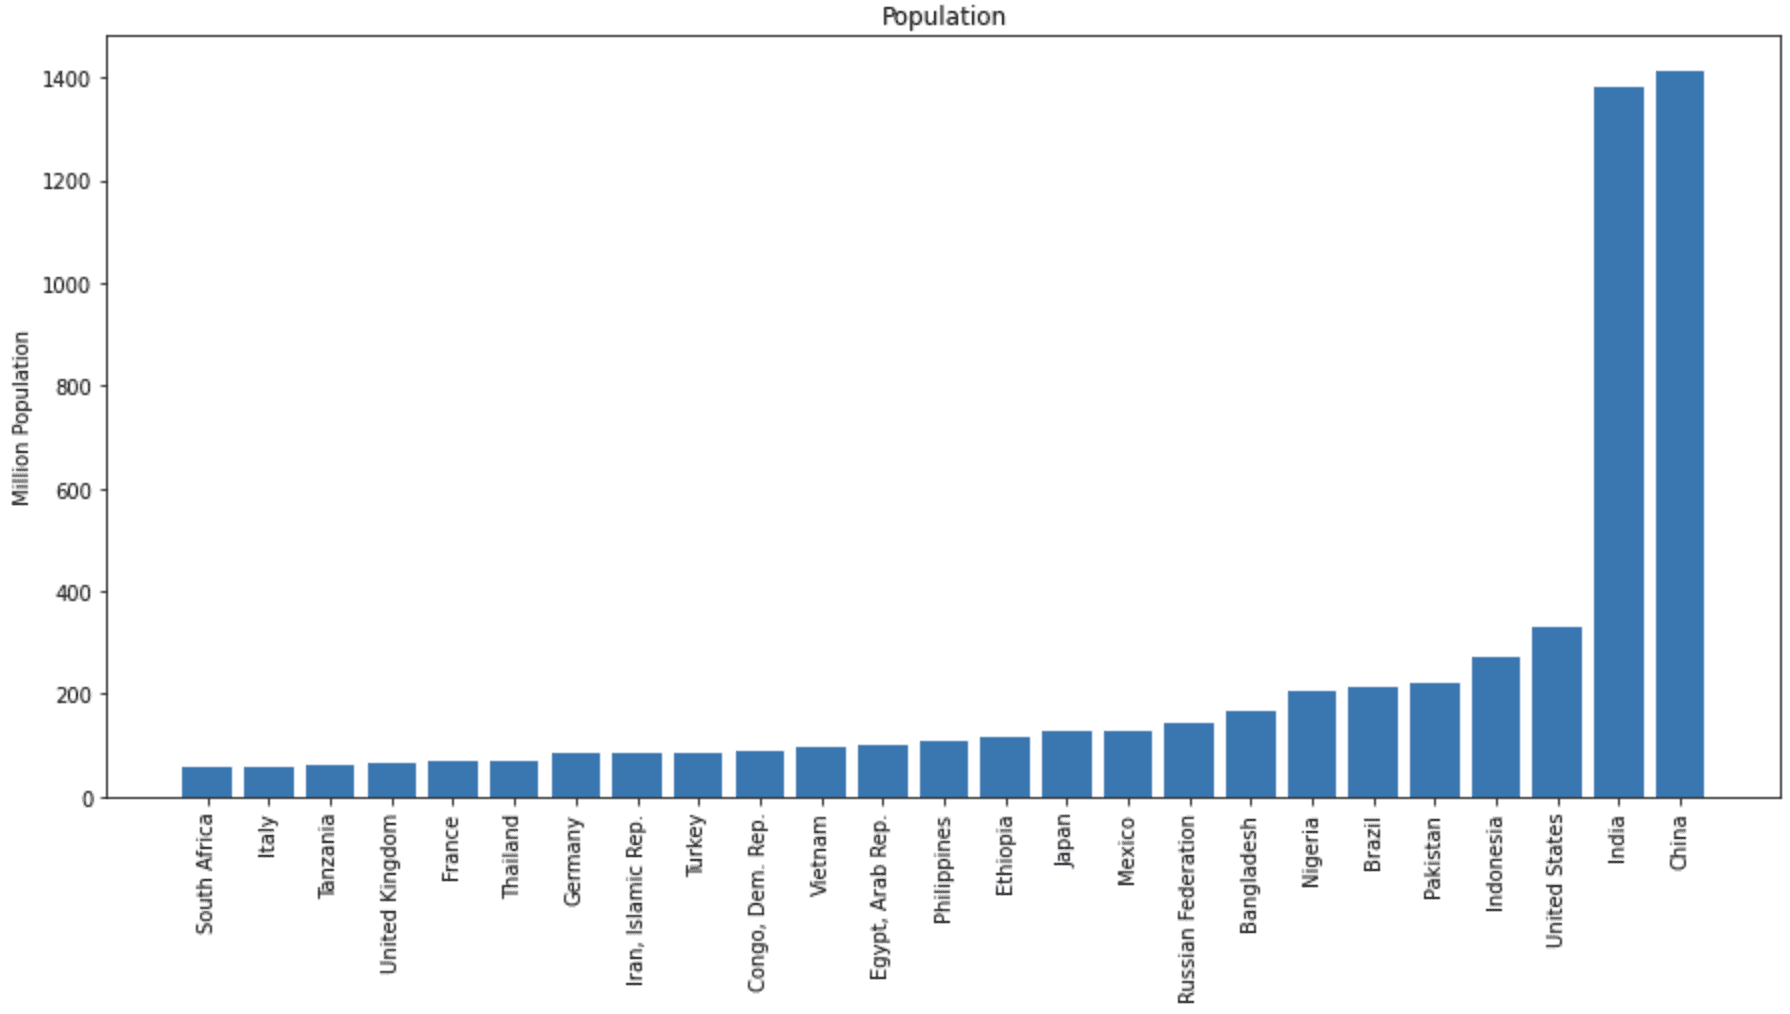
Bar chart of complete inhabitants of various international locations
Fetching Knowledge Utilizing Net APIs
As a substitute of utilizing the pandas_datareader library, generally you will have the choice to fetch information straight from an online information server by calling its net APIs with none authentication wanted. It may be completed in Python utilizing the usual library urllib.requests, or you may additionally use the requests library for a neater interface.
World Financial institution is an instance the place net APIs are freely accessible, so we are able to simply learn information in numerous codecs, reminiscent of JSON, XML, or plain textual content. The web page on the World Financial institution information repository’s API describes numerous APIs and their respective parameters. To repeat what we did within the earlier instance with out utilizing pandas_datareader, we first assemble a URL to learn a listing of all international locations so we are able to discover the nation code that’s not an mixture. Then, we are able to assemble a question URL with the next arguments:
nationargument with worth =allindicatorargument with worth =SP.POP.TOTLdateargument with worth =2020formatargument with worth =json
In fact, you may experiment with totally different indicators. By default, the World Financial institution returns 50 objects on a web page, and we have to question for one web page after one other to exhaust the info. We will enlarge the web page measurement to get all information in a single shot. Beneath is how we get the record of nations in JSON format and accumulate the nation codes:
|
import requests
# Create question URL for record of nations, by default solely 50 entries returned per web page url = “http://api.worldbank.org/v2/nation/all?format=json&per_page=500” response = requests.get(url) # Expects HTTP standing code 200 for proper question print(response.status_code) # Get the response in JSON header, information = response.json() print(header) # Gather a listing of 3-letter nation code excluding aggregates international locations = [item[“id”] for merchandise in information if merchandise[“region”][“value”] != “Aggregates”] print(international locations) |
It can print the HTTP standing code, the header, and the record of nation codes as follows:
|
200 {‘web page’: 1, ‘pages’: 1, ‘per_page’: ‘500’, ‘complete’: 299} [‘ABW’, ‘AFG’, ‘AGO’, ‘ALB’, ..., ‘YEM’, ‘ZAF’, ‘ZMB’, ‘ZWE’] |
From the header, we are able to confirm that we exhausted the info (web page 1 out of 1). Then we are able to get all inhabitants information as follows:
|
...
# Create question URL for complete inhabitants from all international locations in 2020 arguments = { “nation”: “all”, “indicator”: “SP.POP.TOTL”, “date”: “2020:2020”, “format”: “json” } url = “http://api.worldbank.org/v2/nation/{nation}/” “indicator/{indicator}?date={date}&format={format}&per_page=500” query_population = url.format(**arguments) response = requests.get(query_population) # Get the response in JSON header, population_data = response.json() |
It is best to test the World Financial institution API documentation for particulars on the right way to assemble the URL. For instance, the date syntax of 2020:2021 would imply the beginning and finish years, and the additional parameter web page=3 will provide you with the third web page in a multi-page outcome. With the info fetched, we are able to filter for under these non-aggregate international locations, make it right into a pandas DataFrame for sorting, after which plot the bar chart:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 |
...
# Filter for international locations, not aggregates inhabitants = [] for merchandise in population_data: if merchandise[“countryiso3code”] in international locations: title = merchandise[“country”][“value”] inhabitants.append({“nation”:title, “inhabitants”: merchandise[“value”]}) # Create DataFrame for sorting and filtering inhabitants = pd.DataFrame.from_dict(inhabitants) inhabitants = inhabitants.dropna().sort_values(“inhabitants”).iloc[–25:] # Plot bar chart fig = plt.determine(figsize=(15,7)) plt.bar(inhabitants[“country”], inhabitants[“population”]/1e6) plt.xticks(rotation=90) plt.ylabel(“Million Inhabitants”) plt.title(“Inhabitants”) plt.present() |
The determine needs to be exactly the identical as earlier than. However as you may see, utilizing pandas_datareader helps make the code extra concise by hiding the low-level operations.
Placing all the things collectively, the next is the entire code:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 |
import pandas as pd import matplotlib.pyplot as plt import requests
# Create question URL for record of nations, by default solely 50 entries returned per web page url = “http://api.worldbank.org/v2/nation/all?format=json&per_page=500” response = requests.get(url) # Expects HTTP standing code 200 for proper question print(response.status_code) # Get the response in JSON header, information = response.json() print(header) # Gather a listing of 3-letter nation code excluding aggregates international locations = [item[“id”] for merchandise in information if merchandise[“region”][“value”] != “Aggregates”] print(international locations)
# Create question URL for complete inhabitants from all international locations in 2020 arguments = { “nation”: “all”, “indicator”: “SP.POP.TOTL”, “date”: 2020, “format”: “json” } url = “http://api.worldbank.org/v2/nation/{nation}/” “indicator/{indicator}?date={date}&format={format}&per_page=500” query_population = url.format(**arguments) response = requests.get(query_population) print(response.status_code) # Get the response in JSON header, population_data = response.json() print(header)
# Filter for international locations, not aggregates inhabitants = [] for merchandise in population_data: if merchandise[“countryiso3code”] in international locations: title = merchandise[“country”][“value”] inhabitants.append({“nation”:title, “inhabitants”: merchandise[“value”]}) # Create DataFrame for sorting and filtering inhabitants = pd.DataFrame.from_dict(inhabitants) inhabitants = inhabitants.dropna().sort_values(“inhabitants”).iloc[–25:] # Plot bar chart fig = plt.determine(figsize=(15,7)) plt.bar(inhabitants[“country”], inhabitants[“population”]/1e6) plt.xticks(rotation=90) plt.ylabel(“Million Inhabitants”) plt.title(“Inhabitants”) plt.present() |
Creating Artificial Knowledge Utilizing NumPy
Typically, we might not need to use real-world information for our venture as a result of we want one thing particular that won’t occur in actuality. One specific instance is to check out a mannequin with perfect time-series information. On this part, we are going to see how we are able to create artificial autoregressive (AR) time-series information.
The numpy.random library can be utilized to create random samples from totally different distributions. The randn() technique generates information from a normal regular distribution with zero imply and unit variance.
Within the AR($n$) mannequin of order $n$, the worth $x_t$ at time step $t$ relies upon upon the values on the earlier $n$ time steps. That’s,
$$
x_t = b_1 x_{t-1} + b_2 x_{t-2} + … + b_n x_{t-n} + e_t
$$
with mannequin parameters $b_i$ as coefficients to totally different lags of $x_t$, and the error time period $e_t$ is anticipated to observe regular distribution.
Understanding the formulation, we are able to generate an AR(3) time sequence within the instance beneath. We first use randn() to generate the primary 3 values of the sequence after which iteratively apply the above formulation to generate the following information level. Then, an error time period is added utilizing the randn() perform once more, topic to the predefined noise_level:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 |
import numpy as np
# Predefined paramters ar_n = 3 # Order of the AR(n) information ar_coeff = [0.7, –0.3, –0.1] # Coefficients b_3, b_2, b_1 noise_level = 0.1 # Noise added to the AR(n) information size = 200 # Variety of information factors to generate
# Random preliminary values ar_data = record(np.random.randn(ar_n))
# Generate the remainder of the values for i in vary(size – ar_n): next_val = (np.array(ar_coeff) @ np.array(ar_data[–3:])) + np.random.randn() * noise_level ar_data.append(next_val)
# Plot the time sequence fig = plt.determine(figsize=(12,5)) plt.plot(ar_data) plt.present() |
The code above will create the next plot:
However we are able to additional add the time axis by first changing the info right into a pandas DataFrame after which including the time as an index:
|
...
# Convert the info right into a pandas DataFrame artificial = pd.DataFrame({“AR(3)”: ar_data}) artificial.index = pd.date_range(begin=“2021-07-01”, intervals=len(ar_data), freq=“D”)
# Plot the time sequence fig = plt.determine(figsize=(12,5)) plt.plot(artificial.index, artificial) plt.xticks(rotation=90) plt.title(“AR(3) time sequence”) plt.present() |
after which we may have the next plot as a substitute:
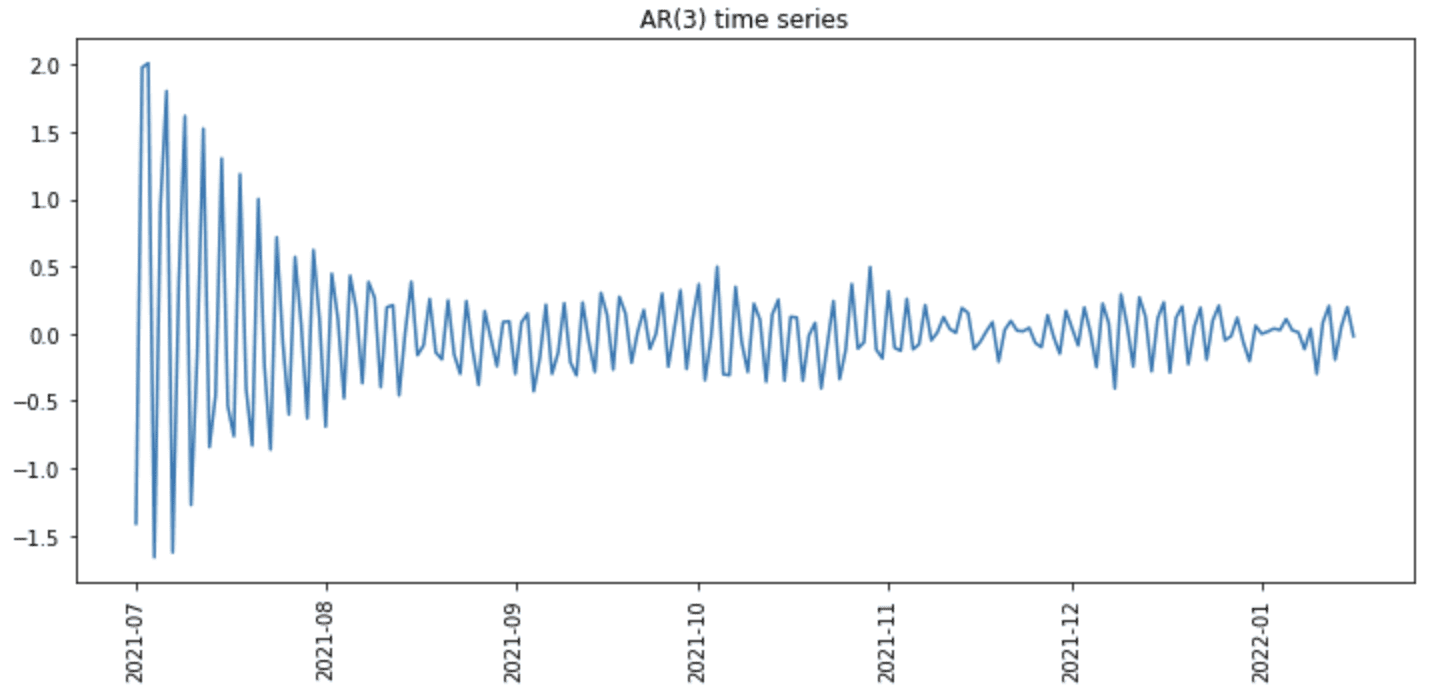
Plot of artificial time sequence
Utilizing related strategies, we are able to generate pure random noise (i.e., AR(0) sequence), ARIMA time sequence (i.e., with coefficients to error phrases), or Brownian movement time sequence (i.e., working sum of random noise) as effectively.
Additional Studying
This part gives extra sources on the subject if you’re trying to go deeper.
Libraries
Knowledge supply
Books
Abstract
On this tutorial, you found numerous choices for fetching information or producing artificial time-series information in Python.
Particularly, you discovered:
- How one can use
pandas_datareaderand fetch monetary information from totally different information sources - How one can name APIs to fetch information from totally different net servers utilizing
the requestslibrary - How one can generate artificial time-series information utilizing NumPy’s random quantity generator
Do you will have any questions in regards to the matters mentioned on this publish? Ask your questions within the feedback beneath, and I’ll do my greatest to reply.
[ad_2]

