


[ad_1]
Labeling information generally is a chore. It’s the primary supply of sustenance for computer-vision fashions; with out it, they’d have loads of issue figuring out objects, folks, and different vital picture traits. But producing simply an hour of tagged and labeled information can take a whopping 800 hours of human time. Our high-fidelity understanding of the world develops as machines can higher understand and work together with our environment. However they want extra assist.
Scientists from MIT’s Laptop Science and Synthetic Intelligence Laboratory (CSAIL), Microsoft, and Cornell College have tried to unravel this downside plaguing imaginative and prescient fashions by creating “STEGO,” an algorithm that may collectively uncover and phase objects with none human labels in any respect, right down to the pixel.
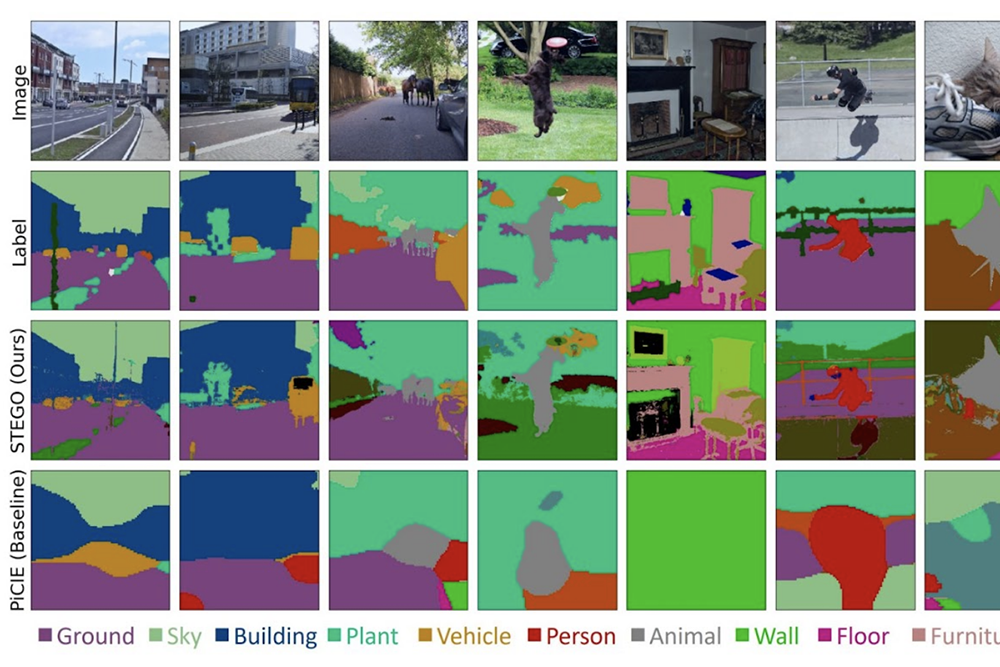
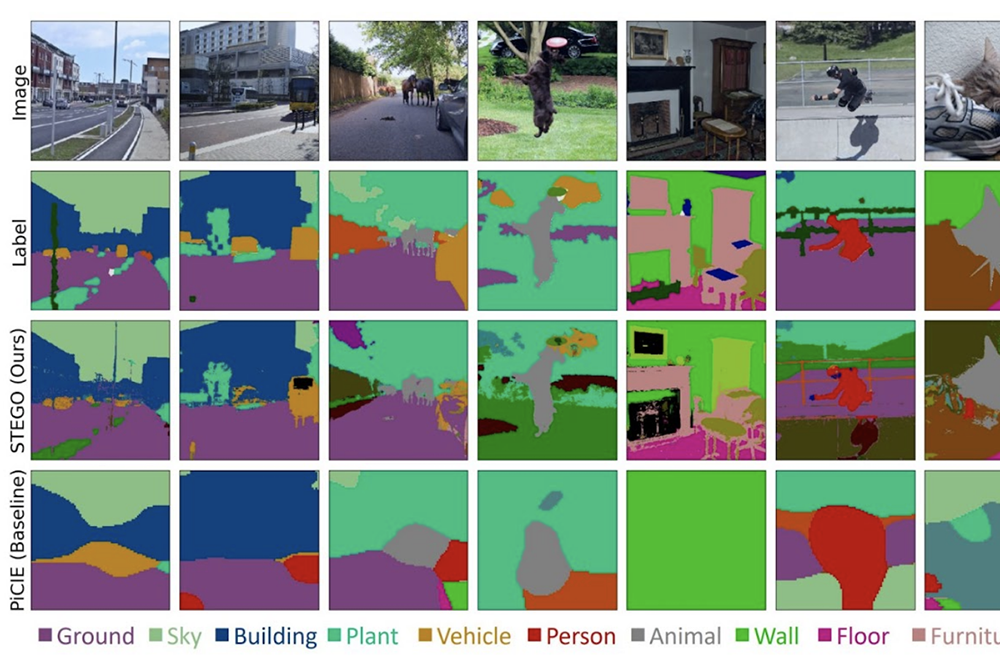
STEGO learns one thing known as “semantic segmentation” — fancy communicate for the method of assigning a label to each pixel in a picture. Semantic segmentation is a crucial talent for right now’s computer-vision programs as a result of pictures may be cluttered with objects. Much more difficult is that these objects do not all the time match into literal packing containers; algorithms are likely to work higher for discrete “issues” like folks and vehicles versus “stuff” like vegetation, sky, and mashed potatoes. A earlier system may merely understand a nuanced scene of a canine enjoying within the park as only a canine, however by assigning each pixel of the picture a label, STEGO can break the picture into its most important substances: a canine, sky, grass, and its proprietor.
Assigning each single pixel of the world a label is formidable — particularly with none sort of suggestions from people. Nearly all of algorithms right now get their data from mounds of labeled information, which might take painstaking human-hours to supply. Simply think about the joy of labeling each pixel of 100,000 pictures! To find these objects with no human’s useful steering, STEGO seems for comparable objects that seem all through a dataset. It then associates these comparable objects collectively to assemble a constant view of the world throughout all the pictures it learns from.
Seeing the world
Machines that may “see” are essential for a big selection of recent and rising applied sciences like self-driving vehicles and predictive modeling for medical diagnostics. Since STEGO can be taught with out labels, it may possibly detect objects in many various domains, even people who people don’t but perceive absolutely.
“For those who’re oncological scans, the floor of planets, or high-resolution organic pictures, it’s arduous to know what objects to search for with out skilled data. In rising domains, typically even human consultants do not know what the fitting objects needs to be,” says Mark Hamilton, a PhD pupil in electrical engineering and laptop science at MIT, analysis affiliate of MIT CSAIL, software program engineer at Microsoft, and lead creator on a new paper about STEGO. “In some of these conditions the place you need to design a way to function on the boundaries of science, you may’t depend on people to determine it out earlier than machines do.”
STEGO was examined on a slew of visible domains spanning basic pictures, driving pictures, and high-altitude aerial pictures. In every area, STEGO was in a position to establish and phase related objects that had been carefully aligned with human judgments. STEGO’s most various benchmark was the COCO-Stuff dataset, which is made up of various pictures from all around the world, from indoor scenes to folks enjoying sports activities to timber and cows. Normally, the earlier state-of-the-art system may seize a low-resolution gist of a scene, however struggled on fine-grained particulars: A human was a blob, a bike was captured as an individual, and it couldn’t acknowledge any geese. On the identical scenes, STEGO doubled the efficiency of earlier programs and found ideas like animals, buildings, folks, furnishings, and plenty of others.
STEGO not solely doubled the efficiency of prior programs on the COCO-Stuff benchmark, however made comparable leaps ahead in different visible domains. When utilized to driverless automotive datasets, STEGO efficiently segmented out roads, folks, and avenue indicators with a lot greater decision and granularity than earlier programs. On pictures from house, the system broke down each single sq. foot of the floor of the Earth into roads, vegetation, and buildings.
Connecting the pixels
STEGO — which stands for “Self-supervised Transformer with Vitality-based Graph Optimization” — builds on high of the DINO algorithm, which discovered in regards to the world by 14 million pictures from the ImageNet database. STEGO refines the DINO spine by a studying course of that mimics our personal approach of sewing collectively items of the world to make which means.
For instance, you may contemplate two pictures of canines strolling within the park. Though they’re totally different canines, with totally different homeowners, in several parks, STEGO can inform (with out people) how every scene’s objects relate to one another. The authors even probe STEGO’s thoughts to see how every little, brown, furry factor within the pictures are comparable, and likewise with different shared objects like grass and folks. By connecting objects throughout pictures, STEGO builds a constant view of the phrase.
“The concept is that some of these algorithms can discover constant groupings in a largely automated trend so we do not have to do this ourselves,” says Hamilton. “It may need taken years to grasp complicated visible datasets like organic imagery, but when we are able to keep away from spending 1,000 hours combing by information and labeling it, we are able to discover and uncover new data that we’d have missed. We hope it will assist us perceive the visible phrase in a extra empirically grounded approach.”
Wanting forward
Regardless of its enhancements, STEGO nonetheless faces sure challenges. One is that labels may be arbitrary. For instance, the labels of the COCO-Stuff dataset distinguish between “food-things” like bananas and hen wings, and “food-stuff” like grits and pasta. STEGO would not see a lot of a distinction there. In different circumstances, STEGO was confused by odd pictures — like one among a banana sitting on a telephone receiver — the place the receiver was labeled “foodstuff,” as an alternative of “uncooked materials.”
For upcoming work, they’re planning to discover giving STEGO a bit extra flexibility than simply labeling pixels into a set variety of courses as issues in the true world can typically be a number of issues on the similar time (like “meals”, “plant” and “fruit”). The authors hope it will give the algorithm room for uncertainty, trade-offs, and extra summary considering.
“In making a basic device for understanding doubtlessly sophisticated datasets, we hope that such a an algorithm can automate the scientific strategy of object discovery from pictures. There’s loads of totally different domains the place human labeling could be prohibitively costly, or people merely don’t even know the precise construction, like in sure organic and astrophysical domains. We hope that future work allows utility to a really broad scope of datasets. Since you do not want any human labels, we are able to now begin to apply ML instruments extra broadly,” says Hamilton.
“STEGO is straightforward, elegant, and really efficient. I contemplate unsupervised segmentation to be a benchmark for progress in picture understanding, and a really troublesome downside. The analysis neighborhood has made terrific progress in unsupervised picture understanding with the adoption of transformer architectures,” says Andrea Vedaldi, professor of laptop imaginative and prescient and machine studying and a co-lead of the Visible Geometry Group on the engineering science division of the College of Oxford. “This analysis offers maybe probably the most direct and efficient demonstration of this progress on unsupervised segmentation.”
Hamilton wrote the paper alongside MIT CSAIL PhD pupil Zhoutong Zhang, Assistant Professor Bharath Hariharan of Cornell College, Affiliate Professor Noah Snavely of Cornell Tech, and MIT professor William T. Freeman. They are going to current the paper on the 2022 Worldwide Convention on Studying Representations (ICLR).
[ad_2]

