

[ad_1]
Google Search Console helps you to have a look at your web site by Google’s eyes.
You get details about the efficiency of your web site and particulars about web page expertise, safety points, crawling, or indexation.
The Excluded a part of the Google Search Console Index Protection report supplies details about the indexing standing of your web site’s pages.
Study why among the pages of your web site land within the Excluded report in Google Search Console – and the right way to repair it.
What Is The Index Protection Report?
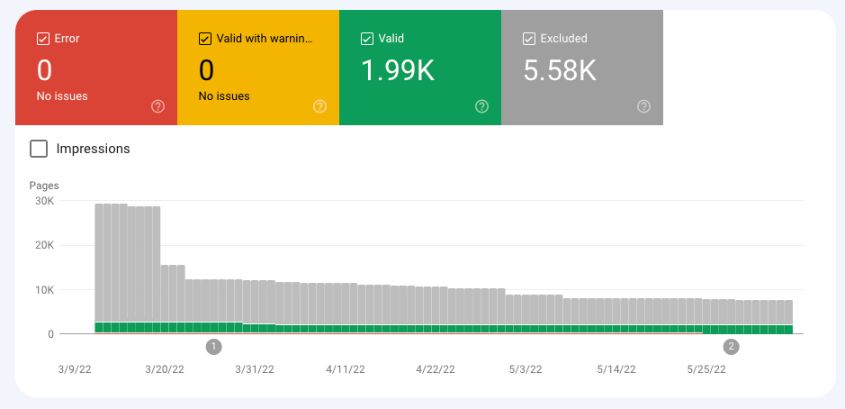
The Google Search Console Protection report reveals detailed details about the index standing of the online pages of your web site.
Your net pages can go into one of many following 4 buckets:
- Error: The pages that Google can not index. You need to overview this report as a result of Google thinks you might have considered trying these pages listed.
- Legitimate with warnings: The pages that Google indexes, however there are some points you must resolve.
- Legitimate: The pages that Google indexes.
- Excluded: The pages which can be excluded from the index.
What Are Excluded Pages?
Google doesn’t index pages within the Error and Excluded buckets.
The primary distinction between the 2 is:
- Google thinks pages in Error must be listed however can not due to an error you must overview. For instance, non-indexable pages submitted by an XML sitemap fall below Error.
- Google thinks pages within the Excluded bucket ought to certainly be excluded, and that is your intention. For instance, non-indexable pages not submitted to Google will seem within the Excluded report.
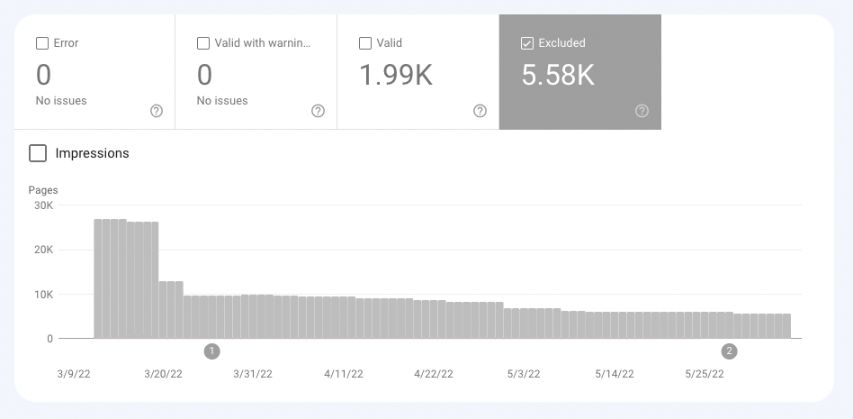 Screenshot from Google Search Console, Might 2022
Nonetheless, Google doesn’t all the time get it proper and pages that must be listed typically go to Excluded.
Happily, Google Search Console supplies the explanation for putting pages in a selected bucket.
For this reason it’s a great apply to rigorously overview the pages in all 4 buckets.
Let’s now dive into the Excluded bucket.
Potential Causes For Excluded Pages
There are 15 attainable causes your net pages are within the Excluded group. Let’s take a more in-depth have a look at each.
Excluded by “noindex” tag
These are the URLs which have a “noindex” tag.
Google thinks you truly need to exclude these pages from indexation since you don’t listing them within the XML sitemap.
These could also be, for instance, login pages, person pages, or search end result pages.
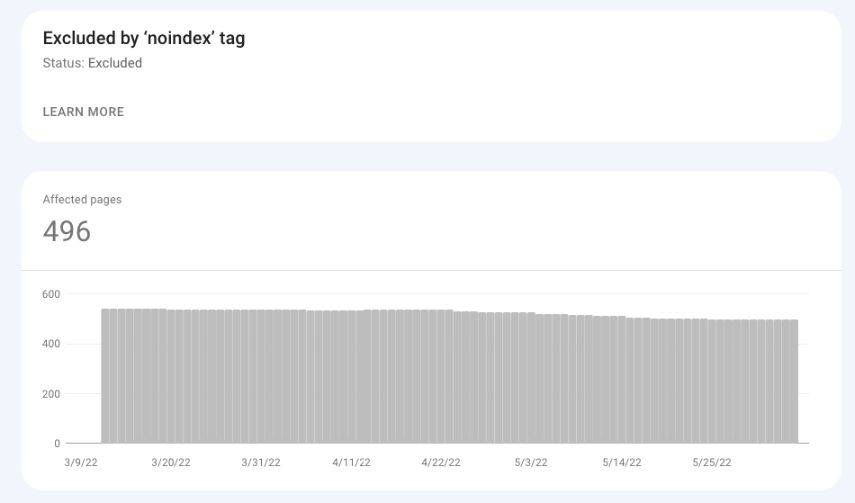
Advised actions:
- Assessment these URLs to make sure you need to exclude them from Google’s index.
- Verify if a “noindex” tag remains to be/truly current on these URLs.
Crawled – At the moment Not Listed
Google has crawled these pages and nonetheless has not listed them.
As Google says in its documentation, the URL on this bucket “could or might not be listed sooner or later; no must resubmit this URL for crawling.”
Many website positioning professionals observed {that a} website may need some severe high quality points if many regular and indexable pages go below Crawled – presently not listed.
This might imply Google has crawled these pages and doesn’t assume they supply sufficient worth to index.
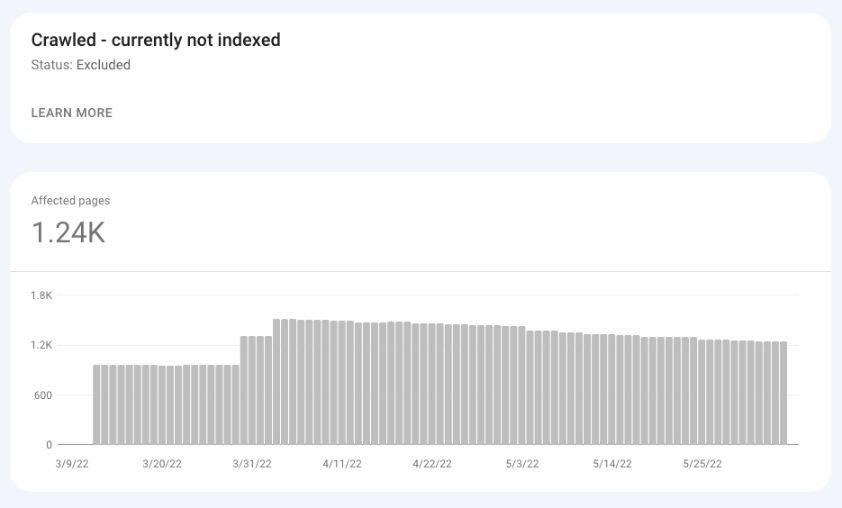 Screenshot from Google Search Console, Might 2022
Advised actions:
- Assessment your web site by way of high quality and E-A-T.
Found – At the moment Not Listed
As Google documentation says, the web page below Found – presently not listed “was discovered by Google, however not crawled but.”
Google didn’t crawl the web page to not overload the server. An enormous variety of pages below this bucket could imply your website has crawl finances points.
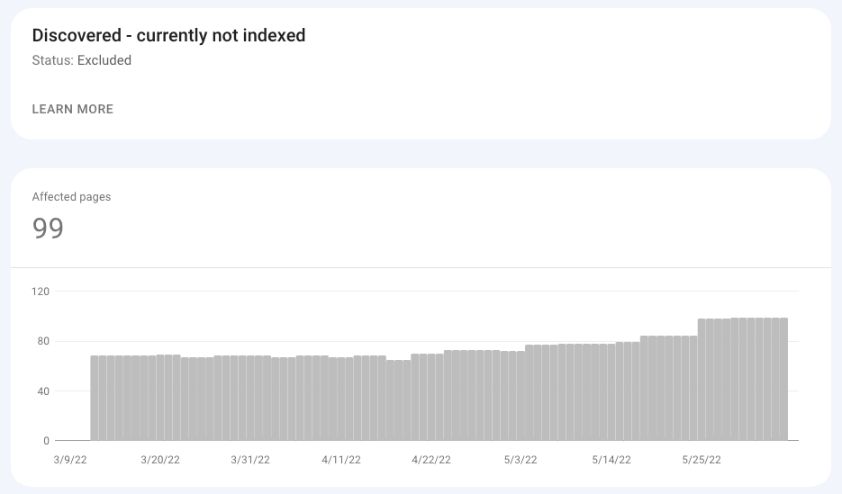 Screenshot from Google Search Console, Might 2022
Advised actions:
- Verify the well being of your server.
Not Discovered (404)
These are the pages that returned standing code 404 (Not Discovered) when requested by Google.
These will not be URLs submitted to Google (i.e., in an XML sitemap), however as a substitute, Google found these pages (i.e., by one other web site that linked to an previous web page deleted a very long time in the past.
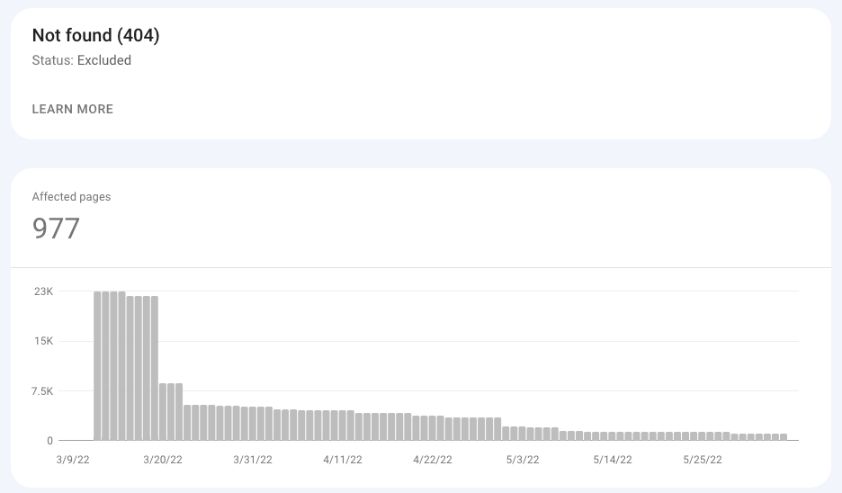 Screenshot from Google Search Console, Might 2022
Advised actions:
- Assessment these pages and resolve whether or not to implement a 301 redirect to a working web page.
Delicate 404
Delicate 404, most often, is an error web page that returns standing code OK (200).
Alternatively, it can be a skinny web page that accommodates little to no content material and makes use of phrases like “sorry,” “error,” “not discovered,” and so on.
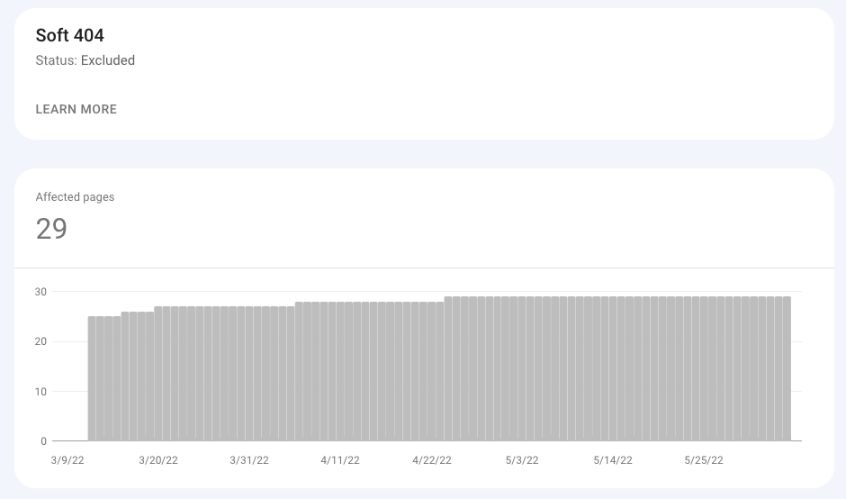 Screenshot from Google Search Console, Might 2022
Advised actions:
- Within the case of an error web page, ensure that to return standing code 404.
- For skinny content material pages, add distinctive content material to assist Google acknowledge this URL as a standalone web page.
Web page With Redirect
All redirected pages in your web site will go to the Excluded bucket, the place you may see all redirected pages that Google detected in your web site.
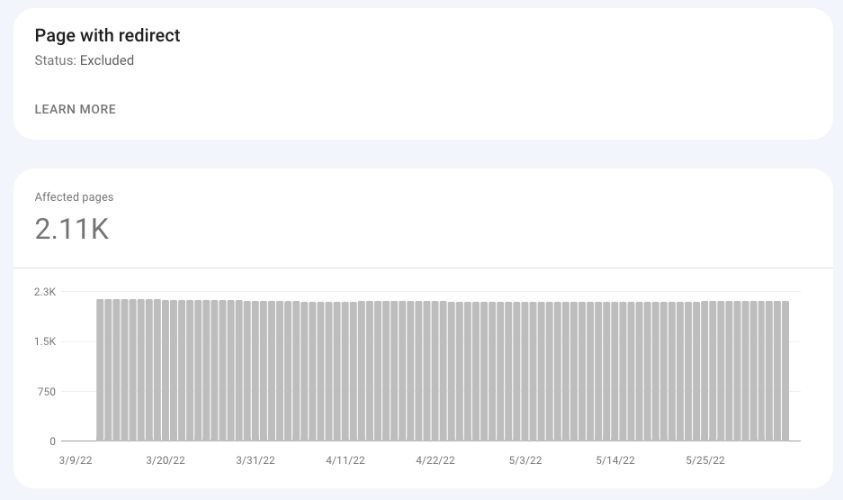 Screenshot from Google Search Console, Might 2022
Advised actions:
- Assessment the redirected pages to verify the redirects had been applied deliberately.
- Some WordPress plugins routinely create redirects once you change the URL, so you might need to overview these sometimes.
Duplicate With out Person-Chosen Canonical
Google thinks these URLs are duplicates of different URLs in your web site and, due to this fact, shouldn’t be listed.
You didn’t set a canonical tag for these URLs, and Google chosen the canonical based mostly on different indicators.
Advised actions:
- Examine these URLs to examine what canonical URLs Google has chosen for these pages.
Duplicate, Google Selected Completely different Canonical Than Person
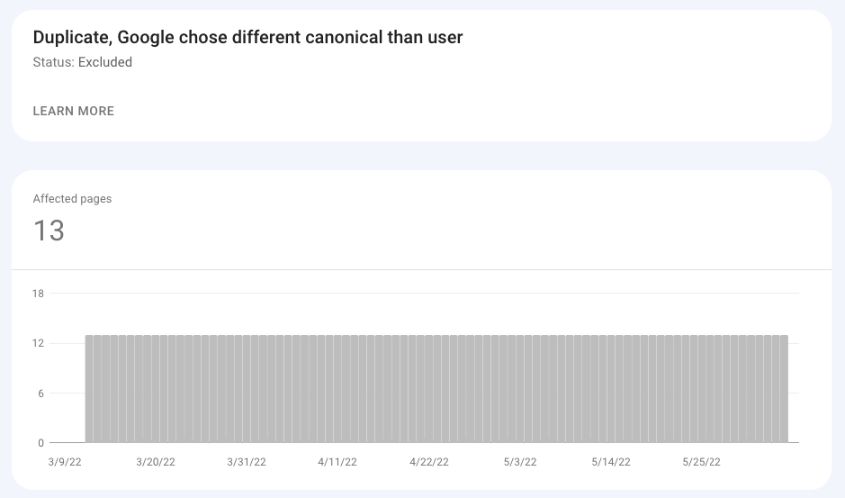 Screenshot from Google Search Console, Might 2022
On this case, you declared a canonical URL for the web page, besides, Google chosen a unique URL because the canonical. In consequence, the Google-selected canonical is listed, and the user-selected one will not be.
Potential actions:
- Examine the URL to examine what canonical Google chosen.
- Analyze attainable indicators that made Google select a unique canonical (i.e., exterior hyperlinks).
Duplicate, Submitted URL Not Chosen As Canonical
The distinction between the above standing and this standing is that within the case of the latter, you submitted a URL to Google for indexation with out declaring its canonical tackle, and Google thinks a unique URL would make a greater canonical.
In consequence, the Google-selected canonical is listed quite than the submitted URL.
Advised actions:
- Examine the URL to examine what canonical Google has chosen.
Alternate Web page With Correct Canonical Tag
These are merely the duplicates of the pages that Google acknowledges as canonical URLs.
These pages have the canonical addresses that time to the right canonical URL.
Advised actions:
- Generally, no motion is required.
Blocked By Robots.txt
These are the pages that robots.txt have blocked.
When analyzing this bucket, understand that Google can nonetheless index these pages (and show them in an “impaired” manner) if Google finds a reference to them on, for instance, different web sites.
Advised actions:
- Confirm if these pages are blocked utilizing the robots.txt tester.
- Add a “noindex” tag and take away the pages from robots.txt if you wish to take away them from the index.
Blocked By Web page Removing Device
This report lists the pages whose removing has been requested by the Removals software.
Understand that this software removes the pages from search outcomes solely briefly (90 days) and doesn’t take away them from the index.
Advised actions:
- Confirm if the pages submitted through the Removals software must be briefly eliminated or have a ‘noindex’ tag.
Blocked Due To Unauthorized Request (401)
Within the case of those URLs, Googlebot was not capable of entry the pages due to an authorization request (401 standing code).
Until these pages must be out there with out authorization, you don’t must do something.
Google is solely informing you about what it encountered.
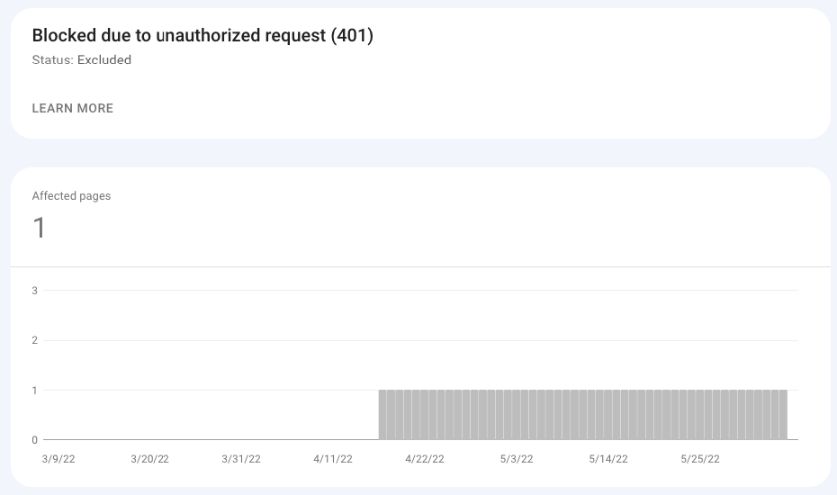 Screenshot from Google Search Console, Might 2022
Advised actions:
- Confirm if these pages ought to truly require authorization.
Blocked Due To Entry Forbidden (403)
This standing code is normally the results of some server error.
403 is returned when credentials offered will not be appropriate, and entry to the web page couldn’t be granted.
As Google documentation states:
“Googlebot by no means supplies credentials, so your server is returning this error incorrectly. This error ought to both be mounted, or the web page must be blocked by robots.txt or noindex.”
What Can You Study From Excluded pages?
Sudden and large spikes in a selected bucket of Excluded pages could point out severe website points.
Listed here are three examples of spikes which will point out extreme issues along with your web site:
- An enormous spike in Not Discovered (404) pages could point out unsuccessful migration the place URLs have been modified, however redirects to new addresses haven’t been applied. This will additionally occur after, for instance, an inexperienced individual modified the slug of weblog posts and because of this, modified the URLs of all blogs.
- An enormous spike within the Found – presently not listed or Crawled – presently not listed could point out that your website has been hacked. Be certain that to overview the instance pages to examine if these are literally your pages or had been created on account of a hack (i.e., pages with Chinese language characters).
- An enormous spike in Excluded by ‘noindex’ tag may additionally point out unsuccessful launch and migration. This typically occurs when a brand new website goes to manufacturing along with “noindex” tags from the staging website.
The Recap
You possibly can study rather a lot about your web site and the way Googlebot interacts with it, due to the Excluded part of the GSC Protection report.
Whether or not you’re a new website positioning or have already got a number of years of expertise, make it your each day behavior to examine Google Search Console.
This may also help you detect numerous technical website positioning points earlier than they flip into actual disasters.
Extra assets:
Featured Picture: Milan1983/Shutterstock
[ad_2]

