



[ad_1]
Amazon OpenSearch Service is a managed service that makes it straightforward to safe, deploy, and function OpenSearch and legacy Elasticsearch clusters at scale.
Within the newest service software program launch of Amazon OpenSearch Service, we’ve modified the conduct of the JVMMemoryPressure metric. This metric now reviews the general heap utilization, together with younger and previous swimming pools, for all domains that use the G1GC rubbish collector. For those who’re utilizing Graviton-based information nodes (C6, R6, and M6 cases), or in case you enabled Auto-Tune and it has switched your rubbish assortment algorithm to G1GC, this alteration will enhance your capability to detect and reply to issues with OpenSearch’s Java heap.
Fundamentals of Java rubbish assortment
Objects in Java are allotted in a heap reminiscence, occupying half of the occasion’s RAM as much as roughly 32 GB. As your utility runs, it creates and destroys objects within the heap, leaving the heap fragmented and making it more durable to allocate new objects. Java’s rubbish assortment algorithm periodically goes by the heap and reclaims the reminiscence of any unused objects. It additionally compacts the heap when needed to offer extra contiguous free house.
The heap is allotted into smaller reminiscence swimming pools:
Younger era – The younger era reminiscence pool is the place new objects are allotted. The younger era is additional divided into an Eden house, the place all new objects begin, and two survivor areas (S0 and S1), the place objects are moved from Eden after surviving one rubbish assortment cycle. When the younger era fills up, Java performs a minor rubbish assortment to scrub up unmarked objects. Objects that stay within the younger era age till they finally transfer to the previous era.
Previous era – The previous era reminiscence pool shops long-lived objects. When objects attain a sure age after a number of rubbish assortment iterations within the younger era, they’re then moved to the previous era.
Everlasting era – The everlasting era incorporates metadata required by the JVM to explain the lessons and strategies used within the utility at runtime. It isn’t populated when the previous era’s objects attain a sure age.

Java processes can make use of completely different rubbish assortment algorithms, chosen by command-line choice.
- Concurrent Mark Sweep (CMS) – The completely different swimming pools are segregated in reminiscence. Cease-the-world pauses, and heap compaction are common occurrences. The younger era pool is small. All non-Graviton information nodes use CMS.
- G1 Rubbish Assortment (G1GC) – All heap reminiscence is a single block, with completely different areas of reminiscence (areas) allotted to the completely different swimming pools. The swimming pools are interleaved in bodily reminiscence. Cease-the-world pauses and heap compaction are rare. The younger era pool is bigger. All Graviton information nodes use G1GC. Amazon OpenSearch Service’s Auto-Tune function can select G1GC for non-Graviton information nodes.
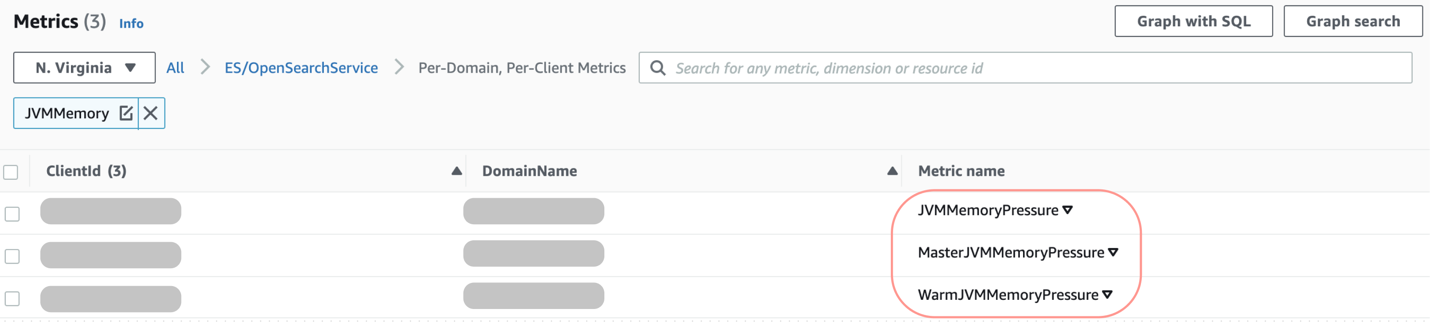
You need to use the CloudWatch console to retrieve statistics about these information factors as an ordered set of time-series information, referred to as metrics. Amazon OpenSearch Service at the moment publishes three metrics associated to JVM reminiscence stress to CloudWatch:
- JVMMemoryPressure – The utmost proportion of the Java heap used for all information nodes within the cluster.
- MasterJVMMemoryPressure – The utmost proportion of the Java heap used for all devoted grasp nodes within the cluster.
- WarmJVMMemoryPressure – The utmost proportion of the Java heap used for UltraWarm nodes within the cluster.
Within the newest service software program replace, Amazon OpenSearch Service improved the logic that it makes use of to compute these metrics to be able to extra precisely replicate precise reminiscence utilization.
The issue
Beforehand, all information nodes used CMS, the place the younger pool was a small portion of reminiscence. The JVM reminiscence stress metrics that Amazon OpenSearch Service revealed to CloudWatch solely thought-about the previous pool of the Java heap. You may detect issues within the heap utilization by wanting solely at previous era utilization.
When the area makes use of G1GC, the younger pool is bigger, representing a bigger proportion of the whole heap. Since objects are created first within the younger pool, after which moved to the previous pool, a good portion of the utilization may very well be within the younger pool. Nevertheless, the prior metric reported solely on the previous pool. This leaves domains weak to invisibly operating out of reminiscence within the younger pool.
What’s altering?
Within the newest service software program replace, Amazon OpenSearch Service modified the logic for the three JVM reminiscence stress metrics that it sends to CloudWatch to account for the whole Java heap in use (previous era and younger era). The aim of this replace is to offer a extra correct illustration of whole reminiscence utilization throughout your Amazon Opensearch Service domains, particularly for Graviton occasion sorts, whose rubbish assortment logic makes it necessary to contemplate all reminiscence swimming pools to calculate precise utilization.
What you may anticipate
After you replace your Amazon OpenSearch Service domains to the newest service software program launch, the next metrics that Amazon OpenSearch Service sends to CloudWatch will start to report JVM reminiscence utilization for the young and old era reminiscence swimming pools, fairly than simply previous: JVMemoryPressure, MasterJVMMemoryPressure, and WarmJVMMemoryPressure.
You may see a rise within the values of those metrics, predominantly in G1GC configured domains. In some instances, you may discover a special reminiscence utilization sample altogether, as a result of the younger era reminiscence pool has extra frequent rubbish assortment. Any CloudWatch alarms that you’ve got created round these metrics could be triggered. If this retains taking place, take into account scaling your cases vertically as much as 64 GiB of RAM, at which level you may scale horizontally by including cases.
As an ordinary apply, for domains which have low obtainable reminiscence, Amazon OpenSearch Service blocks additional write operations to forestall the area from reaching pink standing. It is best to monitor your reminiscence utilization after the replace to get a way of the particular utilization in your area. The _nodes/stats/jvm API provides a helpful abstract of JVM statistics, reminiscence pool utilization, and rubbish assortment info.
Conclusion
Amazon OpenSearch Service lately improved the logic that it makes use of to calculate JVM reminiscence utilization to extra precisely replicate precise utilization. The JVMMemoryPressure, MasterJVMMemoryPressure, and WarmJVMMemoryPressure CloudWatch metrics now account for each young and old era reminiscence swimming pools when calculating reminiscence utilization, fairly than simply previous era. For extra details about these metrics, see Monitoring OpenSearch cluster metrics with Amazon CloudWatch.
With the up to date metrics, your domains will begin to extra precisely replicate reminiscence utilization numbers, and may breach CloudWatch alarms that you just beforehand configured. Ensure that to observe your alarms for these metrics and scale your clusters accordingly to keep up optimum reminiscence utilization.
Keep tuned for extra thrilling updates and new options in Amazon OpenSearch Service.
Concerning the Authors
 Liz Snyder is a San Francisco-based technical author for Amazon OpenSearch Service, OpenSearch OSS, and Amazon CloudSearch.
 Jon Handler is a Senior Principal Options Architect, specializing in AWS search applied sciences – Amazon CloudSearch, and Amazon OpenSearch Service. Primarily based in Palo Alto, he helps a broad vary of shoppers get their search and log analytics workloads deployed proper and functioning effectively.
[ad_2]

