


[ad_1]
Prospects can harness subtle orchestration capabilities via the open-source software Apache Airflow. Airflow could be put in on Amazon EC2 cases or could be dockerized and deployed as a container on AWS container companies. Alternatively, clients may also choose to leverage Amazon Managed Workflows for Apache Airflow (MWAA).
Amazon MWAA is a totally managed service that permits clients to focus extra of their efforts on high-impact actions similar to programmatically authoring knowledge pipelines and workflows, versus sustaining or scaling the underlying infrastructure. Amazon MWAA gives auto-scaling capabilities the place it could actually reply to surges in demand by scaling the variety of Airflow staff out and again in.
With Amazon MWAA, there aren’t any upfront commitments and also you solely pay for what you utilize based mostly on occasion uptime, further auto-scaling capability, and storage of the Airflow back-end metadata database. This database is provisioned and managed by Amazon MWAA and comprises the mandatory metadata to assist the Airflow software. It hosts key knowledge factors similar to historic execution instances for duties and workflows and is efficacious in understanding tendencies and behavior of your knowledge pipelines over time. Though the Airflow console does present a sequence of visualisations that show you how to analyse these datasets, these are siloed from different Amazon MWAA environments you may need working, in addition to the remainder of your online business knowledge.
Information platforms embody a number of environments. Sometimes, non-production environments usually are not topic to the identical orchestration calls for and schedule as these of manufacturing environments. In most cases, these non-production environments are idle outdoors of enterprise hours and could be spun down to understand additional cost-efficiencies. Sadly, terminating Amazon MWAA cases ends in the purging of that essential metadata.
On this submit, we talk about the right way to export, persist and analyse Airflow metadata in Amazon S3 enabling you to run and carry out pipeline monitoring and evaluation. In doing so, you’ll be able to spin down Airflow cases with out dropping operational metadata.
Advantages of Airflow metadata
Persisting the metadata within the knowledge lake allows clients to carry out pipeline monitoring and evaluation in a extra significant method:
- Airflow operational logs could be joined and analysed throughout environments
- Pattern evaluation could be performed to discover how knowledge pipelines are performing over time, what particular levels are taking probably the most time, and the way is efficiency effected as knowledge scales
- Airflow operational knowledge could be joined with enterprise knowledge for improved report stage lineage and audit capabilities
These insights may help clients perceive the efficiency of their pipelines over time and information focus in the direction of which processes must be optimised.
The method described beneath to extract metadata is relevant to any Airflow deployment sort, however we are going to concentrate on Amazon MWAA on this weblog.
Answer Overview
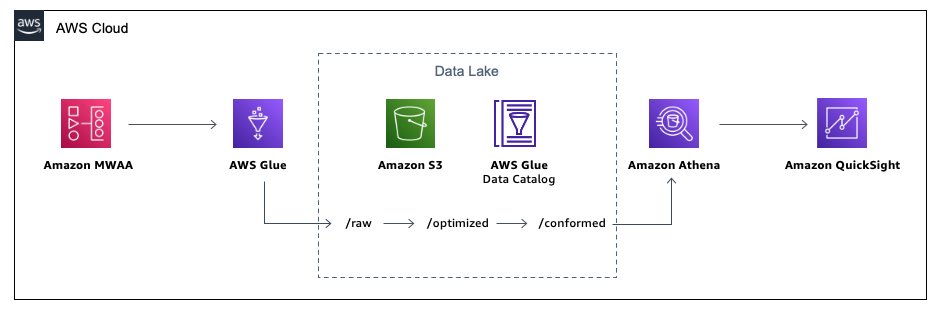
The beneath diagram illustrates the answer structure. Please be aware, Amazon QuickSight is NOT included as a part of the CloudFormation stack and isn’t coated on this tutorial. It has been positioned within the diagram for example that metadata could be visualised utilizing a enterprise intelligence software.
As a part of this tutorial, you may be performing the beneath high-level duties:
- Run CloudFormation stack to create all essential sources
- Set off Airflow DAGs to carry out pattern ETL workload and generate operational metadata in back-end database
- Set off Airflow DAG to export operational metadata into Amazon S3
- Carry out evaluation with Amazon Athena
This submit comes with an AWS CloudFormation stack that robotically provisions the mandatory AWS sources and infrastructure, together with an energetic Amazon MWAA occasion, for this resolution. All the code is out there within the GitHub repository.
The Amazon MWAA occasion will have already got three directed-acyclic graphs (DAGs) imported:
- glue-etl – This ETL workflow leverages AWS Glue to carry out transformation logic on a CSV file (customer_activity.csv). This file shall be loaded as a part of the CloudFormation template into the
s3://<DataBucket>/uncooked/prefix.
The primary activity glue_csv_to_parquet converts the ‘uncooked’ knowledge to parquet format and shops the information in location s3://<DataBucket>/optimised/. By changing the information in parquet format, you’ll be able to obtain sooner question efficiency and decrease question prices.
The second activity glue_transform runs an aggregation over the newly created parquet format and shops the aggregated knowledge in location s3://<DataBucket>/conformed/.
- db_export_dag – This DAG consists of 1 activity, export_db, which exports the information from the back-end Airflow database into Amazon S3 within the location
s3://<DataBucket>/export/.
Please be aware that you could be expertise time-out points when extracting massive quantities of information. On busy Airflow cases, our suggestion shall be to arrange frequent extracts in small chunks.
- run-simple-dag – This DAG doesn’t carry out any knowledge transformation or manipulation. It’s used on this weblog for the needs of populating the back-end Airflow database with adequate operational knowledge.
Conditions
To implement the answer outlined on this weblog, you’ll need following :
Steps to run an information pipeline utilizing Amazon MWAA and saving metadata to s3:
- Select Launch Stack:
- Select Subsequent.

- For Stack identify, enter a reputation to your stack.

- Select Subsequent.
- Preserve the default settings on the ‘Configure stack choices’ web page, and select Subsequent.
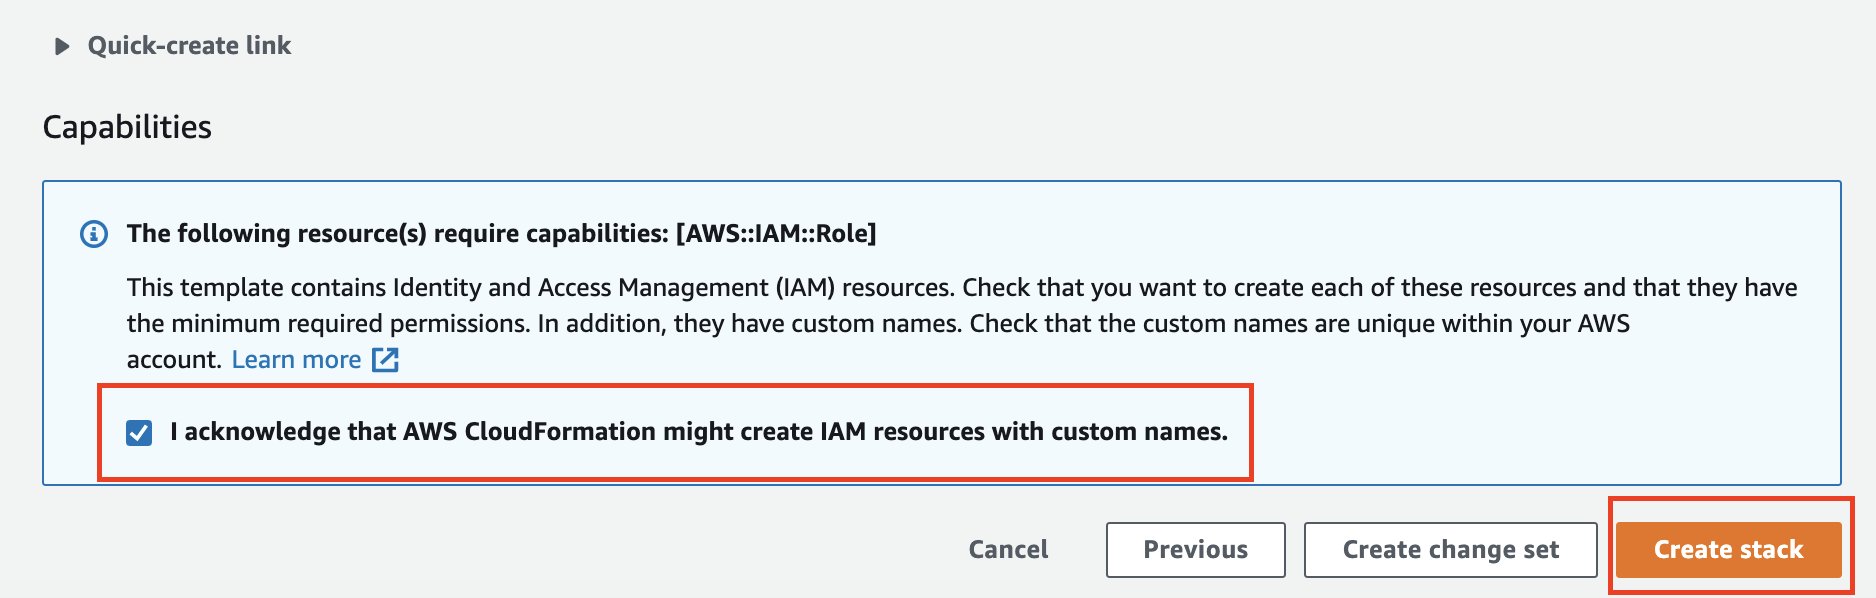
- Acknowledge that the template could create AWS Id and Entry Administration (IAM) sources.
- Select Create stack. The stack can take as much as 30 minutes to finish.
The CloudFormation template generates the next sources:
-
- VPC infrastructure that makes use of Public routing over the Web.
- Amazon S3 buckets required to assist Amazon MWAA, detailed beneath:
- The Information Bucket, refered on this weblog as
s3://<DataBucket>, holds the information which shall be optimised and reworked for additional analytical consumption. This bucket will even maintain the information from the Airflow back-end metadata database as soon as extracted. - The Setting Bucket, refered on this weblog as
s3://<EnvironmentBucket>, shops your DAGs, in addition to any customized plugins, and Python dependencies you could have.
- The Information Bucket, refered on this weblog as
- Amazon MWAA setting that’s related to the
s3://<EnvironmentBucket>/dagslocation. - AWS Glue jobs for knowledge processing and assist generate airflow metadata.
- AWS Lambda-backed customized sources to add to Amazon S3 the pattern knowledge, AWS Glue scripts and DAG configuration information,
- AWS Id and Entry Administration (IAM) customers, roles, and insurance policies.
- As soon as the stack creation is profitable, navigate to the Outputs tab of the CloudFormation stack and make be aware of
DataBucketandEnvironmentBucketidentify. Retailer your Apache Airflow Directed Acyclic Graphs (DAGs), customized plugins in aplugins.zipfile, and Python dependencies in anecessities.txtfile.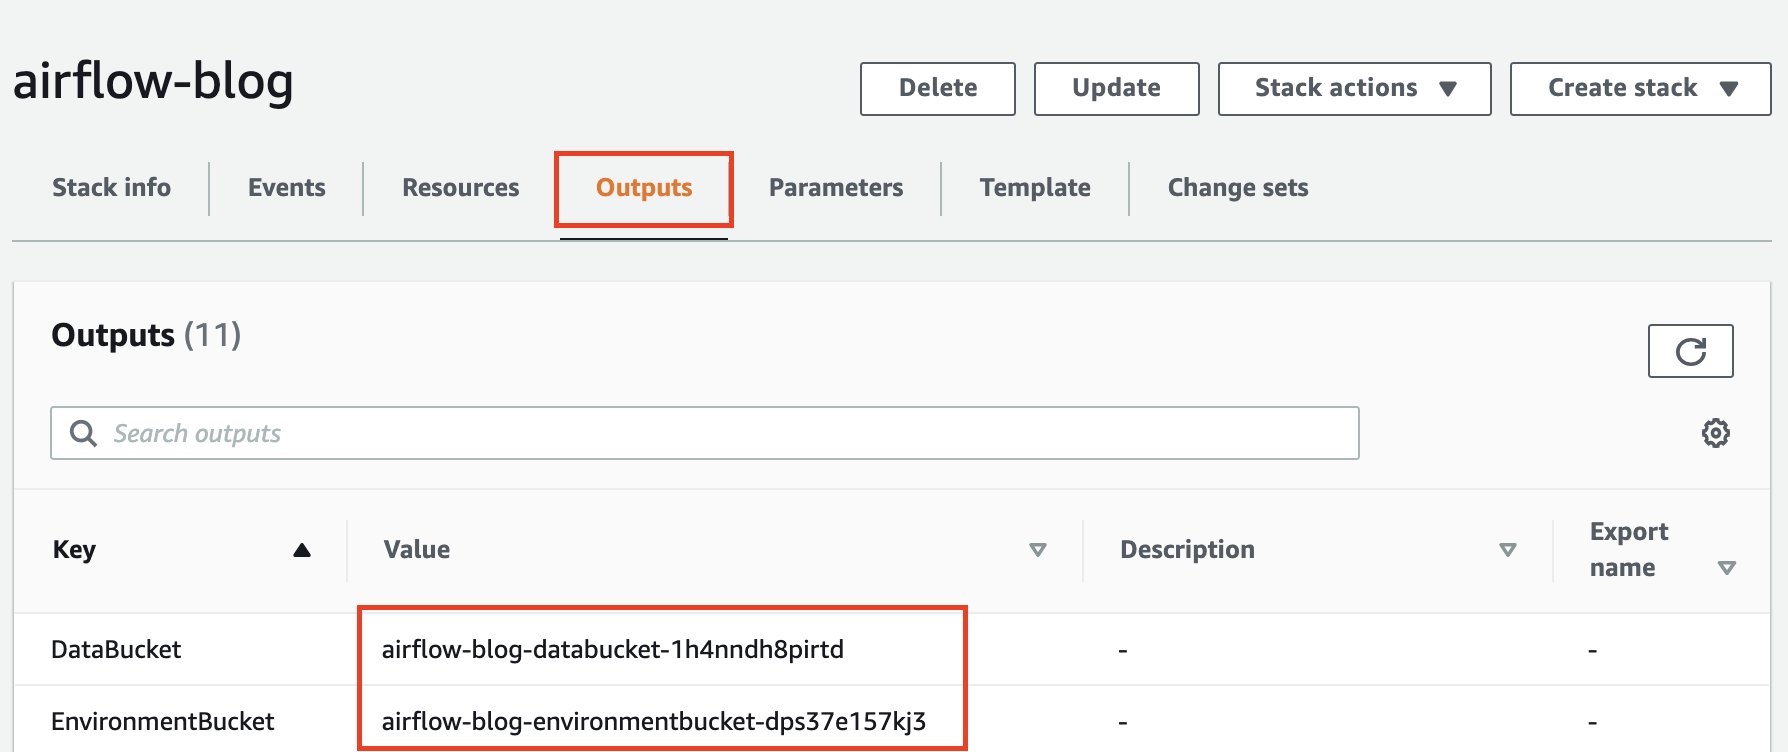
- Open the Environments web page on the Amazon MWAA console.
- Select the setting created above. (The setting identify will embrace the stack identify). Click on on Open Airflow UI.

- Select glue-etl DAG , unpause by clicking the radio button subsequent to the identify of the DAG and click on on the Play Button on Proper hand aspect to Set off DAG. It might take as much as a minute for DAG to look.

- Depart Configuration JSON as empty and hit Set off.

- Select run-simple-dag DAG, unpause and click on on Set off DAG.
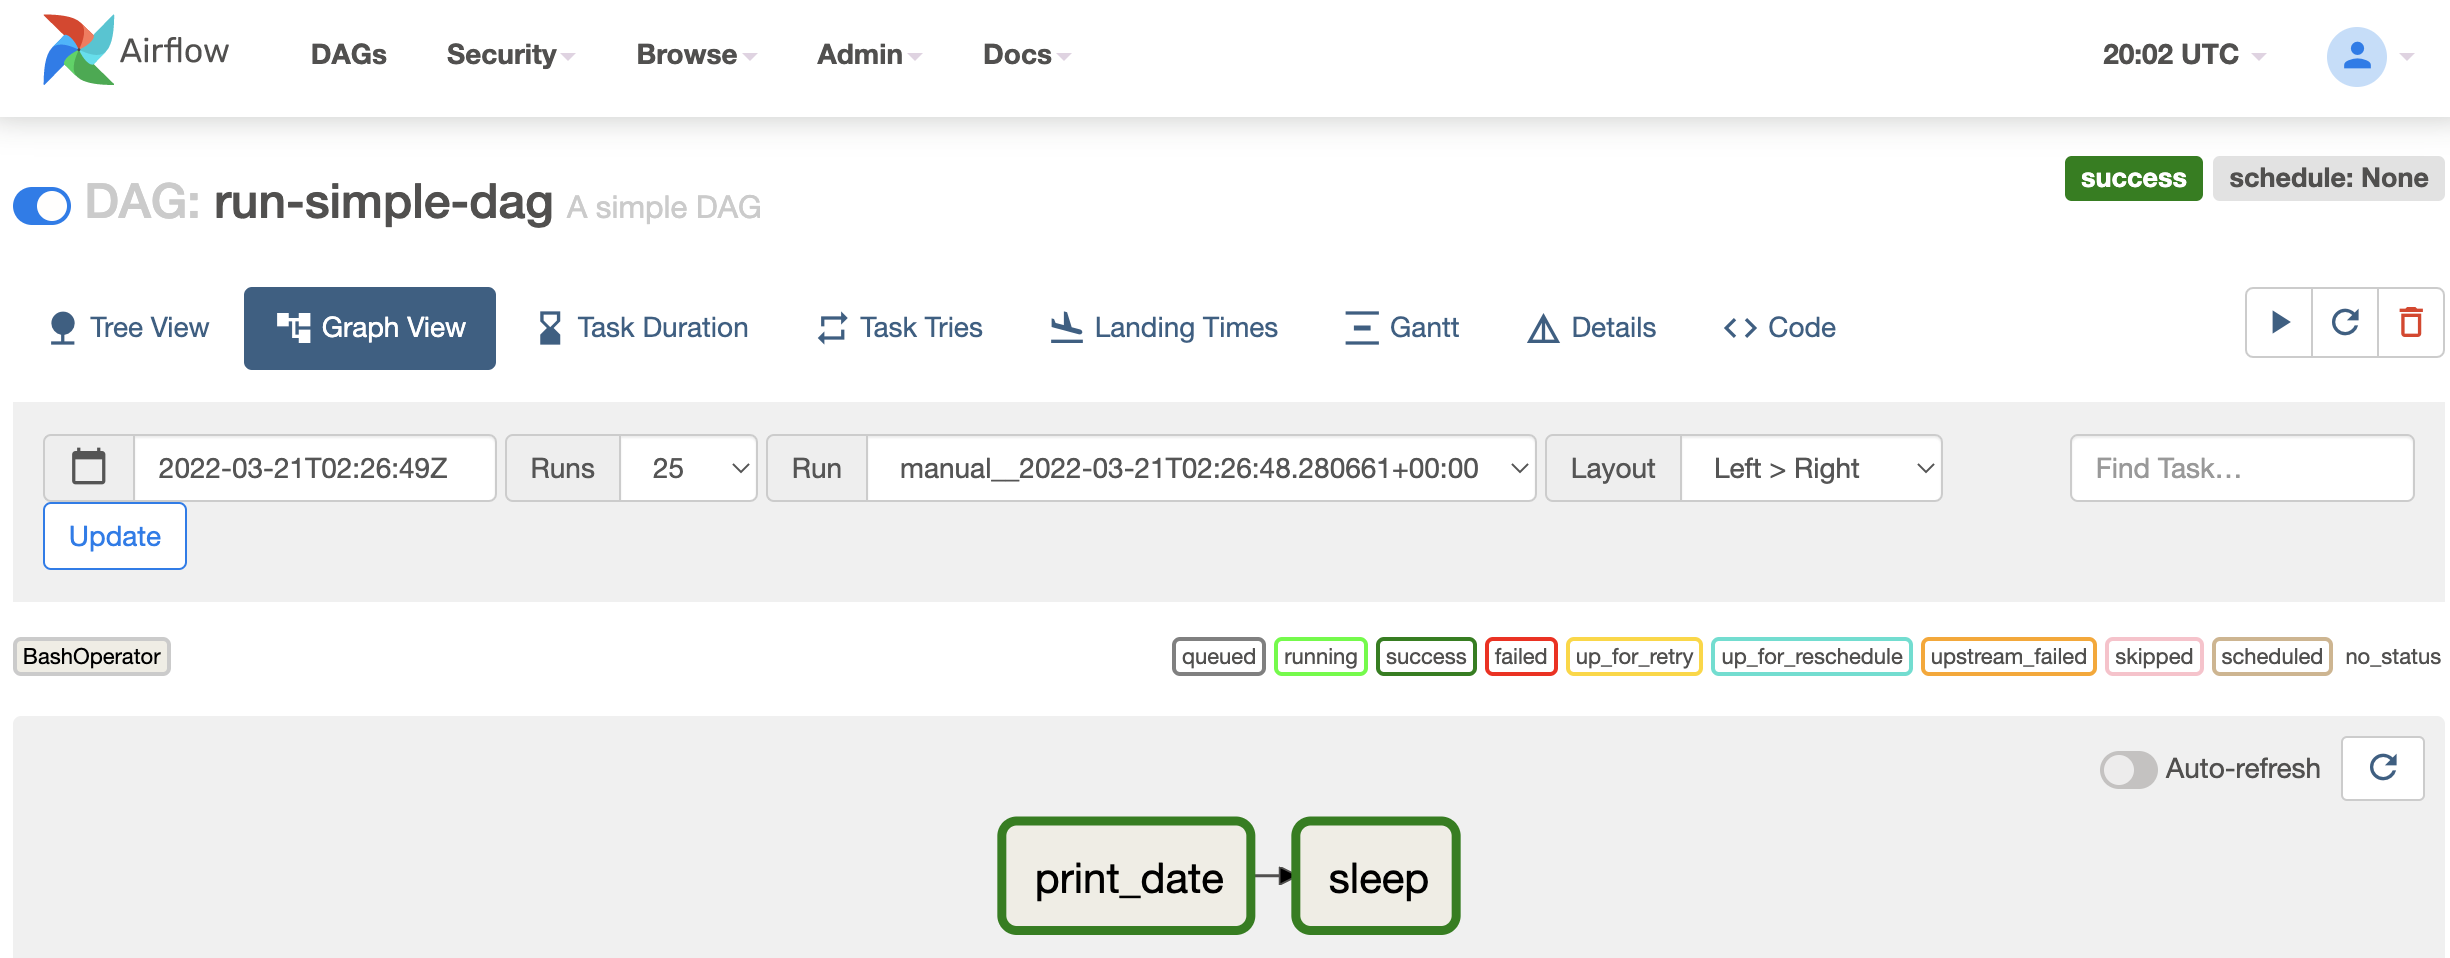
- As soon as each DAG executions have accomplished, choose the db_export_dag DAG, unpause and click on on Set off DAG. Depart Configuration JSON as empty and hit Set off.

This step will extract the dag and activity metadata to a S3 location. This can be a pattern checklist of tables and extra tables could be added as required. The exported metadata shall be situated in s3://<DataBucket>/export/ folder.

Visualise utilizing Amazon QuickSight and Amazon Athena
Amazon Athena is a serverless interactive question service that can be utilized to run exploratory evaluation on knowledge saved in Amazon S3.
In case you are utilizing Amazon Athena for the primary time, please discover the steps right here to setup question location. We are able to use Amazon Athena to discover and analyse the metadata generated from airflow dag runs.
- Navigate to Athena Console and click on discover the question editor.
- Hit View Settings.

- Click on Handle.

- Exchange with
s3://<DataBucket>/logs/athena/. As soon as accomplished, return to the question editor. - Earlier than we are able to carry out our pipeline evaluation, we have to create the beneath DDLs. Exchange the
<DataBucket>as a part of theLOCATIONclause with the parameter worth as outlined within the CloudFormation stack (famous in Step 8 above). - You’ll be able to preview the desk within the question editor of Amazon Athena.

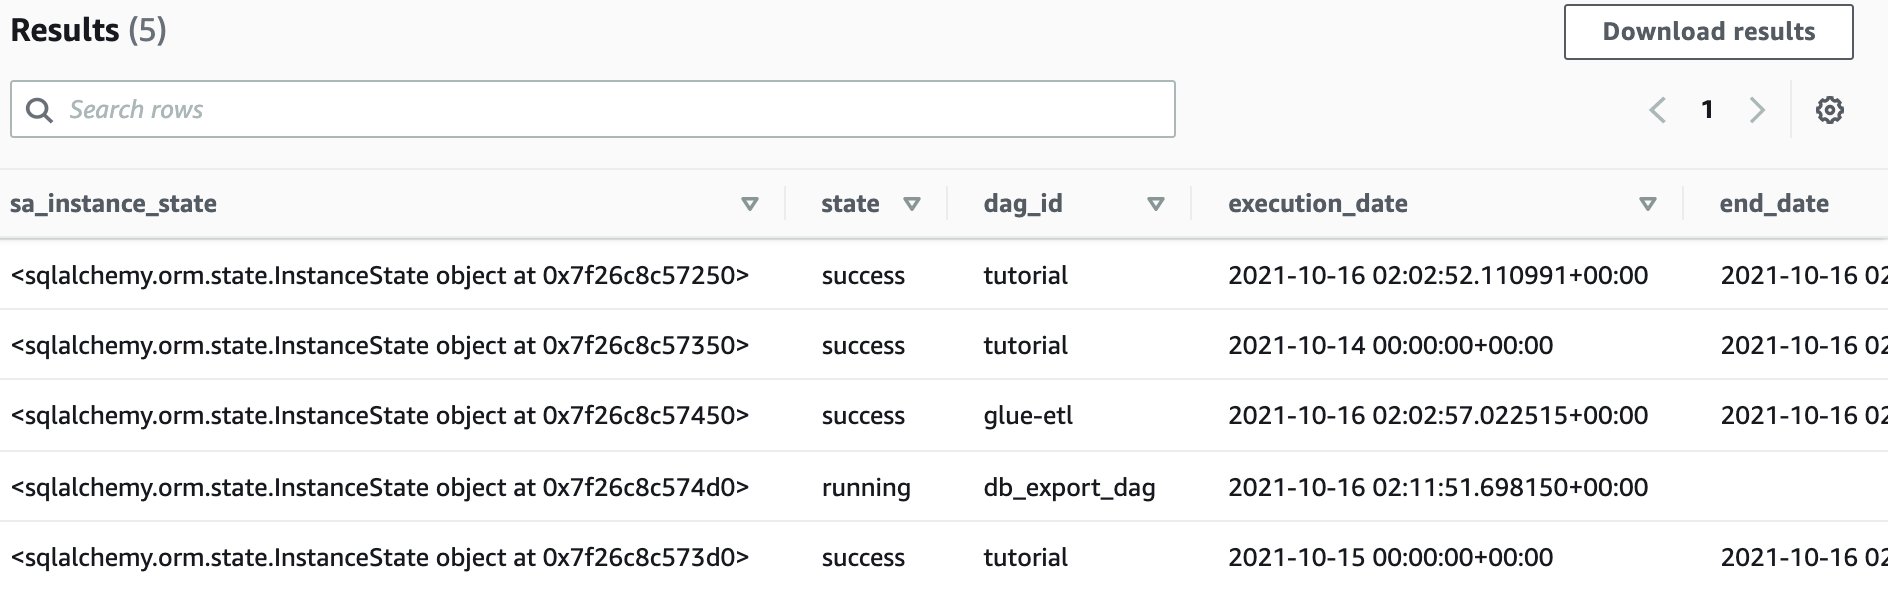
- With the metadata endured, you’ll be able to carry out pipeline monitoring and derive some highly effective insights on the efficiency of your knowledge pipelines time beyond regulation. For example for example this, execute the beneath SQL question in Athena.
This question returns pertinent metrics at a month-to-month grain which embrace variety of executions of the DAG in that month, success fee, minimal/most/common period for the month and a variation in comparison with the earlier months common.
Via the beneath SQL question, it is possible for you to to know how your knowledge pipelines are performing over time.
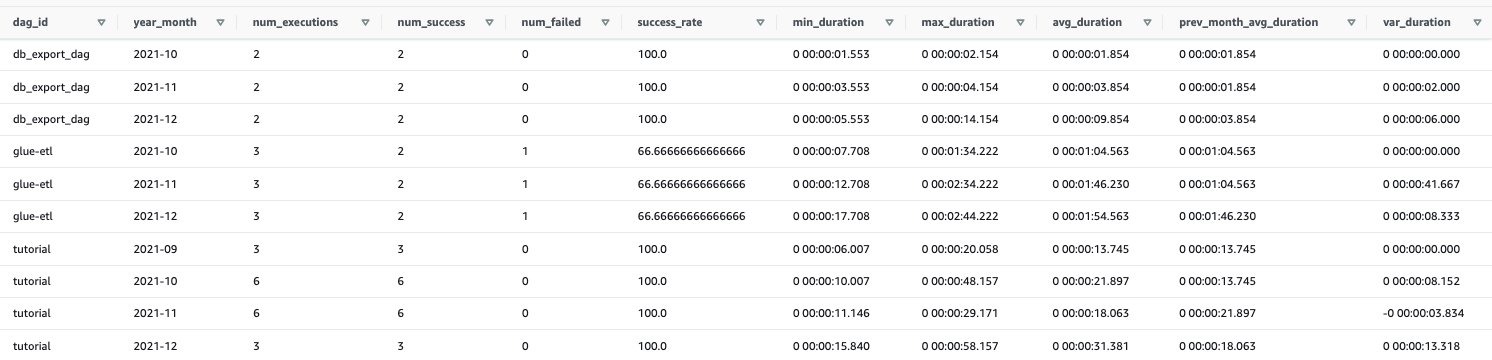
- You too can visualize this knowledge utilizing your BI software of selection. Whereas step-by-step particulars of making a dashboard isn’t coated on this weblog, please refer the beneath dashboard constructed on Amazon QuickSight for instance of what could be constructed based mostly on the metadata extracted above. In case you are utilizing Amazon QuickSight for the primary time, please discover the steps right here on the right way to get began.

Via QuickSight, we are able to rapidly visualise and derive that our knowledge pipelines are finishing efficiently, however on common are taking an extended time to finish over time.
Clear up the setting
- Navigate to the S3 console and click on on the
<DataBucket>famous in step 8 above. - Click on on Empty bucket.

- Verify the choice.
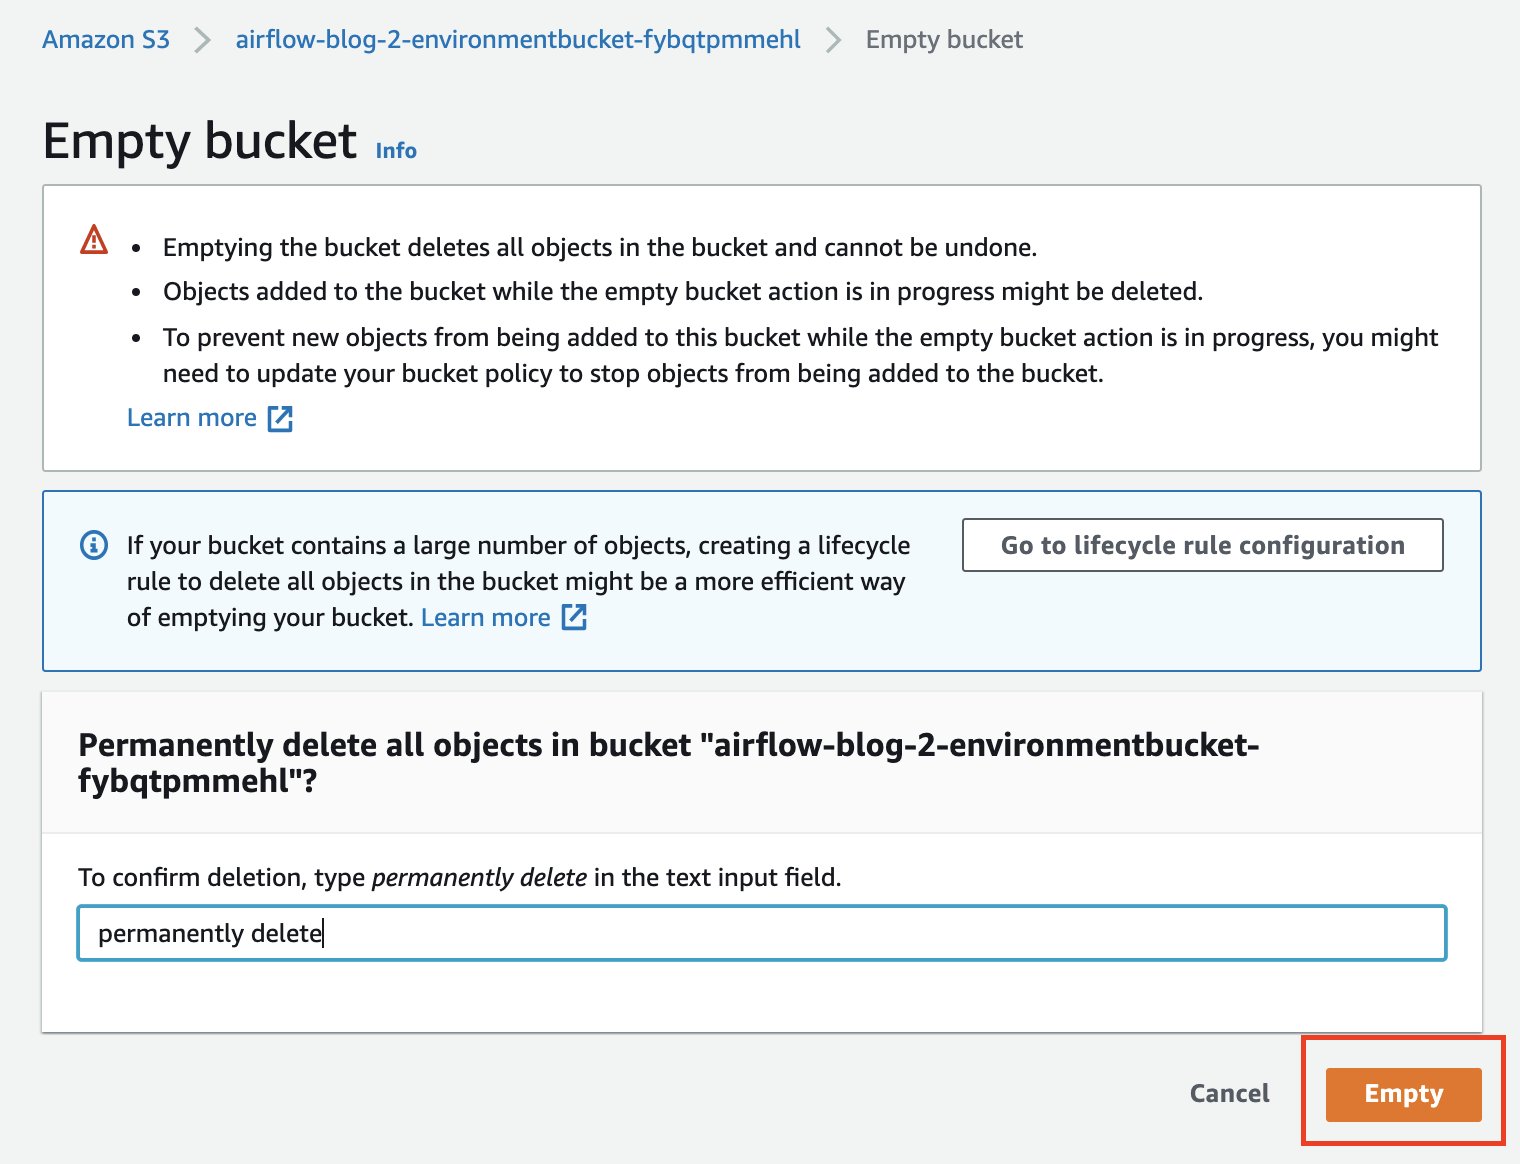
- Repeat this step for bucket
<EnvironmentBucket>(famous in step 8 above) and Empty bucket. - Run the beneath statements within the question editor to drop the 2 Amazon Athena tables. Run statements individually.
- On the AWS CloudFormation console, choose the stack you created and select Delete.
Abstract
On this submit, we offered an answer to additional optimise the prices of Amazon MWAA by tearing down cases while preserving the metadata. Storing this metadata in your knowledge lake allows you to higher carry out pipeline monitoring and evaluation. This course of could be scheduled and orchestrated programatically and is relevant to all Airflow deployments, similar to Amazon MWAA, Apache Airflow put in on Amazon EC2, and even on-premises installations of Apache Airflow.
To study extra, please go to Amazon MWAA and Getting Began with Amazon MWAA.
Concerning the Authors
 Praveen Kumar is a Specialist Answer Architect at AWS with experience in designing, constructing, and implementing fashionable knowledge and analytics platforms utilizing cloud-native companies. His areas of pursuits are serverless expertise, streaming functions, and fashionable cloud knowledge warehouses.
 Avnish Jain is a Specialist Answer Architect in Analytics at AWS with expertise designing and implementing scalable, fashionable knowledge platforms on the cloud for giant scale enterprises. He’s captivated with serving to clients construct performant and strong data-driven options and realise their knowledge & analytics potential.
[ad_2]

