



[ad_1]
Our prospects use Apache Hive on Amazon EMR for large-scale information analytics and extract, remodel, and cargo (ETL) jobs. Amazon EMR Hive makes use of Apache Tez because the default job execution engine, which creates Directed Acyclic Graphs (DAGs) to course of information. Every DAG can include a number of vertices from which duties are created to run the applying in parallel. Their closing output is written to Amazon Easy Storage Service (Amazon S3).
Hive initially writes information to staging directories after which transfer it to the ultimate location after a collection of rename operations. This design of Hive renames helps job failure restoration, equivalent to rescheduling the failed job with one other try, operating speculative execution, and recovering from a failed job try. These transfer and rename operations don’t have a major efficiency impression in HDFS as a result of it’s solely a metadata operation when in comparison with Amazon S3 the place the efficiency can degrade considerably primarily based on the variety of information written.
This put up discusses the brand new optimized committer for Hive in Amazon EMR and in addition highlights its spectacular efficiency by operating a TPCx-BB efficiency benchmark and evaluating it with the Hive default commit logic.
How Hive commit logic works
By default, Apache Hive manages the duty and job commit part and doesn’t have assist for pluggable Hadoop output committers, which you should use to customise Hive’s file commit conduct.
In its present state, the rename operation with Hive-managed and exterior tables occurs in three locations:
- Job commit – The output of job makes an attempt is saved in its personal staging listing. Within the job commit part, they’re renamed and moved to a task-specific staging listing.
- Job commit – On this part, the ultimate output is generated from the output of all dedicated duties of a job try. Job-specific staging directories are renamed and moved to the job commit staging listing.
- Transfer job – The job commit staging listing is renamed or moved to the ultimate desk listing.
The impression of those rename operations is extra vital on Hive jobs writing numerous information.
Hive EMRFS S3-optimized committer
To mitigate the slowdown in write efficiency because of renames, we added assist for output committers in Hive. We developed a brand new output committer, the Hive EMRFS S3-optimized committer, to keep away from Hive rename operations. This committer instantly writes the information to the output location, and the file commit occurs solely on the finish of the job to make sure that it’s resilient to job failures.
It modifies the default Hive file naming conference from <task_id>_<attempt_id>_<copy_n> to <task_id>_<attempt_id>_<copy_n>-<query_id>. For instance, after an insert question in a Hive desk, the output file is generated as 000000_0-hadoop_20210714130459_ba7c23ec-5695-4947-9d98-8a40ef759222-1 as a substitute of 000000_0, the place the suffix is the mix of user_name, timestamp, and UUID, which varieties the question ID.
Efficiency analysis
We ran the TPCx-BB Categorical Benchmark exams with and with out the brand new committer and evaluated the write efficiency enchancment.
The next graph reveals efficiency enchancment measured as whole runtime of the queries. With the brand new committer, the runtime is healthier(decrease).
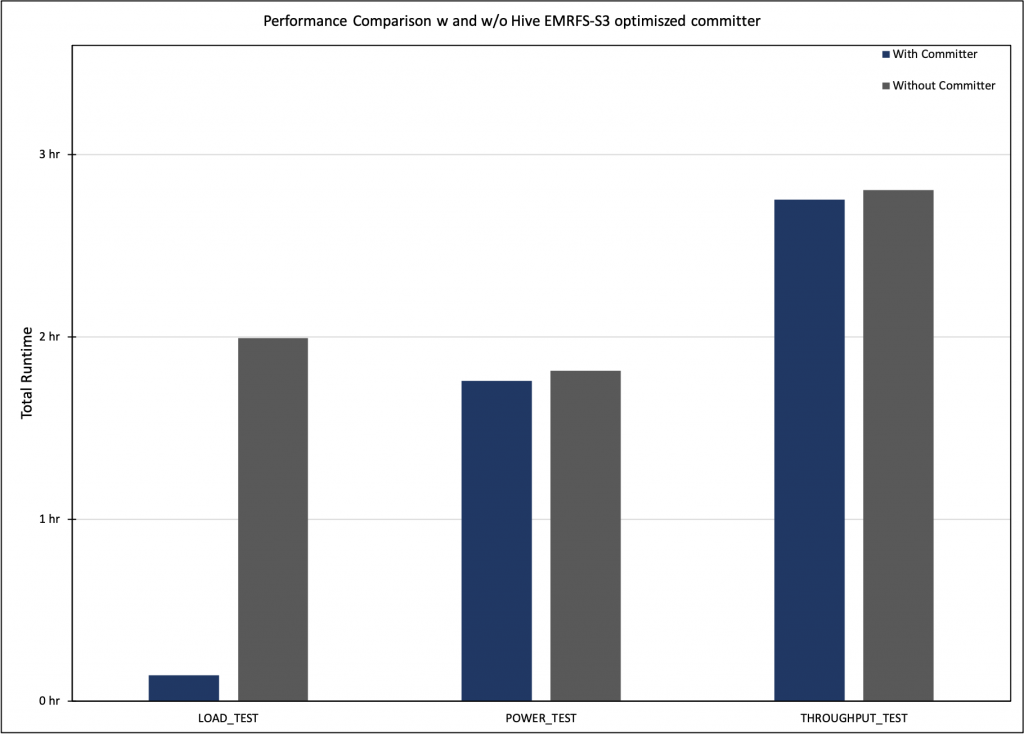
This optimization is for Hive writes and therefore the vast majority of enchancment occurred within the load check, which is the writing part of the benchmark. We noticed an approximate 15-times discount in runtime. Nonetheless, we didn’t see a lot enchancment within the energy check and throughput check as a result of every question is simply writing a single file to the ultimate desk.
The benchmark used on this put up is derived from the industry-standard TPCx-BB benchmark, and has the next traits:
- The schema and information are used unmodified from TPCx-BB.
- The size issue used is 1000.
- The queries are used unmodified from TPCx-BB.
- The suite has three exams: the load check is the method of constructing of check database and is write heavy; the ability check determines the utmost pace the system takes to run all of the queries; and the Throughput check runs the queries in concurrent streams. The run elapsed instances are used as the first metric.
- The facility exams and throughput exams embody 25 out of 30 queries. The 5 queries for machine studying workloads have been excluded.
Notice that that is derived from the TPCx-BB benchmark, and as such isn’t akin to revealed TPCx-BB outcomes, because the outcomes of our exams don’t adjust to the specification.
Understanding efficiency impression with completely different information sizes and variety of information
To benchmark the efficiency impression with variable information sizes and variety of information, we additionally evaluated the next INSERT OVERWRITE question over the store_sales desk from the TPC-DS dataset with further variations, equivalent to dimension of knowledge (1 GB, 5 GB, 10 GB, 25 GB, 50 GB, 100 GB), variety of information, and variety of partitions:
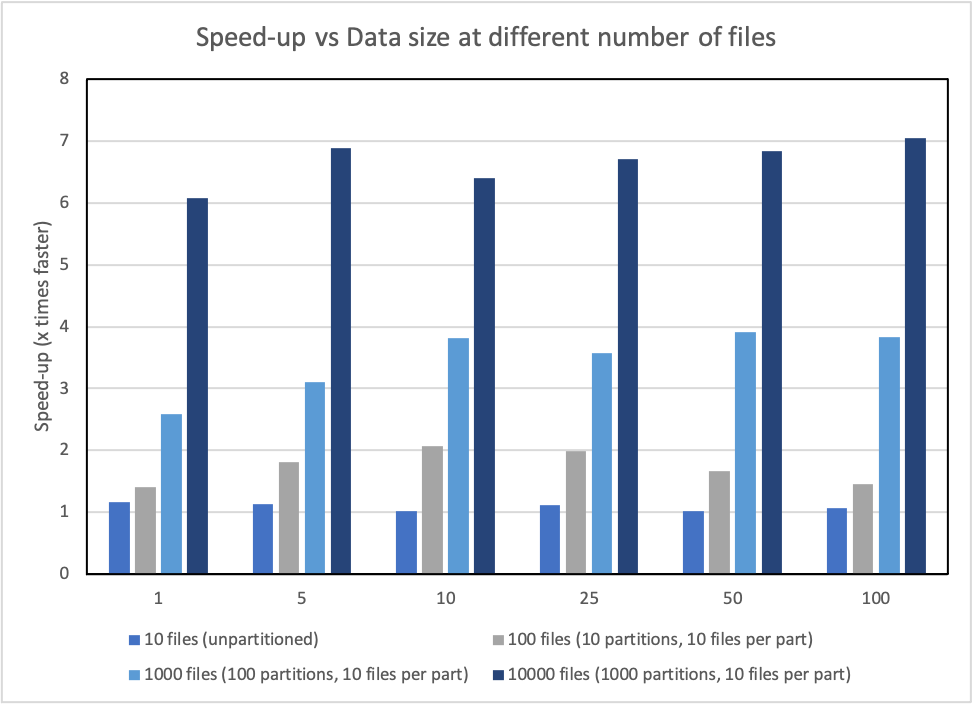
The outcomes present that the variety of information written is the crucial issue for efficiency enchancment when utilizing this new committer compared to the default Hive commit logic.
Within the following graph, the y-axis denotes the speedup (whole time taken with rename / whole time taken by question with committer), and the x-axis denotes the information dimension.
Enabling the characteristic
To allow Amazon EMR Hive to make use of HiveEMRFSOptimizedCommitter to commit information because the default for all Hive-managed and exterior tables, use the next hive-site configuration beginning with EMR 6.5.0 or EMR 5.34.0 clusters:
The brand new committer isn’t suitable with the hive.exec.parallel=true setting. Remember to not allow each settings on the similar time in Amazon EMR 6.5.0. In future EMR releases, parallel execution will routinely be disabled when the brand new Hive committer is used.
Limitations
This committer is not going to be used and default Hive commit logic can be utilized within the following eventualities:
- When merge small information (
hive.merge.tezfiles) is enabled - When utilizing Hive ACID tables
- When partitions are distributed throughout file techniques equivalent to HDFS and Amazon S3
Abstract
The Hive EMRFS S3-optimized committer improves write efficiency in comparison with the default Hive commit logic, eliminating Amazon S3 renames. You need to use this characteristic beginning with Amazon EMR 6.5.0 and Amazon EMR 5.34.0.
Keep tuned for extra updates on new options and additional enhancements in Apache Hive on Amazon EMR.
Concerning the Authors
 Suthan Phillips works with prospects to offer them architectural steering and helps them obtain efficiency enhancements for complicated purposes on Amazon EMR. In his spare time, he enjoys climbing and exploring the Pacific Northwest.
 Aditya Shah is a Software program Improvement Engineer at AWS. He’s all in favour of Databases and Knowledge warehouse engines and has labored on distributed filesystem, ACID compliance and metadata administration of Apache Hive. When not fascinated by information, he’s searching pages of web to sate his urge for food for random trivia and is a film geek at coronary heart.
 Syed Shameerur Rahman is a software program improvement engineer at Amazon EMR. He’s all in favour of extremely scalable, distributed computing. He’s an energetic contributor of open supply initiatives like Apache Hive, Apache Tez, Apache ORC and has contributed vital options and optimizations. Throughout his free time, he enjoys exploring new locations and meals.
[ad_2]

