



[ad_1]
That is the fifth in a collection of posts. We’re excited to share dozens of recent options to automate your schema conversion; protect your funding in current scripts, experiences, and functions; speed up question efficiency; and probably simplify your migrations from legacy knowledge warehouses to Amazon Redshift.
Amazon Redshift is the main cloud knowledge warehouse. No different knowledge warehouse makes it as straightforward to realize new insights out of your knowledge. With Amazon Redshift, you may question exabytes of information throughout your knowledge warehouse, operational knowledge shops, and knowledge lake utilizing customary SQL. You may as well combine different AWS companies corresponding to Amazon EMR, Amazon Athena, Amazon SageMaker, AWS Glue, AWS Lake Formation, and Amazon Kinesis to make use of all of the analytic capabilities within the AWS Cloud.
Till now, migrating a knowledge warehouse to AWS has been a fancy enterprise, involving a big quantity of handbook effort. You could manually remediate syntax variations, inject code to interchange proprietary options, and manually tune the efficiency of queries and experiences on the brand new platform.
Legacy workloads could depend on non-ANSI, proprietary options that aren’t immediately supported by trendy databases like Amazon Redshift. For instance, many Teradata functions use SET tables, which implement full row uniqueness—there can’t be two rows in a desk which might be an identical in all of their attribute values.
If you happen to’re an Amazon Redshift person, it’s possible you’ll wish to implement SET semantics however can’t depend on a local database characteristic. You should use the design patterns on this publish to emulate SET semantics in your SQL code. Alternatively, in case you’re migrating a workload to Amazon Redshift, you should use the AWS Schema Conversion Instrument (AWS SCT) to robotically apply the design patterns as a part of your code conversion.
On this publish, we describe the SQL design patterns and analyze their efficiency, and present how AWS SCT can automate this as a part of your knowledge warehouse migration. Let’s begin by understanding how SET tables behave in Teradata.
Teradata SET tables
At first look, a SET desk could seem just like a desk that has a main key outlined throughout all of its columns. Nonetheless, there are some necessary semantic variations from conventional main keys. Take into account the next desk definition in Teradata:
We populate the desk with 4 rows of information, as follows:
Discover that we didn’t outline a UNIQUE PRIMARY INDEX (just like a main key) on the desk. Now, once we attempt to insert a brand new row into the desk that could be a duplicate of an current row, the insert fails:
Equally, if we attempt to replace an current row in order that it turns into a reproduction of one other row, the replace fails:
In different phrases, easy INSERT-VALUE and UPDATE statements fail in the event that they introduce duplicate rows right into a Teradata SET desk.
There’s a notable exception to this rule. Take into account the next staging desk, which has the identical attributes because the goal desk:
The staging desk is a MULTISET desk and accepts duplicate rows. We populate three rows into the staging desk. The primary row is a reproduction of a row within the goal desk. The second and third rows are duplicates of one another, however don’t duplicate any of the goal rows.
Now we efficiently insert the staging knowledge into the goal desk (which is a SET desk):
If we study the goal desk, we will see {that a} single row for (2022-01-05, 500) has been inserted, and the duplicate row for (2022-01-01, 100) has been discarded. Primarily, Teradata silently discards any duplicate rows when it performs an INSERT-SELECT assertion. This contains duplicates which might be within the staging desk and duplicates which might be shared between the staging and goal tables.
Primarily, SET tables behave in another way relying on the kind of operation being run. An INSERT-VALUE or UPDATE operation suffers a failure if it introduces a reproduction row into the goal. An INSERT-SELECT operation doesn’t endure a failure if the staging desk accommodates a reproduction row, or a reproduction row is shared between the staging and desk tables.
On this publish, we don’t go into element on learn how to convert INSERT-VALUE or UPDATE statements. These statements usually contain one or a number of rows and are much less impactful by way of efficiency than INSERT-SELECT statements. For INSERT-VALUE or UPDATE statements, you may materialize the row (or rows) being created, and be part of that set to the goal desk to test for duplicates.
INSERT-SELECT
In the remainder of this publish, we analyze INSERT-SELECT statements fastidiously. Clients have informed us that INSERT-SELECT operations can comprise as much as 78% of the INSERT workload towards SET tables. We’re involved with statements with the next kind:
The schema of the staging desk is an identical to the goal desk on a column-by-column foundation. As we talked about earlier, a reproduction row can seem in two completely different circumstances:
- The staging desk just isn’t set-unique, that means that there are two or extra full row duplicates within the staging knowledge
- There’s a row x within the staging desk and an an identical row x within the goal desk
As a result of Amazon Redshift helps multiset desk semantics, it’s attainable that the staging desk accommodates duplicates (the primary circumstance we listed). Due to this fact, any automation should deal with each circumstances, as a result of both can introduce a reproduction into an Amazon Redshift desk.
Primarily based on this evaluation, we applied the next algorithms:
- MINUS – This implements the total set logic deduplication utilizing SQL MINUS. MINUS works in all circumstances, together with when the staging desk isn’t set-unique and when the intersection of the staging desk and goal desk is non-empty. MINUS additionally has the benefit that NULL values don’t require particular comparability logic to beat NULL to NULL comparisons. MINUS has the next syntax:
- MINUS-MIN-MAX – That is an optimization on MINUS that includes a filter to restrict the goal desk scan primarily based on the values within the stage desk. The min/max filters enable the question engine to skip massive numbers of block throughout desk scans. See Working with kind keys for extra particulars.
We additionally thought-about different algorithms, however we don’t advocate that you just use them. For instance, you may carry out a GROUP BY to eradicate duplicates within the staging desk, however this step is pointless in case you use the MINUS operator. You may as well carry out a left (or proper) outer be part of to search out shared duplicates between the staging and goal tables, however then further logic is required to account for NULL = NULL situations.
Efficiency
We examined the MINUS and MINUS-MIN-MAX algorithms on Amazon Redshift. We ran the algorithms on two Amazon Redshift clusters. The primary configuration consisted of 6 x ra3.4xlarge nodes. The second consisted of 12 x ra3.4xlarge nodes. Every node contained 12 CPU and 96 GB of reminiscence.
We created the stage and goal tables with an identical kind and distribution keys to reduce knowledge motion. We loaded the identical goal dataset into each clusters. The goal dataset consisted of 1.1 billion rows of information. We then created staging datasets that ranged from 20 million to 200 million rows, in 20 million row increments.
The next graph reveals our outcomes.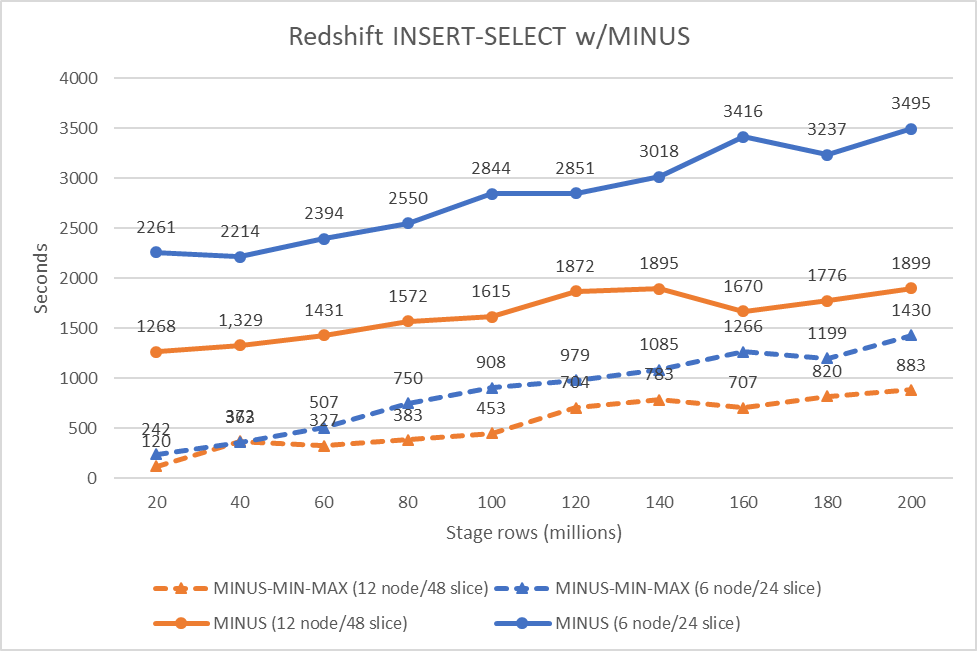
The check knowledge was artificially generated and a few skew was current within the distribution key values. That is manifested within the small deviations from linearity within the efficiency.
Nonetheless, you may observe the efficiency enhance that’s afforded the MINUS-MIN-MAX algorithm over the fundamental MINUS algorithm (evaluating orange traces or blue traces to themselves). If you happen to’re implementing SET tables in Amazon Redshift, we advocate utilizing MINUS-MIN-MAX as a result of this algorithm gives a contented convergence of straightforward, readable code and good efficiency.
Automation
All Amazon Redshift tables enable duplicate rows, i.e., they’re MULTISET tables by default. In case you are changing a Teradata workload to run on Amazon Redshift, you’ll must implement SET semantics outdoors of the database.
We’re blissful to share that AWS SCT will robotically convert your SQL code that operates towards SET tables. AWS SCT will rewrite INSERT-SELECT that load SET tables to include the rewrite patterns we described above.
Let’s see how this works. Suppose you have got the next goal desk definition in Teradata:
The stage desk is an identical to the goal desk, besides that it’s created as a MULTISET desk in Teradata.
Subsequent, we create a process to load the very fact desk from the stage desk. The process accommodates a single INSERT-SELECT assertion:
Now we use AWS SCT to transform the Teradata saved process to Amazon Redshift. First, choose the saved process within the supply database tree, then right-click and select Convert schema.

AWS SCT converts the saved process (and embedded INSERT-SELECT) utilizing the MINUS-MIN-MAX rewrite sample.

And that’s it! Presently, AWS SCT solely performs rewrite for INSERT-SELECT as a result of these statements are closely utilized by ETL workloads and have probably the most affect on efficiency. Though the instance we used was embedded in a saved process, you may as well use AWS SCT to transform the identical statements in the event that they’re in BTEQ scripts, macros, or software packages. Obtain the newest model of AWS SCT and provides it a strive!
Conclusion
On this publish, we confirmed learn how to implement SET desk semantics in Amazon Redshift. You should use the described design patterns to develop new functions that require SET semantics. Or, in case you’re changing an current Teradata workload, you should use AWS SCT to robotically convert your INSERT-SELECT statements in order that they protect the SET desk semantics.
We’ll be again quickly with the following installment on this collection. Test again for extra data on automating your migrations from Teradata to Amazon Redshift. Within the meantime, you may study extra about Amazon Redshift and AWS SCT. Glad migrating!
Concerning the Authors
 Michael Soo is a Principal Database Engineer with the AWS Database Migration Service workforce. He builds services and products that assist prospects migrate their database workloads to the AWS cloud.
 Po Hong, PhD, is a Principal Information Architect of the Fashionable Information Structure International Specialty Observe (GSP), AWS Skilled Companies. He’s obsessed with serving to prospects to undertake modern options and migrate from massive scale MPP knowledge warehouses to the AWS trendy knowledge structure.
[ad_2]

