

[ad_1]
Introduction
This weblog is an element considered one of our Admin Necessities collection, the place we’ll concentrate on matters which can be necessary to these managing and sustaining Databricks environments. Preserve a watch out for extra blogs on knowledge governance, ops & automation, consumer administration & accessibility, and price monitoring & administration within the close to future!
In 2020, Databricks started releasing non-public previews of a number of platform options recognized collectively as Enterprise 2.0 (or E2); these options offered the following iteration of the Lakehouse platform, creating the scalability and safety to match the ability and velocity already obtainable on Databricks. When Enterprise 2.0 was made publicly obtainable, one of the crucial anticipated additions was the flexibility to create a number of workspaces from a single account. This characteristic opened new prospects for collaboration, organizational alignment, and simplification. As now we have discovered since, nonetheless, it has additionally raised a bunch of questions. Based mostly on our expertise throughout enterprise clients of each dimension, form and vertical, this weblog will lay out solutions and greatest practices to the most typical questions round workspace administration inside Databricks; at a elementary degree, this boils right down to a easy query: precisely when ought to a brand new workspace be created? Particularly, we’ll spotlight the important thing methods for organizing your workspaces, and greatest practices of every.
Workspace group fundamentals
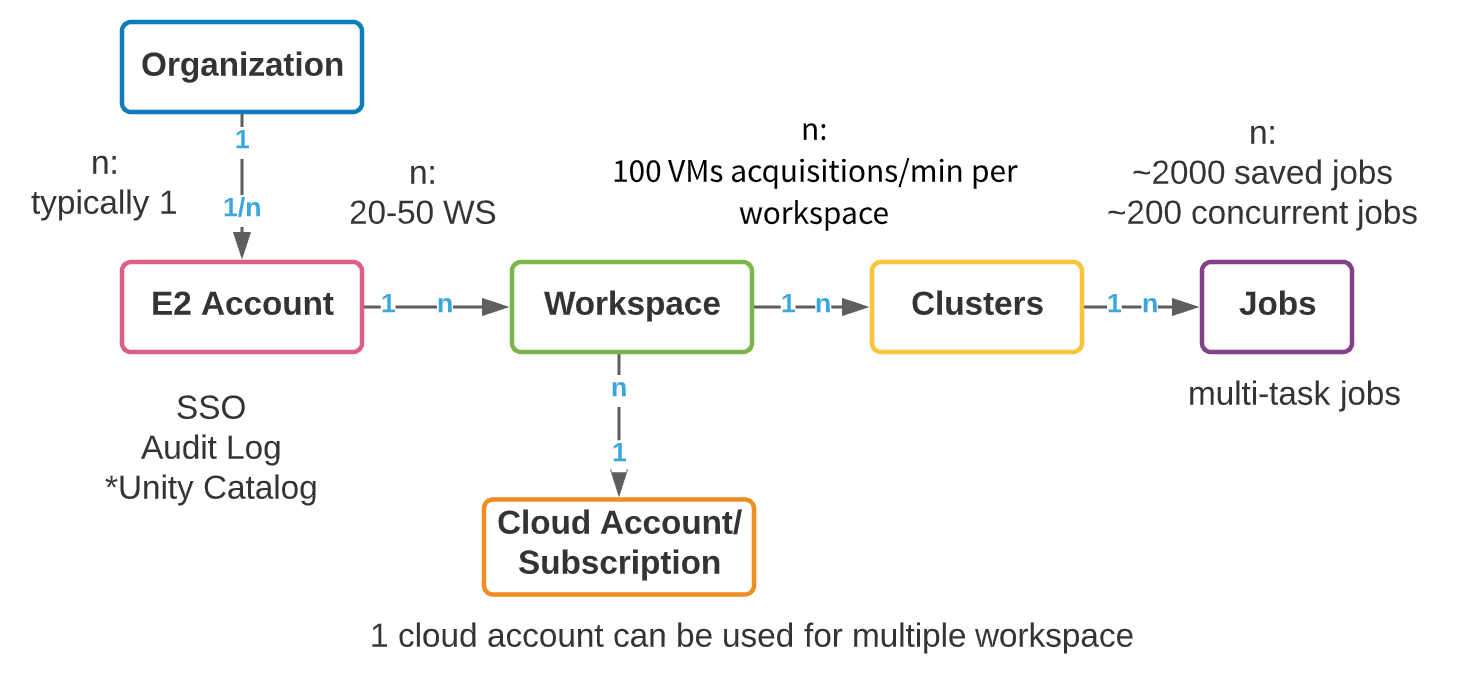
Though every cloud supplier (AWS, Azure and GCP) has a distinct underlying structure, the group of Databricks workspaces throughout clouds is analogous. The logical prime degree assemble is an E2 grasp account (AWS) or a subscription object (Azure Databricks/GCP). In AWS, we provision a single E2 account per group that gives a unified pane of visibility and management to all workspaces. On this manner, your admin exercise is centralized, with the flexibility to allow SSO, Audit Logs, and Unity Catalog. Azure has comparatively much less restriction on creation of top-level subscription objects; nonetheless, we nonetheless suggest that the variety of top-level subscriptions used to create Databricks workspaces be managed as a lot as potential. We are going to consult with the top-level assemble as an account all through this weblog, whether or not it’s an AWS E2 account or GCP/Azure subscription.
Inside a top-level account, a number of workspaces might be created. The advisable max workspaces per account is between 20 and 50 on Azure, with a onerous restrict on AWS. This restrict arises from the executive overhead that stems from a rising variety of workspaces: managing collaboration, entry, and safety throughout tons of of workspaces can grow to be an especially tough job, even with distinctive automation processes. Beneath, we current a high-level object mannequin of a Databricks account.
Enterprises must create assets of their cloud account to help multi-tenancy necessities. The creation of separate cloud accounts and workspaces for every new use case does have some clear benefits: ease of value monitoring, knowledge and consumer isolation, and a smaller blast radius in case of safety incidents. Nonetheless, account proliferation brings with it a separate set of complexities – governance, metadata administration and collaboration overhead develop together with the variety of accounts. The important thing, in fact, is steadiness. Beneath, we’ll first undergo some normal concerns for enterprise workspace group; then, we’ll undergo two frequent workspace isolation methods that we see amongst our clients: LOB-based and product-based. Every has strengths, weaknesses and complexities that we are going to talk about earlier than giving greatest practices.
Normal workspace group concerns
When designing your workspace technique, the very first thing we regularly see clients leap to is the macro-level organizational decisions; nonetheless, there are a lot of lower-level selections which can be simply as necessary! We’ve compiled essentially the most pertinent of those under.
A easy three-workspace strategy
Though we spend most of this weblog speaking about easy methods to cut up your workspaces for optimum effectiveness, there are a complete class of Databricks clients for whom a single, unified workspace per setting is greater than sufficient! In actual fact, this has grow to be an increasing number of sensible with the rise of options like Repos, Unity Catalog, persona-based touchdown pages, and so on. In such instances, we nonetheless suggest the separation of Growth, Staging and Manufacturing workspaces for validation and QA functions. This creates an setting very best for small companies or groups that worth agility over complexity.
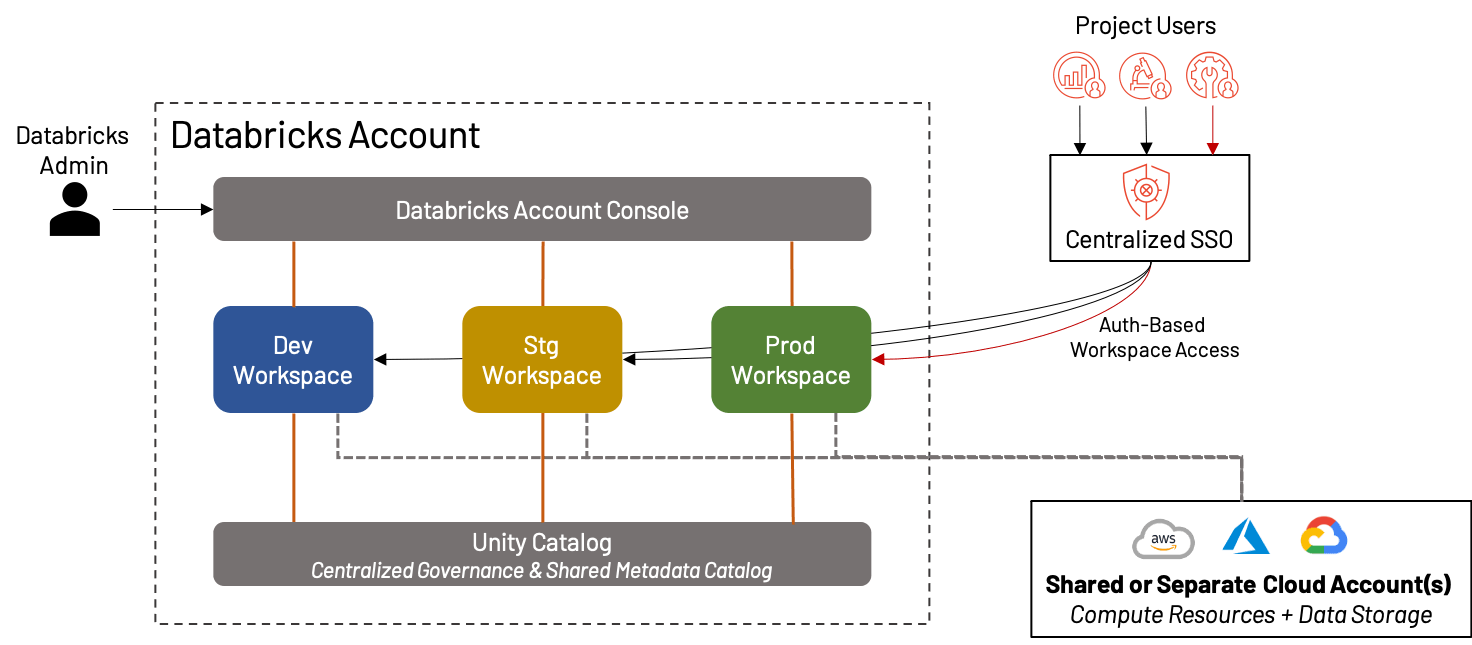
The advantages and downsides of making a single set of workspaces are:
+ There isn’t a concern of cluttering the workspace internally, mixing property, or diluting the fee/utilization throughout a number of tasks/groups; every thing is in the identical setting
+ Simplicity of group means diminished administrative overhead
– For bigger organizations, a single dev/stg/prd workspace is untenable as a result of platform limits, muddle, lack of ability to isolate knowledge, and governance issues
If a single set of workspaces looks as if the precise strategy for you, the next greatest practices will assist preserve your Lakehouse working easily:
- Outline a standardized course of for pushing code between the varied environments; as a result of there is just one set of environments, this can be easier than with different approaches. Leverage options similar to Repos and Secrets and techniques and exterior instruments that foster good CI/CD processes to ensure your transitions happen mechanically and easily.
- Set up and often evaluation Identification Supplier teams which can be mapped to Databricks property; as a result of these teams are the first driver of consumer authorization on this technique, it’s essential that they be correct, and that they map to the suitable underlying knowledge and compute assets. For instance, most customers seemingly don’t want entry to the manufacturing workspace; solely a small handful of engineers or admins could have the permissions.
- Keep watch over your utilization and know the Databricks Useful resource Limits; in case your workspace utilization or consumer rely begins to develop, you might want to think about adopting a extra concerned workspace group technique to keep away from per-workspace limits. Leverage useful resource tagging wherever potential with a purpose to observe value and utilization metrics.
Leveraging sandbox workspaces
In any of the methods talked about all through this text, a sandbox setting is an effective observe to permit customers to incubate and develop much less formal, however nonetheless probably useful work. Critically, these sandbox environments must steadiness the liberty to discover actual knowledge with safety towards unintentionally (or deliberately) impacting manufacturing workloads. One frequent greatest observe for such workspaces is to host them in a wholly separate cloud account; this drastically limits the blast radius of customers within the workspace. On the identical time, establishing easy guardrails (similar to Cluster Insurance policies, limiting the information entry to “play” or cleansed datasets, and shutting down outbound connectivity the place potential) means customers can have relative freedom to do (virtually) no matter they wish to do without having fixed admin supervision. Lastly, inner communication is simply as necessary; if customers unwittingly construct an incredible software within the Sandbox that draws 1000’s of customers, or count on production-level help for his or her work on this setting, these administrative financial savings will evaporate rapidly.
Greatest practices for sandbox workspaces embody:
- Use a separate cloud account that doesn’t comprise delicate or manufacturing knowledge.
- Arrange easy guardrails in order that customers can have relative freedom over the setting without having admin oversight.
- Talk clearly that the sandbox setting is “self-service.”
Information isolation & sensitivity
Delicate knowledge is rising in prominence amongst our clients in all verticals; knowledge that was as soon as restricted to healthcare suppliers or bank card processors is now changing into supply for understanding affected person evaluation or buyer sentiment, analyzing rising markets, positioning new merchandise, and virtually the rest you’ll be able to consider. This wealth of knowledge comes with excessive potential threat, with ever-increasing threats of knowledge breaches; because of this, conserving delicate knowledge segregated and guarded is necessary it doesn’t matter what organizational technique you select. Databricks gives a number of means to defend delicate knowledge (similar to ACLs and safe sharing), and mixed with cloud supplier instruments, could make the Lakehouse you construct as low-risk as potential. A number of the greatest practices round Information Isolation & Sensitivity embody:
- Perceive your distinctive knowledge safety wants; that is crucial level. Each enterprise has completely different knowledge, and your knowledge will drive your governance.
- Apply insurance policies and controls at each the storage degree and on the metastore. S3 insurance policies and ADLS ACLs ought to all the time be utilized utilizing the precept of least-access. Leverage Unity Catalog to use an extra layer of management over knowledge entry.
- Separate your delicate knowledge from non-sensitive knowledge each logically and bodily; many shoppers use completely separate cloud accounts (and Databricks workspaces) for delicate and non-sensitive knowledge.
DR and regional backup
Catastrophe Restoration (DR) is a broad subject that’s necessary whether or not you employ AWS, Azure or GCP; we received’t cowl every thing on this weblog, however will relatively concentrate on how DR and Regional concerns play into workspace design. On this context, DR implies the creation and upkeep of a workspace in a separate area from the usual Manufacturing workspace.
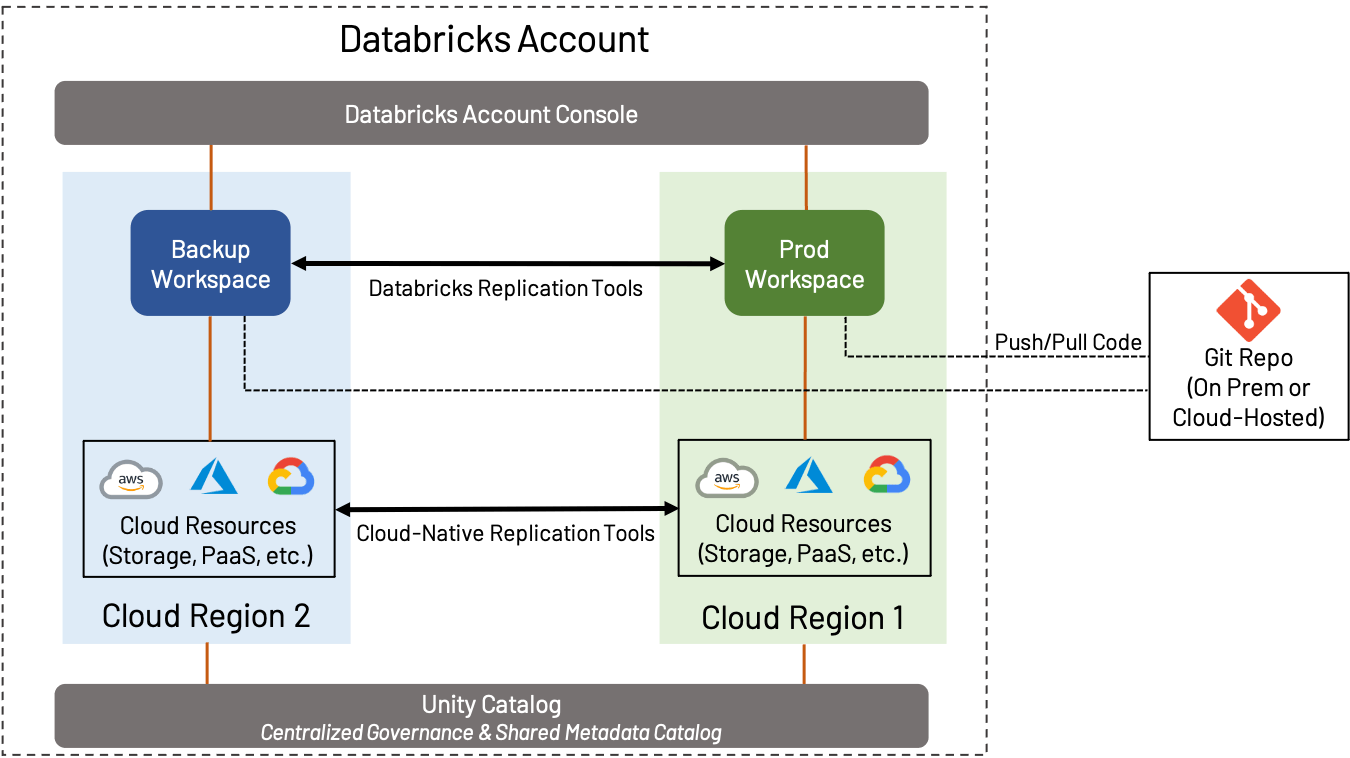
DR technique can fluctuate broadly relying on the wants of the enterprise. For instance, some clients choose to keep up an active-active configuration, the place all property from one workspace are continually replicated to a secondary workspace; this gives the utmost quantity of redundancy, but in addition implies complexity and price (continually transferring knowledge cross-region and performing object replication and deduplication is a sophisticated course of). Alternatively, some clients choose to do the minimal obligatory to make sure enterprise continuity; a secondary workspace could comprise little or no till failover happens, or could also be backed up solely on an occasional foundation. Figuring out the precise degree of failover is essential.
No matter what degree of DR you select to implement, we suggest the next:
- Retailer code in a Git repository of your selection, both on-prem or within the cloud, and use options similar to Repos to sync it to Databricks wherever potential.
- Every time potential, use Delta Lake along side Deep Clone to copy knowledge; this gives a simple, open-source method to effectively again up knowledge.
- Use the cloud-native instruments offered by your cloud supplier to carry out backup of issues similar to knowledge not saved in Delta Lake, exterior databases, configurations, and so on.
- Use instruments similar to Terraform to again up objects similar to notebooks, jobs, secrets and techniques, clusters, and different workspace objects.
Bear in mind: Databricks is chargeable for sustaining regional workspace infrastructure within the Management Aircraft, however you might be chargeable for your workspace-specific property, in addition to the cloud infrastructure your manufacturing jobs depend upon.
Isolation by line of enterprise (LOB)
We now dive into the precise group of workspaces in an enterprise context. LOB-based mission isolation grows out of the standard enterprise-centric manner of taking a look at IT assets – it additionally carries many conventional strengths (and weaknesses) of LOB-centric alignment. As such, for a lot of massive companies, this strategy to workspace administration will come naturally.
In an LOB-based workspace technique, every practical unit of a enterprise will obtain a set of workspaces; historically, this may embody growth, staging, and manufacturing workspaces, though now we have seen clients with as much as 10 intermediate phases, every potential with their very own workspace (not advisable)! Code is written and examined in DEV, then promoted (by way of CI/CD automation) to STG, and eventually lands in PRD, the place it runs as a scheduled job till being deprecated. Atmosphere kind and unbiased LOB are the first causes to provoke a brand new workspace on this mannequin; doing so for each use case or knowledge product could also be extreme.
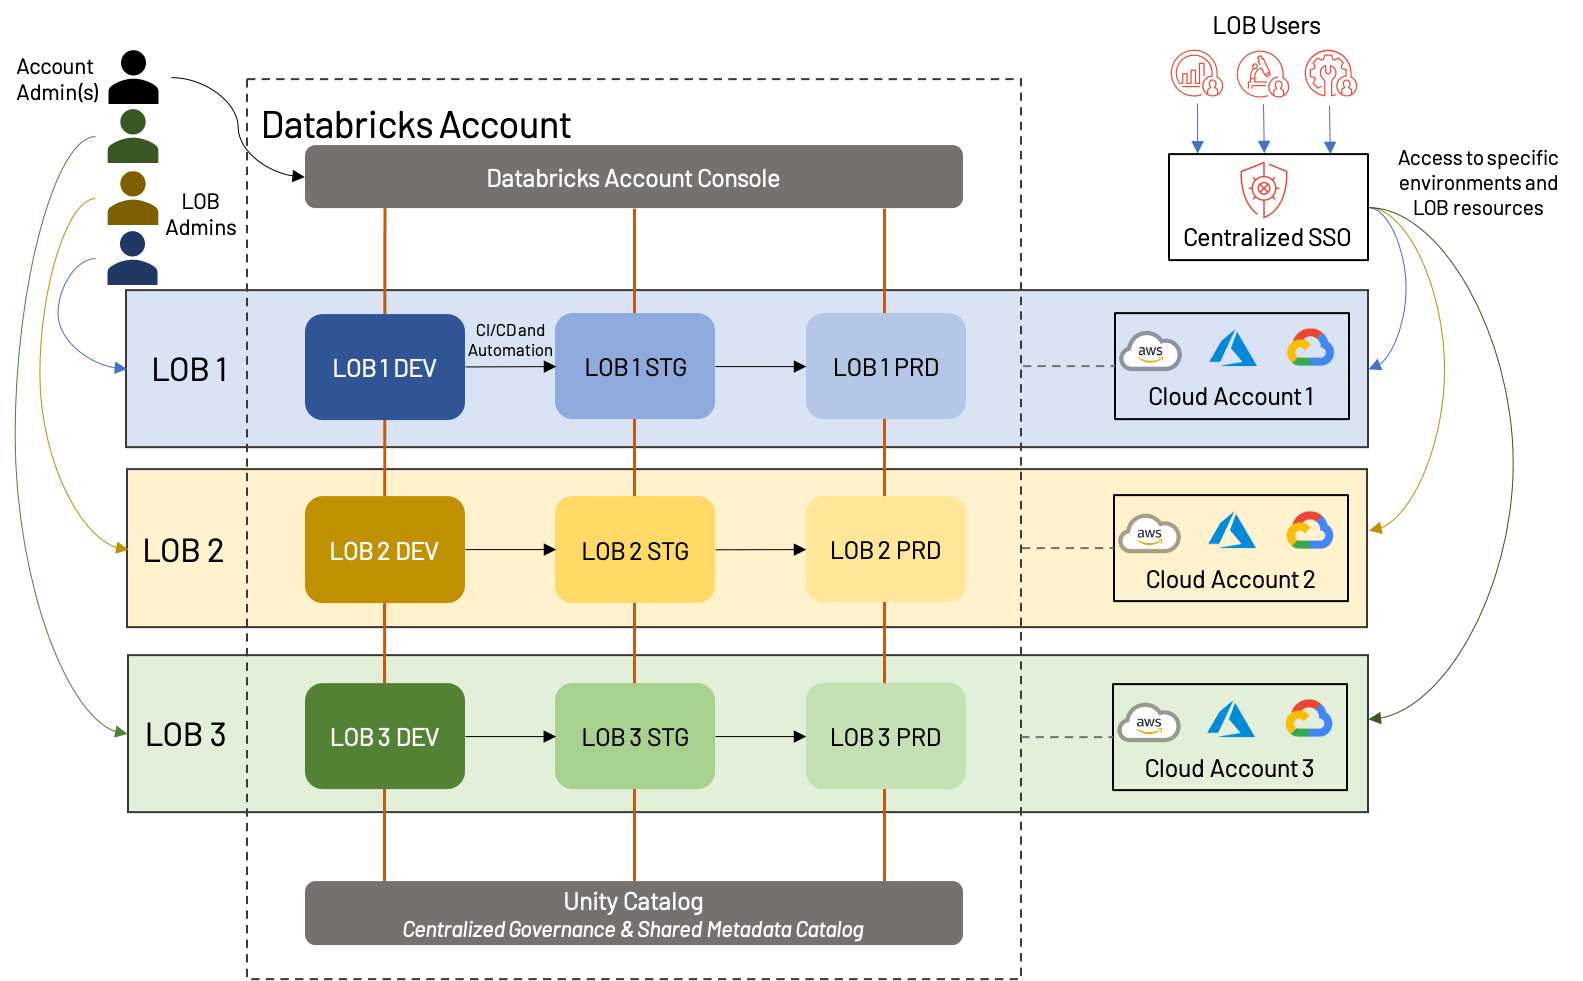
The above diagram exhibits one potential manner that LOB-based workspace might be structured; on this case, every LOB has a separate cloud account with one workspace in every setting (dev/stg/prd) and likewise has a devoted admin. Importantly, all of those workspaces fall beneath the identical Databricks account, and leverage the identical Unity Catalog. Some variations would come with sharing cloud accounts (and probably underlying assets similar to VPCs and cloud providers), utilizing a separate dev/stg/prd cloud account, or creating separate exterior metastores for every LOB. These are all affordable approaches that rely closely on enterprise wants.
General, there are a number of advantages, in addition to a number of drawbacks to the LOB strategy:
+Belongings for every LOB might be remoted, each from a cloud perspective and from a workspace perspective; this makes for easy reporting/value evaluation, in addition to a much less cluttered workspace.
+Clear division of customers and roles improves the general governance of the Lakehouse, and reduces total threat.
+Automation of promotion between environments creates an environment friendly and low-overhead course of.
–Up-front planning is required to make sure that cross-LOB processes are standardized, and that the general Databricks account is not going to hit platform limits.
–Automation and administrative processes require specialists to arrange and keep.
As greatest practices, we suggest the next to these constructing LOB-based Lakehouses:
- Make use of a least-privilege entry mannequin utilizing fine-grained entry management for customers and environments; normally, only a few customers ought to have manufacturing entry, and interactions with this setting must be automated and extremely managed. Seize these customers and teams in your id supplier and sync them to the Lakehouse.
- Perceive and plan for each cloud supplier and Databricks platform limits; these embody, for instance, the variety of workspaces, API price limiting on ADLS, throttling on Kinesis streams, and so on.
- Use a standardized metastore/catalog with sturdy entry controls wherever potential; this enables for re-use of property with out compromising isolation. Unity Catalog permits for fine-grained controls over tables and workspace property, which incorporates objects similar to MLflow experiments.
- Leverage knowledge sharing wherever potential to securely share knowledge between LOBs without having to duplicate effort.
Information product isolation
What will we do when LOBs must collaborate cross-functionally, or when a easy dev/stg/prd mannequin doesn’t match the use instances of our LOB? We will shed a few of the formality of a strict LOB-based Lakehouse construction and embrace a barely extra trendy strategy; we name this workspace isolation by Information Product. The idea is that as a substitute of isolating strictly by LOB, we isolate as a substitute by top-level tasks, giving every a manufacturing setting. We additionally combine in shared growth environments to keep away from workspace proliferation and make reuse of property easier.
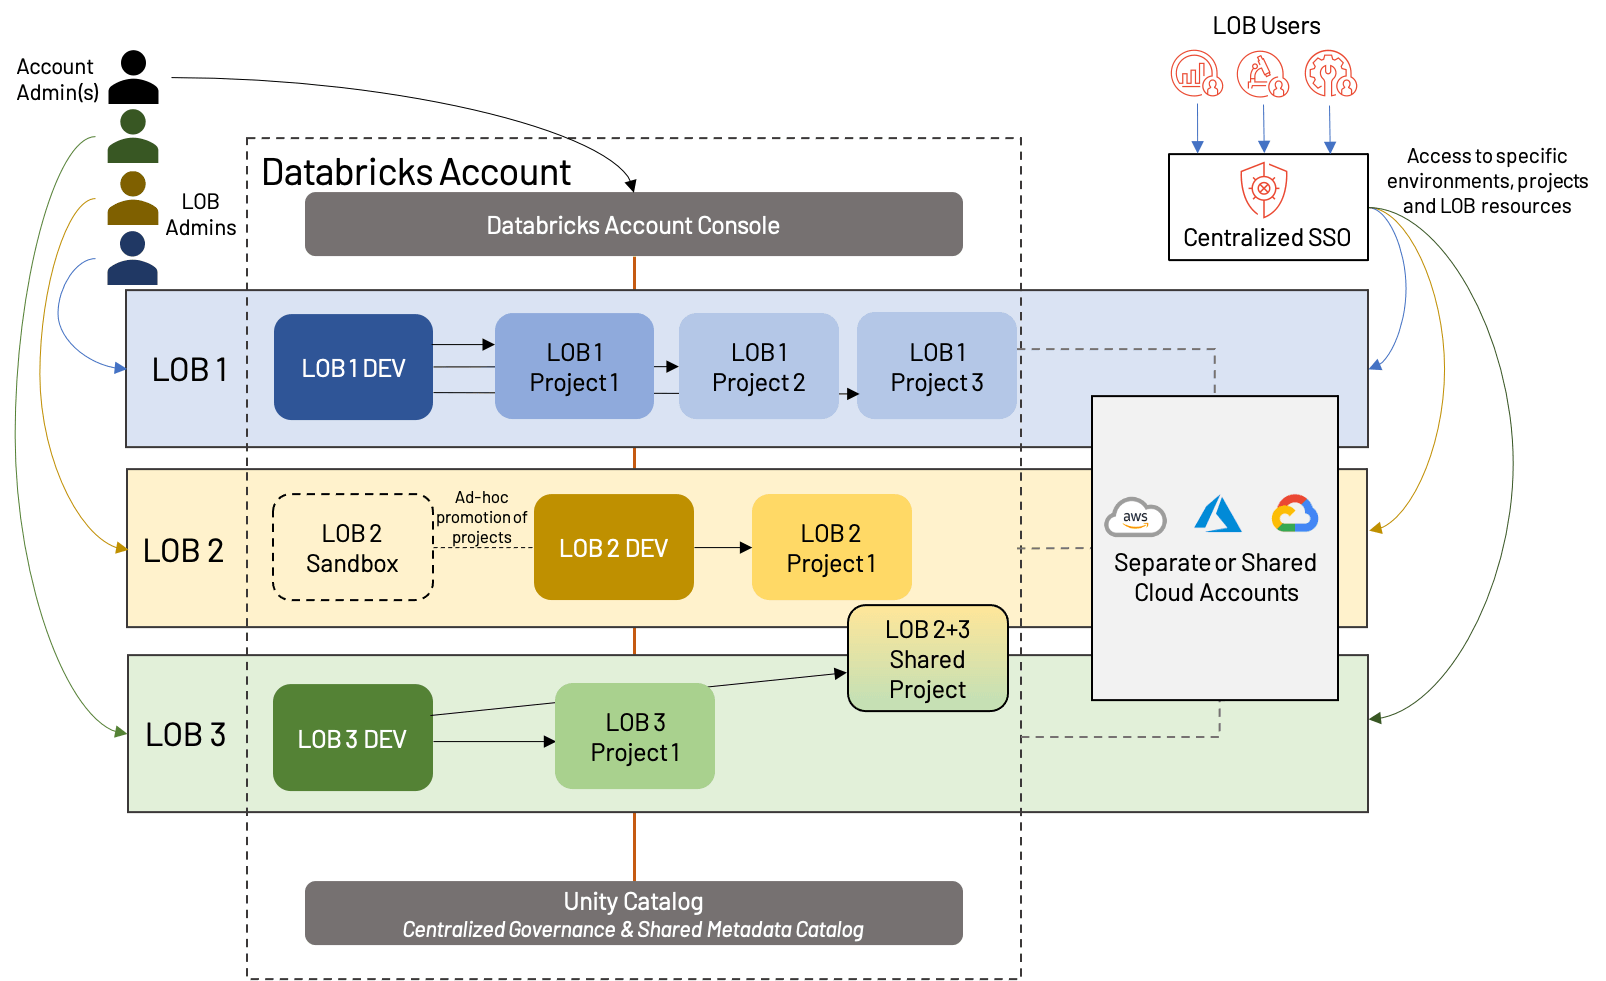
At first look, this seems just like the LOB-based isolation from above, however there are a number of necessary distinctions:
- A shared dev workspace, with separate workspaces for every top-level mission (which implies every LOB could have a distinct variety of workspaces total)
- The presence of sandbox workspaces, that are particular to an LOB, and provide extra freedom and fewer automation than conventional Dev workspaces
- Sharing of assets and/or workspaces; that is additionally potential in LOB-based architectures, however is commonly difficult by extra inflexible separation
This strategy shares most of the identical strengths and weaknesses as LOB-based isolation, however affords extra flexibility and emphasizes the worth of tasks within the trendy Lakehouse. An increasing number of, we see this changing into the “gold customary” of workspace group, corresponding with the motion of know-how from primarily a cost-driver to a worth generator. As all the time, enterprise wants could drive slight deviations from this pattern structure, similar to devoted dev/stg/prd for notably massive tasks, cross-LOB tasks, kind of segregation of cloud assets, and so on. Whatever the actual construction, we recommend the next greatest practices:
- Share knowledge and assets at any time when potential; though segregation of infrastructure and workspaces is helpful for governance and monitoring, proliferation of assets rapidly turns into a burden. Cautious evaluation forward of time will assist to determine areas of re-use.
- Even when not sharing extensively between tasks, use a shared metastore similar to Unity Catalog, and shared code-bases (by way of, i.e., Repos) the place potential.
- Use Terraform (or related instruments) to automate the method of making, managing and deleting workspaces and cloud infrastructure.
- Present flexibility to customers by way of sandbox environments, however make sure that these have acceptable guard rails set as much as restrict cluster sizes, knowledge entry, and so on.
Abstract
To completely leverage all the advantages of the Lakehouse and help future development and manageability, care must be taken to plan workspace format. Different related artifacts that should be thought of throughout this design embody a centralized mannequin registry, codebase, and catalog to help collaboration with out compromising safety. To summarize a few of the greatest practices highlighted all through this text, our key takeaways are listed under:
Greatest Follow #1: Decrease the variety of top-level accounts (each on the cloud supplier and Databricks degree) the place potential, and create a workspace solely when separation is critical for compliance, isolation, or geographical constraints. When doubtful, preserve it easy!
Greatest Follow #2: Determine on an isolation technique that may present you long-term flexibility with out undue complexity. Be real looking about your wants and implement strict pointers earlier than starting to onramp workloads to your Lakehouse; in different phrases, measure twice, minimize as soon as!
Greatest Follow #3: Automate your cloud processes. This ranges each facet of your infrastructure (lots of which will probably be lined in following blogs!), together with SSO/SCIM, Infrastructure-as-Code with a software similar to Terraform, CI/CD pipelines and Repos, cloud backup, and monitoring (utilizing each cloud-native and third-party instruments).
Greatest Follow #4: Take into account establishing a COE crew for central governance of an enterprise-wide technique, the place repeatable points of an information and machine studying pipeline is templatized and automatic in order that completely different knowledge groups can use self-service capabilities with sufficient guardrails in place. The COE crew is commonly a light-weight however essential hub for knowledge groups and will view itself as an enabler- sustaining documentation, SOPs, how-tos and FAQs to coach different customers.
Greatest Follow #5: The Lakehouse gives a degree of governance that the Information Lake doesn’t; take benefit! Assess your compliance and governance wants as one of many first steps of building your Lakehouse, and leverage the options that Databricks gives to ensure threat is minimized. This consists of audit log supply, HIPAA and PCI (the place relevant), correct exfiltration controls, use of ACLs and consumer controls, and common evaluation of the entire above.
We’ll be offering extra Admin greatest observe blogs within the close to future, on matters from Information Governance to Person Administration. Within the meantime, attain out to your Databricks account crew with questions on workspace administration, or should you’d wish to study extra about greatest practices on the Databricks Lakehouse Platform!
[ad_2]

