


[ad_1]
Amazon Redshift is essentially the most broadly used cloud information warehouse. Amazon Redshift makes it simple and cost-effective to carry out analytics on huge quantities of knowledge. Amazon Redshift launched Streaming Ingestion for Amazon Kinesis Knowledge Streams, which allows you to load information into Amazon Redshift with low latency and with out having to stage the info in Amazon Easy Storage Service (Amazon S3). This new functionality allows you to construct experiences and dashboards and carry out analytics utilizing contemporary and present information, while not having to handle customized code that periodically masses new information.
Upsolver is an AWS Superior Expertise Accomplice that allows you to ingest information from a variety of sources, remodel it, and cargo the outcomes into your goal of selection, reminiscent of Kinesis Knowledge Streams and Amazon Redshift. Knowledge analysts, engineers, and information scientists outline their transformation logic utilizing SQL, and Upsolver automates the deployment, scheduling, and upkeep of the info pipeline. It’s pipeline ops simplified!
There are a number of methods to stream information to Amazon Redshift and on this publish we’ll cowl two choices that Upsolver may also help you with: First, we present you easy methods to configure Upsolver to stream occasions to Kinesis Knowledge Streams which are consumed by Amazon Redshift utilizing Streaming Ingestion. Second, we display easy methods to write occasion information to your information lake and eat it utilizing Amazon Redshift Serverless so you may go from uncooked occasions to analytics-ready datasets in minutes.
Conditions
Earlier than you get began, you should set up Upsolver. You may join Upsolver and deploy it immediately into your VPC to securely entry Kinesis Knowledge Streams and Amazon Redshift.
Configure Upsolver to stream occasions to Kinesis Knowledge Streams
The next diagram represents the structure to jot down occasions to Kinesis Knowledge Streams and Amazon Redshift.
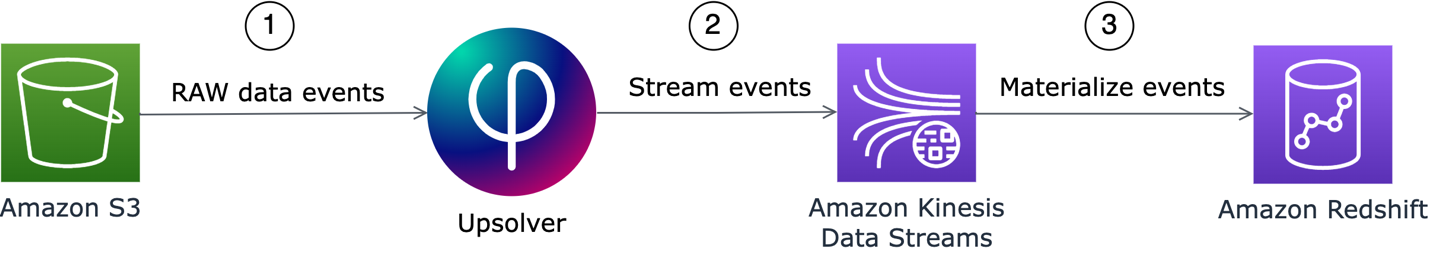
To implement this resolution, you full the next high-level steps:
- Configure the supply Kinesis information stream.
- Execute the info pipeline.
- Create an Amazon Redshift exterior schema and materialized view.
Configure the supply Kinesis information stream
For the aim of this publish, you create an Amazon S3 information supply that incorporates pattern retail information in JSON format. Upsolver ingests this information as a stream; as new objects arrive, they’re routinely ingested and streamed to the vacation spot.
- On the Upsolver console, select Knowledge Sources within the navigation sidebar.
- Select New.
- Select Amazon S3 as your information supply.
- For Bucket, you should use the bucket with the general public dataset or a bucket with your individual information.
- Select Proceed to create the info supply.

- Create an information stream in Kinesis Knowledge Streams, as proven within the following screenshot.
That is the output stream Upsolver makes use of to jot down occasions which are consumed by Amazon Redshift.
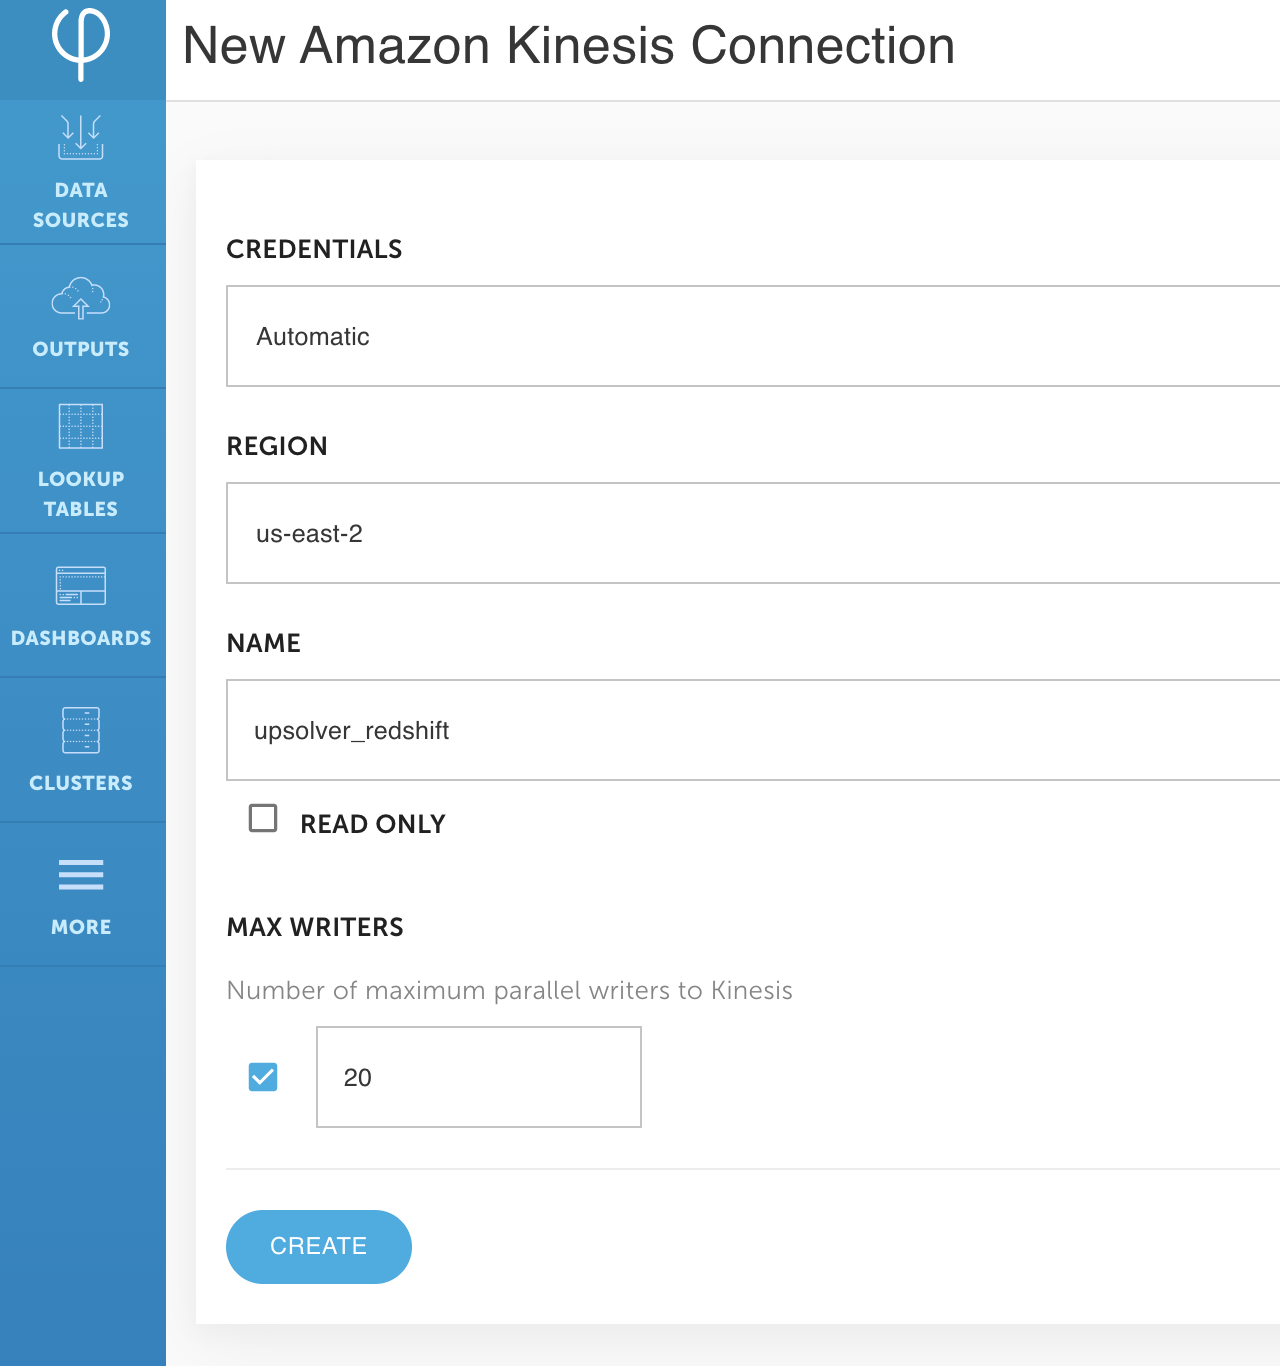
Subsequent, you create a Kinesis connection in Upsolver. Making a connection allows you to outline the authentication technique Upsolver makes use of—for instance, an AWS Identification and Entry Administration (IAM) entry key and secret key or an IAM position.
- On the Upsolver console, select Extra within the navigation sidebar.
- Select Connections.
- Select New Connection.
- Select Amazon Kinesis.
- For Area, enter your AWS Area.
- For Identify, enter a reputation on your connection (for this publish, we title it
upsolver_redshift). - Select Create.
Earlier than you may eat the occasions in Amazon Redshift, you could write them to the output Kinesis information stream.
- On the Upsolver console, navigate to Outputs and select Kinesis.
- For Knowledge Sources, select the Kinesis information supply you created within the earlier step.
- Relying on the construction of your occasion information, you have got two selections:
- If the occasion information you’re writing to the output doesn’t comprise any nested fields, choose Tabular. Upsolver routinely flattens nested information for you.
- To put in writing your information in a nested format, choose Hierarchical.
- As a result of we’re working with Kinesis Knowledge Streams, choose Hierarchical.

Execute the info pipeline
Now that the stream is linked from the supply to an output, you could choose which fields of the supply occasion you want to move via. You may as well select to use transformations to your information—for instance, including right timestamps, masking delicate values, and including computed fields. For extra data, seek advice from Fast information: SQL information transformation.
After including the columns you wish to embrace within the output and making use of transformations, select Run to begin the info pipeline. As new occasions arrive within the supply, Upsolver routinely transforms them and forwards the outcomes to the output stream. There isn’t any have to schedule or orchestrate the pipeline; it’s at all times on.

Create an Amazon Redshift exterior schema and materialized view
First, create an IAM position with the suitable permissions (for extra data, seek advice from Streaming ingestion). Now you should use the Amazon Redshift question editor, AWS Command Line Interface (AWS CLI), or API to run the next SQL statements.
- Create an exterior schema that’s backed by Kinesis Knowledge Streams. The next command requires you to incorporate the IAM position you created earlier:
- Create a materialized view that means that you can run a SELECT assertion towards the occasion information that Upsolver produces:
- Instruct Amazon Redshift to materialize the outcomes to a desk known as
mv_orders: - Now you can run queries towards your streaming information, reminiscent of the next:

Use Upsolver to jot down information to a knowledge lake and question it with Amazon Redshift Serverless
The next diagram represents the structure to jot down occasions to your information lake and question the info with Amazon Redshift.
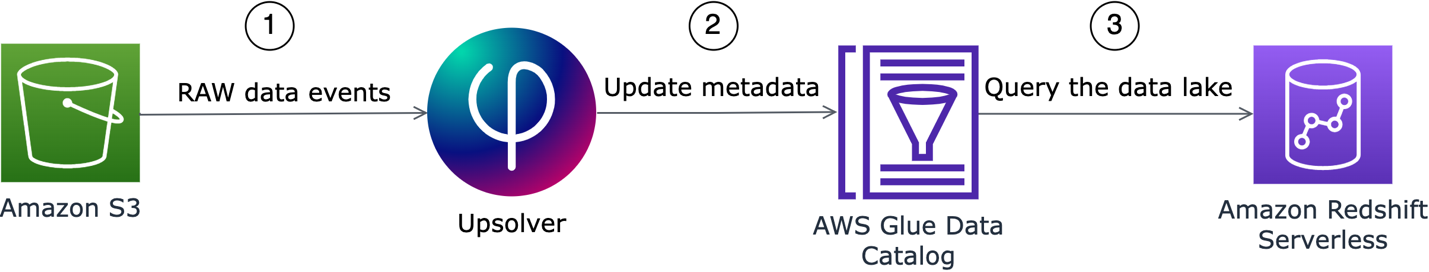
To implement this resolution, you full the next high-level steps:
- Configure the supply Kinesis information stream.
- Hook up with the AWS Glue Knowledge Catalog and replace the metadata.
- Question the info lake.
Configure the supply Kinesis information stream
We already accomplished this step earlier within the publish, so that you don’t have to do something totally different.
Hook up with the AWS Glue Knowledge Catalog and replace the metadata
To replace the metadata, full the next steps:
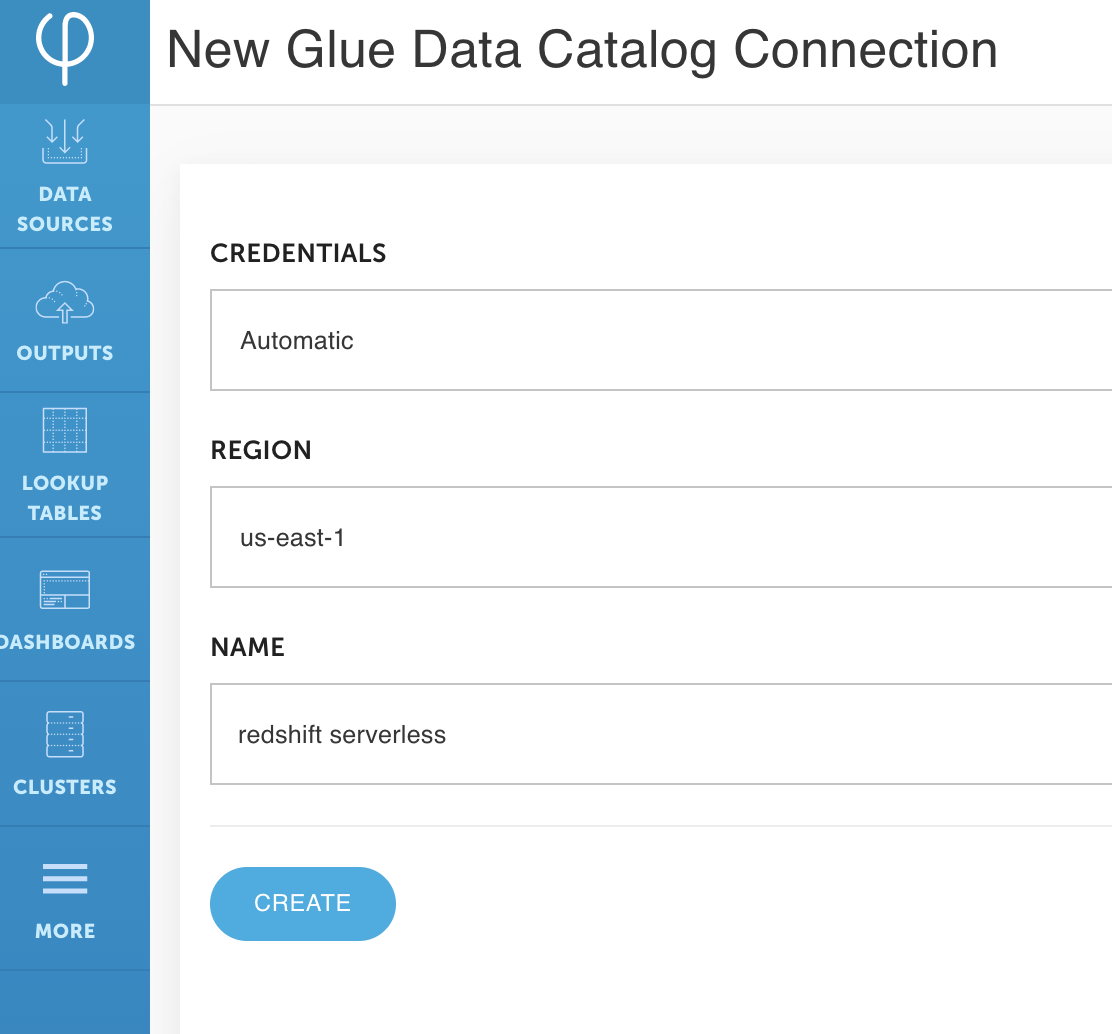
- On the Upsolver console, select Extra within the navigation sidebar.
- Select Connections.
- Select the AWS Glue Knowledge Catalog connection.
- For Area, enter your Area.
- For Identify, enter a reputation (for this publish, we name it
redshift serverless). - Select Create.
- Create a Redshift Spectrum output, following the identical steps from earlier on this publish.
- Choose Tabular as we’re writing output in table-formatted information to Amazon Redshift.

- Map the info supply fields to the Redshift Spectrum output.
- Select Run.

- On the Amazon Redshift console, create an Amazon Redshift Serverless endpoint.
- Ensure you affiliate your Upsolver position to Amazon Redshift Serverless.
- When the endpoint launches, open the brand new Amazon Redshift question editor to create an exterior schema that factors to the AWS Glue Knowledge Catalog (see the next screenshot).
This allows you to run queries towards information saved in your information lake.

Question the info lake
Now that your Upsolver information is being routinely written and maintained in your information lake, you may question it utilizing your most popular instrument and the Amazon Redshift question editor, as proven within the following screenshot.

Conclusion
On this publish, you discovered easy methods to use Upsolver to stream occasion information into Amazon Redshift utilizing streaming ingestion for Kinesis Knowledge Streams. You additionally discovered how you should use Upsolver to jot down the stream to your information lake and question it utilizing Amazon Redshift Serverless.
Upsolver makes it simple to construct information pipelines utilizing SQL and automates the complexity of pipeline administration, scaling, and upkeep. Upsolver and Amazon Redshift allow you to shortly and simply analyze information in actual time.
You probably have any questions, or want to focus on this integration or discover different use instances, begin the dialog in our Upsolver Group Slack channel.
In regards to the Authors
 Roy Hasson is the Head of Product at Upsolver. He works with prospects globally to simplify how they construct, handle and deploy information pipelines to ship prime quality information as a product. Beforehand, Roy was a Product Supervisor for AWS Glue and AWS Lake Formation.
 Mei Lengthy is a Product Supervisor at Upsolver. She is on a mission to make information accessible, usable and manageable within the cloud. Beforehand, Mei performed an instrumental position working with the groups that contributed to the Apache Hadoop, Spark, Zeppelin, Kafka, and Kubernetes initiatives.
 Maneesh Sharma is a Senior Database Engineer at AWS with greater than a decade of expertise designing and implementing large-scale information warehouse and analytics options. He collaborates with varied Amazon Redshift Companions and prospects to drive higher integration.
[ad_2]

