



[ad_1]
Proteins are important molecules present in all dwelling issues. They play a central function in our our bodies’ construction and performance, and they’re additionally featured in lots of merchandise that we encounter on daily basis, from medicines to home items like laundry detergent. Every protein is a series of amino acid constructing blocks, and simply as a picture might embrace a number of objects, like a canine and a cat, a protein might also have a number of parts, that are known as protein domains. Understanding the connection between a protein’s amino acid sequence — for instance, its domains — and its construction or perform are long-standing challenges with far-reaching scientific implications.
| An instance of a protein with identified construction, TrpCF from E. coli, for which areas utilized by a mannequin to foretell perform are highlighted (inexperienced). This protein produces tryptophan, which is a necessary a part of an individual’s weight loss program. |
Many are acquainted with latest advances in computationally predicting protein construction from amino acid sequences, as seen with DeepMind’s AlphaFold. Equally, the scientific group has an extended historical past of utilizing computational instruments to deduce protein perform instantly from sequences. For instance, the widely-used protein household database Pfam accommodates quite a few highly-detailed computational annotations that describe a protein area’s perform, e.g., the globin and trypsin households. Whereas current approaches have been profitable at predicting the perform of lots of of tens of millions of proteins, there are nonetheless many extra with unknown capabilities — for instance, a minimum of one-third of microbial proteins should not reliably annotated. As the amount and variety of protein sequences in public databases proceed to extend quickly, the problem of precisely predicting perform for extremely divergent sequences turns into more and more urgent.
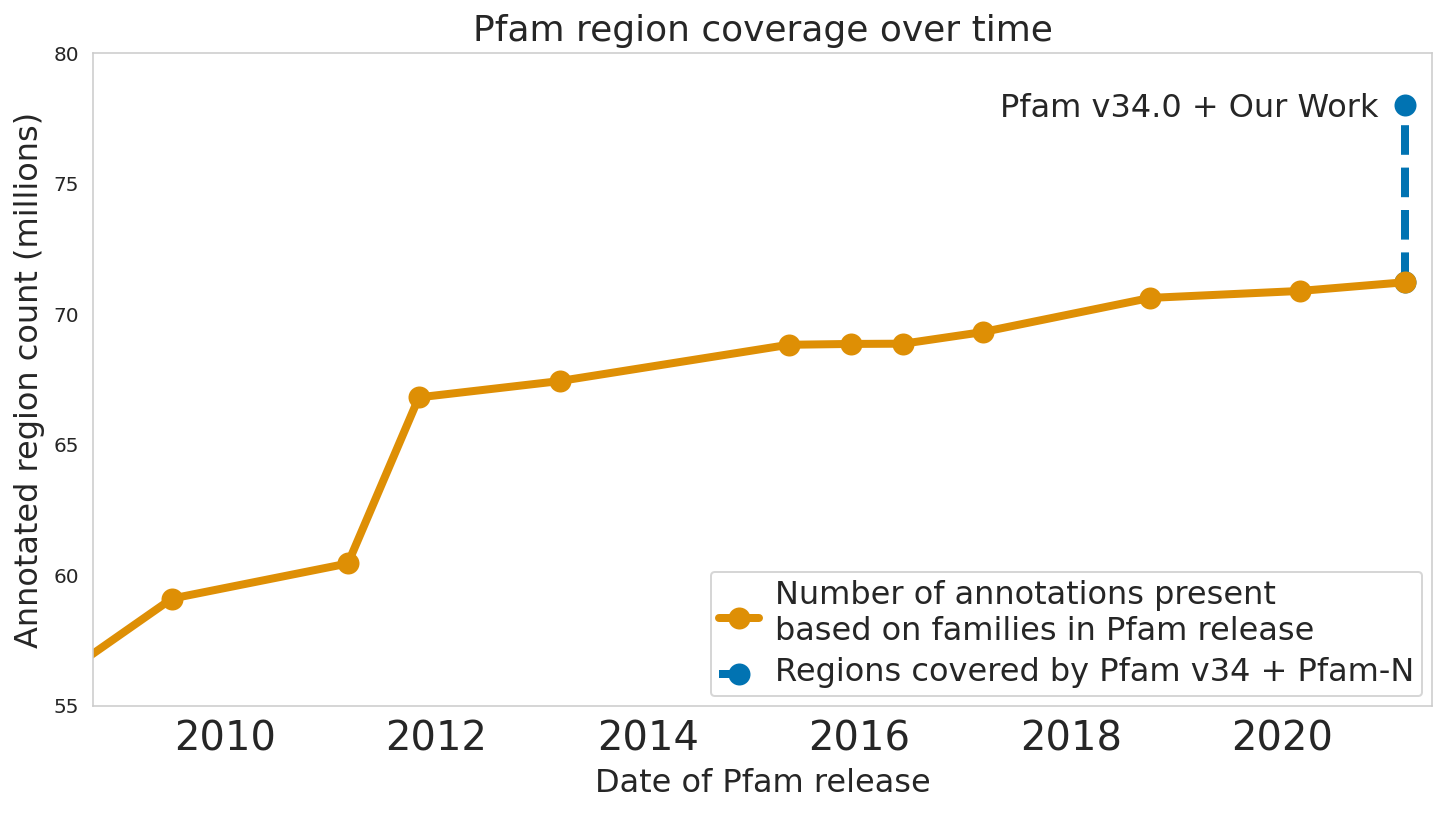
In “Utilizing Deep Studying to Annotate the Protein Universe”, printed in Nature Biotechnology, we describe a machine studying (ML) method to reliably predict the perform of proteins. This strategy, which we name ProtENN, has enabled us so as to add about 6.8 million entries to Pfam’s well-known and trusted set of protein perform annotations, about equal to the sum of progress over the past decade, which we’re releasing as Pfam-N. To encourage additional analysis on this route, we’re releasing the ProtENN mannequin and a distill-like interactive article the place researchers can experiment with our strategies. This interactive software permits the person to enter a sequence and get outcomes for a predicted protein perform in actual time, within the browser, with no setup required. On this put up, we’ll give an outline of this achievement and the way we’re making progress towards revealing extra of the protein universe.
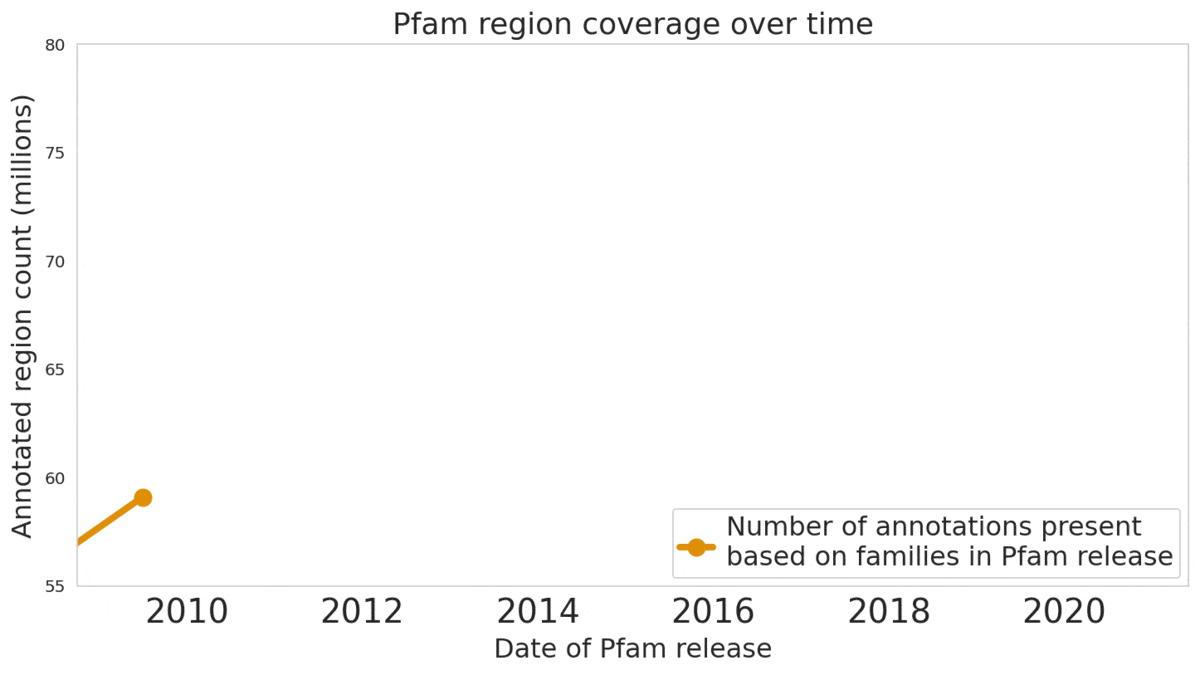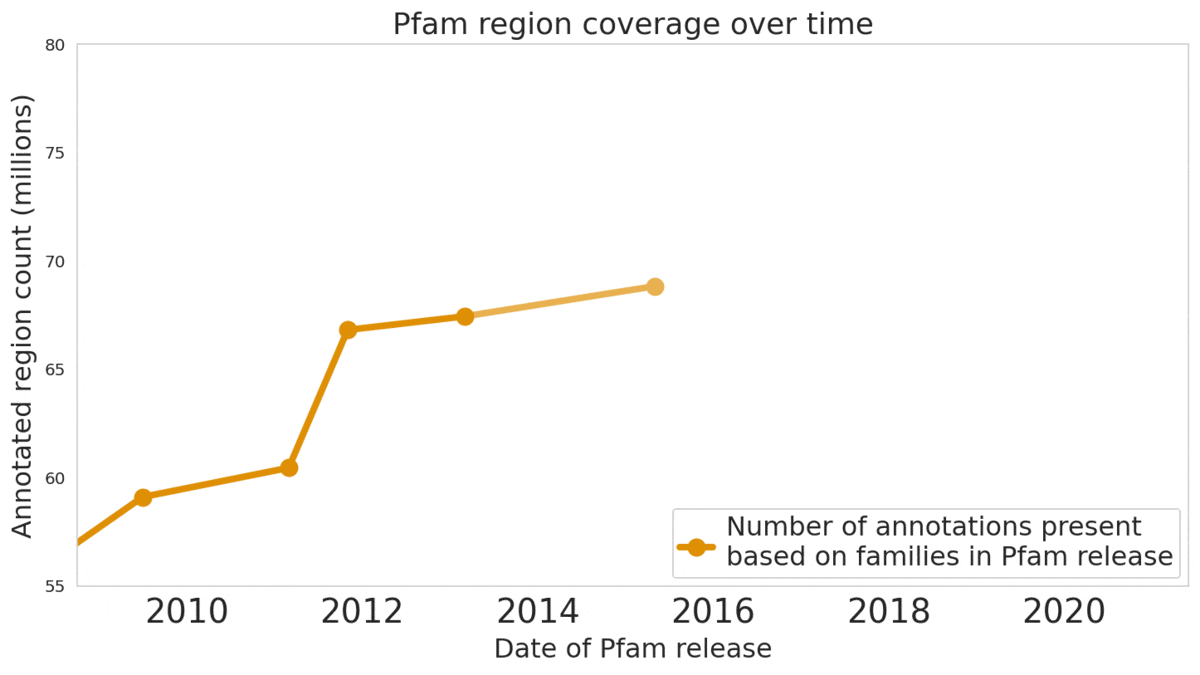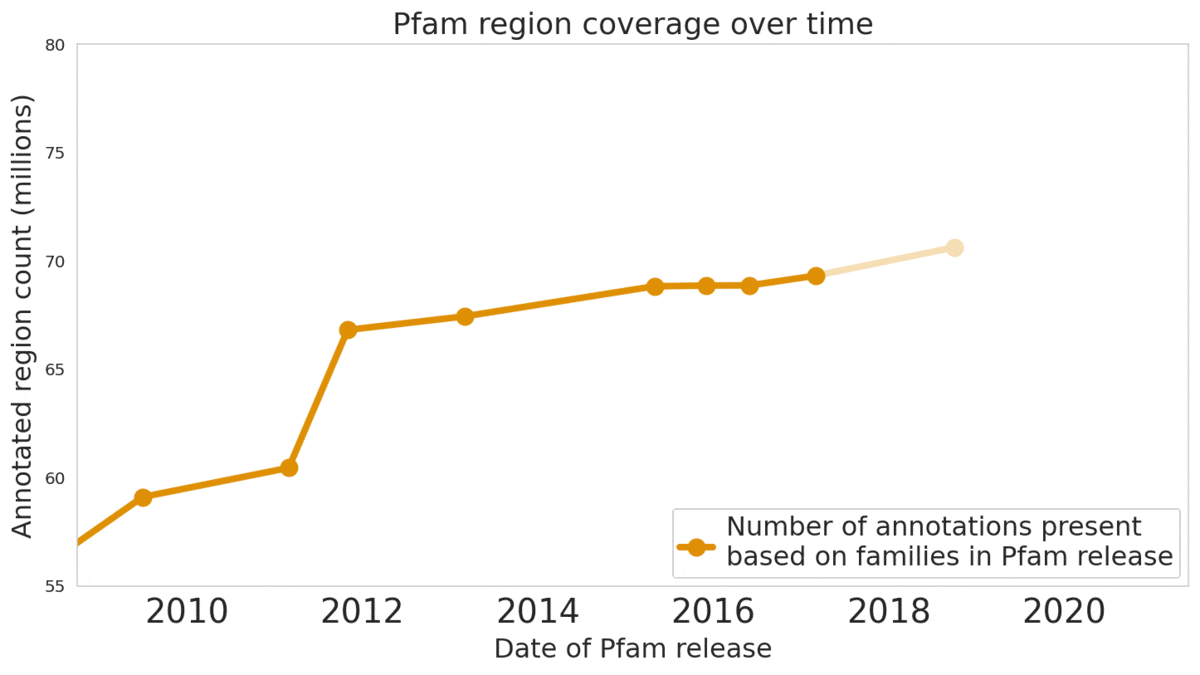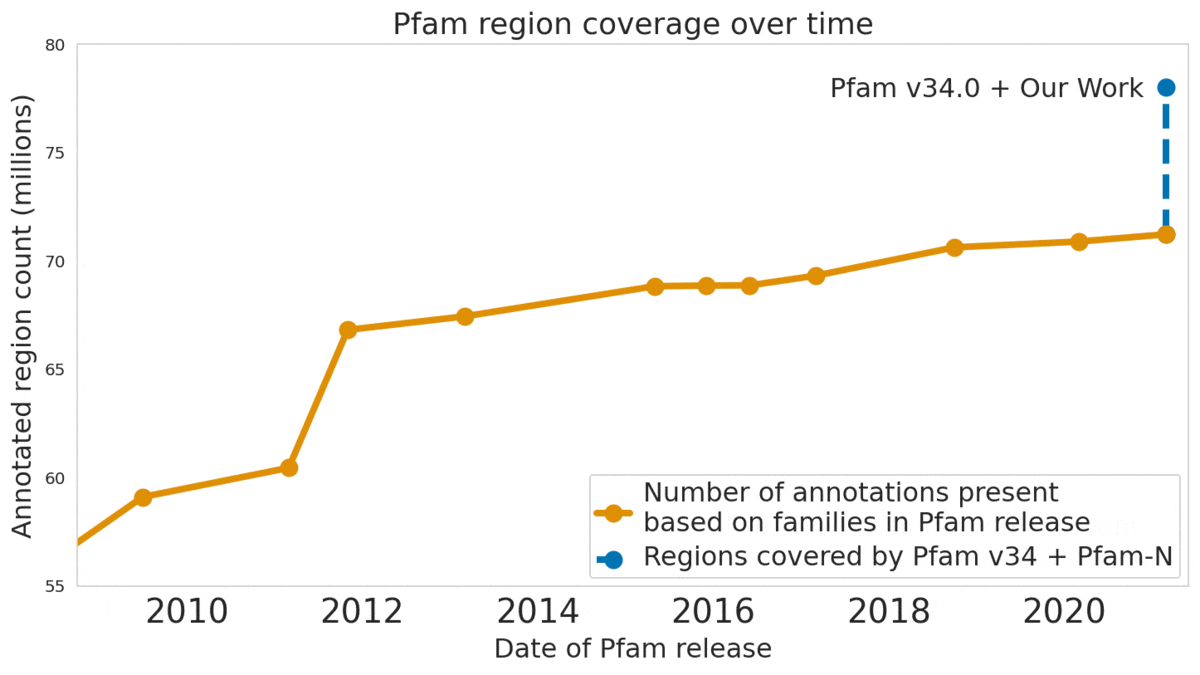 |
| The Pfam database is a big assortment of protein households and their sequences. Our ML mannequin ProtENN helped annotate 6.8 million extra protein areas within the database. |
Protein Perform Prediction as a Classification Drawback
In laptop imaginative and prescient, it’s frequent to first practice a mannequin for picture classification duties, like CIFAR-100, earlier than extending it to extra specialised duties, like object detection and localization. Equally, we develop a protein area classification mannequin as a primary step in direction of future fashions for classification of complete protein sequences. We body the issue as a multi-class classification activity wherein we predict a single label out of 17,929 courses — all courses contained within the Pfam database — given a protein area’s sequence of amino acids.
Fashions that Hyperlink Sequence to Perform
Whereas there are a variety of fashions at present obtainable for protein area classification, one disadvantage of the present state-of-the-art strategies is that they’re primarily based on the alignment of linear sequences and don’t think about interactions between amino acids in several components of protein sequences. However proteins don’t simply keep as a line of amino acids, they fold in on themselves such that nonadjacent amino acids have robust results on one another.
Aligning a brand new question sequence to a number of sequences with identified perform is a key step of present state-of-the-art strategies. This reliance on sequences with identified perform makes it difficult to foretell a brand new sequence’s perform whether it is extremely dissimilar to any sequence with identified perform. Moreover, alignment-based strategies are computationally intensive, and making use of them to massive datasets, such because the metagenomic database MGnify, which accommodates >1 billion protein sequences, could be value prohibitive.
To deal with these challenges, we suggest to make use of dilated convolutional neural networks (CNNs), which must be well-suited to modeling non-local pairwise amino-acid interactions and could be run on trendy ML {hardware} like GPUs. We practice 1-dimensional CNNs to foretell the classification of protein sequences, which we name ProtCNN, in addition to an ensemble of independently skilled ProtCNN fashions, which we name ProtENN. Our purpose for utilizing this strategy is so as to add data to the scientific literature by creating a dependable ML strategy that enhances conventional alignment-based strategies. To show this, we developed a way to precisely measure our technique’s accuracy.
Analysis with Evolution in Thoughts
Just like well-known classification issues in different fields, the problem in protein perform prediction is much less in creating a totally new mannequin for the duty, and extra in creating truthful coaching and check units to make sure that the fashions will make correct predictions for unseen knowledge. As a result of proteins have developed from shared frequent ancestors, totally different proteins typically share a considerable fraction of their amino acid sequence. With out correct care, the check set might be dominated by samples which might be extremely just like the coaching knowledge, which might result in the fashions performing effectively by merely “memorizing” the coaching knowledge, somewhat than studying to generalize extra broadly from it.
| We create a check set that requires ProtENN to generalize effectively on knowledge removed from its coaching set. |
To protect in opposition to this, it’s important to guage mannequin efficiency utilizing a number of separate setups. For every analysis, we stratify mannequin accuracy as a perform of similarity between every held-out check sequence and the closest sequence within the practice set.
The primary analysis features a clustered cut up coaching and check set, in keeping with prior literature. Right here, protein sequence samples are clustered by sequence similarity, and full clusters are positioned into both the practice or check units. Consequently, each check instance is a minimum of 75% totally different from each coaching instance. Robust efficiency on this activity demonstrates {that a} mannequin can generalize to make correct predictions for out-of-distribution knowledge.
For the second analysis, we use a randomly cut up coaching and check set, the place we stratify examples primarily based on an estimate of how troublesome they are going to be to categorise. These measures of problem embrace: (1) the similarity between a check instance and the closest coaching instance, and (2) the variety of coaching examples from the true class (it’s rather more troublesome to precisely predict perform given only a handful of coaching examples).
To put our work in context, we consider the efficiency of probably the most broadly used baseline fashions and analysis setups, with the next baseline fashions specifically: (1) BLAST, a nearest-neighbor technique that makes use of sequence alignment to measure distance and infer perform, and (2) profile hidden Markov fashions (TPHMM and phmmer). For every of those, we embrace the stratification of mannequin efficiency primarily based on sequence alignment similarity talked about above. We in contrast these baselines in opposition to ProtCNN and the ensemble of CNNs, ProtENN.
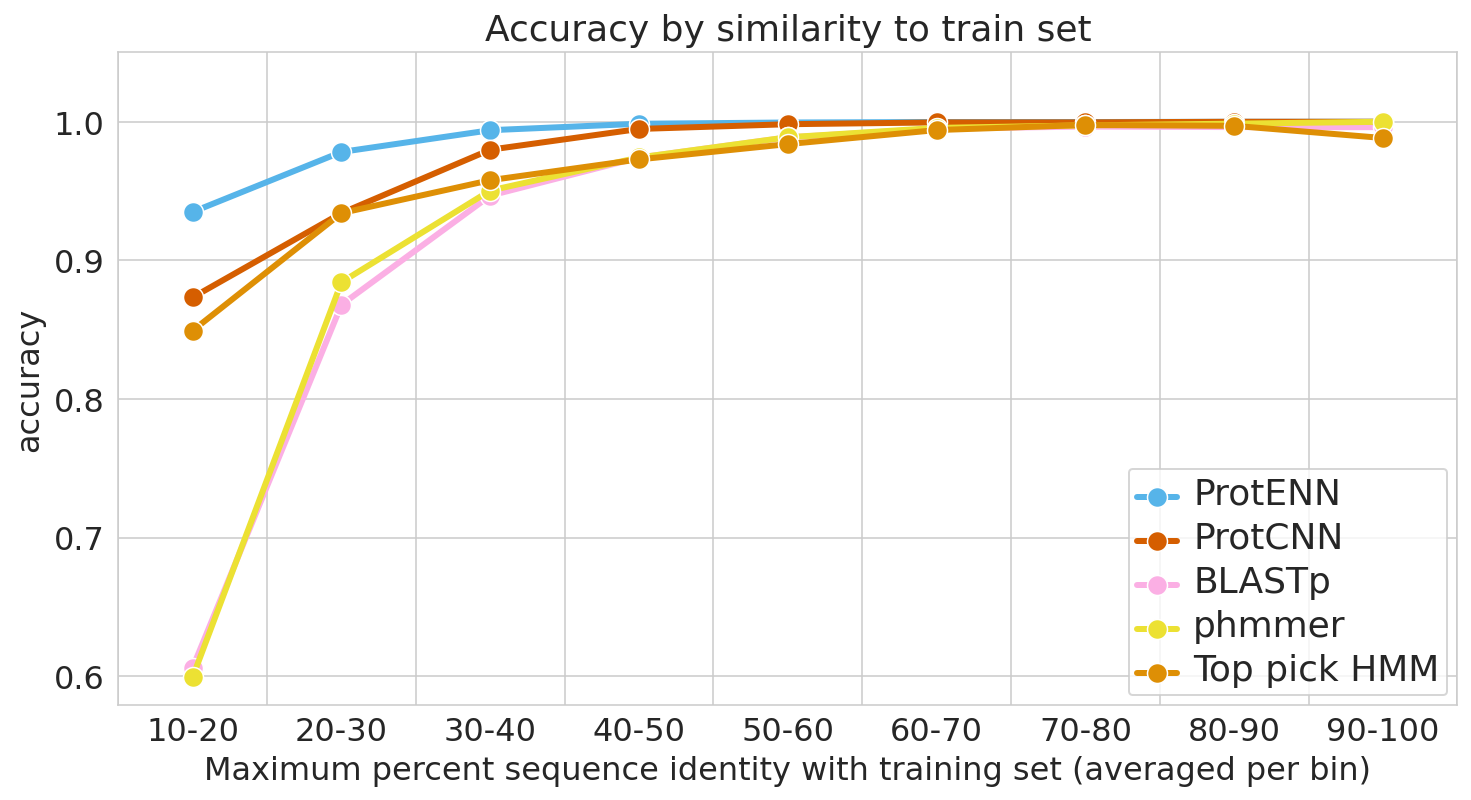 |
| We measure every mannequin’s capability to generalize, from the toughest examples (left) to the best (proper). |
Reproducible and Interpretable Outcomes
We additionally labored with the Pfam workforce to check whether or not our methodological proof of idea might be used to label real-world sequences. We demonstrated that ProtENN learns complementary data to alignment-based strategies, and created an ensemble of the 2 approaches to label extra sequences than both technique might by itself. We publicly launched the outcomes of this effort, Pfam-N, a set of 6.8 million new protein sequence annotations.
After seeing the success of those strategies and classification duties, we inspected these networks to know whether or not the embeddings had been usually helpful. We constructed a software that allows customers to discover the relation between the mannequin predictions, embeddings, and enter sequences, which we have now made obtainable by way of our interactive manuscript, and we discovered that comparable sequences had been clustered collectively in embedding area. Moreover, the community structure that we chosen, a dilated CNN, permits us to make use of previously-discovered interpretability strategies like class activation mapping (CAM) and ample enter subsets (SIS) to establish the sub-sequences accountable for the neural community predictions. With this strategy, we discover that our community usually focuses on the related parts of a sequence to foretell its perform.
Conclusion and Future Work
We’re excited concerning the progress we’ve seen by making use of ML to the understanding of protein construction and performance over the previous few years, which has been mirrored in contributions from the broader analysis group, from AlphaFold and CAFA to the multitude of workshops and analysis shows dedicated to this matter at conferences. As we glance to construct on this work, we predict that persevering with to collaborate with scientists throughout the sector who’ve shared their experience and knowledge, mixed with advances in ML will assist us additional reveal the protein universe.
Acknowledgments
We’d prefer to thank all the co-authors of the manuscripts, Maysam Moussalem, Jamie Smith, Eli Bixby, Babak Alipanahi, Shanqing Cai, Cory McLean, Abhinay Ramparasad, Steven Kearnes, Zack Nado, and Tom Small.
[ad_2]

