



[ad_1]
Why suggestion methods are essential
On-line procuring has develop into the default expertise for the typical client – even established brick-and-mortar retailers have embraced e-commerce. To make sure a clean person expertise, a number of elements have to be thought of for e-commerce. One core performance that has confirmed to enhance the person expertise and, consequently income for on-line retailers, is a product suggestion system. This present day, it will be practically not possible to go to an internet site for consumers and never see product suggestions.
However not all recommenders are created equal, nor ought to they be. Totally different procuring experiences require completely different information to make suggestions. Participating the patron with a personalised expertise requires a number of modalities of information and suggestion strategies. Most recommenders concern themselves with coaching machine studying fashions on person and product attribute information massaged to a tabular kind.
There was an exponential enhance within the quantity and number of information at our disposal to construct recommenders and notable advances in compute and algorithms to make the most of within the course of. Notably, the means to retailer, course of and be taught from picture information has dramatically elevated prior to now a number of years. This enables retailers to transcend easy collaborative filtering algorithms and make the most of extra advanced strategies, equivalent to picture classification and deep convolutional neural networks, that may have in mind the visible similarity of things as an enter for making suggestions. That is particularly essential given on-line procuring is a largely visible expertise and plenty of client items are judged on aesthetics.
On this article, we’ll change the script and present the end-to-end course of for coaching and deploying an image-based similarity mannequin that may function the inspiration for a recommender system. Moreover, we’ll present how the underlying distributed compute out there in Databricks will help scale the coaching course of and the way foundational elements of the Lakehouse, Delta Lake and MLflow, could make this course of easy and reproducible.
Why similarity studying?
Similarity fashions are educated utilizing contrastive studying. In contrastive studying, the purpose is to make the machine studying (ML) mannequin be taught an embedding area the place the space between related gadgets is minimized and the space between dissimilar gadgets is maximized. Right here, we’ll use the style MNIST dataset, which contains round 70,000 photographs of varied clothes gadgets. Based mostly on the above description, a similarity mannequin educated on this labeled dataset will be taught an embedding area the place embeddings of comparable merchandise (e.g., boots, are nearer collectively and completely different gadgets e.g., boots and pullovers) are far aside. In supervised contrastive studying, the algorithm has entry to metadata, equivalent to picture labels, to be taught from, along with the uncooked pixel information itself.
This could possibly be illustrated as follows.
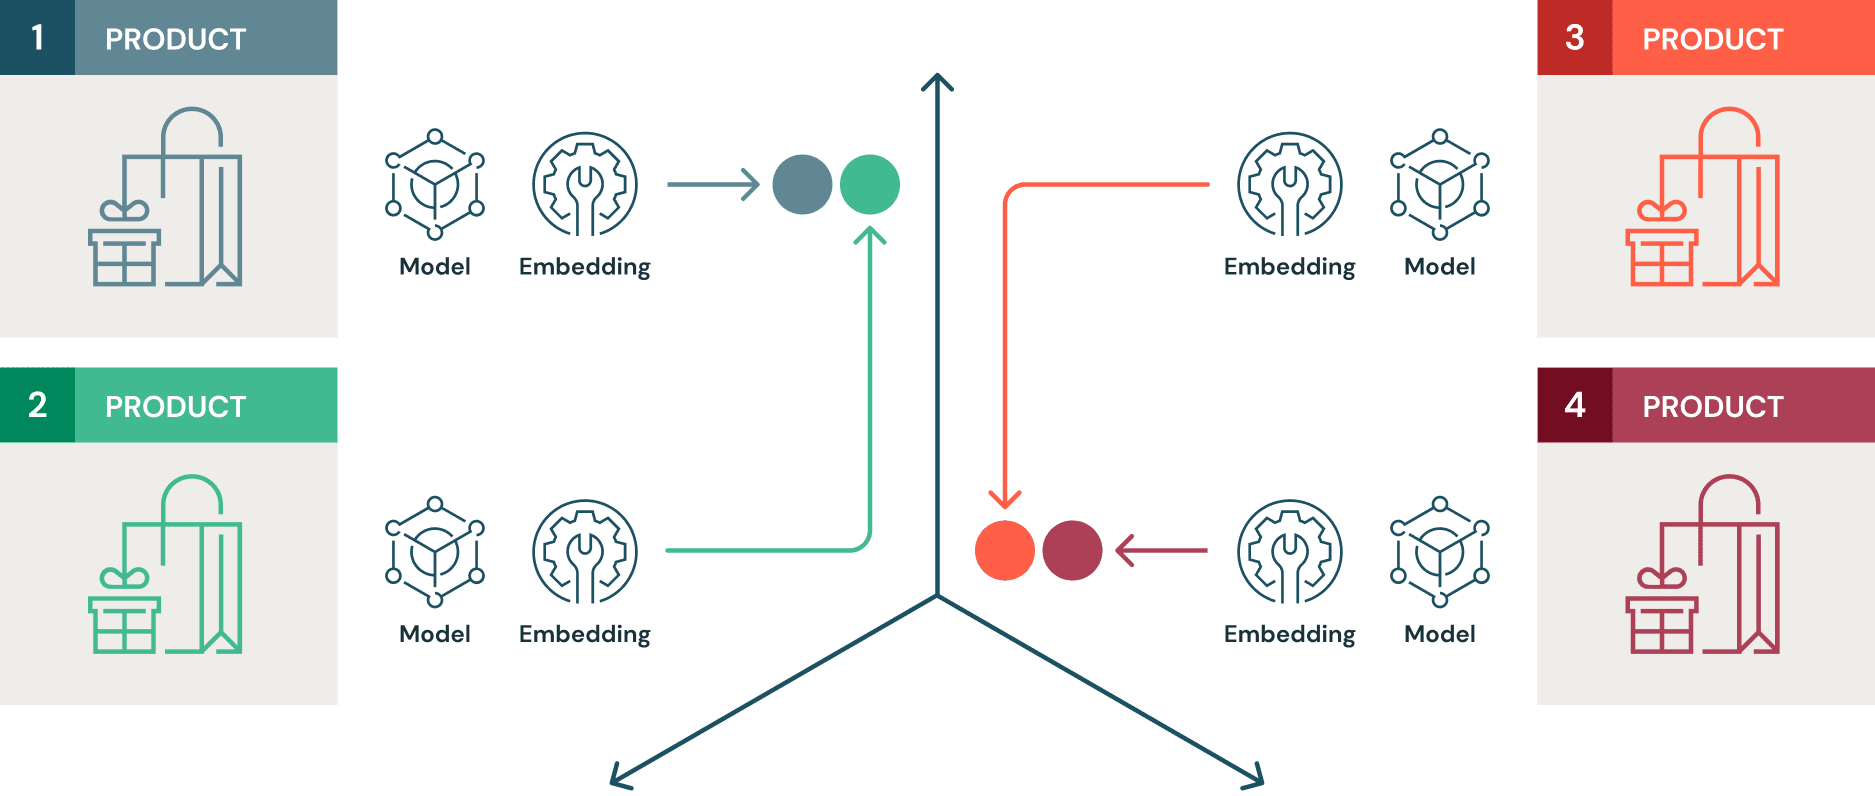
Conventional ML fashions for picture classification concentrate on decreasing a loss perform that’s geared in the direction of maximizing predicted class chances. Nonetheless, what a recommender system basically makes an attempt to do to counsel options to a given merchandise. This stuff could possibly be described as nearer to at least one one other in a sure embedding area than others. Thus, generally, the working precept of advice methods carefully align with that of contrastive studying mechanisms in comparison with conventional supervised studying. Moreover, similarity fashions are more proficient at generalizing to unseen information, primarily based on their similarities. For instance, if the unique coaching information doesn’t include any photographs of jackets however accommodates photographs of hoodies and boots, a similarity mannequin educated on this information would find the embeddings of the picture of a jacket nearer to hoodies and farther away from boots. That is very highly effective on the planet of advice strategies.
Particularly, we use the Tensorflow Similarity library to coach the mannequin and Apache Spark, mixed with Horovod to scale the mannequin coaching throughout a GPU cluster. We use Hyperopt to scale hyperparameter search throughout the GPU cluster with Spark in just a few traces of code. All these experiments will likely be tracked and logged with MLflow to protect mannequin lineage and reproducibility. Delta will likely be used as the information supply format to trace information lineage.
Organising the atmosphere
The supervised_hello_world instance within the Tensorflow Similarity Github repository offers an ideal template to make use of for the duty at hand. What we attempt to do with a recommender is much like the style through which a similarity mannequin behaves. That’s, you select a picture of an merchandise, and also you question the mannequin to return n of probably the most related gadgets that might additionally pique your curiosity.
To totally leverage the Databricks platform, it’s greatest to spin up a cluster with a GPU node for the motive force (since we will likely be doing a little single node coaching initially), two or extra GPU employee nodes (as we will likely be scaling hyperparameter optimization and distributing the coaching itself), and a Databricks Machine Studying runtime of 10.0 or above. T4 GPU cases are a sensible choice for this train.
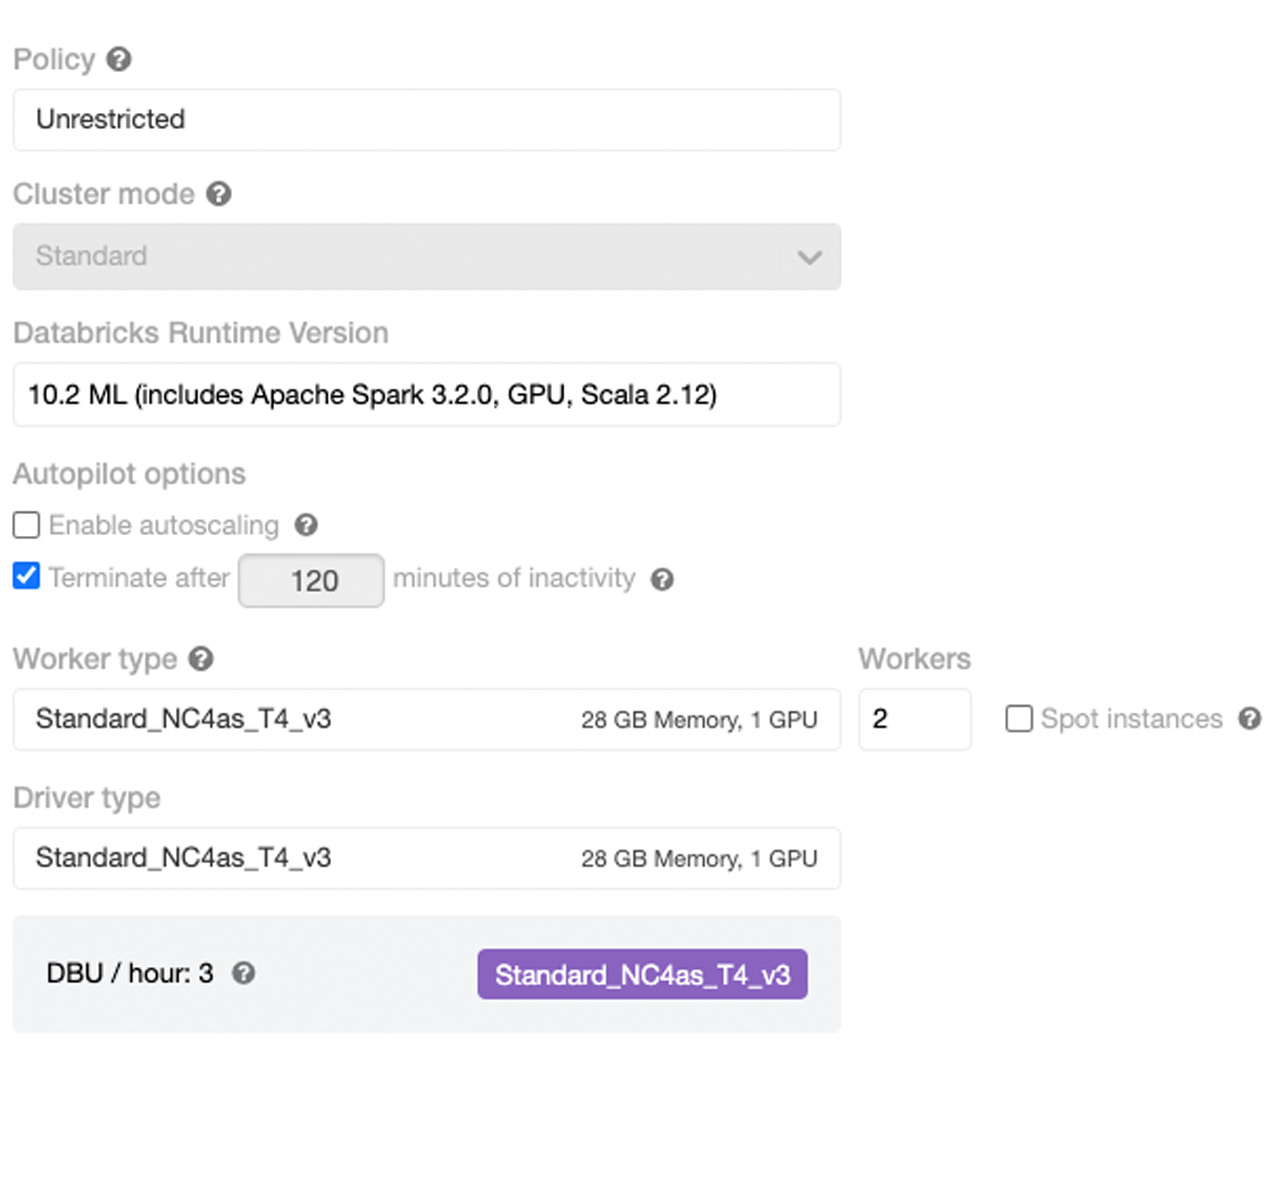
Your complete course of ought to take not more than 5 minutes (together with the cluster spin up time).
Ingest information into Delta tables
Vogue MNIST coaching and take a look at information could be imported to the environment utilizing a sequence of straightforward shell instructions and the helper perform `convert` (modified from the unique model at: ‘https://pjreddie.com/initiatives/mnist-in-csv/’ (to scale back pointless file I/O) can be utilized to transform the picture and label recordsdata right into a tabular format. Subsequently these tables could be saved as Delta tables.
Storing the coaching and take a look at information as Delta tables is essential as we incrementally write new observations (new photographs and their labels) to those tables, the Delta transaction log can hold monitor of the modifications to information. This allows us to trace the recent information we are able to use to re-index information within the similarity index we’ll describe later.
Nuances of coaching similarity fashions
A neural community used to coach a similarity mannequin is kind of much like one used for normal supervised studying. The first variations listed below are within the loss perform we use and the metric embedding layer. Right here we use a easy convolutional neural community (cnn) structure, which is usually seen in laptop imaginative and prescient purposes. Nonetheless, there are refined variations within the code that allow the mannequin to be taught utilizing contrastive strategies.
You will notice the multi similarity loss perform instead of the softmax loss perform for multiclass classification you’ll see in any other case. In comparison with different conventional loss features used for contrastive studying, Multi-Similarity Loss takes under consideration a number of similarities. These similarities are self similarity, constructive relative similarity, and adverse relative similarity. Multi-similarity Loss measures these three similarities via iterative onerous pair mining and weighting, bringing vital efficiency positive aspects in contrastive studying duties. Additional particulars of this particular loss is mentioned at size in the unique publication by Wang et al.
Within the context of this instance, this loss helps reduce the space between related gadgets and maximize distance between dissimilar gadgets within the embedding area. As defined within the supervised_hello_world instance in the Tensorflow_Similarity repository, the embedding layer added to the mannequin with the MetricEmbedding() is a dense layer with L2 normalization. For every minibatch, a hard and fast variety of embeddings (corresponding to pictures) are randomly chosen from randomly sampled lessons (the variety of lessons is a hyper parameter). These are then subjected to onerous pair mining and weighting iteratively within the Multi-Similarity Loss layer, the place info from three various kinds of similarities is used to penalize dissimilar samples in shut proximity extra.
This may be seen beneath.
``` def get_model(): from tensorflow_similarity.layers import MetricEmbedding from tensorflow.keras import layers from tensorflow_similarity.fashions import SimilarityModel inputs = layers.Enter(form=(28, 28, 1)) x = layers.experimental.preprocessing.Rescaling(1/255)(inputs) x = layers.Conv2D(32, 3, activation='relu')(x) x = layers.MaxPool2D(2, 2)(x) x = layers.Dropout(0.3)(x) … … x = layers.Dropout(0.3)(x) x = layers.Flatten()(x) outputs = MetricEmbedding(128)(x) return SimilarityModel(inputs, outputs) … … loss = MultiSimilarityLoss(distance=distance) mannequin.compile(optimizer=Adam(learning_rate), loss=loss) ```You will need to perceive how a educated similarity mannequin features in TensorFlow Similarity. Throughout coaching of the mannequin, we realized embeddings that reduce the space between related gadgets. The Indexer class of the library gives the aptitude to construct an index from these embeddings on the idea of the chosen distance metric. For instance, if the chosen distance metric is ‘cosine’, the index will likely be constructed on the idea of cosine similarity.
The index exists to shortly discover gadgets with ‘shut’ embeddings. For this search to be fast, probably the most related gadgets must be retrieved with comparatively low latency. The question methodology right here makes use of Quick Approximate Nearest Neighbor Search to retrieve the n nearest neighbors to a given merchandise, which we are able to then function suggestions.
``` #Construct an index utilizing coaching information x_index, y_index = select_examples(x_train, y_train, CLASSES, 20) tfsim_model.reset_index() tfsim_model.index(x_index, y_index, information=x_index) #Question the index utilizing the lookup methodology tfsim_model.lookup(x_display, ok=5) . . . ```Leveraging parallelism with Apache Spark
This mannequin could be educated in a single node with out a problem and we are able to construct an index to question it. Subsequently the educated mannequin could be deployed to be queried by way of a REST endpoint with the assistance of MLflow. This notably is smart, for the reason that style MNIST dataset used on this instance is small and suits in a single GPU enabled occasion’s reminiscence simply. Nonetheless, in apply, picture datasets of merchandise can span a number of gigabytes in measurement. Additionally, even for a mannequin educated on a small dataset, the method of discovering the optimum hyperparameters of the mannequin is usually a very time consuming course of if executed on a single GPU enabled occasion. In each circumstances, parallelism enabled by Spark can do wonders solely by altering a couple of traces of code.
Parallelizing hyperparameter optimization with Apache Spark
Within the case of a neural community, you might consider weights of the substitute neurons as parameters which might be up to date throughout coaching. That is carried out via gradient descent and backpropagation of error. Nonetheless, values such because the variety of layers, the variety of neurons per layer, and even the activation features in neurons aren’t optimized throughout this course of. These are termed hyperparameters, and we have now to look the area of all such attainable hyperparameter combos in a intelligent technique to proceed with the modeling course of.
Conventional mannequin tuning (a shorthand for hyperparameter search) could be executed with naive approaches equivalent to an exhaustive grid search or a random search. Hyperopt, a broadly adopted open-source framework for mannequin tuning, leverages much more environment friendly Bayesian seek for this course of.
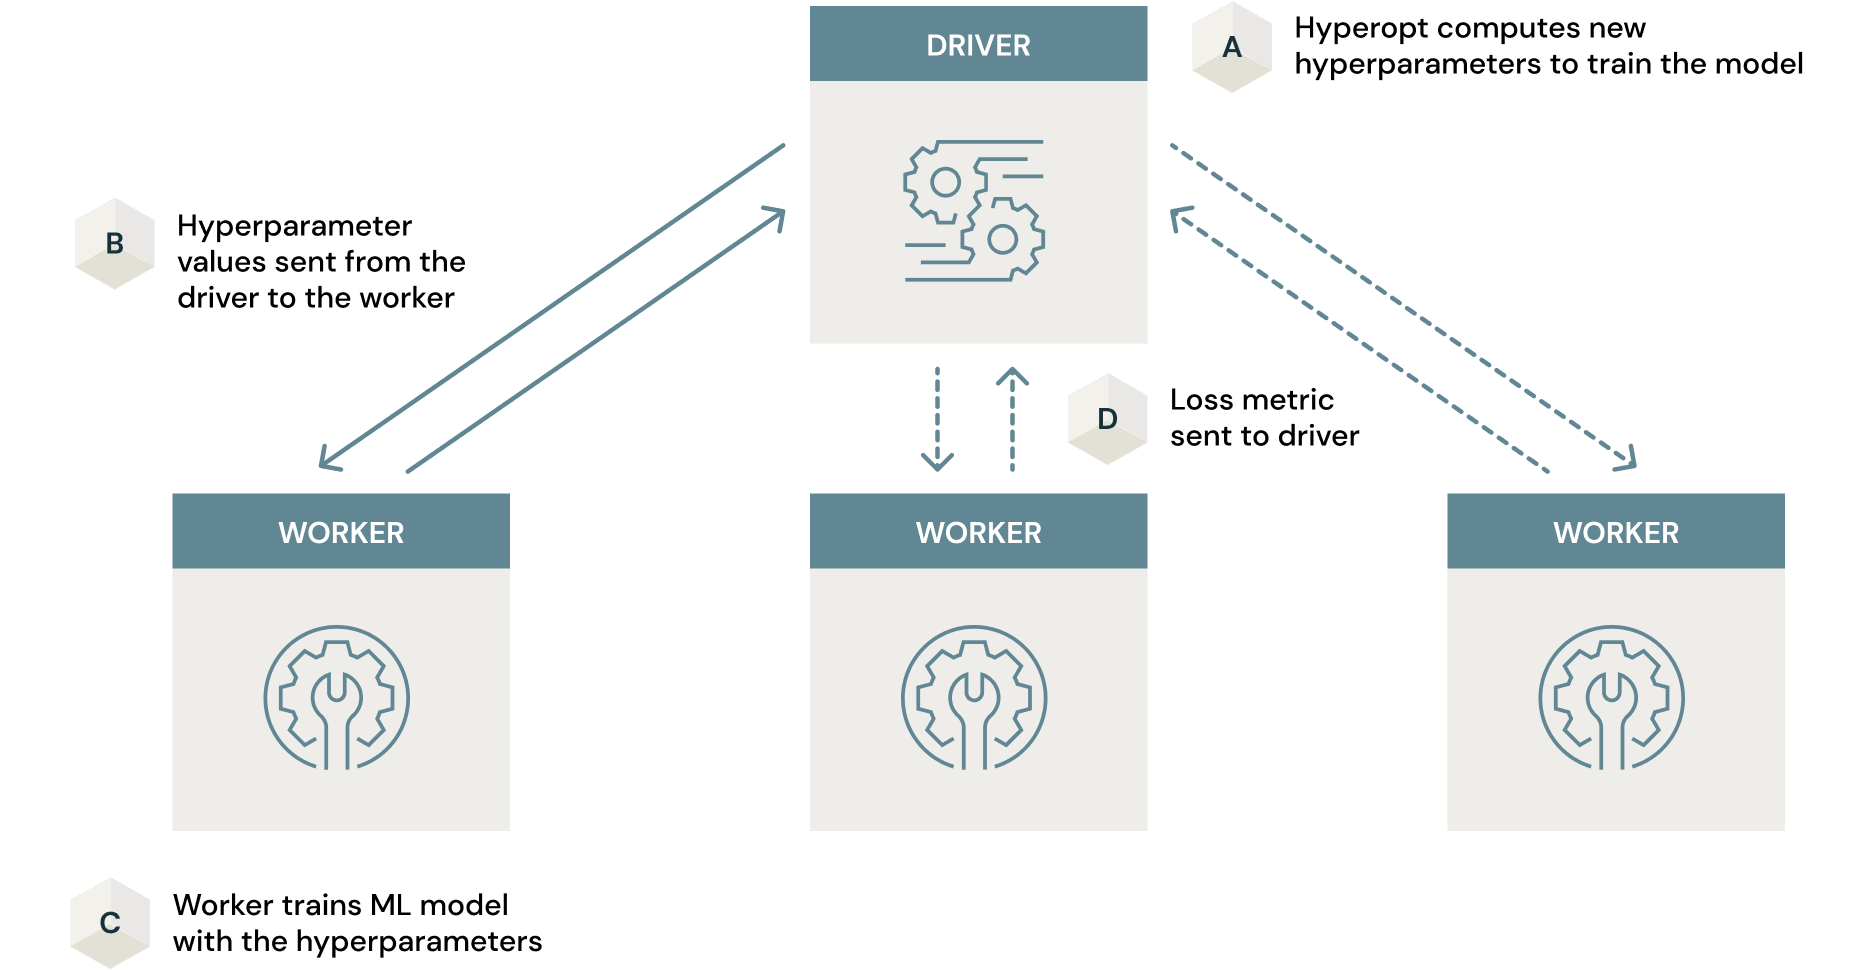
This search could be time consuming, even with clever algorithms equivalent to Bayesian search. Nonetheless, Spark can work along with Hyperopt to parallelize this course of throughout your complete cluster leading to a dramatic discount within the time consumed. All that must be executed to carry out this scaling is so as to add 2 traces of python code to what you’ll usually use with Hyepropt. Word how the parallelism argument is about to 2, (i.e. the variety of cluster GPUs).
``` . . from hyperopt import SparkTrials . . trials = SparkTrials(parallelism = 2) . . best_params = fmin( fn=train_hyperopt, area=area, algo=algo, max_evals=32, trials = trials ) . . ```The mechanism through which this parallelism works could be illustrated as follows.
The article Scaling Hyperopt to Tune Machine Studying Fashions in Python offers a wonderful deep dive on how this works. You will need to use GPU enabled nodes for this course of within the case of similarity fashions, notably on this instance leveraging Tensorflow. Any time financial savings could possibly be negated by unnecessarily lengthy and inefficient coaching processes leveraging CPU nodes. An in depth evaluation of that is supplied on this article.
Parallelizing mannequin coaching with Horovod
As we noticed within the earlier part, Hyperopt leverages Spark to distribute hyperparameter search by coaching a number of fashions with completely different hyperparameter combos, in parallel. The coaching of every mannequin takes place in a single machine. Distributed mannequin coaching is yet one more approach through which distributed processing with Spark could make the coaching course of extra environment friendly. Right here, a single mannequin is educated throughout many machines within the cluster.
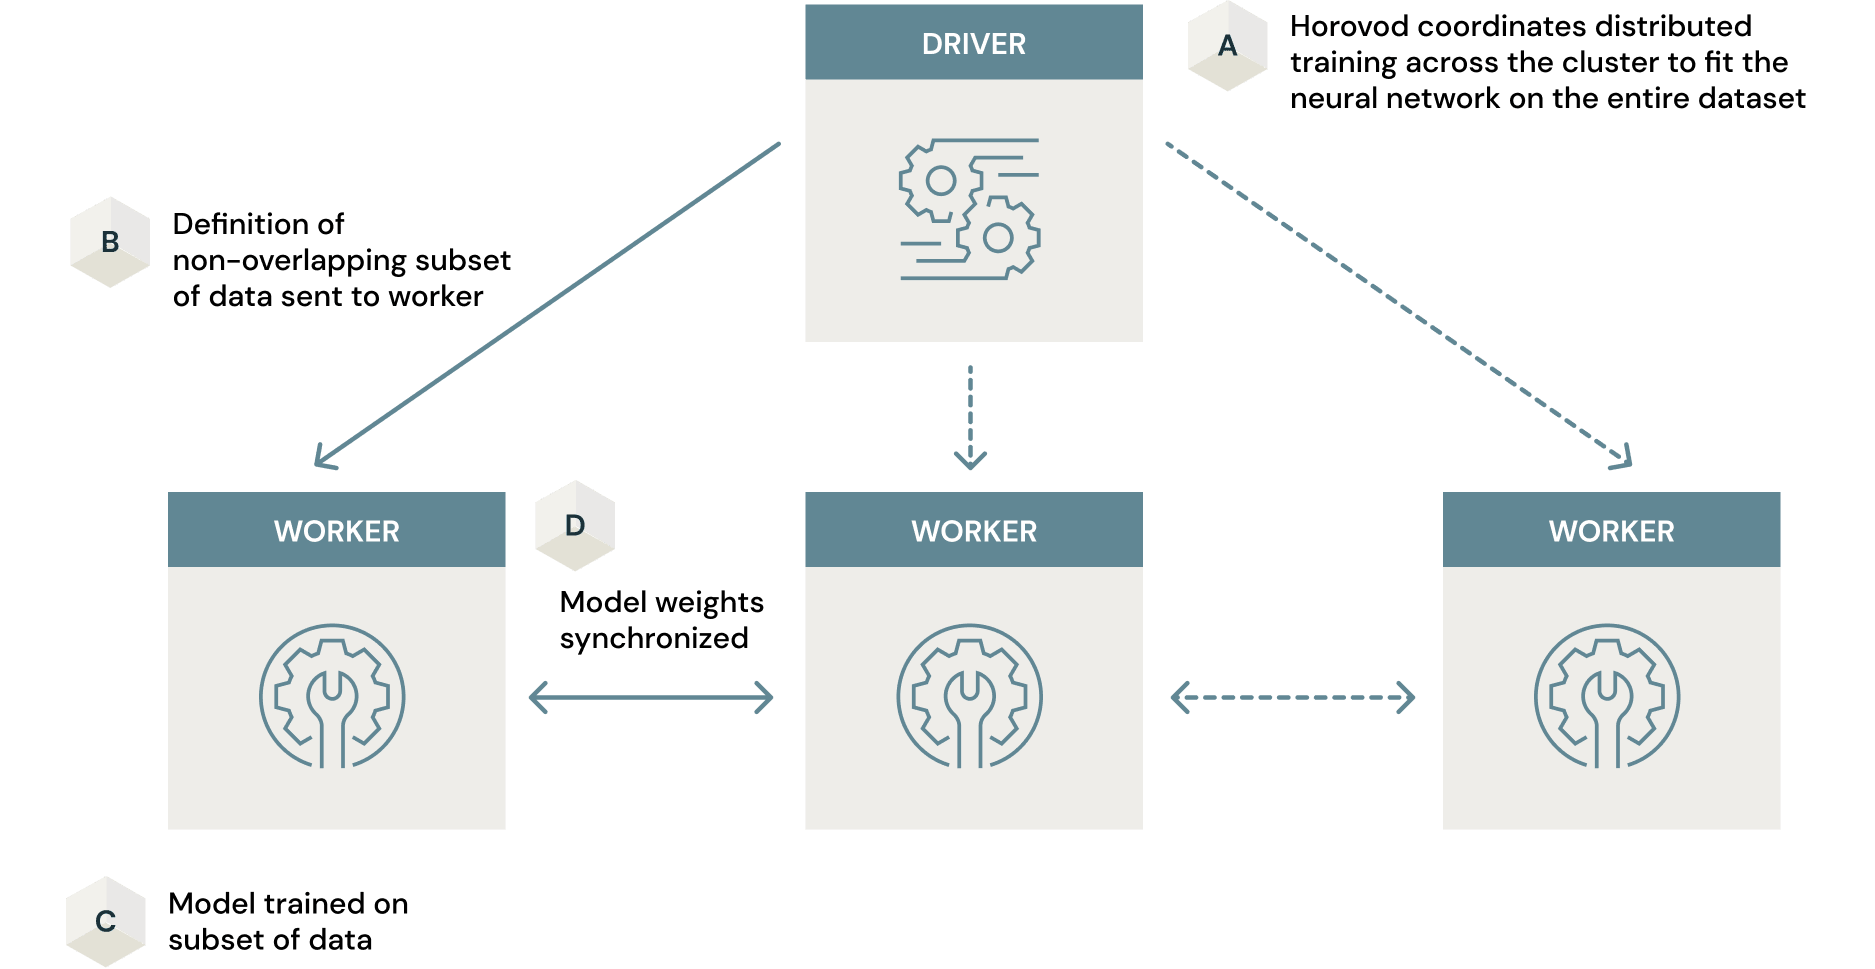
If the coaching dataset is massive, it could possibly be yet one more bottleneck for coaching a manufacturing prepared similarity mannequin. Some approaches to this embody coaching the mannequin solely on a subset of the information on a single machine. This comes at the price of the ultimate mannequin being sub-optimal. Nonetheless, with Spark and Horovod, an open-source framework for parallelizing the mannequin coaching course of throughout a cluster, this drawback could be solved. Horovod, along with Spark, gives a data-parallel strategy to mannequin coaching on large-scale datasets with minimal code modifications. Right here, fashions are educated in parallel in every node within the cluster as soon as definitions of subsets of information are handed, to be taught weights of the neural community. These weights are synchronized throughout the cluster ensuing within the ultimate mannequin. Finally, you find yourself with a extremely optimized mannequin educated on your complete dataset inside a fraction of the time you’ll spend on trying to do that on a single machine. The article How (Not) To Scale Deep Studying in 6 Straightforward Steps goes into nice element on tips on how to leverage distributed compute for deep studying. Once more, Horovod is best when used on a GPU cluster. In any other case some great benefits of scaling mannequin coaching throughout a cluster wouldn’t convey the specified efficiencies.
Dealing with massive picture datasets for mannequin coaching is one other essential issue to think about. On this instance, style MNIST is a really small dataset that doesn’t pressure the cluster in any respect. Nonetheless, massive picture datasets are sometimes seen within the enterprise and a use case might contain coaching a similarity mannequin on such information. Right here, Petastorm, a knowledge caching library constructed with Deep studying in thoughts, will likely be very helpful. The linked pocket book will show you how to leverage this expertise in your use case.
Deploying mannequin and index
As soon as the ultimate mannequin with the optimum hyperparameters is educated, the method of deploying a similarity mannequin is a nuanced one. It’s because the mannequin and the index have to be deployed collectively. Nonetheless, with MLflow, this course of is trivially easy. As talked about earlier than, suggestions are retrieved by querying the index of information with the embedding inferred from the question pattern. This may be illustrated in a simplified method as follows.
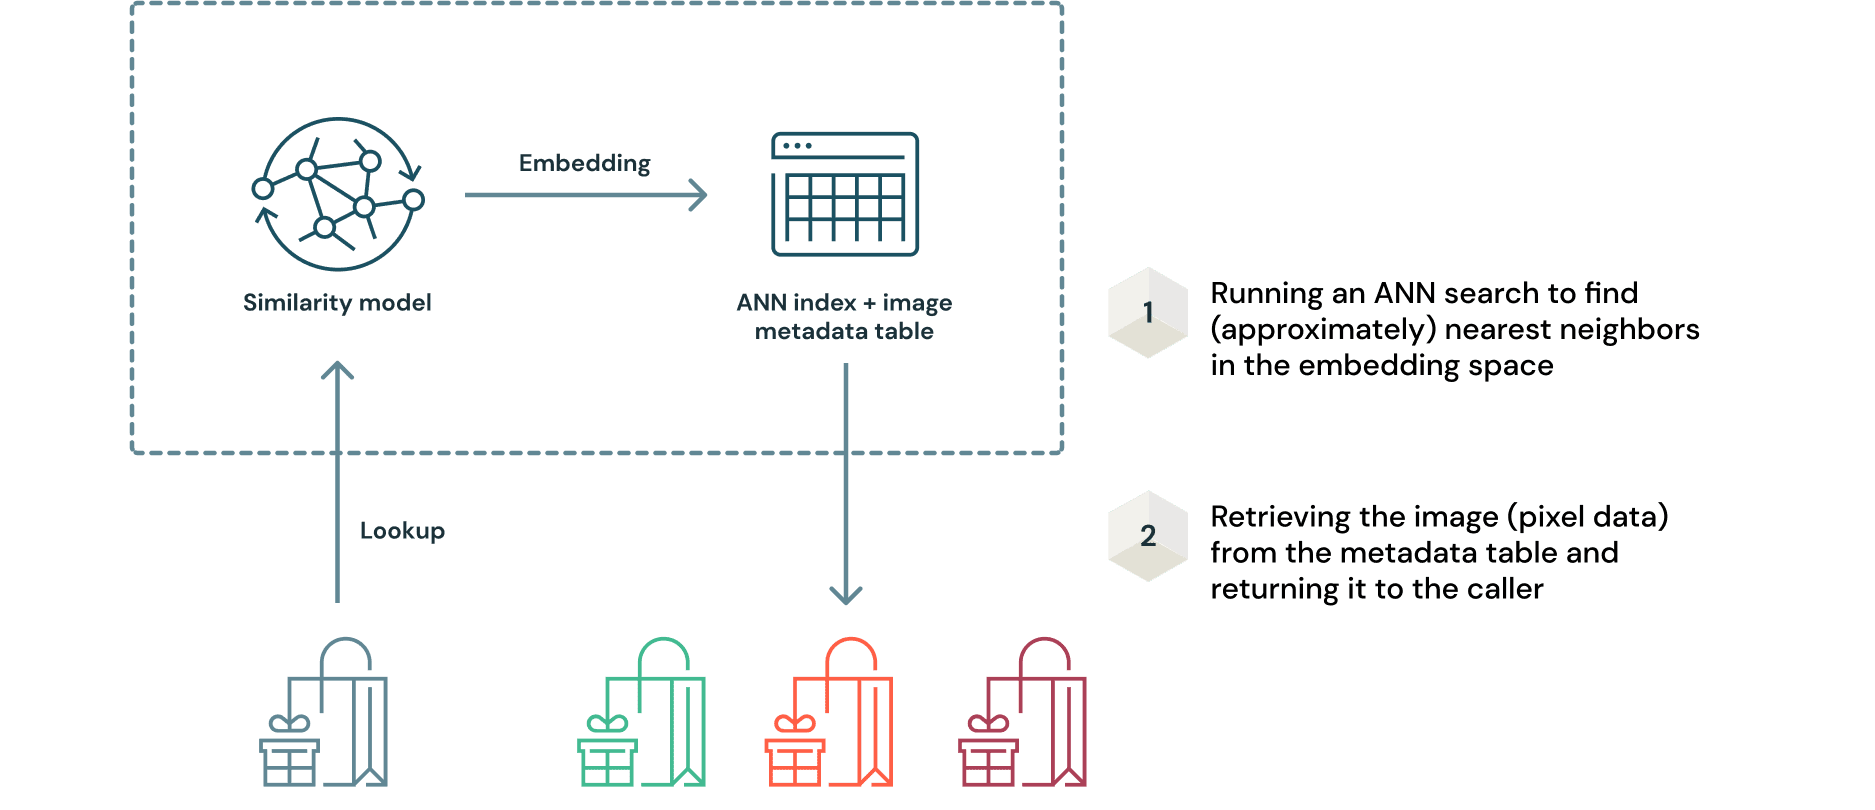
One of many key benefits of this strategy is that there isn’t any have to retrain the mannequin as new picture information is acquired. Embeddings could be generated with the mannequin and added to the ANN index for querying. Because the authentic picture information is within the Delta format, any increments to the desk will likely be recorded within the Delta transaction log. This ensures reproducibility of your complete information ingestion course of.
In MLflow, there are quite a few mannequin flavors for in style (and even obscure) ML frameworks to allow simple packaging of fashions for serving. In apply, there are quite a few cases the place a educated mannequin must be deployed with pre and/or submit processing logic, as within the case of the query-able similarity mannequin and ANN index. Right here we are able to use the mlflow.pyfunc module to create a customized `recommender mannequin` class (named TfsimWrapper on this case ) to encapsulate the inference and lookup logic. This hyperlink gives detailed documentation on how this could possibly be executed.
``` import mlflow.pyfunc class TfsimWrapper(mlflow.pyfunc.PythonModel): """ mannequin enter is a single row, single column pandas dataframe with base64 encoded byte string i.e. of the sort bytes. Column identify is 'enter' on this case""" """ mannequin output is a pandas dataframe the place every row(i.e.ingredient since just one column) is a string transformed to hexadecimal that must be transformed again to bytes after which a numpy array utilizing np.frombuffer(...) and reshaped to (28, 28) after which visualized (if wanted)""" def load_context(self, context): import tensorflow_similarity as tfsim from tensorflow_similarity.fashions import SimilarityModel from tensorflow.keras import fashions import pandas as pd import numpy as np self.tfsim_model = fashions.load_model(context.artifacts["tfsim_model"]) self.tfsim_model.load_index(context.artifacts["tfsim_model"]) def predict(self, context, model_input): from PIL import Picture import base64 import io picture = np.array(Picture.open(io.BytesIO(base64.b64decode(model_input["input"][0].encode())))) #The model_input must be of the shape (1, 28, 28) image_reshaped = picture.reshape(-1, 28, 28)/255.0 photographs = np.array(self.tfsim_model.lookup(image_reshaped, ok=5)) image_dict = {} for i in vary(5): image_dict[i] = photographs[0][i].information.tostring().hex() return pd.DataFrame.from_dict(image_dict, orient="index") ```The mannequin artifact could be logged, registered and deployed as a REST endpoint all inside the identical MLflow UI or by leveraging the MLflow API. Along with this performance, it’s attainable to outline enter and output schema as a mannequin signature within the logging course of to help swift hand-off to deployment. That is dealt with mechanically by together with the next 3 traces of code
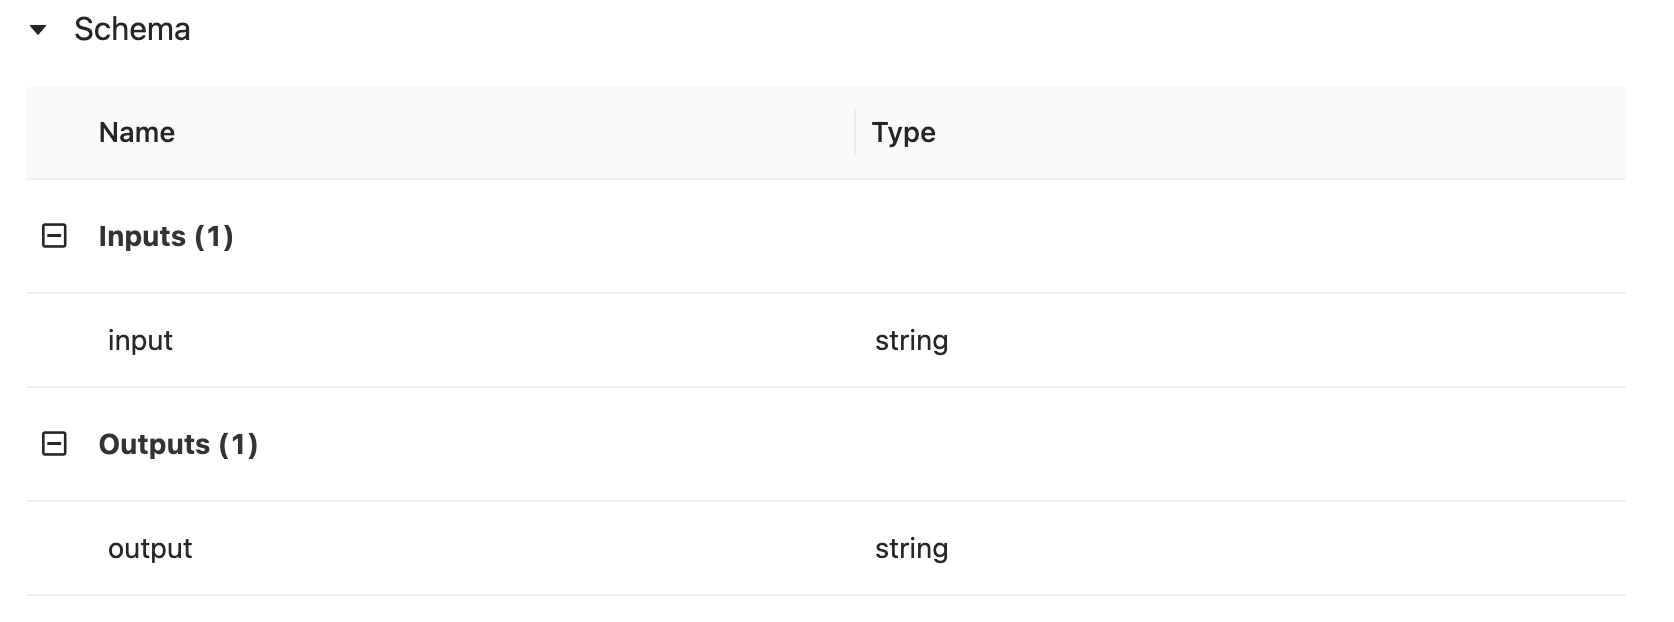
``` from mlflow.fashions.signature import infer_signature signature = infer_signature(sample_image, loaded_model.predict(sample_image)) mlflow.pyfunc.log_model(artifact_path=mlflow_pyfunc_model_path, python_model=TfsimWrapper(), artifacts=artifacts, conda_env=conda_env, signature = signature) ```As soon as the signature is inferred, information enter output schema expectations will likely be indicated within the UI as follows.
As soon as the REST endpoint has been created, you’ll be able to conveniently generate a bearer token by going to the person settings on the sliding panel on the left hand facet of the workspace. With this bearer token, you’ll be able to insert the mechanically generated Python wrapper code for the REST endpoint in any finish person dealing with software or inside course of that depends on mannequin inference.
The next perform will assist decode the JSON response from the REST name.
``` import numpy as np def process_response_image(i): “””response is the returned JSON object. We are able to loop by means of this object and return the reshaped numpy array for every advisable picture which might then be rendered””” single_image_string = response[i]["0"] image_array = np.frombuffer(bytes.fromhex(single_image_string), dtype=np.float32) image_reshaped = np.reshape(image_array, (28,28)) return image_reshaped ```The code for a easy Streamlit software constructed to question this endpoint is accessible within the repository for this weblog article. The next brief recording exhibits the recommender in motion.
Construct your personal with Databricks
Usually, the method of ingesting and formatting the information, mannequin optimization, coaching at scale, and deploying a similarity mannequin for suggestions is a novel and nuanced course of for a lot of. With the extremely optimized managed Spark, Delta Lake, and MLflow foundations that Databricks gives, this course of turns into easy and simple within the Lakehouse platform. Given you can entry managed compute clusters, the method of provisioning a number of GPUs is made seamless, with your complete course of taking solely a number of minutes. The pocket book linked beneath walks you thru the tip to finish means of constructing and deploying a similarity mannequin in an in depth method. We welcome you to attempt it, customise it in a fashion that matches your wants, and construct your personal production-grade ML-based picture suggestion system with Databricks.
[ad_2]

