



[ad_1]
Amazon Redshift is a quick, scalable, safe, and totally managed cloud information warehouse that makes it easy and cost-effective to research all of your information utilizing normal SQL. Amazon Redshift provides as much as thrice higher worth efficiency than another cloud information warehouse. Tens of hundreds of shoppers use Amazon Redshift to course of exabytes of knowledge per day and energy analytics workloads resembling high-performance enterprise intelligence (BI) reporting, dashboarding functions, information exploration, and real-time analytics.
As the quantity of knowledge generated by IoT gadgets, social media, and cloud functions continues to develop, organizations wish to simply and cost-effectively analyze this information with minimal time-to-insight. An unlimited quantity of this information is on the market in semi-structured format and wishes extra extract, remodel, and cargo (ETL) processes to make it accessible or to combine it with structured information for evaluation. Amazon Redshift powers the trendy information structure, which allows you to question information throughout your information warehouse, information lake, and operational databases to realize sooner and deeper insights not attainable in any other case. With a contemporary information structure, you’ll be able to retailer information in semi-structured format in your Amazon Easy Storage Service (Amazon S3) information lake and combine it with structured information on Amazon Redshift. This lets you make this information obtainable to different analytics and machine studying functions somewhat than locking it in a silo.
On this publish, we talk about the UNLOAD characteristic in Amazon Redshift and the way to export information from an Amazon Redshift cluster to JSON recordsdata on an Amazon S3 information lake.
JSON help options in Amazon Redshift
Amazon Redshift options resembling COPY, UNLOAD, and Amazon Redshift Spectrum allow you to maneuver and question information between your information warehouse and information lake.
With the UNLOAD command, you’ll be able to export a question consequence set in textual content, JSON, or Apache Parquet file format to Amazon S3. UNLOAD command can be really helpful when it’s essential retrieve massive consequence units out of your information warehouse. Since UNLOAD processes and exports information in parallel from Amazon Redshift’s compute nodes to Amazon S3, this reduces the community overhead and thus time in studying massive variety of rows. When utilizing the JSON choice with UNLOAD, Amazon Redshift unloads to a JSON file with every line containing a JSON object, representing a full file within the question consequence. Within the JSON file, Amazon Redshift varieties are unloaded because the closest JSON illustration. For instance, Boolean values are unloaded as true or false, NULL values are unloaded as null, and timestamp values are unloaded as strings. If a default JSON illustration doesn’t go well with a selected use case, you’ll be able to modify it by casting to the specified sort within the SELECT question of the UNLOAD assertion.
Moreover, to create a legitimate JSON object, the title of every column within the question consequence should be distinctive. If the column names within the question consequence aren’t distinctive, the JSON UNLOAD course of fails. To keep away from this, we advocate utilizing correct column aliases so that every column within the question consequence stays distinctive whereas getting unloaded. We illustrate this habits later on this publish.
With the Amazon Redshift SUPER information sort, you’ll be able to retailer information in JSON format on native Amazon Redshift tables. This fashion, you’ll be able to course of the info with none community overhead and use Amazon Redshift schema properties to optimally save and question semi structured information domestically. Along with attaining low latency, you may also use the SUPER information sort when your question requires robust consistency, predictable question efficiency, complicated question help, and ease of use with evolving schemas and schemaless information. Amazon Redshift helps writing nested JSON when the question consequence accommodates SUPER columns.
Updating and sustaining information with always evolving schemas could be difficult and provides additional ETL steps to the analytics pipeline. The JSON file format supplies help for schema definition, is light-weight, and is broadly used as an information switch mechanism by totally different providers, instruments, and applied sciences.
Amazon OpenSearch Service (successor to Amazon Elasticsearch Service) is a distributed, open-source search and analytics suite used for a broad set of use circumstances like real-time utility monitoring, log analytics, and web site search. It makes use of JSON because the supported file format for information ingestion. The power to unload information natively in JSON format from Amazon Redshift into the Amazon S3 information lake reduces complexity and extra information processing steps if that information must be ingested into Amazon OpenSearch Service for additional evaluation.
That is one instance of how seamless information motion may help you construct an built-in information platform with an information lake on Amazon S3, information warehouse on Amazon Redshift and search and log analytics utilizing Amazon OpenSearch Service and another JSON-oriented downstream analytics resolution. For extra details about the Lake Home strategy, see Construct a Lake Home Structure on AWS.
Examples of Amazon Redshift JSON UNLOAD
On this publish, we present you the next totally different eventualities:
- Instance 1 – Unload buyer information in JSON format into Amazon S3, partitioning output recordsdata into partition folders, following the Apache Hive conference, with buyer beginning month because the partition key. We make a couple of modifications to the columns within the SELECT assertion of the UNLOAD command:
- Convert the
c_preferred_cust_flagcolumn from character to Boolean - Take away main and trailing areas from the
c_first_name,c_last_name, andc_email_addresscolumns utilizing the Amazon Redshift built-in operate btrim
- Convert the
- Instance 2 – Unload line merchandise information (with SUPER column) in JSON format into Amazon S3 with information not partitioned
- Instance 3 – Unload line merchandise information (With SUPER column) in JSON format into Amazon S3, partitioning output recordsdata into partition folders, following the Apache Hive conference, with buyer key because the partition key
For the primary instance, we used the buyer desk and information from the TPCDS dataset. For examples involving desk with SUPER column, we used the customer_orders_lineitem desk and information from the next tutorial.
Instance 1: Export buyer information
For this instance, we used the client desk and information from TPCDS dataset. We created the database schema and buyer desk, and copied information into it. See the next code:
You possibly can create a default AWS Id and Entry Administration (IAM) position in your Amazon Redshift cluster to repeat from and unload to your Amazon S3 location. For extra info, see Use the default IAM position in Amazon Redshift to simplify accessing different AWS providers.
On this instance, we unloaded buyer information for all prospects with beginning 12 months 1992 in JSON format into Amazon S3 with none partitions. We make the next modifications to the UNLOAD assertion:
- Convert the
c_preferred_cust_flagcolumn from character to Boolean - Take away main and trailing areas from the
c_first_name,c_last_name, andc_email_addresscolumns utilizing thebtrimoperate - Set the utmost dimension of exported recordsdata in Amazon S3 to 64 MB
See the next code:
After we ran the UNLOAD command, we encountered an error as a result of the columns that used the btrim operate all tried to be exported as btrim (which is the default habits of Amazon Redshift when the identical operate is utilized to a number of columns which can be chosen collectively). To keep away from this error, we have to use a singular column alias for every column the place the btrim operate was used.
If we choose the c_first_name, c_last_name, and c_email_address columns by making use of the btrim operate and c_preferred_cust_flag, we will convert them from character to Boolean.
We ran the next question in Amazon Redshift Question Editor v2:
All three columns that used the btrim operate are set as btrim within the output consequence as a substitute of their respective column title.
An error occurred in UNLOAD as a result of we didn’t use a column alias.
We added column aliases within the following code:
After we added column aliases, the UNLOAD command accomplished efficiently and recordsdata had been exported to the specified location in Amazon S3.
The next screenshot exhibits information is unloaded in JSON format partitioning output recordsdata into partition folders, following the Apache Hive conference, with buyer beginning month because the partition key into Amazon S3 from the Amazon Redshift buyer desk.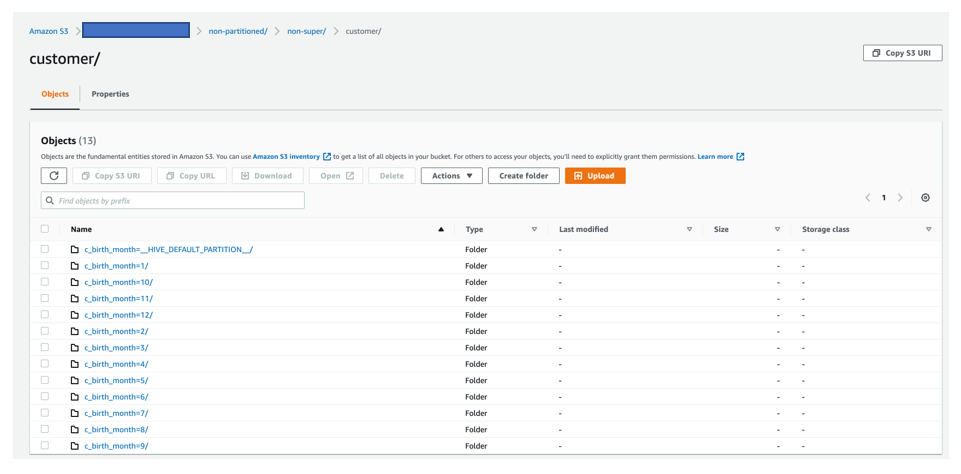
A question with Amazon S3 Choose exhibits a snippet of knowledge within the JSON file on Amazon S3 that was unloaded.
The column aliases c_first_name, c_last_name, and c_email_addr_trimmed had been written into the JSON file as per the SELECT question. Boolean values had been saved in c_preferred_cust_flag_bool as properly.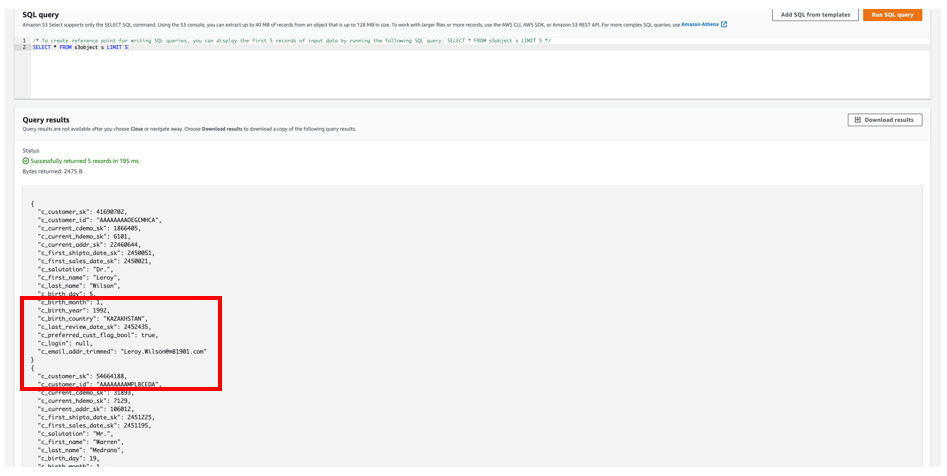
Examples 2 and three: Utilizing the SUPER column
For the subsequent two examples, we used the customer_orders_lineitem desk and information. We created the customer_orders_lineitem desk and copied information into it with the next code:
Subsequent, we ran a couple of queries to discover the customer_orders_lineitem desk’s information:


Instance 2: With out partitions
On this instance, we unloaded all of the rows of the customer_orders_lineitem desk in JSON format into Amazon S3 with none partitions:
After we run the UNLOAD command, the info is on the market within the desired Amazon S3 location. The next screenshot exhibits information is unloaded in JSON format with none partitions into Amazon S3 from the Amazon Redshift customer_orders_lineitem desk.
A question with Amazon S3 Choose exhibits a snippet of knowledge within the JSON file on Amazon S3 that was unloaded.
Instance 3: With partitions
On this instance, we unloaded all of the rows of the customer_orders_lineitem desk in JSON format partitioning output recordsdata into partition folders, following the Apache Hive conference, with buyer key because the partition key into Amazon S3:
After we run the UNLOAD command, the info is on the market within the desired Amazon S3 location. The next screenshot exhibits information is unloaded in JSON format partitioning output recordsdata into partition folders, following the Apache Hive conference, with buyer key because the partition key into Amazon S3 from the Amazon Redshift customer_orders_lineitem desk.
A question with Amazon S3 Choose exhibits a snippet of knowledge within the JSON file on Amazon S3 that acquired unloaded.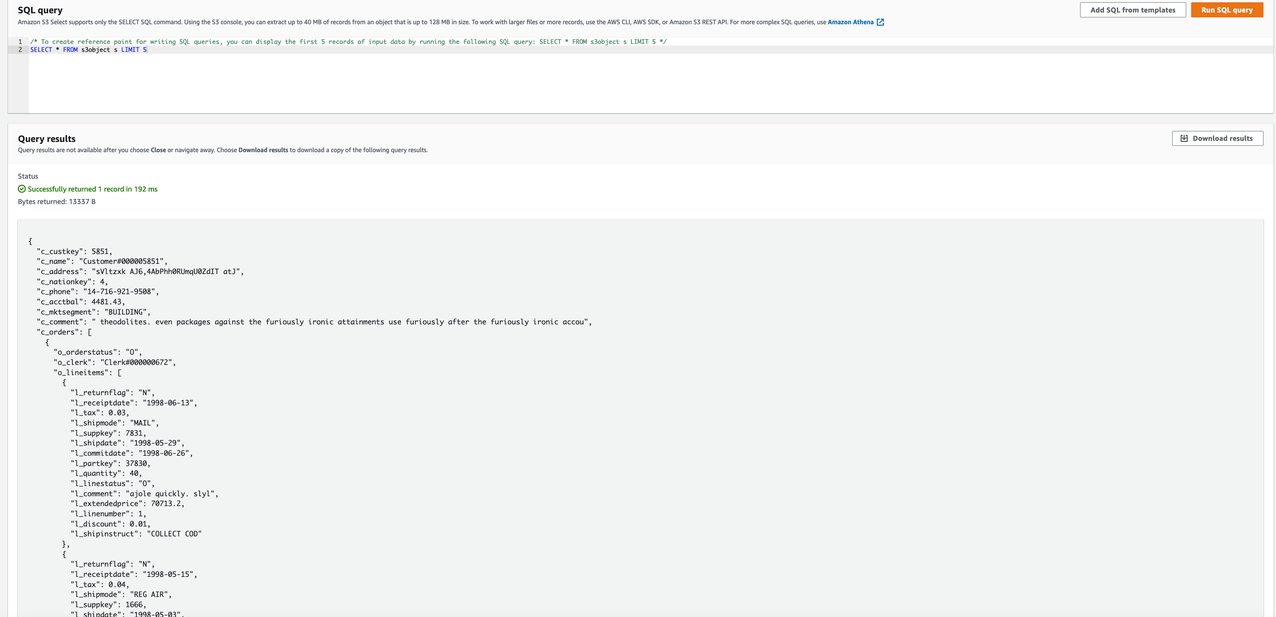
Conclusion
On this publish, we confirmed how you should use the Amazon Redshift UNLOAD command to unload the results of a question to a number of JSON recordsdata into your Amazon S3 location. We additionally confirmed how one can partition the info utilizing your selection of partition key whilst you unload the info. You should utilize this characteristic to export information to JSON recordsdata into Amazon S3 out of your Amazon Redshift cluster or your Amazon Redshift Serverless endpoint to make your information processing easier and construct an built-in information analytics platform.
Concerning the Authors
 Dipankar Kushari is a Senior Analytics Options Architect with AWS.
 Sayali Jojan is a Senior Analytics Options Architect with AWS. She has 7 years of expertise working with prospects to design and construct options on the AWS Cloud, with a concentrate on information and analytics.
 Cody Cunningham is a Software program Improvement Engineer with AWS, engaged on information ingestion for Amazon Redshift.
[ad_2]

