



[ad_1]
In Half 1 of this submit, we offered an answer to construct the sourcing, orchestration, and transformation of information from a number of supply programs, together with Salesforce, SAP, and Oracle, right into a managed trendy knowledge platform. Roche partnered with AWS Skilled Companies to construct out this totally automated and scalable platform to offer the inspiration for his or her machine studying targets. This submit continues the info journey to incorporate the steps undertaken to construct an agile and extendable Amazon Redshift knowledge warehouse platform utilizing a DevOps strategy.
The fashionable knowledge platform ingests delta modifications from all supply knowledge feeds as soon as per night time. The orchestration and transformations of the info is undertaken by dbt. dbt permits knowledge analysts and engineers to put in writing knowledge transformation queries in a modular method with out having to take care of the run order manually. It compiles all code into uncooked SQL queries that run towards the Amazon Redshift cluster. It additionally controls the dependency administration inside your queries and runs it within the right order. dbt code is a mixture of SQL and Jinja (a templating language); due to this fact, you possibly can categorical logic reminiscent of if statements, loops, filters, and macros in your queries. dbt additionally accommodates computerized knowledge validation job scheduling to measure the info high quality of the info loaded. For extra details about the best way to configure a dbt challenge inside an AWS surroundings, see Automating deployment of Amazon Redshift ETL jobs with AWS CodeBuild, AWS Batch, and DBT.
Amazon Redshift was chosen as the info warehouse due to its means to seamlessly entry knowledge saved in business commonplace open codecs inside Amazon Easy Storage Service (Amazon S3) and quickly ingest the required datasets into native, quick storage utilizing well-understood SQL instructions. Having the ability to develop extract, load, and remodel (ELT) code pipelines in SQL was vital for Roche to reap the benefits of the present deep SQL expertise of their knowledge engineering groups.
A contemporary ELT platform requires a contemporary, agile, and extremely performant knowledge mannequin. The answer on this submit builds a knowledge mannequin utilizing the Knowledge Vault 2.0 requirements. Knowledge Vault has a number of compelling benefits for data-driven organizations:
- It removes knowledge silos by storing all of your knowledge in reusable supply system impartial knowledge shops keyed on your online business keys.
- It’s a key driver for knowledge integration at many ranges, from a number of supply programs, a number of native markets, a number of corporations and associates, and extra.
- It reduces knowledge duplication. As a result of knowledge is centered round enterprise keys, if a couple of system sends the identical knowledge, then a number of knowledge copies aren’t wanted.
- It holds all historical past from all sources; downstream you possibly can entry any knowledge at any time limit.
- You may load knowledge with out rivalry or in parallel, and in batch or actual time.
- The mannequin can adapt to alter with minimal affect. New enterprise relationships will be made independently of the present relationships
- The mannequin is nicely established within the business and naturally drives templated and reusable code builds.
The next diagram illustrates the high-level overview of the structure:
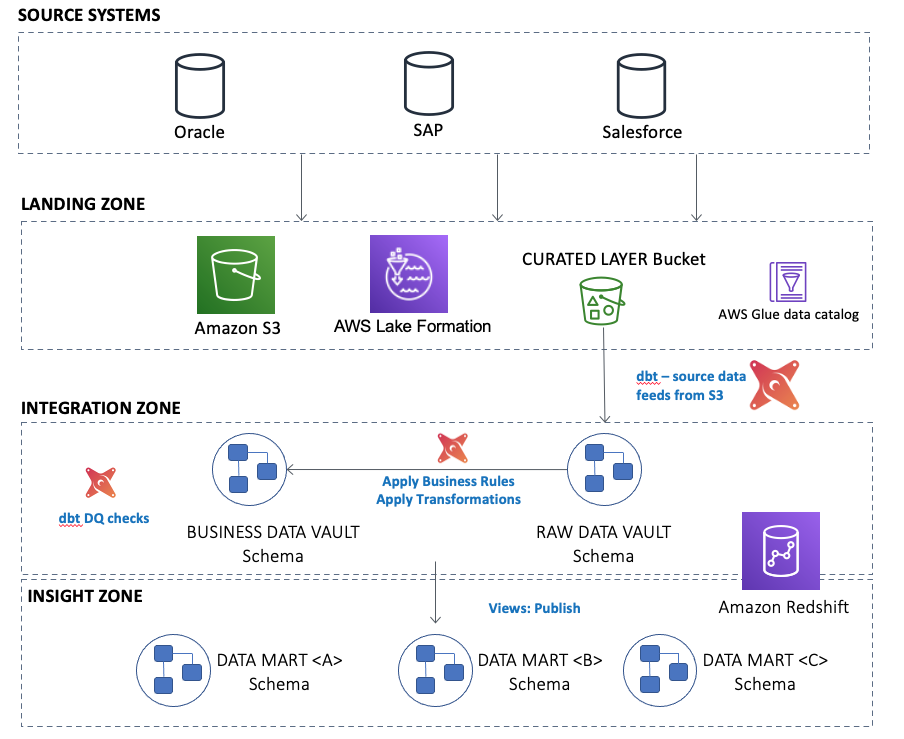
Amazon Redshift has a number of strategies for ingesting knowledge from Amazon S3 into the info warehouse cluster. For this contemporary knowledge platform, we use a mixture of the next strategies:
- We use Amazon Redshift Spectrum to learn knowledge straight from Amazon S3. This permits the challenge to quickly load, retailer, and use exterior datasets. Amazon Redshift permits the creation of exterior schemas and exterior tables to facilitate knowledge being accessed utilizing commonplace SQL statements.
- Some feeds are continued in a staging schema inside Amazon Redshift, for instance bigger knowledge volumes and datasets which are used a number of occasions in subsequent ELT processing. dbt handles the orchestration and loading of this knowledge in an incremental method to cater to day by day delta modifications.
Inside Amazon Redshift, the Knowledge Vault 2.0 knowledge mannequin is cut up into three separate areas:
- Uncooked Knowledge Vault inside a schema known as
raw_dv - Enterprise Knowledge Vault inside a schema known as
business_dv - A number of Knowledge Marts, every with their very own schema
Uncooked Knowledge Vault
Enterprise keys are central to the success of any Knowledge Vault challenge, and we created hubs inside Amazon Redshift as follows:
Take note the next:
- The enterprise keys from a number of supply feeds are written to the reusable
_bkcolumn; compound enterprise keys ought to be concatenated along with a standard separator between every aspect. - The first secret is saved within the
_pkcolumn and is a hashed worth of the_bkcolumn. On this case, MD5 is the hashing algorithm used. Load_Dtsis the date and time of the insertion of this row.- Hubs maintain reference knowledge, which is often smaller in quantity than transactional knowledge, so it’s best to select a distribution model of ALL for essentially the most performant becoming a member of to different tables at runtime.
As a result of Knowledge Vault is constructed on a standard reusable notation, the dbt code is parameterized for every goal. The Roche engineers constructed a Yaml-driven code framework to parameterize the logic for the construct of every goal desk, enabling fast construct and testing of recent feeds. For instance, the previous person hub accommodates parameters to determine supply columns for the enterprise key, supply to focus on mappings, and physicalization decisions for the Amazon Redshift goal:
On studying the YAML configuration, dbt outputs the next, which is run towards the Amazon Redshift cluster:
dbt additionally has the potential so as to add reusable macros to permit widespread duties to be automated. The next instance reveals the development of the enterprise key with applicable separators (the macro is named compound_key):
Historized reference knowledge about every enterprise secret is saved in satellites. The first key of every satellite tv for pc is a compound key consisting of the _pk column of the dad or mum hub and the Load_Dts. See the next code:
Take note the next:
- The feed title is saved as a part of the satellite tv for pc title. This permits the loading of reference knowledge from both a number of feeds inside the similar supply system or from a number of supply programs.
- Satellites are insert solely; new reference knowledge is loaded as a brand new row with an applicable
Load_Dts. - The
HASH_DIFFcolumn is a hashed concatenation of all of the descriptive columns inside the satellite tv for pc. The dbt code makes use of it to determine whether or not reference knowledge has modified and a brand new row is to be inserted. - Until the info volumes inside a satellite tv for pc develop into very giant (tens of millions of rows), it’s best to select a distribution selection of ALL to allow essentially the most performant joins at runtime. For bigger volumes of information, select a distribution model of AUTO to reap the benefits of Amazon Redshift computerized desk optimization, which chooses essentially the most optimum distribution model and kind key based mostly on the downstream utilization of those tables.
Transactional knowledge is saved in a mixture of hyperlink and hyperlink satellite tv for pc tables. These tables maintain the enterprise keys that contribute to the transaction being undertaken in addition to elective measures describing the transaction.
Beforehand, we confirmed the construct of the person hub and two of its satellites. Within the following hyperlink desk, the person hub international secret is one in all a number of hub keys within the compound key:
Take note the next:
- The international keys again to every hub are a hash worth of the enterprise keys, giving a 1:1 be part of with the
_pkcolumn of every hub. - The first key of this hyperlink desk is a hash worth of the entire hub international keys.
- The first key provides direct entry to the elective hyperlink satellite tv for pc that holds additional historized knowledge about this transaction. The definition of the hyperlink satellites is nearly similar to satellites; as a substitute of the
_pkfrom the hub being a part of the compound key, the_pkof the hyperlink is used. - As a result of knowledge volumes are usually bigger for hyperlinks and hyperlink satellites than hubs or satellites, you possibly can once more select AUTO distribution model to let Amazon Redshift select the optimum bodily desk distribution selection. If you happen to do select a distribution model, then select KEY on the
_pkcolumn for each the distribution model and kind key on each the hyperlink and any hyperlink satellites. This improves downstream question efficiency by co-locating the datasets on the identical slice inside the compute nodes and permits MERGE JOINS at run time for optimum efficiency.
Along with the dbt code to construct all of the previous targets within the Amazon Redshift schemas, the product accommodates a robust testing software that makes assertions on the underlying knowledge contents. The platform repeatedly checks the outcomes of every knowledge load.
Checks are specified utilizing a YAML file known as schema.yml. For instance, taking the territory satellite tv for pc (s_territory), we are able to see automated testing for situations, together with making certain the first secret is populated, its dad or mum secret is current within the territory hub (h_territory), and the compound key of this satellite tv for pc is exclusive:
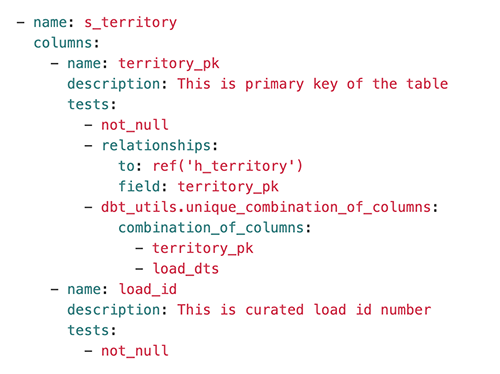
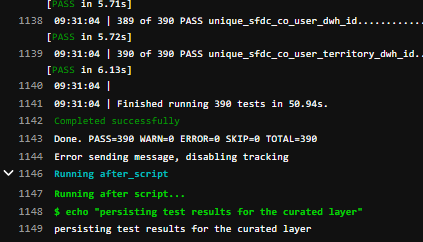
As proven within the following screenshot, the checks are clearly labeled as PASS or FAILED for fast identification of information high quality points.
Enterprise Knowledge Vault
The Enterprise Knowledge Vault is an important aspect of any Knowledge Vault mannequin. That is the place the place enterprise guidelines, KPI calculations, efficiency denormalizations, and roll-up aggregations happen. Enterprise guidelines can change over time, however the uncooked knowledge doesn’t, which is why the contents of the Uncooked Knowledge Vault ought to by no means be modified.
The kind of objects created within the Enterprise Knowledge Vault schema embrace the next:
- Sort 2 denormalization based mostly on both the newest load date timestamp or a business-supplied efficient date timestamp. These objects are splendid as the bottom for a sort 2 dimension view inside a knowledge mart.
- Newest row filtering based mostly on both the newest load date timestamp or a business-supplied efficient date timestamp. These objects are splendid as the bottom for a sort 1 dimension inside a knowledge mart.
- For hubs with a number of independently loaded satellites, point-in-time (PIT) tables are created with the snapshot date set to at least one time per day.
- The place the info entry necessities span a number of hyperlinks and hyperlink satellites, bridge tables are created with the snapshot date set to at least one time per day.
Within the following diagram, we present an instance of person reference knowledge from two supply programs being loaded into separate satellite tv for pc targets.
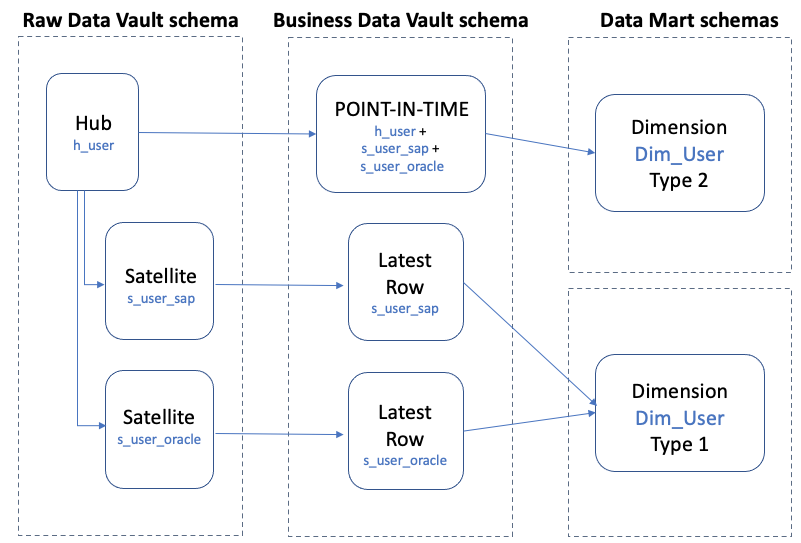
Take note the next:
- It is best to create a separate schema for the Enterprise Knowledge Vault objects
- You may construct a number of object sorts within the Enterprise Knowledge Vault:
- PIT and bridge targets are usually both tables or materialized views can be utilized for knowledge that incrementally modifications as a result of auto refresh capabilities
- The sort 2 and newest row choices from an underlying satellite tv for pc are usually views due to the decrease knowledge volumes usually present in reference datasets
- As a result of the Uncooked Knowledge Vault tables are insert solely, to find out a timeline of modifications, create a view just like the next:
Knowledge Marts
The work undertaken within the Enterprise Knowledge Vault signifies that views will be developed inside the Knowledge Marts to straight entry the info with out having to physicalize the outcomes into one other schema. These views might apply filters to the Enterprise Vault objects, for instance to filter just for knowledge from particular international locations, or the views might select a KPI that has been calculated within the Enterprise Vault that’s solely helpful inside this one knowledge mart.
Conclusion
On this submit, we detailed how you need to use dbt and Amazon Redshift for steady construct and validation of a Knowledge Vault mannequin that shops all knowledge from a number of sources in a source-independent method whereas providing flexibility and selection of subsequent enterprise transformations and calculations.
Particular thanks go to Roche colleagues Bartlomiej Zalewski, Wojciech Kostka, Michalina Mastalerz, Kamil Piotrowski, Igor Tkaczyk, Andrzej Dziabowski, Joao Antunes, Krzysztof Slowinski, Krzysztof Romanowski, Patryk Szczesnowicz, Jakub Lanski, and Chun Wei Chan for his or her challenge supply and help with this submit.
Concerning the Authors
 Dr. Yannick Misteli, Roche – Dr. Yannick Misteli is main cloud platform and ML engineering groups in world product technique (GPS) at Roche. He’s obsessed with infrastructure and operationalizing data-driven options, and he has broad expertise in driving enterprise worth creation via knowledge analytics.
 Simon Dimaline, AWS – Simon Dimaline has specialised in knowledge warehousing and knowledge modelling for greater than 20 years. He at present works for the Knowledge & Analytics staff inside AWS Skilled Companies, accelerating clients’ adoption of AWS analytics companies.
 Matt Noyce, AWS – Matt Noyce is a Senior Cloud Software Architect in Skilled Companies at Amazon Net Companies. He works with clients to architect, design, automate, and construct options on AWS for his or her enterprise wants.
 Chema Artal Banon, AWS – Chema Artal Banon is a Safety Guide at AWS Skilled Companies and he works with AWS’s clients to design, construct, and optimize their safety to drive enterprise. He focuses on serving to corporations speed up their journey to the AWS Cloud in essentially the most safe method potential by serving to clients construct the arrogance and technical functionality.
[ad_2]

