



[ad_1]
It is a visitor weblog publish co-written by Amit Nayak at Microstrategy. In their very own phrases, “MicroStrategy is the biggest unbiased publicly traded enterprise intelligence (BI) firm, with the main enterprise analytics platform. Our imaginative and prescient is to allow Intelligence All over the place. MicroStrategy offers fashionable analytics on an open, complete enterprise platform utilized by most of the world’s most admired manufacturers within the Fortune International 500. Optimized for cloud and on-premises deployments, the platform options HyperIntelligence, a breakthrough know-how that overlays actionable enterprise information on in style enterprise purposes to assist customers make smarter, sooner selections.”
Amazon Redshift is a quick, totally managed, petabyte-scale information warehouse. It offers a easy and cost-effective solution to analyze all of your information utilizing your present BI instruments. Amazon Redshift delivers quick question efficiency through the use of columnar storage know-how to enhance I/O effectivity and parallelizing queries throughout a number of nodes. Amazon Redshift has customized JDBC and ODBC drivers that you could obtain from the Join Consumer tab on the Amazon Redshift console, permitting you to make use of a variety of acquainted BI instruments.
When utilizing your MicroStrategy utility with Amazon Redshift, it’s essential to know the right way to optimize Amazon Redshift to get the perfect efficiency to fulfill your workload SLAs.
On this publish, we have a look at the perfect practices for optimized deployment of MicroStrategy utilizing Amazon Redshift.
Optimize Amazon Redshift
On this part, we focus on methods to optimize Amazon Redshift.
Amazon Redshift RA3 situations
RA3 nodes with managed storage make it easier to optimize your information warehouse by scaling and paying for the compute capability and managed storage independently. With RA3 situations, you’ll be able to select the variety of nodes primarily based in your efficiency necessities, and solely pay for the managed storage that you just use. Dimension your RA3 cluster primarily based on the quantity of information you course of each day with out growing your storage prices.
For extra particulars about RA3 options, see Amazon Redshift RA3 situations with managed storage.
Distribution kinds
While you load information right into a desk, Amazon Redshift distributes the rows of the desk to every of the compute nodes in response to the desk’s distribution fashion. While you run a question, the question optimizer redistributes the rows to the compute nodes as wanted to carry out any joins and aggregations. The aim in selecting a desk distribution fashion is to attenuate the affect of the redistribution step by finding the information the place it must be earlier than the question is run.
While you create a desk, you’ll be able to designate considered one of 4 distribution kinds: AUTO, EVEN, KEY, or ALL. For those who don’t specify a distribution fashion, Amazon Redshift makes use of AUTO distribution. With AUTO distribution, Amazon Redshift assigns an optimum distribution fashion primarily based on the scale of the desk information. You should use computerized desk optimization to get began with Amazon Redshift simply or optimize manufacturing workloads whereas reducing the executive effort required to get the very best efficiency.
MicroStrategy, like every SQL utility, transparently takes benefit of the distribution fashion outlined on base tables. MicroStrategy recommends following Amazon Redshift advisable finest practices when implementing the bodily schema of the bottom tables.
Kind keys
Defining a desk with a type key leads to the bodily ordering of information within the Amazon Redshift cluster nodes primarily based on the kind sort and the columns chosen in the important thing definition. Sorting allows environment friendly dealing with of range-restricted predicates to scan the minimal variety of blocks on disk to fulfill a question. A contrived instance can be having an orders desk with 5 years of information with a SORTKEY on the order_date column. Now suppose a question on the orders desk specifies a date vary of 1 month on the order_date column. On this case, you’ll be able to get rid of as much as 98% of the disk blocks from the scan. If the information isn’t sorted, extra of the disk blocks (probably all of them) must be scanned, ensuing within the question working longer.
We advocate creating your tables with SORTKEY AUTO. This fashion, Amazon Redshift makes use of computerized desk optimization to decide on the kind key. If Amazon Redshift determines that making use of a SORTKEY improves cluster efficiency, tables are routinely altered inside hours from the time the cluster was created, with minimal affect to queries.
We additionally advocate utilizing the kind key on columns usually used within the WHERE clause of the report queries. Remember the fact that SQL features (equivalent to information transformation features) utilized to type key columns in queries cut back the effectiveness of the kind key for these queries. As an alternative, just remember to apply the features to the in contrast values in order that the kind key’s used. That is generally discovered on DATE columns which can be used as type keys.
Amazon Redshift Advisor offers suggestions that can assist you enhance the efficiency and reduce the working prices in your Amazon Redshift cluster. The Advisor analyzes your cluster’s workload to determine probably the most acceptable distribution key and type key primarily based on the question patterns of your cluster.
Compression
Compression settings may also play a giant position with regards to question efficiency in Amazon Redshift. Compression conserves cupboard space and reduces the scale of information that’s learn from storage, which reduces the quantity of disk I/O and due to this fact improves question efficiency.
By default, Amazon Redshift routinely manages compression encoding for all columns in a desk. You possibly can specify the ENCODE AUTO choice for the desk to allow Amazon Redshift to routinely handle compression encoding for all columns in a desk. You possibly can alternatively apply a particular compression sort to the columns in a desk manually if you create the desk, or you should use the COPY command to investigate and apply compression routinely.
We don’t advocate compressing the primary column in a compound type key as a result of it would lead to scanning extra rows than anticipated.
Amazon Redshift materialized views
Materialized views can considerably enhance question efficiency for repeated and predictable analytical workloads equivalent to dashboarding, queries from BI instruments, and extract, load, and remodel (ELT) information processing.
Materialized views are particularly helpful for queries which can be predictable and repeated again and again. As an alternative of performing resource-intensive queries on massive tables, purposes can question the pre-computed information saved within the materialized view.
For instance, think about the state of affairs the place a set of queries is used to populate a group of charts for a dashboard. This use case is good for a materialized view, as a result of the queries are predictable and repeated time and again. Every time a change happens within the base tables (information is inserted, deleted, or up to date), the materialized views might be routinely or manually refreshed to symbolize the present information.
Amazon Redshift can routinely refresh materialized views with up-to-date information from its base tables when materialized views are created with or altered to have the auto-refresh choice. Amazon Redshift auto-refreshes materialized views as quickly as attainable after base tables modifications.
To replace the information in a materialized view manually, you should use the REFRESH MATERIALIZED VIEW assertion at any time. There are two methods for refreshing a materialized view:
- Incremental refresh – In an incremental refresh, it identifies the modifications to the information within the base tables because the final refresh and updates the information within the materialized view
- Full refresh – If incremental refresh isn’t attainable, Amazon Redshift performs a full refresh, which reruns the underlying SQL assertion, changing all the information within the materialized view
Amazon Redshift routinely chooses the refresh technique for a materialized view relying on the SELECT question used to outline the materialized view. For details about the constraints for incremental refresh, see Limitations for incremental refresh.
The next are a number of the key benefits utilizing materialized views:
- You possibly can pace up queries by pre-computing the outcomes of advanced queries, together with a number of base tables, predicates, joins, and aggregates
- You possibly can simplify and speed up ETL and BI pipelines
- Materialized views assist Amazon Redshift native, Amazon Redshift Spectrum, and federated queries
- Amazon Redshift can use computerized question rewrites of materialized views
For instance, let’s think about the gross sales crew needs to construct a report that exhibits
the product gross sales throughout completely different shops. This dashboard question is predicated out of a 3 TB Cloud DW benchmark dataset primarily based on the TPC-DS benchmark dataset.
On this first step, you create an everyday view. See the next code:
The next code is a report to investigate the product gross sales by class:
The previous stories take roughly 15 seconds to run. As extra merchandise are offered, this elapsed time regularly will get longer. To hurry up these stories, you’ll be able to create a materialized view to precompute the full gross sales per class. See the next code:
The next code analyzes the product gross sales by class towards the materialized view:
The identical stories towards a materialized view took round 4 seconds as a result of the brand new queries entry precomputed joins, filters, grouping, and partial sums as an alternative of the a number of, bigger base tables.
Workload administration
Amazon Redshift workload administration (WLM) lets you flexibly handle priorities inside workloads in order that quick, fast-running queries don’t get caught in queues behind long-running queries. You should use WLM to outline a number of question queues and route queries to the suitable queues at runtime.
You possibly can question WLM in two modes:
- Computerized WLM – Amazon Redshift manages the assets required to run queries. Amazon Redshift determines what number of queries run concurrently and the way a lot reminiscence is allotted to every dispatched question. Amazon Redshift makes use of extremely skilled refined ML algorithms to make these selections.
- Question precedence is a function of computerized WLM that allows you to assign precedence ranks to completely different consumer teams or question teams, to make sure that higher-priority workloads get extra assets for constant question efficiency, even throughout busy occasions. For instance, think about a essential dashboard report question that has increased precedence than an ETL job. You possibly can assign the precedence as highest for the report question and excessive precedence to the ETL question.
- No queries are ever starved of assets, and decrease precedence queries all the time full, however could take longer to finish.
- Handbook WLM – With handbook WLM, you’ll be able to handle the system efficiency by modifying the WLM configuration to create separate queues for long-running queries and short-running queries. You possibly can outline as much as eight queues to separate workloads from one another. Every queue incorporates numerous question slots, and every queue is related to a portion of obtainable reminiscence.
You may as well use the Amazon Redshift question monitoring guidelines (QMR) function to set metrics-based efficiency boundaries for workload administration (WLM) queues, and specify what motion to take when a question goes past these boundaries. For instance, for a queue that’s devoted to short-running queries, you may create a rule that cancels queries that run for greater than 60 seconds. To trace poorly designed queries, you might need one other rule that logs queries that comprise nested loops. You should use predefined rule templates in Amazon Redshift to get began with QMR.
We advocate the next configuration for WLM:
- Allow computerized WLM
- Allow concurrency scaling to deal with a rise in concurrent learn queries, with constant quick question efficiency
- Create QMR guidelines to trace and deal with poorly written queries
After you create and configure completely different WLM queues, you should use a MicroStrategy question label to set the Amazon Redshift question group for queue project. This tells Amazon Redshift which WLM queue to ship the question to.
You possibly can set the next as a report pre-statement in MicroStrategy:
You should use MicroStrategy question labels to determine the MicroStrategy submitted SQL statements inside Amazon Redshift system tables.
You should use it with all SQL assertion varieties; due to this fact, we advocate utilizing it for multi-pass SQL stories. When the label of a question is saved within the system view stl_query, it’s truncated to fifteen characters (30 characters are saved in all different system tables). For that reason, you ought to be cautious when selecting the worth for question label.
You possibly can set the next as a report pre-statement:
This collects info on the server facet about variables like venture title, report title, consumer, and extra.
To wash up the question group and launch assets, use the cleanup post-statement:
MicroStrategy permits the usage of wildcards which can be changed by values retrieved at a report’s run time, as proven within the pre- and post-statements. The next desk offers an instance of pre- and post-statements.
| VLDB Class | VLDB Property Setting | Worth Instance |
| Pre/Publish Statements | Report Pre-statement | set query_group to 'MSTR=!o;Venture=!p;Person=!u;Job=!j;' |
| Pre/Publish Statements | Cleanup Publish-statement | reset query_group; |
For instance, see the next code:
Question prioritization in MicroStrategy
Generally, you will have a number of purposes submitting queries to Amazon Redshift along with MicroStrategy. You should use Amazon Redshift question teams to determine MicroStrategy submitted SQL to Amazon Redshift, together with its project to the suitable Amazon Redshift WLM queue.
The Amazon Redshift question group for a MicroStrategy report is about and reset by means of the usage of the next report-level MicroStrategy VLDB properties.
| VLDB Class | VLDB Property Setting | Worth Instance |
| Pre/Publish Statements | Report Pre-statement | set query_group to 'MSTR_High=!o;' |
| Pre/Publish Statements | Cleanup Publish-statement | reset query_group; |
A MicroStrategy report job can submit a number of queries to Amazon Redshift. In such circumstances, all queries for a MicroStrategy report are labeled with the identical question group and due to this fact are assigned to similar queue in Amazon Redshift.
The next is an instance implementation of MicroStrategy Amazon Redshift WLM:
- Excessive-priority MicroStrategy stories are set with report pre-statement
MSTR_HIGH=!o;, medium precedence stories withMSTR_MEDIUM=!o;, and low precedence stories withMSTR_LOW=!o;. - Amazon Redshift WLM queues are created and related to corresponding question teams. For instance, the
MSTR_HIGH_QUEUEqueue is related to theMSTR_HIGH=*;question group (the place*is an Amazon Redshift wildcard).
Concurrency scaling
With concurrency scaling, you’ll be able to configure Amazon Redshift to deal with spikes in workloads whereas sustaining constant SLAs by elastically scaling the underlying assets as wanted. When concurrency scaling is enabled, Amazon Redshift repeatedly displays the designated workload. If the queries begin to get backlogged due to bursts of consumer exercise, Amazon Redshift routinely provides transient cluster capability and routes the requests to those new clusters. You handle which queries are despatched to the concurrency scaling cluster by configuring the WLM queues. This occurs transparently in a matter of seconds, so your queries proceed to be served with low latency. As well as, each 24 hours that the Amazon Redshift essential cluster is in use, you accrue a 1-hour credit score in direction of utilizing concurrency scaling. This permits 97% of Amazon Redshift clients to learn from concurrency scaling at no further cost.
For extra particulars on concurrency scaling pricing, see Amazon Redshift pricing.
Amazon Redshift removes the extra transient capability routinely when exercise reduces on the cluster. You possibly can allow concurrency scaling for the MicroStrategy report queue and in case of heavy load on the cluster, the queries run on a concurrent cluster, thereby enhancing the general dashboard efficiency and sustaining a constant consumer expertise.
To make concurrency scaling work with MicroStrategy, use derived tables as an alternative of momentary tables, which you are able to do by setting the VLDB property Intermediate desk sort to Derived desk.
Within the following instance, we allow concurrency scaling on the Amazon Redshift cluster for the MicroStrategy dashboard queries. We create a consumer group in Amazon Redshift, and all of the dashboard queries are allotted to this consumer group’s queue. With concurrency scaling in place for the report queries, we are able to see a major discount in question wait time.
For this instance, we created one WLM queue to run our dashboard queries with highest precedence and one other ETL queue with excessive precedence. Concurrency scaling is turned on for the dashboard queue, as proven within the following screenshot.
As a part of this take a look at, we ran a number of queries in parallel on the cluster, a few of that are ETL jobs (insert, delete, replace, and replica), and a few are advanced choose queries, equivalent to dashboard queries. The next graph illustrates what number of queries are ready within the WLM queues and the way concurrency scaling helps to deal with these queries.

Within the previous graph, a number of queries are ready within the WLM queues; concurrency scaling routinely begins in seconds to course of queries with none delays, as proven within the following graph.
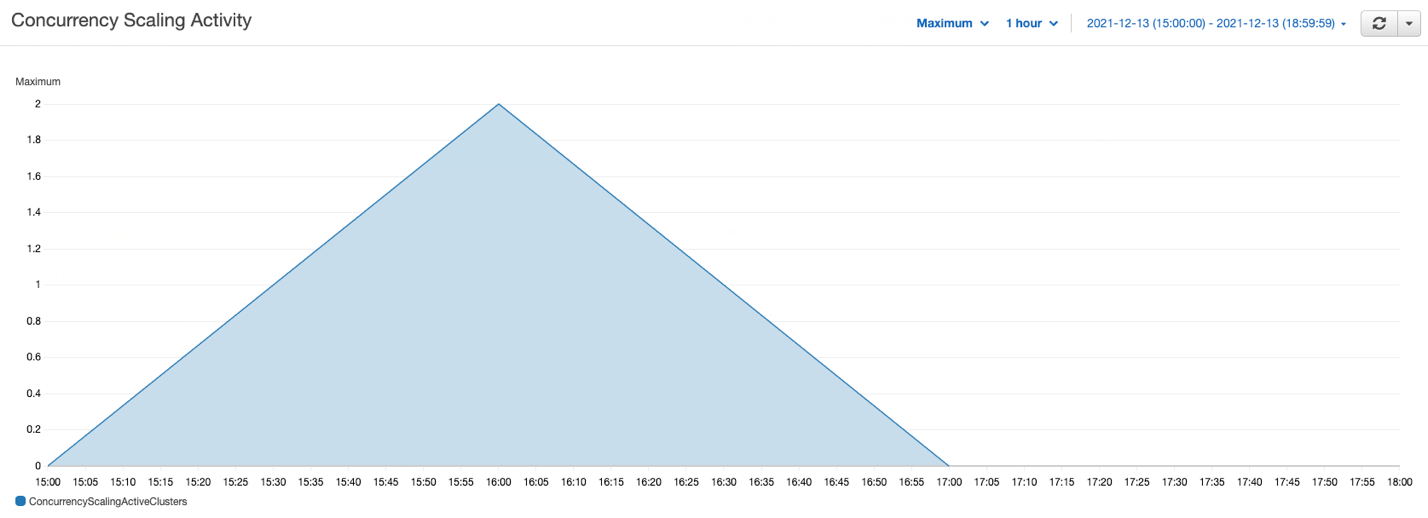
This instance has demonstrated how concurrency scaling helps deal with spikes in consumer workloads by including transient clusters as wanted to supply constant efficiency even because the workload grows to a whole bunch of concurrent queries.
Amazon Redshift federated queries
Prospects utilizing MicroStrategy usually join numerous relational information sources to a single MicroStrategy venture for reporting and evaluation functions. For instance, you may combine an operational (OLTP) information supply (equivalent to Amazon Aurora PostgreSQL) and information warehouse information to get significant insights into your online business.
With federated queries in Amazon Redshift, you’ll be able to question and analyze information throughout operational databases, information warehouses, and information lakes. The federated question function permits you to combine queries from Amazon Redshift on stay information in exterior databases with queries throughout your Amazon Redshift and Amazon Easy Storage Service (Amazon S3) environments.
Federated queries assist incorporate stay information as a part of your MicroStrategy reporting and evaluation, with out the necessity to hook up with a number of relational information sources from MicroStrategy.
You may as well use federated queries to MySQL.
This simplifies the multi-source stories use case by being able to run queries on each operational and analytical information sources, with out the necessity to explicitly join and import information from completely different information sources inside MicroStrategy.
Redshift Spectrum
The MicroStrategy Amazon Redshift connector consists of assist for Redshift Spectrum, so you’ll be able to join instantly to question information in Amazon Redshift and analyze it along side information in Amazon S3.
With Redshift Spectrum, you’ll be able to effectively question and retrieve structured and semi-structured information (equivalent to PARQUET, JSON, and CSV) from information in Amazon S3 with out having to load the information into Amazon Redshift tables. It permits clients with massive datasets saved in Amazon S3 to question that information from inside the Amazon Redshift cluster utilizing Amazon Redshift SQL queries with no information motion—you pay just for the information you scanned. Redshift Spectrum additionally permits a number of Amazon Redshift clusters to concurrently question the identical dataset in Amazon S3 with out the necessity to make copies of the information for every cluster. Based mostly on the calls for of the queries, Redshift Spectrum can intelligently scale out to benefit from massively parallel processing.
Use circumstances that may profit from utilizing Redshift Spectrum embrace:
- A big quantity of less-frequently accessed information
- Heavy scan-intensive and aggregation-intensive queries
- Selective queries that may use partition pruning and predicate pushdown, so the output is pretty small
Redshift Spectrum provides you the liberty to retailer your information the place you need, within the format you need, and have it out there for processing if you want it.
With Redshift Spectrum, you benefit from a quick, cost-effective engine that minimizes information processed with dynamic partition pruning. You possibly can additional enhance question efficiency by decreasing the quantity of information scanned. You could possibly do that by partitioning and compressing information and through the use of a columnar format for storage.
For extra particulars on the right way to optimize Redshift Spectrum question efficiency and price, see Greatest Practices for Amazon Redshift Spectrum.
Optimize MicroStrategy
On this part, we focus on methods to optimize MicroStrategy.
SQL optimizations
With MicroStrategy 2021, MicroStrategy has delivered assist for 70 new superior customizable features to boost usability and functionality, particularly when in comparison with beforehand present Apply features. Utility architects can customise the features and make them prepared and out there for normal customers like enterprise analysts to make use of! For extra info on the right way to use these new customizable features, go to the MicroStrategy neighborhood website.
SQL International Optimization
This setting can considerably cut back the variety of SQL passes generated by MicroStrategy. In MicroStrategy, SQL International Optimization reduces the full variety of SQL passes with the next optimizations:
- Eliminates unused SQL passes – For instance, a temp desk is created however not referenced in a later cross
- Reuses redundant SQL passes – For instance, the very same temp desk is created a number of occasions when a single temp desk is created
- Combines SQL passes the place the SELECT listing is completely different – For instance, two temp tables which have the identical FROM clause, joins, WHERE clause, and GROUP BY SELECT lists are mixed into single SELECT assertion
- Combines SQL passes the place the WHERE clause is completely different – For instance, two temp tables which have similar the SELECT listing, FROM clause, joins, and GROUP BY predicates from the WHERE clause are moved into CASE statements within the SELECT listing
The default setting for Amazon Redshift is to allow SQL International Optimization at its highest degree. In case your database occasion is configured as an earlier model of Amazon Redshift, you will have to allow this setting manually. For extra info, see the MicroStrategy System Administration Information.
Set Operator Optimization
This setting is used to mix a number of subqueries right into a single subquery utilizing set operators (equivalent to UNION, INTERSECT, and EXCEPT). The default setting for Amazon Redshift is to allow Set Operator Optimization.
SQL question technology
The MicroStrategy question engine is ready to mix a number of passes of SQL that entry the identical desk (usually the primary truth desk). This may enhance efficiency by eliminating a number of desk scans of huge tables. For instance, this function considerably reduces the variety of SQL passes required to course of datasets with customized teams.
Technically, the WHERE clauses of various passes are resolved in CASE statements of a single SELECT clause, which doesn’t comprise {qualifications} within the WHERE clause. Usually, this elimination of WHERE clauses causes a full desk scan on a big desk.
In some circumstances (on a report-by-report foundation), this strategy might be slower than many extremely certified SELECT statements. As a result of any efficiency distinction between approaches is usually impacted by the reporting requirement and implementation within the MicroStrategy utility, it’s obligatory to check each choices for every dataset to determine the optimum case.
The default conduct is to merge all passes with completely different WHERE clauses (degree 4). We advocate testing any choice for this setting, however mostly the most important efficiency enhancements (if any) are noticed by switching to the choice Degree 2: Merge Passes with Completely different SELECT.
| VLDB Class | VLDB Property Setting | Worth |
| Question Optimizations | SQL International Optimization | Degree 2: Merge Passes with Completely different SELECT |
SQL measurement
As we defined earlier, MicroStrategy tries to submit a single question assertion containing the analytics of a number of passes within the derived desk syntax. This may result in sizeable SQL question syntax. It’s attainable for such an announcement to exceed the capabilities of the driving force or database. For that reason, MicroStrategy governs the scale of generated queries and throws an error message if that is exceeded. Beginning with MicroStrategy 10.9, this worth is tuned to present Amazon Redshift capabilities (16 MB). Earlier variations specify a smaller restrict that may be modified utilizing the next VLDB setting on the Amazon Redshift DB occasion in Developer.
| VLDB Class | VLDB Property Setting | Worth |
| Governing | SQL Dimension/MDX Dimension | 16777216 |
Subquery sort
There are numerous circumstances through which the SQL engine generates subqueries (question blocks within the WHERE clause):
- Stories that use relationship filters
- Stories that use NOT IN set qualification, equivalent to AND NOT
- Stories that use attribute qualification with M-M relationships; for instance, displaying income by class and filtering on catalog
- Stories that elevate the extent of a filter; for instance, dimensional metric at Area degree, however qualify on retailer
- Stories that use non-aggregatable metrics, equivalent to stock metrics
- Stories that use dimensional extensions
- Stories that use attribute-to-attribute comparability within the filter
The default setting for subquery sort for Amazon Redshift is The place EXISTS(choose (col1, col2…)):
Some stories might carry out higher with the choice of utilizing a short lived desk and falling again to IN for a correlated subquery. Stories that embrace a filter with an AND NOT set qualification (equivalent to AND NOT relationship filter) will doubtless profit from utilizing temp tables to resolve the subquery. Nonetheless, such stories will in all probability profit extra from utilizing the Set Operator Optimization choice mentioned earlier. The opposite settings aren’t prone to be advantageous with Amazon Redshift.
| VLDB Class | VLDB Property Setting | Worth |
| Question Optimizations | Subquery Sort | Use momentary desk, falling again to IN for correlated subquery |
Full outer be part of assist
Full outer be part of assist is enabled within the Amazon Redshift object by default. Ranges at which you’ll set this are database occasion, report, and template.
For instance, the next question exhibits the usage of full outer be part of with the states_dates and areas tables:
DISTINCT or GROUP BY choice (for no aggregation and no desk key)
If no aggregation is required and the attribute outlined on the desk isn’t a major key, this property tells the SQL engine whether or not to make use of SELECT DISTINCT, GROUP BY, or neither.
Attainable values for this setting embrace:
- Use DISTINCT
- No DISTINCT, no GROUP BY
- Use GROUP BY
The DISTINCT or GROUP BY choice property controls the technology of DISTINCT or GROUP BY within the SELECT SQL assertion. The SQL engine doesn’t think about this property if it could make the choice primarily based by itself information. Particularly, the SQL engine ignores this property within the following conditions:
- If there may be aggregation, the SQL engine makes use of GROUP BY, not DISTINCT
- If there isn’t a attribute (solely metrics), the SQL engine doesn’t use DISTINCT
- If there may be COUNT (DISTINCT …) and the database doesn’t assist it, the SQL engine performs a SELECT DISTINCT cross after which a COUNT(*) cross
- If for sure chosen column information varieties, the database doesn’t permit DISTINCT or GROUP BY, the SQL engine doesn’t do it
- If the SELECT degree is identical because the desk key degree and the desk’s true key property is chosen, the SQL engine doesn’t problem a DISTINCT
When not one of the previous circumstances are met, the SQL engine makes use of the DISTINCT or GROUP BY property.
Use the most recent Amazon Redshift drivers
For working MicroStrategy stories utilizing Amazon Redshift, we encourage upgrading when new variations of the Amazon Redshift drivers can be found. Working an utility on the most recent driver offers higher efficiency, bugs restoration, and higher safety features. To get the most recent driver model primarily based on the OS, see Drivers and Connectors.
Conclusion
On this publish, we mentioned numerous Amazon Redshift cluster optimizations, information mannequin optimizations, and SQL optimizations inside MicroStrategy for optimizing your Amazon Redshift and MicroStrategy deployment.
Concerning the Authors
 Ranjan Burman is an Analytics Specialist Options Architect at AWS. He focuses on Amazon Redshift and helps clients construct scalable analytical options. He has greater than 13 years of expertise in numerous database and information warehousing applied sciences. He’s captivated with automating and fixing buyer issues with the usage of cloud options.
 Nita Shah is a Analytics Specialist Options Architect at AWS primarily based out of New York. She has been constructing information warehouse options for over 20 years and focuses on Amazon Redshift. She is concentrated on serving to clients design and construct enterprise-scale well-architected analytics and determination assist platforms.
 Bosco Albuquerque is a Sr Accomplice Options Architect at AWS and has over 20 years of expertise working with database and analytics merchandise from enterprise database distributors and cloud suppliers, and has helped massive know-how corporations design information analytics options in addition to led engineering groups in designing and implementing information analytics platforms and information merchandise.
 Amit Nayak is liable for driving the Gateways roadmap at MicroStrategy, specializing in relational and large information databases, in addition to authentication. Amit joined MicroStrategy after finishing his grasp’s in Enterprise Analytics at George Washington College and has maintained an oversight of the corporate’s gateways portfolio for the three+ years he has been with the corporate.
[ad_2]

