


[ad_1]
This put up is part of our weblog sequence on our frontend work. You’ll be able to see the earlier one on “Simplifying Information + AI, One Line of TypeScript at a Time.” and “Constructing the Subsequent Technology Visualization Instruments at Databricks.”
At Databricks, we take the standard of our buyer expertise very severely. As such, we observe many metrics for product reliability. One metric we concentrate on is the proportion of periods that see no JavaScript (JS) exceptions. Our objective is to maintain this completely satisfied case above 99.9%, however traditionally, these points have been tracked manually, which for a lot of causes wasn’t enough for protecting errors at bay.
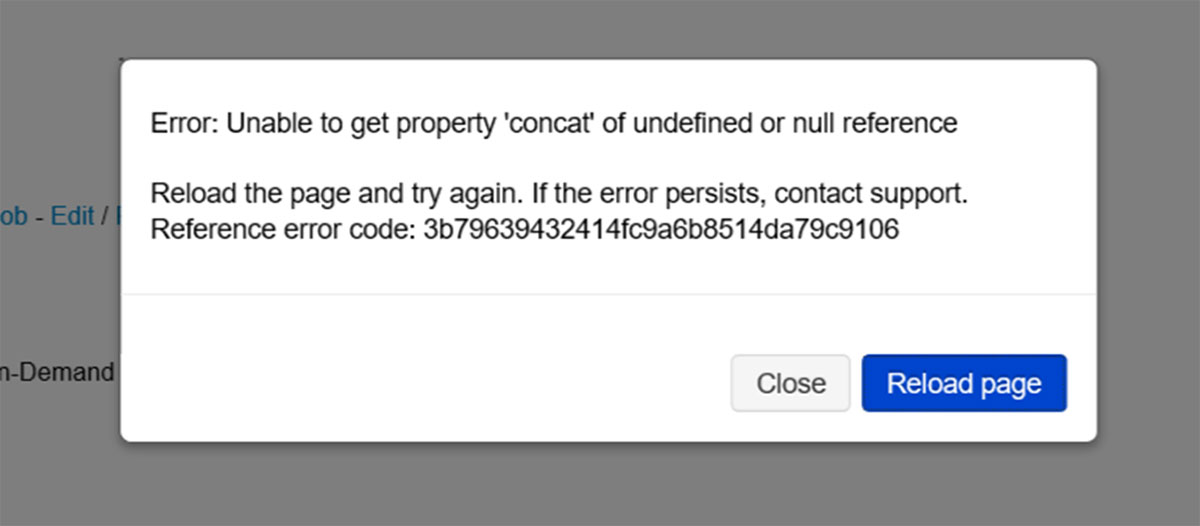
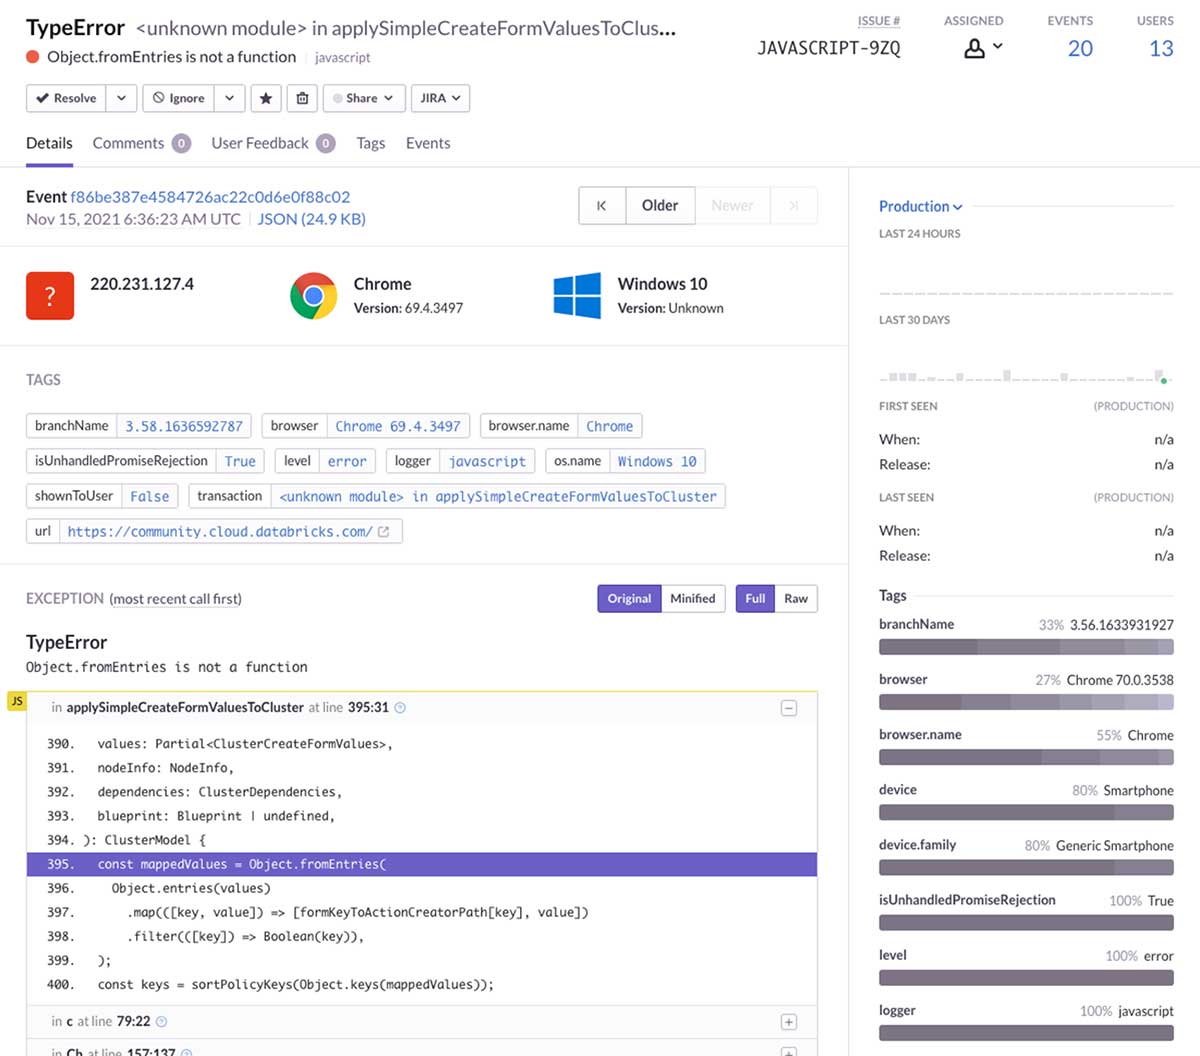
Previously, we used Sentry to mixture and categorize quite a lot of exceptions, together with these from JS. Sentry each ingests the errors and, on the entrance finish, aggregates sourcemaps to decode minified stack traces.
Utilizing Databricks to trace JS exceptions
Whereas contemplating how we might higher automate our exception monitoring and, thus, lower the variety of points being shipped out, we regarded into extending Sentry. Sadly, we discovered that the hassle required was excessive. As we regarded into what Sentry was fixing for our use case, we realized that Databricks’ merchandise might largely accomplish the identical duties, with a better path for extensibility.

First, Databricks is greater than a knowledge platform; it’s primarily a general-purpose computing and app infrastructure that sits on prime of your knowledge. This allows you to create an ETL the place you ingest all types of data and apply programmatic transformations, all from inside the internet product.
And when you’ve constructed that ETL, you should use the outcomes to construct dynamic dashboards, connect with third-party APIs or anything. Databricks even has GUIs to orchestrate pipelines of duties and handles alerting when something fails.
With that in thoughts, our problem was to construct an inside, maintainable pipeline for our JS exceptions, with the objective of robotically creating tickets each time we detected points in staging or manufacturing.
Transferring from Sentry to Databricks
Aggregating into Delta
Step one in setting up our ETL was to seek out our supply of reality. This was our usage_logs desk, which accommodates all kinds of various logs and metrics for buyer interactions with the product. Each JS exception was saved right here with the minified stack traces.
We began by constructing a Databricks Pocket book to course of our usage_logs. This desk is gigantic and troublesome to optimize, so querying it for exceptions can take thirty minutes or extra. So, we aggregated the info we needed right into a standalone Delta Desk, which enabled us to question and slice the info (roughly a 12 months’s price of exceptions) in seconds.
Information enrichment: stack hint decoding
Critically, we would have liked to discover a strategy to decode the minified stack traces in our usage_logs as part of the ETL. This is able to tell us what file and line brought about a given difficulty and take additional steps to counterpoint the exception based mostly on that information.

Step one right here was to retailer our sourcemaps in an AWS S3 bucket as part of our construct. Databricks helpfully offers you the power to mount S3 buckets into your workspace’s file system, which makes these sourcemaps easily-accessible to our code.
As soon as we had the sourcemaps in S3, we had the power to decode the stack traces on Databricks. This was finished solely in Databricks Notebooks, which have the power to put in Python libraries through pip. We put in the sourcemap bundle to deal with the decode, then constructed a small Python script to guage a given stacktrace and fetch the related sourcemaps from the file system.

As soon as we had that, we wrapped the script in a UDF in order that we might run it straight from SQL queries in our notebooks! This gave us the power to decode the stack hint and return the file that brought about the error, the road and context of supply code, and the decoded stack itself, all of which have been saved in separate columns.
Code possession
As soon as we decoded the stack traces, we had excessive confidence on which file was accountable for every error and will use that to find out which crew owned the difficulty. To do that, we used Github’s API to crawl the repository, discover the closest OWNERS file and map the proudly owning crew to a JIRA part.
We constructed this into one other UDF and added it to our aggregator, so when an exception got here in, it was pre-triaged to the proper crew!
Databricks SQL dashboards
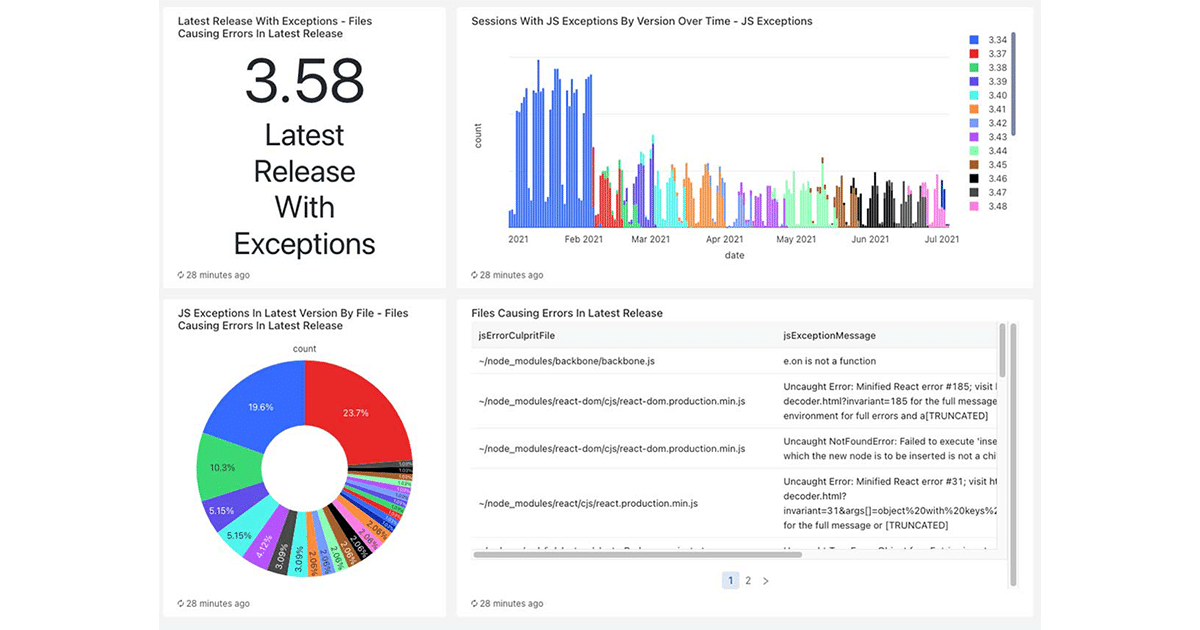
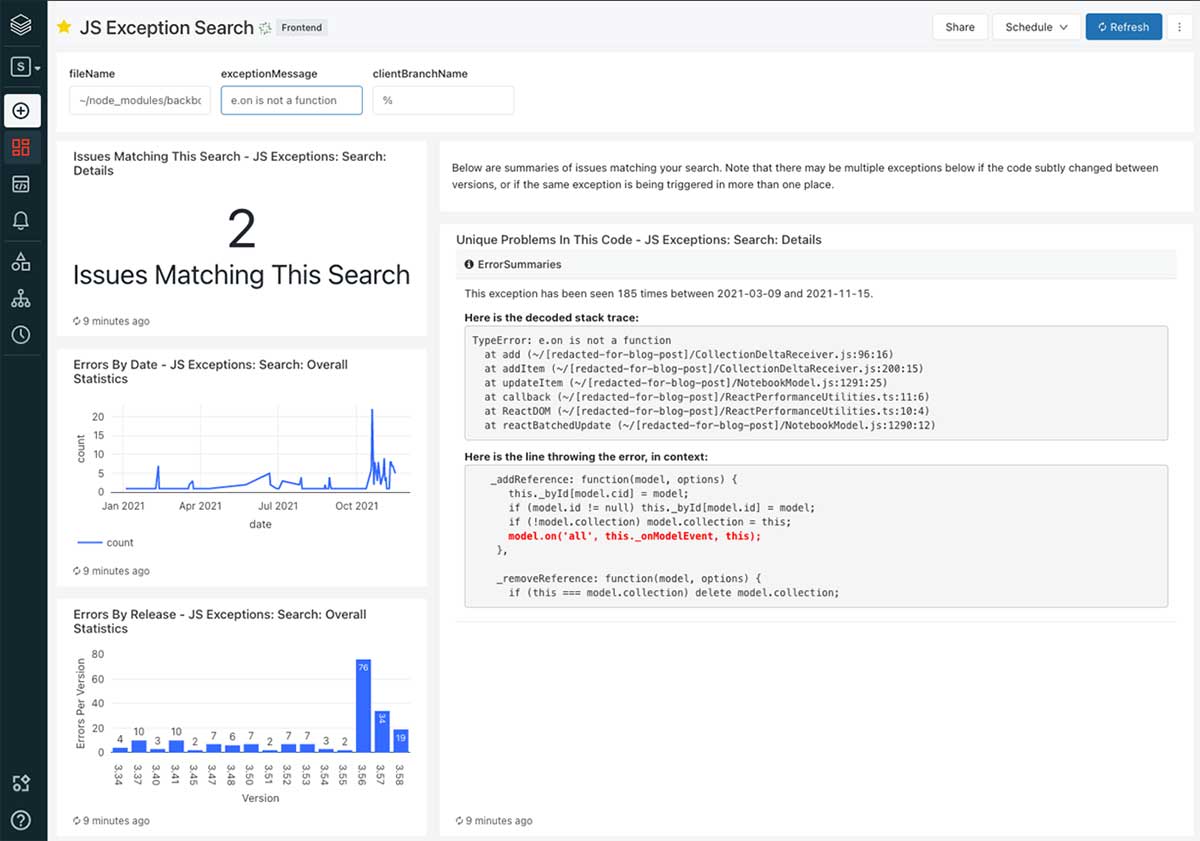
To achieve visibility into what was occurring within the product, we used Databricks SQL to construct dashboards for high-level metrics. This helped us visualize tendencies and captured the fine-grain points occurring within the present launch.
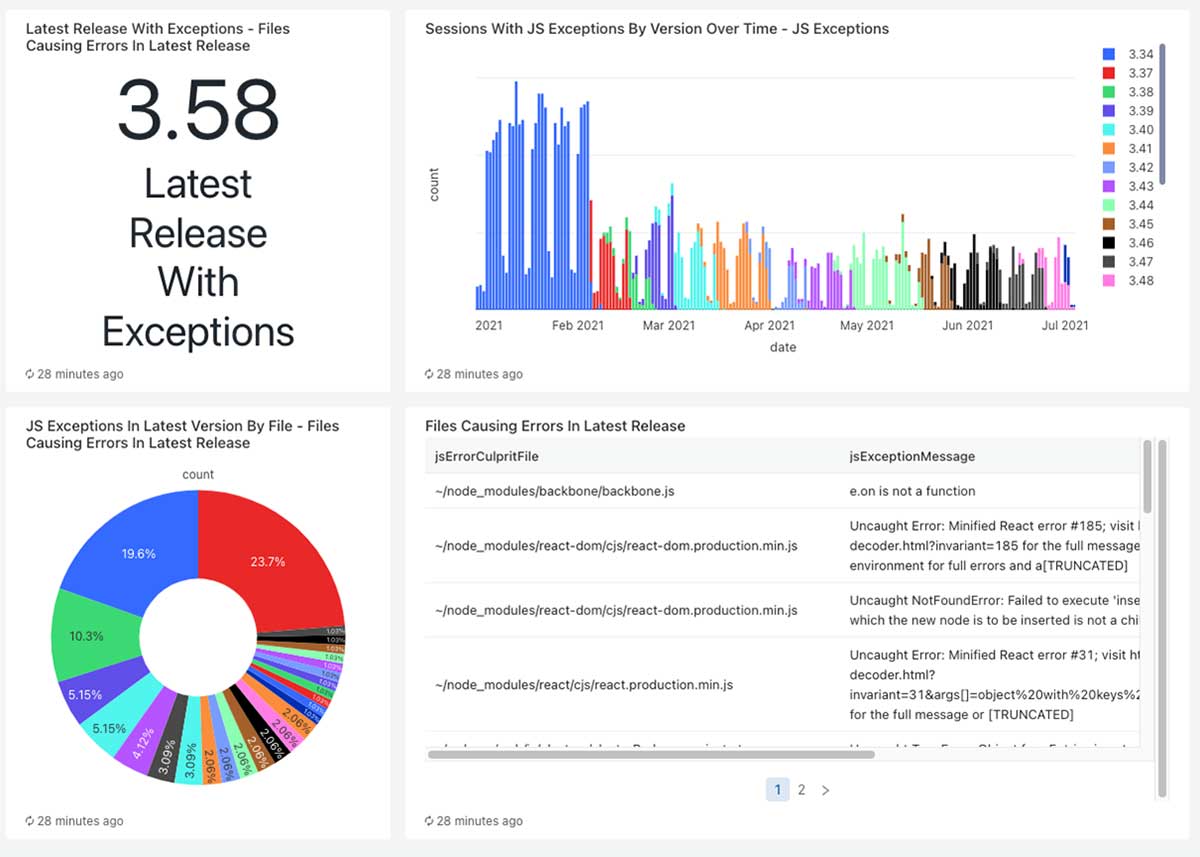
We additionally constructed dashboards for analyzing explicit points, which present error frequency, variations of the error and extra. This, in impact, replaces Sentry’s UI, and we will increase it to supply whichever knowledge is essentially the most related to our firm.
Ticketing
As soon as we had our ETL constructed and populated, we regarded on the incident frequency in staging and manufacturing relative to the variety of Databricks customers in these environments. We determined that it made sense to robotically increase a JIRA ticket anytime an exception occurred in staging, whereas in manufacturing, we set the brink at ten distinct periods throughout a launch.
This instantly raised dozens of tickets. The bulk have been indirectly or one other identified however have been all low sufficient impression that the crew hadn’t tackled them. In mixture, nonetheless, dozens of small tickets have been tremendously regressing our expertise. Round this time, we calculated that 20% of periods noticed no less than one error!
With all the info we might pull and enrich, our engineers have been in a position to successfully soar proper right into a repair quite than wading by totally different companies and logs to get the data they wanted to behave. Because of this, we shortly burned down a big portion of our points and received again above our 99.9% error-free objective.

Activity orchestration with Jobs
When executing our pipeline, we’ve one pocket book that handles the ETL and one other that compares the state of the delta desk to JIRA and opens any essential points. Operating these requires some orchestration, however fortunately, Databricks Jobs makes it straightforward to deal with this.
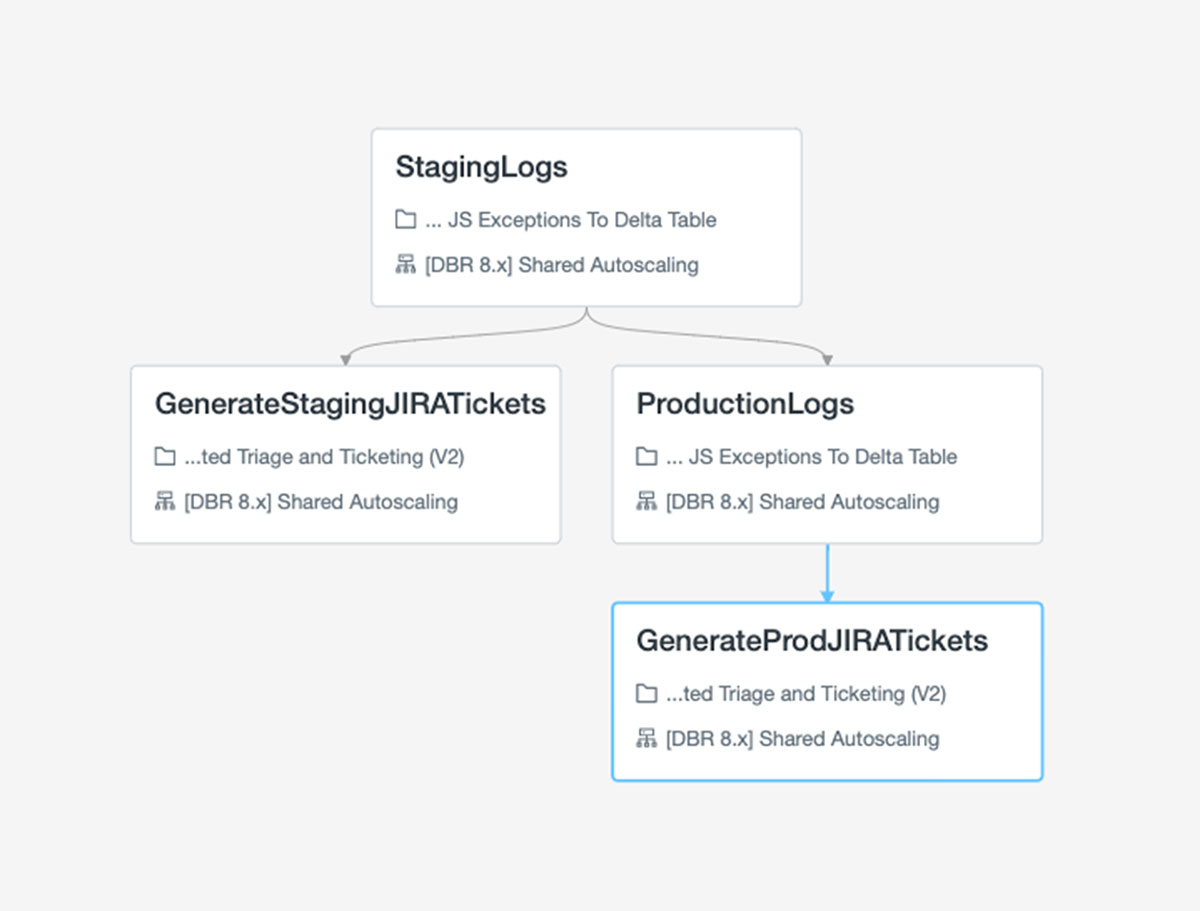
With Jobs, we will run these notebooks for staging and manufacturing in sequence. That is very straightforward to arrange within the internet GUI to deal with routing of failures to our crew’s alert inbox.
Closing ideas
General, the merchandise we’ve been constructing at Databricks are extremely highly effective and provides us the aptitude to construct bespoke monitoring and analytics for something we’re engaged on. We’re utilizing processes like these to watch frontend efficiency, hold observe of React part utilization, handle dashboards for code migrations and rather more.
Initiatives like this one current us with a possibility to make use of our merchandise as a buyer would, to really feel their ache and pleasure and to provide different groups the suggestions they should make Databricks even higher.
If engaged on a platform like this sounds attention-grabbing, we’re hiring! There’s an unimaginable number of frontend work being finished and being deliberate, and we might use your assist. Come and be a part of us!
[ad_2]

