


[ad_1]
Information is being produced, streamed, and consumed at an immense price, and that price is projected to develop exponentially sooner or later. Particularly, JSON is probably the most extensively used information format throughout streaming applied sciences and workloads. As functions, web sites, and machines more and more undertake information streaming applied sciences corresponding to Apache Kafka and Amazon Kinesis Information Streams, which function a extremely obtainable transport layer that decouples the info producers from information shoppers, it may turn into progressively more difficult for groups to coordinate and evolve JSON Schemas. Including or eradicating a discipline or altering the info sort on a number of current fields might introduce information high quality points and downstream utility failures with out cautious information dealing with. Groups depend on customized instruments, complicated code, tedious processes, or unreliable documentation to guard in opposition to these schema modifications. This places heavy dependency on human oversight, which may make the change administration processes error-prone. A typical resolution is a schema registry that allows information producers and shoppers to carry out validation of schema modifications in a coordinated vogue. This enables for risk-free evolution as enterprise calls for change over time.
The AWS Glue Schema Registry, a serverless function of AWS Glue, now lets you validate and reliably evolve streaming information in opposition to JSON Schemas. The Schema Registry is a free function that may considerably enhance information high quality and developer productiveness. With it, you possibly can eradicate defensive coding and cross-team coordination, scale back downstream utility failures, and use a registry that’s built-in throughout a number of AWS providers. Every schema could be versioned inside the guardrails of a compatibility mode, offering builders the pliability to reliably evolve JSON Schemas. Moreover, the Schema Registry can serialize information right into a compressed format, which helps you save on information switch and storage prices.
This put up reveals you the best way to use the Schema Registry for JSON Schemas and gives examples of the best way to use it with each Kinesis Information Streams and Apache Kafka or Amazon Managed Streaming for Apache Kafka (Amazon MSK).
Overview of the answer
On this put up, we stroll you thru an answer to retailer, validate, and evolve a JSON Schema within the AWS Glue Schema Registry. The schema is utilized by Apache Kafka and Kinesis Information Streams functions whereas producing and consuming JSON objects. We additionally present you what occurs when a brand new model of the schema is created with a brand new discipline.
The next diagram illustrates our resolution workflow:
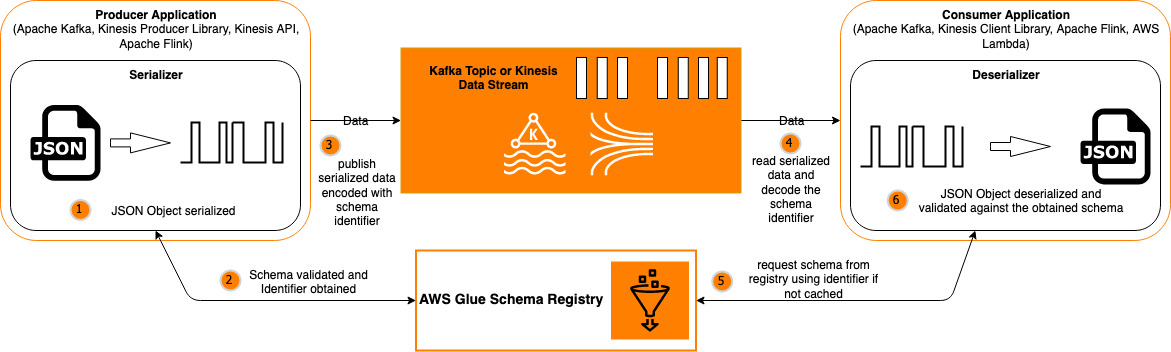
The steps to implement this resolution are as follows:
- Create a brand new registry and register a schema utilizing an AWS CloudFormation template.
- Create a brand new model of the schema utilizing the AWS Glue console that’s backward-compatible with the earlier model.
- Construct a producer utility to do the next:
- Generate JSON objects that adhere to one of many schema variations.
- Serialize the JSON objects into an array of bytes.
- Get hold of the corresponding schema model ID from the Schema Registry and encode the byte array with the identical.
- Ship the encoded byte array by means of a Kinesis information stream or Apache Kafka matter.
- Construct a client utility to do the next:
- Obtain the encoded byte array by means of a Kinesis information stream or Apache Kafka matter.
- Decode the schema model ID and procure the corresponding schema from the Schema Registry.
- Deserialize the array of bytes into the unique JSON object.
- Eat the JSON object as wanted.
Description of the schema used
For this put up, we begin with the next schema. The schema is of a climate report object that incorporates three fundamental items of knowledge: location, temperature, and timestamp. All three are required fields, however the schema does permit further fields (indicated by the additionalProperties flag) corresponding to windSpeed or precipitation if the producer needs to incorporate them. The location discipline is an object with two string fields: metropolis and state. Each are required fields and the schema doesn’t permit any further fields inside this object.
Utilizing the above schema, a sound JSON object would appear like this:
Deploy with AWS CloudFormation
For a fast begin, you possibly can deploy the supplied CloudFormation stack. The CloudFormation template generates the next assets in your account:
- Registry – A registry is a container of schemas. Registries assist you to manage your schemas, in addition to handle entry management in your functions. A registry has an Amazon Useful resource Title (ARN) to assist you to manage and set completely different entry permissions to schema operations inside the registry.
- Schema – A schema defines the construction and format of a knowledge report. A schema is a versioned specification for dependable information publication, consumption, or storage. Every schema can have a number of variations. Versioning is ruled by a compatibility rule that’s utilized on a schema. Requests to register new schema variations are checked in opposition to this rule by the Schema Registry earlier than they will succeed.
To manually create these assets with out utilizing AWS CloudFormation, seek advice from Making a Registry and Making a Schema.
Stipulations
Be certain that to finish the next steps as conditions:
- Create an AWS account. For this put up, you configure the required AWS assets within the
us-east-1orus-west-2Area. In case you haven’t signed up, full the next duties:- Create an account. For directions, see Signal Up for AWS.
- Create an AWS Id and Entry Administration (IAM) person. For directions, see Creating an IAM Person in your AWS account.
- Select Launch Stack to launch the CloudFormation stack:
Overview the newly registered schema
Let’s assessment the registry and the schema on the AWS Glue console.
- Register to the AWS Glue console and select the suitable Area.
- Below Information Catalog, select Schema registries.
- Select the
GsrBlogRegistryschema registry. - Select the
GsrBlogSchemaschema. - Select Model 1.
We will see the JSON Schema model particulars and its definition. Word that the compatibility mode chosen is Backward compatibility. We see the aim of that within the subsequent part.

Evolve the schema by creating a brand new backward-compatible model
On this part, we take what’s created to this point and add a brand new schema model to show how we are able to evolve our schema whereas preserving the integrity intact.
So as to add a brand new schema model, full the next steps, persevering with from the earlier part:
- On the Schema model particulars web page, select Register new model.
- Contained in the
propertiesobject inside thelocationobject (after thestatediscipline), add a brand newnationdiscipline as follows:
As a result of the compatibility mode chosen for the schema is backward compatibility, it’s vital that we don’t make this new discipline a required discipline. If we try this, the Schema Registry fail this new model.
- Select Register model.
We now have a brand new model of the schema that permits the producers to incorporate an non-obligatory nation discipline inside the location object in the event that they select to.
Use the AWS Glue Schema Registry
On this part, we stroll by means of the steps to make use of the Schema Registry with Kinesis Information Streams or Apache Kafka.
Stipulations
Be certain that to finish the next steps as conditions:
- Configure your AWS credentials in your native machine.
- Set up Maven on the native machine.
- Obtain the appliance code from the GitHub repo.
- Construct the bundle:
Use the Schema Registry with Kinesis Information Streams
Run the Kinesis producer code to supply JSON messages which might be related to a schema ID assigned by the Schema Registry:
This command returns the next output:
Run the Kinesis client code to obtain JSON messages with the schema ID, receive the schema from the Schema Registry, and validate:
This command returns the next output with the JSON information obtained and decoded:
Use the Schema Registry with Apache Kafka
Within the root of the downloaded GitHub repo folder, create a config file with the connection parameters for the Kafka cluster:
Run the Kafka producer code to supply JSON messages which might be related to a schema ID assigned by the Schema Registry:
This command returns the next output:
Run the Kafka client code to eat JSON messages with the schema ID, receive the schema from the Schema Registry, and validate:
This command returns the next output with the JSON information obtained and decoded:
Clear up
Now to the ultimate step, cleansing up the assets. Delete the CloudFormation stack to take away any assets you created as a part of this walkthrough.
Schema Registry options
Let’s talk about the options the Schema Registry has to supply:
- Schema discovery – When a producer registers a schema change, metadata could be utilized as a key-value pair to supply searchable data for directors or builders. This metadata can point out the unique supply of the info (
supply=MSK_west), the workforce’s title to contact (proprietor=DataEngineering), or AWS tags (atmosphere=Manufacturing). You would doubtlessly encrypt a discipline in your information on the manufacturing shopper and use metadata to specify to potential client shoppers which public key fingerprint to make use of for decryption. - Schema compatibility – The versioning of every schema is ruled by a compatibility mode. If a brand new model of a schema is requested to be registered that breaks the desired compatibility mode, the request fails, and an exception is thrown. Compatibility checks allow builders constructing downstream functions to have a bounded set of eventualities to construct functions in opposition to, which helps put together for the modifications with out concern. Generally used modes are FORWARD, BACKWARD, and FULL. For extra details about mode definitions, see Schema Versioning and Compatibility.
- Schema validation – Schema Registry serializers work to validate that the info produced is appropriate with the assigned schema. If it isn’t, the info producer receives an exception from the serializer. This ensures that doubtlessly breaking modifications are discovered earlier in improvement cycles and may assist stop unintentional schema modifications on account of human error.
- Auto-registration of schemas – If configured to take action, the info producer can auto-register schema modifications as they circulation within the information stream. That is particularly useful to be used circumstances the place the supply of the info is generated by a change information seize course of (CDC) from the database.
- IAM help – Because of built-in IAM help, solely approved producers can change sure schemas. Moreover, solely these shoppers approved to learn the schema can achieve this. Schema modifications are usually carried out intentionally and with care, so it’s vital to make use of IAM to manage who performs these modifications. Moreover, entry management to schemas is vital in conditions the place you might need delicate data included within the schema definition itself. Within the earlier examples, IAM roles are inferred through the AWS SDK for Java, so they’re inherited from the Amazon Elastic Compute Cloud (Amazon EC2) occasion’s position that the appliance runs on, if utilizing Amazon EC2. You too can apply IAM roles to every other AWS service that would include this code, corresponding to containers or AWS Lambda features.
- Secondary deserializer – When you’ve got already registered schemas in one other schema registry, there’s an choice for specifying a secondary deserializer when performing schema lookups. This enables for migrations from different schema registries with out having to begin another time. Any schema ID that’s unknown to the Schema Registry is appeared up within the registry tied to the secondary deserializer.
- Compression – Utilizing a schema registry can scale back information payload by now not needing to ship and obtain schemas with every message. Schema Registry libraries additionally present an choice for zlib compression, which may scale back information necessities even additional by compressing the payload of the message. This varies by use case, however compression can scale back the scale of the message considerably.
- A number of information codecs – The Schema Registry at the moment helps AVRO (v1.10.2) information format, JSON information format with JSON Schema format for the schema (specs Draft-04, Draft-06, and Draft-07), and Java language help, with different information codecs and languages to return.
Conclusion
On this put up, we mentioned the advantages of utilizing the AWS Glue Schema Registry to register, validate, and evolve JSON Schemas for information streams as enterprise wants change. We additionally supplied examples of the best way to use the Schema Registry.
Study extra about Integrating with AWS Glue Schema Registry.
Concerning the Writer
 Aditya Challa is a Senior Options Architect at Amazon Net Providers. Aditya loves serving to prospects by means of their AWS journeys as a result of he is aware of that journeys are at all times higher when there’s firm. He’s an enormous fan of journey, historical past, engineering marvels, and studying one thing new daily.
[ad_2]

