


[ad_1]
Many AWS clients depend on a multi-account technique to scale their group and higher handle their information lake throughout completely different initiatives or traces of enterprise. The AWS Glue Information Catalog incorporates references to information used as sources and targets of your extract, remodel, and cargo (ETL) jobs in AWS Glue. Utilizing a centralized Information Catalog presents organizations a unified metadata repository and minimizes the executive overhead associated to sharing information throughout completely different accounts, thereby increasing entry to the info lake.
Amazon Athena is among the widespread decisions to run analytical queries in information lakes. This interactive question service makes it simple to research information in Amazon Easy Storage Service (Amazon S3) utilizing customary SQL. Athena is serverless, so there is no such thing as a infrastructure to handle, and also you’re charged based mostly on the quantity of information scanned by your queries.
In Might 2021, Athena launched the power to question Information Catalogs throughout a number of AWS accounts, enabling you to entry your information lake with out the complexity of replicating catalog metadata in particular person AWS accounts. This weblog put up particulars the process for utilizing the characteristic.
Answer overview
The next diagram exhibits the required parts utilized in two completely different accounts (shopper account and producer account, internet hosting a central Information Catalog) and the circulate between the 2 for cross-account Information Catalog entry utilizing Athena.

Our use case showcases Information Catalog sharing between two accounts:
- Producer account – The account that administrates the central Information Catalog
- Client account – The account querying information from the producer’s Information Catalog (the central Information Catalog)
On this walkthrough, we use the next two tables, extracted from an ecommerce dataset:
- The orders desk logs the web site’s orders and incorporates the next key attributes:
- Row ID – Distinctive entry identifier within the orders desk
- Order ID – Distinctive order identifier
- Order date – Date the order was positioned
- Revenue – Revenue worth of the order
- The returns desk logs the returned objects and incorporates the next attributes:
- Returned – If the order has been returned (Sure/No)
- Order ID – Distinctive order identifier
- Market – Area market
We stroll you thru the next high-level steps to make use of this answer:
- Arrange the producer account.
- Arrange the buyer account.
- Arrange permissions.
- Register the producer account within the Information Catalog.
- Question your information.
You utilize Athena within the shopper account to carry out completely different operations utilizing the producer account’s Information Catalog.
First, you utilize the buyer account to question the orders desk within the producer account’s Information Catalog.

Subsequent, you utilize the buyer account to affix the 2 tables and retrieve details about misplaced revenue from returned objects. The returns desk is within the shopper’s Information Catalog, and the orders desk is within the producer’s.

Stipulations
The next are the stipulations for this walkthrough:

This lists all of your Athena workgroups. Make it possible for the one you utilize runs on Athena engine model 2.
If all of your workgroups are utilizing Athena engine model 1, you have to replace the engine model of an present workgroup or create a brand new workgroup with the suitable model.
Arrange the producer account
Within the producer account, full the next steps:
- Create an S3 bucket in your producer’s information. For details about learn how to safe your S3 bucket, see Safety Finest Practices for Amazon S3.
- On this bucket, create a prefix named
orders. - Obtain the orders desk in CSV format and add it to the
ordersprefix. - Run the next Athena question to create the producer’s database:
- Run the next Athena question to create the orders desk within the producer’s database. Ensure to exchange <your-producer-s3-bucket-name> with the identify of the bucket you created.
Arrange the buyer account
Within the shopper account, full the next steps:
- Create an S3 bucket in your shopper’s information.
- On this bucket, create a prefix named
returns. - Obtain the returns desk in CSV format and add it to the
returnsprefix. - Run the next Athena question to create the buyer’s database:
- Run the next Athena question to create the returns desk within the shopper’s database. Ensure to exchange <your-consumer-s3-bucket-name> with the identify of the bucket you created.
Arrange permissions
For the buyer account to question information within the producer account, we have to arrange permissions.
First, we give the buyer account permission to entry the producer account’s AWS Glue sources.
- Within the producer account’s Information Catalog settings, add the next AWS Glue useful resource coverage, which grants the buyer account entry to the Information Catalog:

Subsequent, we give the buyer account permission to listing and get information from the S3 bucket within the producer account.
- Within the producer account, add the next S3 bucket coverage to the bucket <Producer-bucket>, which shops the info:
Register the producer account’s Information Catalog
At this stage, you might have arrange the required permissions to entry the central Information Catalog within the producer account from the buyer account. You now have to register the central Information Catalog as a knowledge supply in Athena.
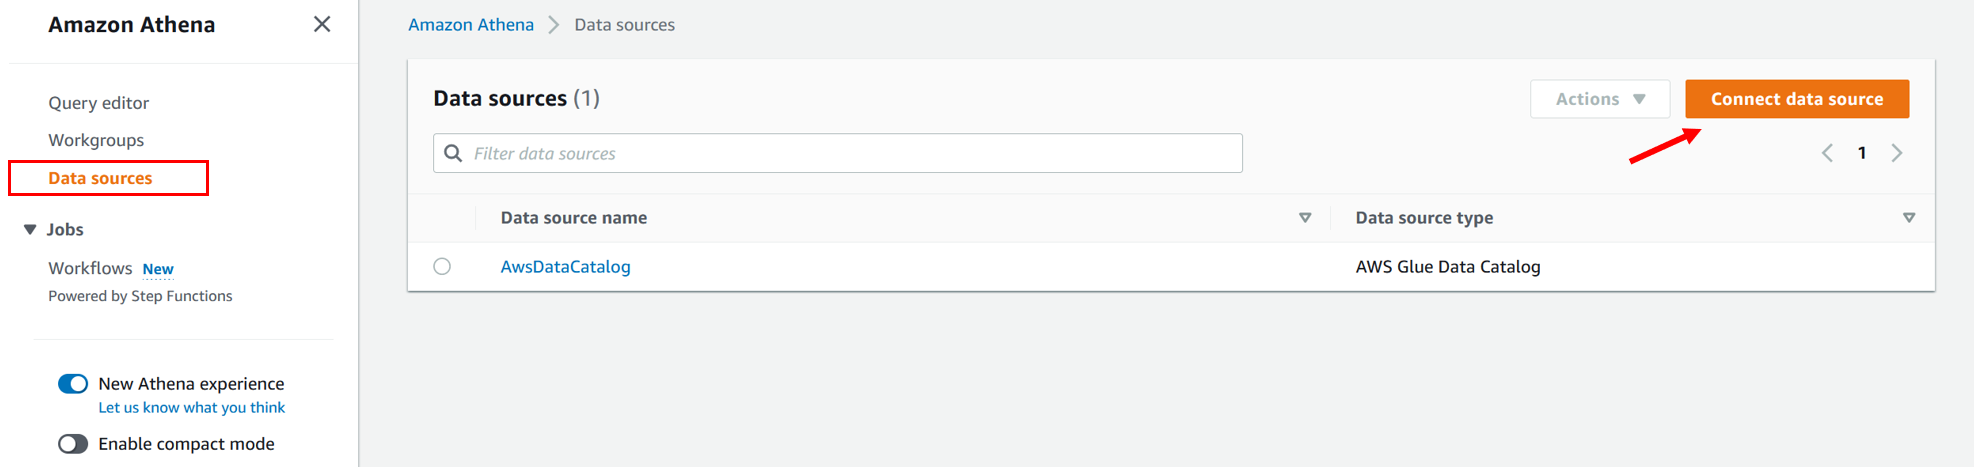
- Within the shopper account, go the Athena console and select Join information supply.
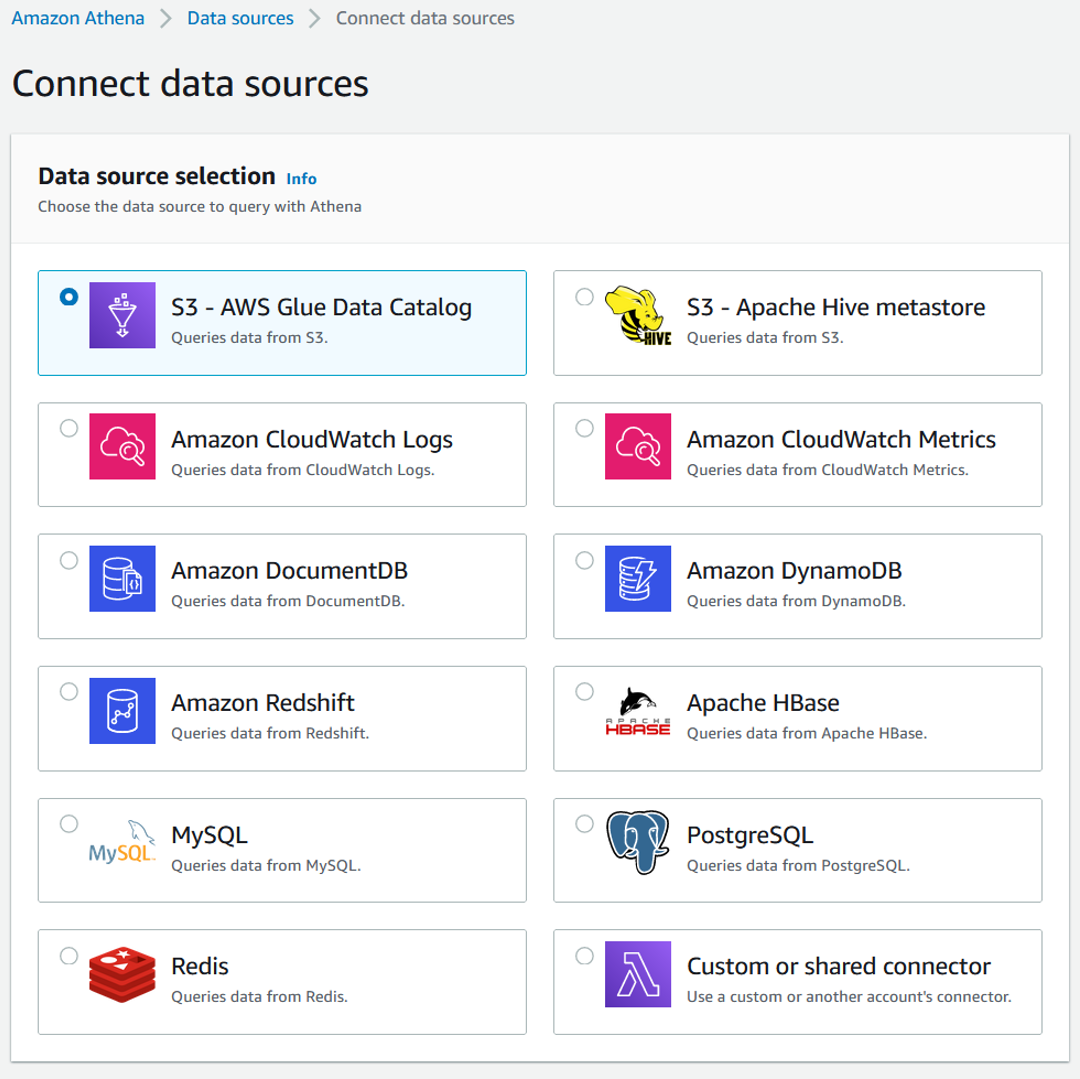
- Choose S3 – AWS Glue Information Catalog as the info supply choice.
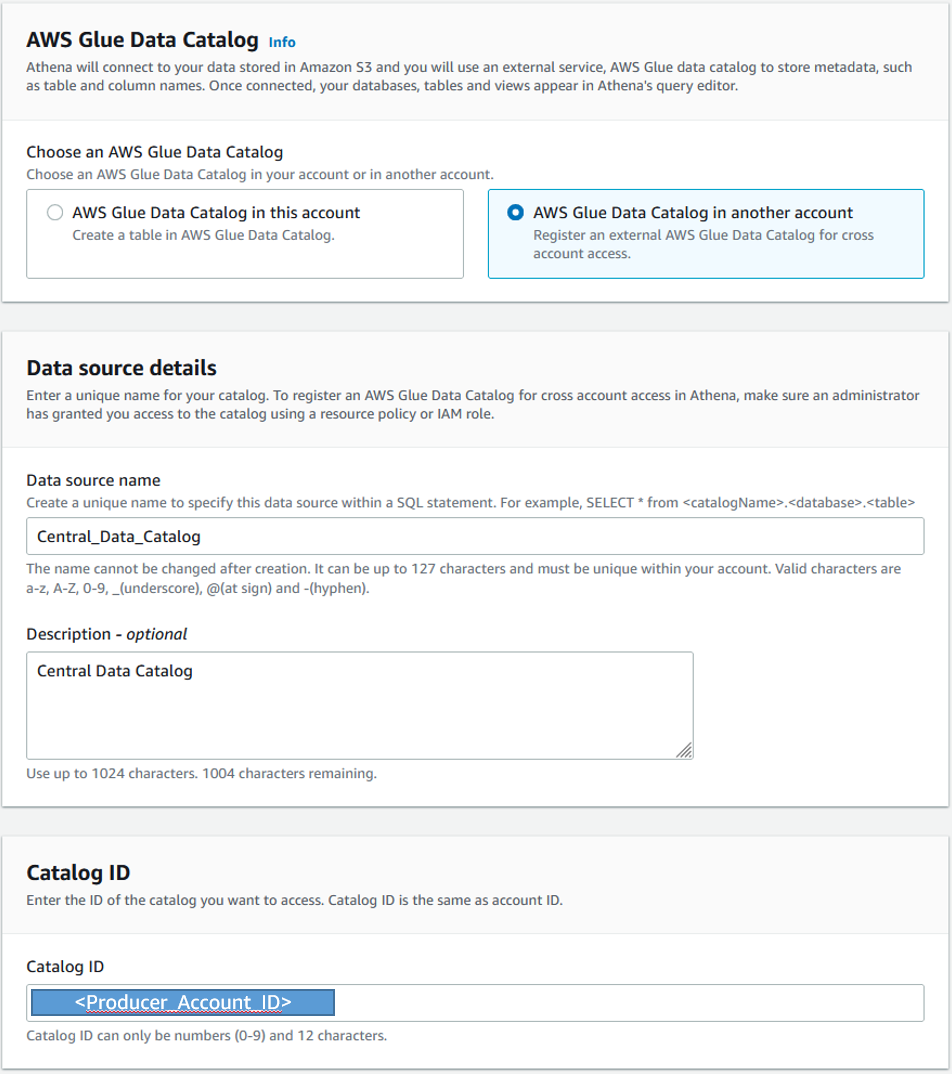
- Choose AWS Glue Information Catalog in one other account.
You then want to offer some data relating to the central Information Catalog you need to register.
- For Information supply identify, enter a reputation for the catalog (for instance,
Central_Data_Catalog). This serves as an alias within the shopper account, pointing to the central Information Catalog within the producer account.
- For Catalog ID, enter the producer account ID.
- Select Register to finish the method.
Question your information
You’ve got now registered the central Information Catalog as a knowledge supply within the shopper account. Within the Athena question editor, you possibly can then select Central_Data_Catalog as a knowledge supply. Underneath Database, you possibly can see all of the databases for which you had been granted entry within the producer account’s AWS Glue useful resource coverage. The identical applies for the tables. After finishing the steps within the earlier sections, you need to see the orders desk from producer_database positioned within the producer account.
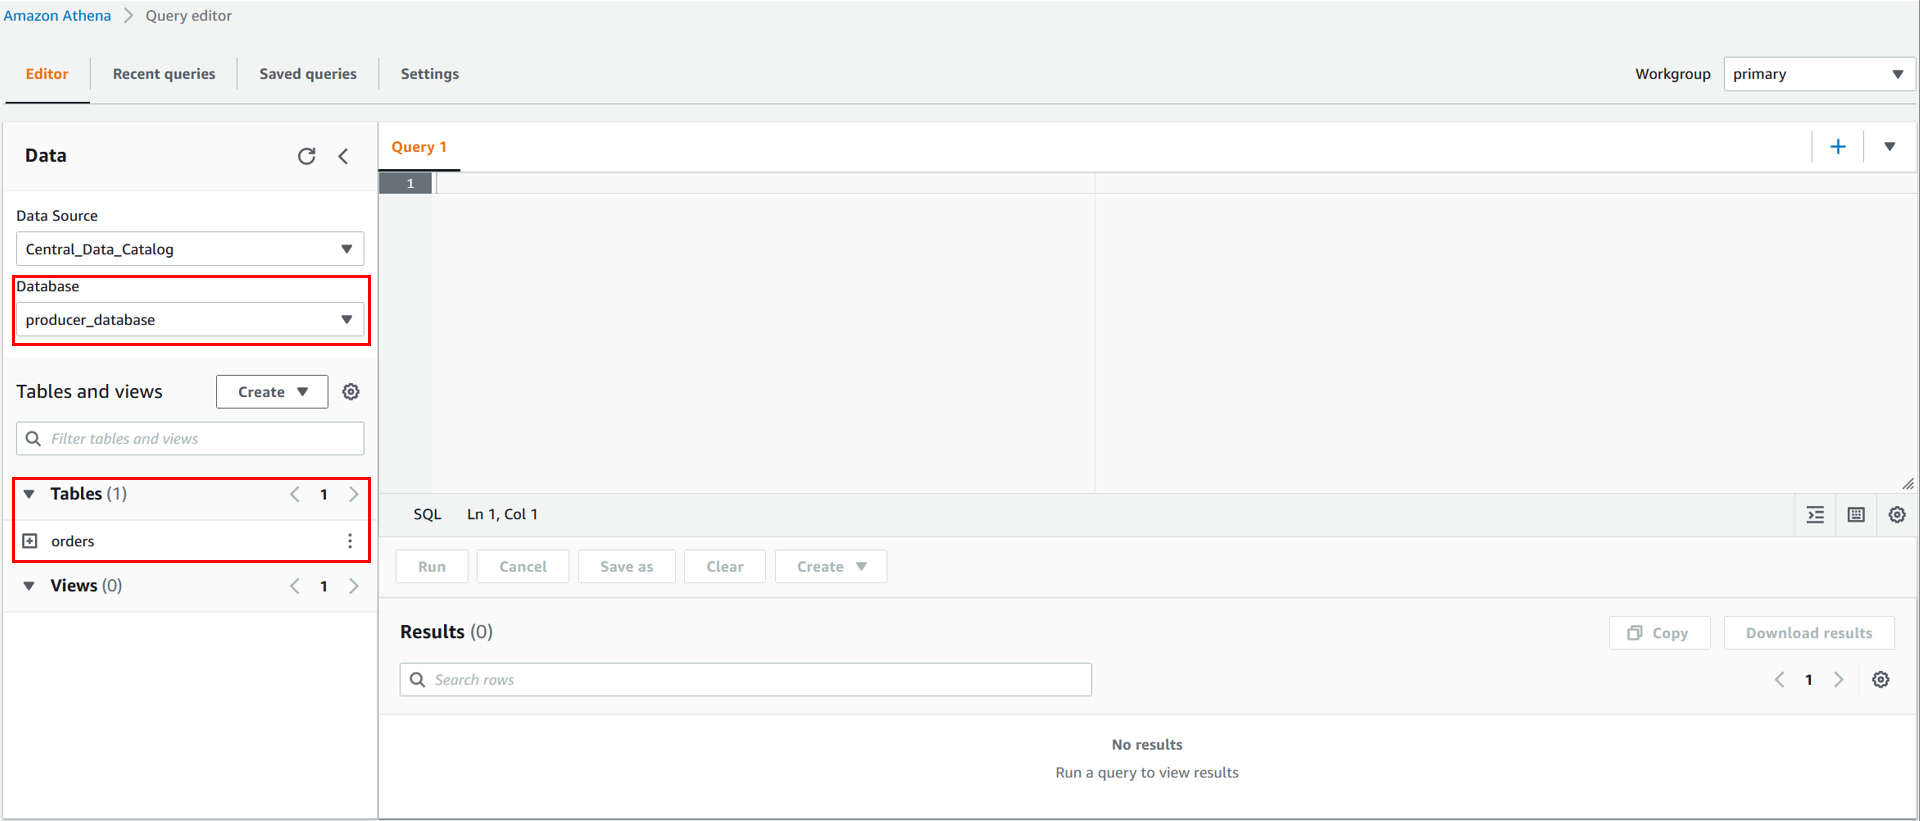
You can begin querying the Information Catalog of the producer account straight from Athena within the shopper account. You possibly can take a look at this by working the next SQL question in Athena:
This SQL question extracts the primary 10 rows of the orders desk positioned within the producer account.
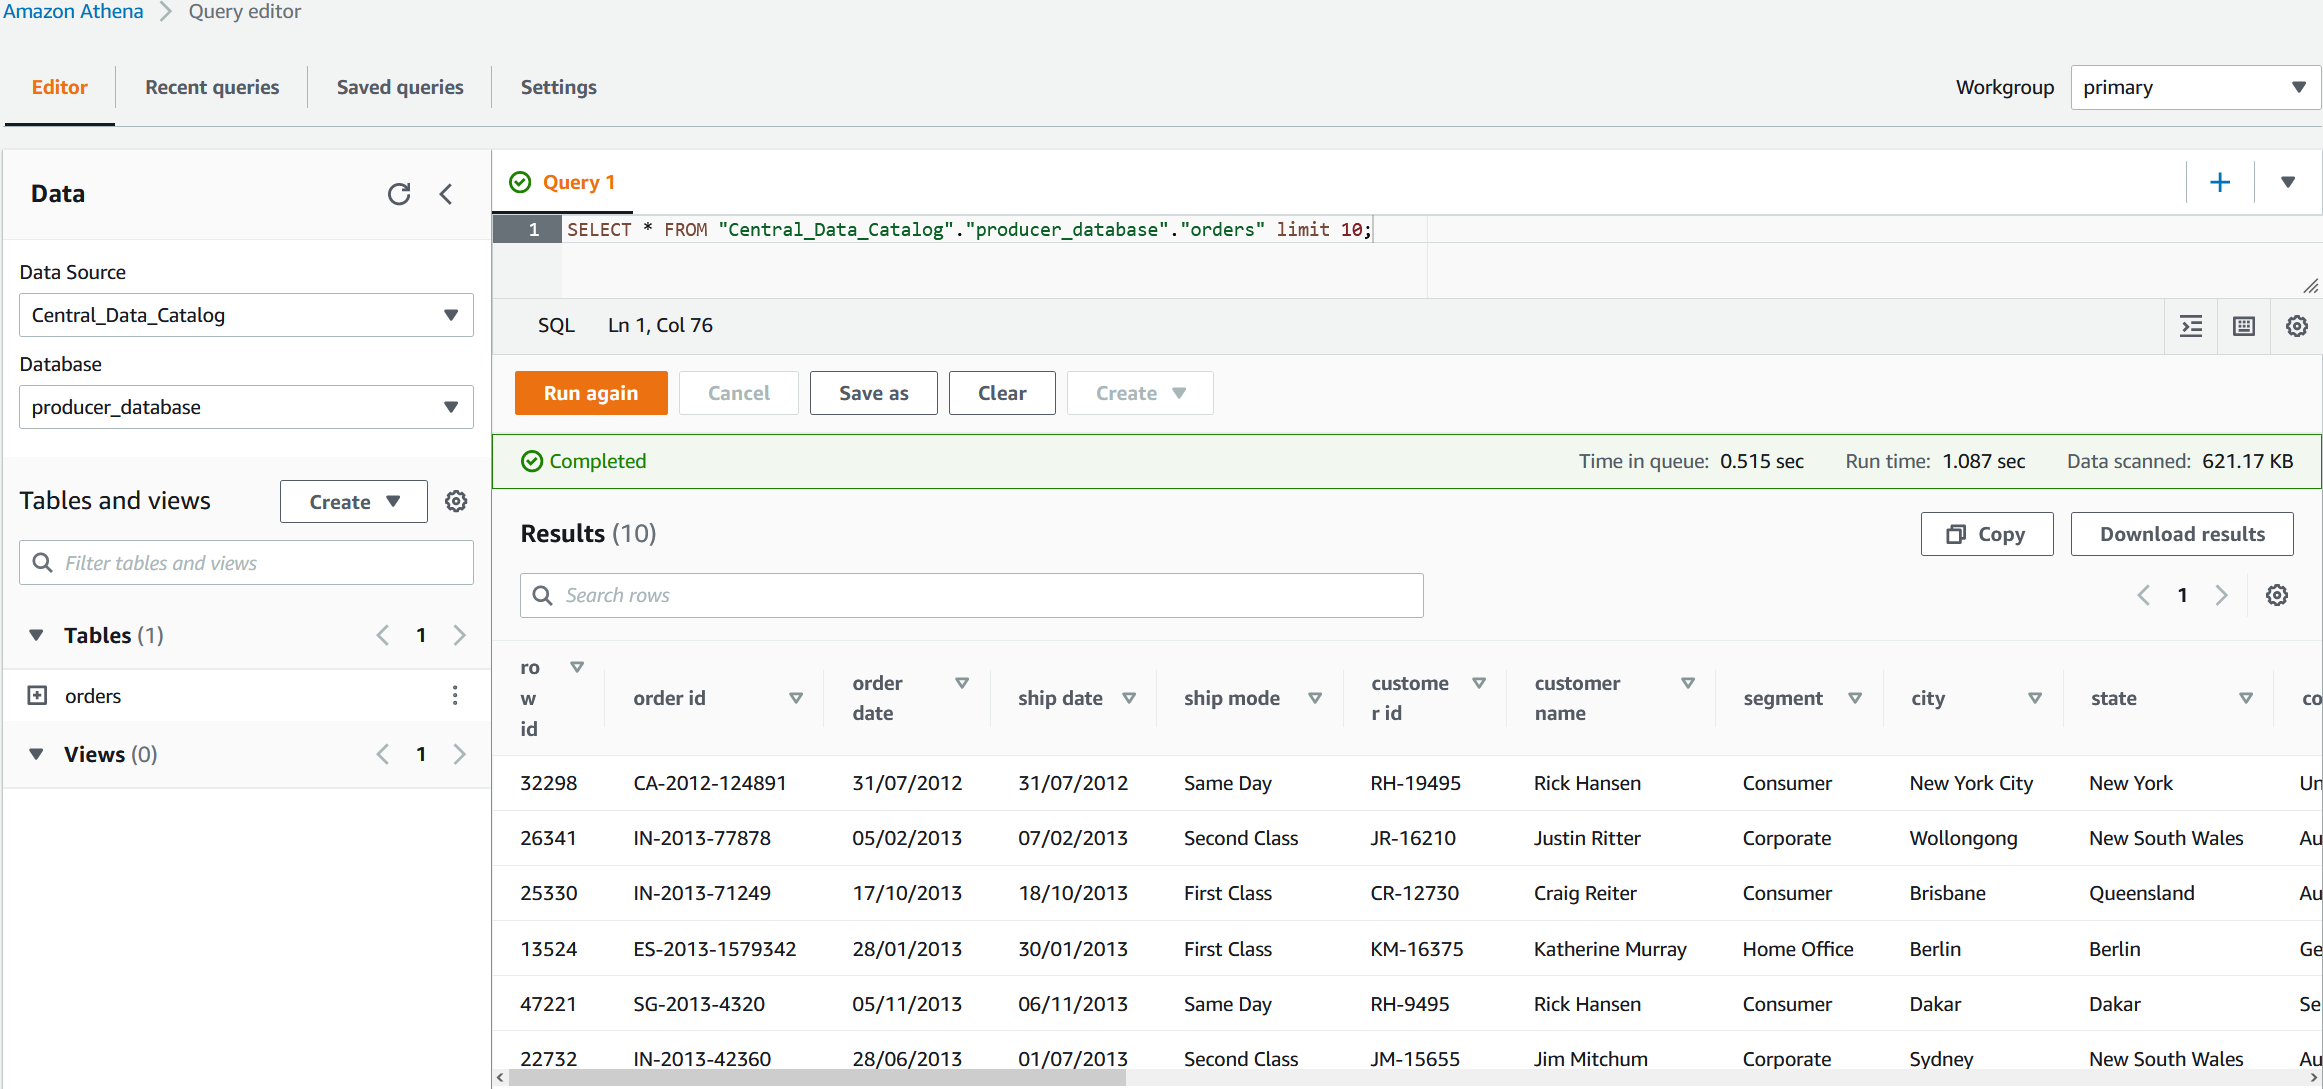
You simply queried a Information Catalog positioned in one other AWS account, which allows you to simply entry your central Information Catalog and scale your information lake technique.
Now, let’s see how we will be part of two tables which are in several AWS accounts. In our state of affairs, the returns desk is within the shopper account and the orders desk is within the producer account. Suppose you need to be part of the 2 tables and see the overall quantity of things returned in every market. The Athena built-in help for cross-account Information Catalogs makes this operation simple. Within the Athena question editor, run the next SQL question:
On this SQL question, you utilize each the buyer’s Information Catalog AwsDataCatalog and the producer’s Information Catalog Central_Data_Catalog to affix tables and get insights out of your information.
Limitations and concerns
The next are some limitations that you need to take into accounts earlier than utilizing Athena built-in help for cross-account Information Catalogs:
- This Athena characteristic is on the market solely in Areas the place Athena engine model 2 is supported. For an inventory of Areas that help Athena engine model 2, see Athena engine model 2. To improve a workgroup to engine model 2, see Altering Athena Engine Variations.
- As of this writing, CREATE VIEW statements that embody a cross-account Information Catalog will not be supported.
- Cross-Area Information Catalog queries will not be supported.
Clear up
After you question and analyze the info, you need to clear up the sources used on this tutorial to forestall any recurring AWS prices.
To scrub up the sources, navigate to the Amazon S3 console in each the supplier and shopper accounts, and empty the S3 buckets. Additionally, navigate to the AWS Glue console and delete the databases.
Conclusion
On this put up, you realized learn how to question information from a number of accounts utilizing Athena, which permits your group to entry to a centralized Information Catalog. We hope that this put up helps you construct and discover your information lake throughout a number of accounts.
To study extra about AWS instruments to handle entry to your information, take a look at AWS Lake Formation. This service facilitates establishing a centralized information lake and lets you grant customers and ETL jobs cross-account entry to Information Catalog metadata and underlying information.
In regards to the Authors
 Louis Hourcade is a Information Scientist within the AWS Skilled Companies staff. He works with AWS buyer throughout varied industries to speed up their enterprise outcomes with modern applied sciences. In his spare time he enjoys working, climbing huge rocks, and browsing (not so huge) waves.
 Sara Kazdagli is a Skilled Companies guide specialised in information analytics and machine studying. She helps clients throughout completely different industries construct modern options and make data-driven choices. Sara holds a MSc in Software program engineering and a MSc in information science. In her spare time, she likes to go on hikes and walks together with her australian shepherd canine Kiba.
 Jahed Zaïdi is an AI/ML & Massive Information specialist at AWS Skilled Companies. He’s a builder and a trusted advisor to firms throughout industries, serving to them innovate sooner and on a bigger scale. As a lifelong explorer, Jahed enjoys discovering new locations, cultures, and outside actions.
[ad_2]

