



[ad_1]
It is a visitor put up written by Dr. Yannick Misteli, lead cloud platform and ML engineering in international product technique (GPS) at Roche.
Just lately the Roche Knowledge Insights (RDI) initiative was launched to realize our imaginative and prescient utilizing new methods of working and collaboration with a purpose to construct shared, interoperable information & insights with federated governance. Moreover, a simplified & built-in information panorama shall be established with a purpose to empower insights communities. One of many first domains to have interaction on this program is the Go-to-Market (GTM) space which contains gross sales, advertising, medical entry and market affairs in Roche. GTM area permits Roche to grasp prospects and to finally create and ship invaluable providers that meet their wants. GTM as a site extends past well being care professionals (HCPs) to a bigger healthcare ecosystem consisting of sufferers, communities, well being authorities, payers, suppliers, academia, rivals, so on and so forth. Due to this fact, Knowledge & Analytics are key in supporting the interior and exterior stakeholders of their decision-making processes by means of actionable insights.
Roche GTM constructed a contemporary information and machine studying (ML) platform on AWS whereas using DevOps finest practices. The mantra of all the pieces as code (EaC) was key in constructing a completely automated, scalable information lake and information warehouse on AWS.
On this this put up, you study how Roche used AWS services similar to Amazon AppFlow, AWS Lake Formation, and Amazon Redshift to provision and populate their information lake; how they sourced, remodeled, and loaded information into the info warehouse; and the way they realized finest practices in safety and entry management.
Within the following sections, you dive deep into the scalable, safe, and automatic fashionable information platform that Roche has constructed. We show methods to automate information ingestion, safety requirements, and make the most of DevOps finest practices to ease administration of your fashionable information platform on AWS.
Knowledge platform structure
The next diagram illustrates the info platform structure.
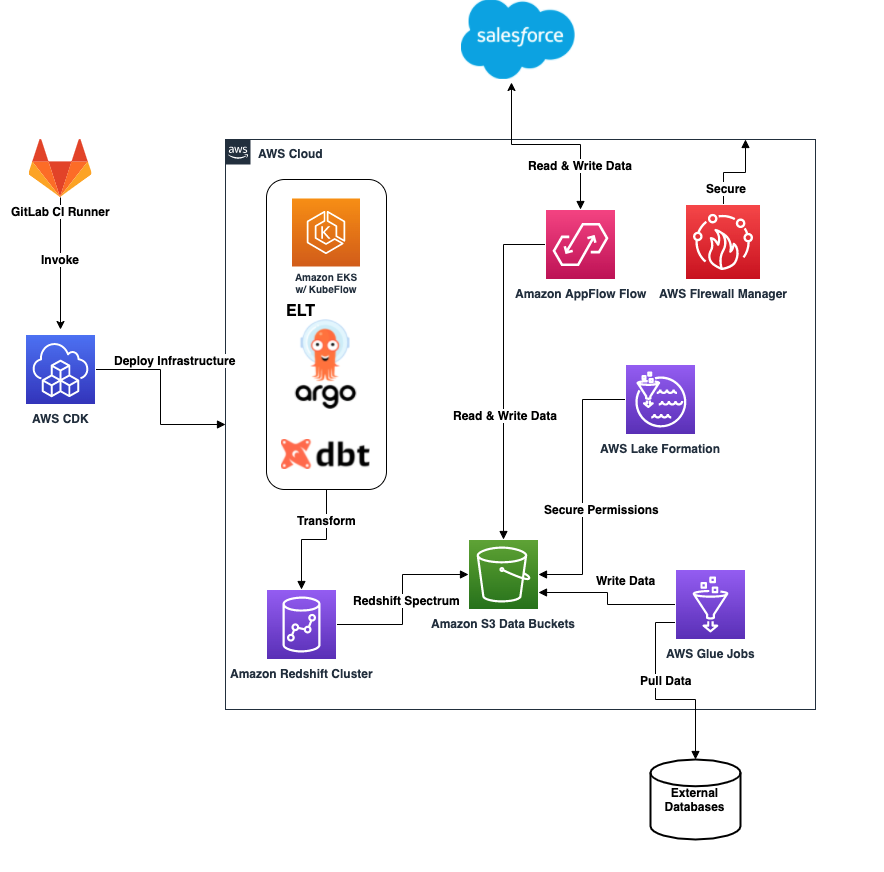
The structure incorporates the next parts:
Lake Formation safety
We use Lake Formation to safe all information because it lands within the information lake. Separating every information lake layer into distinct S3 buckets and prefixes permits fine-grained entry management insurance policies that Lake Formation implements. This idea additionally extends to locking down entry to particular rows and columns and making use of insurance policies to particular IAM roles and customers. Governance and entry to information lake assets is tough to handle, however Lake Formation simplifies this course of for directors.
To safe entry to the info lake utilizing Lake Formation, the next steps are automated utilizing the AWS CDK with custom-made constructs:
- Register the S3 information buckets and prefixes, and corresponding AWS Glue databases with Lake Formation.
- Add information lake directors (GitLab runner IAM deployment position and administrator IAM position).
- Grant the AWS Glue job IAM roles entry to the particular AWS Glue databases.
- Grant the AWS Lambda IAM position entry to the Amazon AppFlow databases.
- Grant the listed IAM roles entry to the corresponding tables within the AWS Glue databases.
AWS Glue Knowledge Catalog
The AWS Glue Knowledge Catalog is the centralized registration and entry level for all databases and tables which might be created in each the info lake and in Amazon Redshift. This gives centralized transparency to all assets together with their schemas and the situation of all information that’s referenced. It is a crucial facet for any information operations carried out throughout the lake home platform.
Knowledge sourcing and ingestion
Knowledge is sourced and loaded into the info lake by means of using AWS Glue jobs and Amazon AppFlow. The ingested information is made accessible within the Amazon Redshift information warehouse by means of Amazon Redshift Spectrum utilizing exterior schemas and tables. The method of making the exterior schemas and linking it to the Knowledge Catalog is printed later on this put up.
Amazon AppFlow Salesforce ingestion
Amazon AppFlow is a fully-managed integration service that lets you pull information from sources similar to Salesforce, SAP, and Zendesk. Roche integrates with Salesforce to load Salesforce objects securely into their information lake while not having to put in writing any customized code. Roche additionally pushes ML outcomes again to Salesforce utilizing Amazon AppFlow to facilitate the method.
Salesforce objects are first absolutely loaded into Amazon S3 after which are flipped to a every day incremental load to seize deltas. The info lands within the uncooked zone bucket in Parquet format utilizing the date as a partition. The Amazon AppFlow flows are created by means of using a YAML configuration file (see the next code). This configuration is consumed by the AWS CDK deployment to create the corresponding flows.
The YAML configuration makes it straightforward to pick whether or not information needs to be loaded from an S3 bucket again to Salesforce or from Salesforce to an S3 bucket. This configuration is subsequently learn by the AWS CDK app and corresponding stacks to translate into Amazon AppFlow flows.
The next choices are specified within the previous YAML configuration file:
- supply – The situation to tug information from (Amazon S3, Salesforce)
- vacation spot – The vacation spot to place information to (Amazon S3, Salesforce)
- object_name – The identify of the Salesforce object to work together with
- incremental_load – A Boolean specifying if the load needs to be incremental or full (0 means full, 1 means incremental)
- schedule_expression – The cron or charge expression to run the move (
namakes it on demand) - s3_prefix – The prefix to push or pull the info from within the S3 bucket
- connector_profile – The Amazon AppFlow connector profile identify to make use of when connecting to Salesforce (generally is a CSV listing)
- atmosphere – The atmosphere to deploy this Amazon AppFlow move to (
allmeans deploy to dev and prod,devmeans improvement atmosphere,prodmeans manufacturing atmosphere) - upsert_field_list – The set of Salesforce object fields (generally is a CSV listing) to make use of when performing an upsert operation again to Salesforce (solely relevant when loaded information again from an S3 bucket again to Salesforce)
- bookmark_col – The identify of the column to make use of within the Knowledge Catalog for registering the every day load date string partition
Register Salesforce objects to the Knowledge Catalog
Full the next steps to register information loaded into the info lake with the Knowledge Catalog and hyperlink it to Amazon Redshift:
- Collect Salesforce object fields and corresponding information sorts.
- Create a corresponding AWS Glue database within the Knowledge Catalog.
- Run a question towards Amazon Redshift to create an exterior schema that hyperlinks to the AWS Glue database.
- Create tables and partitions within the AWS Glue database and tables.
Knowledge is accessible by way of the Knowledge Catalog and the Amazon Redshift cluster.
Amazon AppFlow dynamic subject gathering
To assemble the schema of the loaded Salesforce object within the information lake, you invoke the next Python operate. The code makes use of an Amazon AppFlow consumer from Boto3 to dynamically collect the Salesforce object fields to assemble the Salesforce object’s schema.
We use the operate for each the creation of the Amazon AppFlow move by way of the AWS CDK deployment and for creating the corresponding desk within the Knowledge Catalog within the applicable AWS Glue database.
Create an Amazon CloudWatch Occasions rule, AWS Glue desk, and partition
So as to add new tables (one per Salesforce object loaded into Amazon S3) and partitions into the Knowledge Catalog routinely, you create an Amazon CloudWatch Occasions rule. This operate allows you to question the info in each AWS Glue and Amazon Redshift.
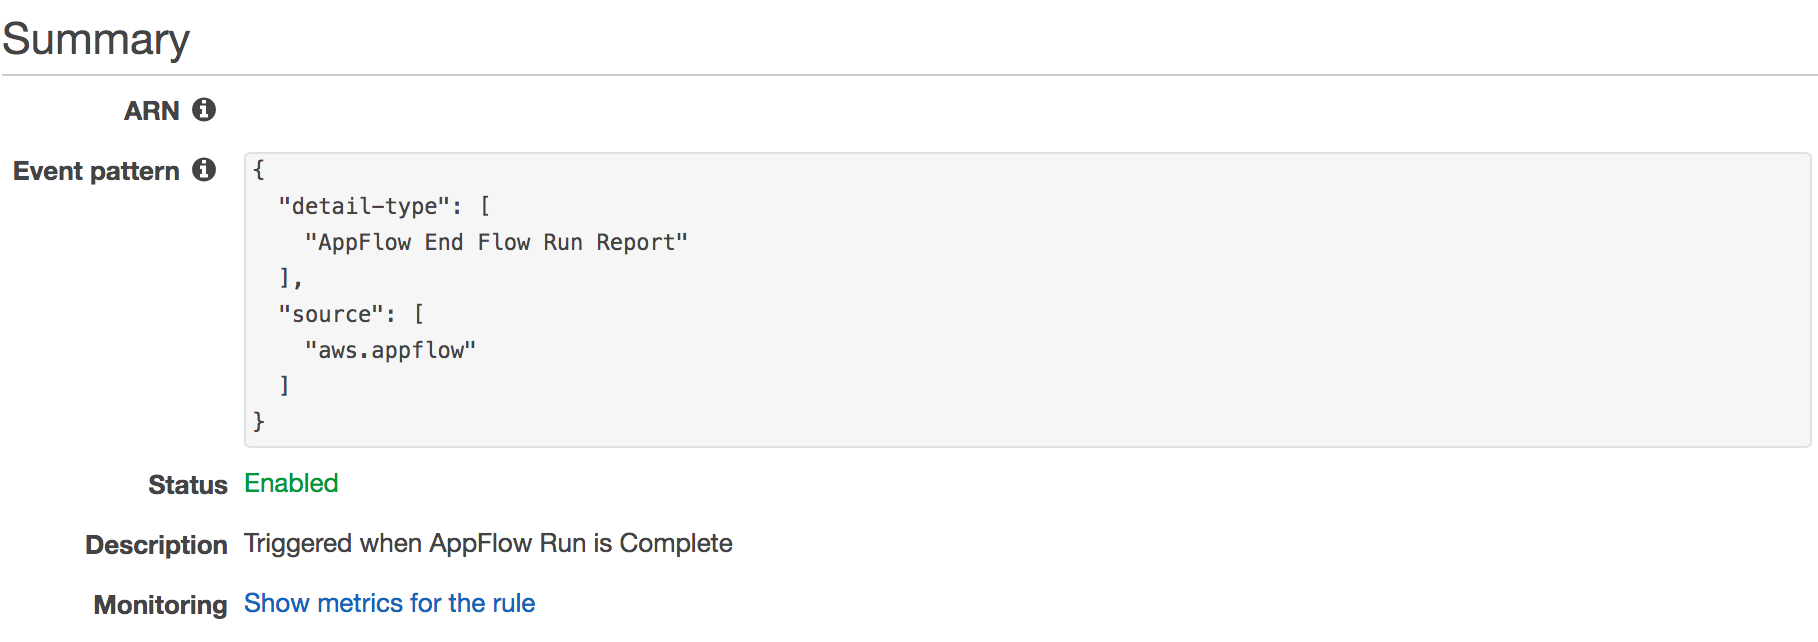
After the Amazon AppFlow move is full, it invokes a CloudWatch Occasions rule and a corresponding Lambda operate to both create a brand new desk in AWS Glue or add a brand new partition with the corresponding date string for the present day. The CloudWatch Occasions rule appears like the next screenshot.
The invoked Lambda operate makes use of the Amazon SageMaker Knowledge Wrangler Python bundle to work together with the Knowledge Catalog. Utilizing the previous operate definition, the item fields and their information sorts are accessible to move to the next operate name:
If the desk already exists, the Lambda operate creates a brand new partition to account for the date during which the move accomplished (if it doesn’t exist already):
Amazon Redshift exterior schema question
An AWS Glue database is created for every Amazon AppFlow connector profile that’s current within the previous configuration. The objects which might be loaded from Salesforce into Amazon S3 are registered as tables within the Knowledge Catalog beneath the corresponding database. To hyperlink the database within the Knowledge Catalog with an exterior Amazon Redshift schema, run the next question:
The required iam_role worth have to be an IAM position created forward of time and will need to have the suitable entry insurance policies specified to question the Amazon S3 location.
Now, all of the tables accessible within the Knowledge Catalog may be queried utilizing SQL domestically in Amazon Redshift Spectrum.
Amazon AppFlow Salesforce vacation spot
Roche trains and invokes ML fashions utilizing information discovered within the Amazon Redshift information warehouse. After the ML fashions are full, the outcomes are pushed again into Salesforce. Via using Amazon AppFlow, we are able to obtain the info switch with out writing any customized code. The schema of the outcomes should match the schema of the corresponding Salesforce object, and the format of the outcomes have to be written in both JSON strains or CSV format with a purpose to be written again into Salesforce.
AWS Glue Jobs
To supply on-premises information feeds into the info lake, Roche has constructed a set of AWS Glue jobs in Python. There are numerous exterior sources together with databases and APIs which might be immediately loaded into the uncooked zone S3 bucket. The AWS Glue jobs are run every day to load new information. The info that’s loaded follows the partitioning scheme of YYYYMMDD format with a purpose to extra effectively retailer and question datasets. The loaded information is then transformed into Parquet format for extra environment friendly querying and storage functions.
Amazon EKS and KubeFlow
To deploy ML fashions on Amazon EKS, Roche makes use of Kubeflow on Amazon EKS. The usage of Amazon EKS because the spine infrastructure makes it straightforward to construct, practice, take a look at, and deploy ML fashions and work together with Amazon Redshift as an information supply.
Firewall Supervisor
As an added layer of safety, Roche takes further precautions by means of using Firewall Supervisor. This enables Roche to explicitly deny or enable inbound and outbound site visitors by means of using stateful and stateless rule units. This additionally permits Roche to permit sure outbound entry to exterior web sites and deny web sites that they don’t need assets inside their Amazon VPC to have entry to. That is crucial particularly when coping with any delicate datasets to make sure that information is secured and has no probability of being moved externally.
CI/CD
All of the infrastructure outlined within the structure diagram was automated and deployed to a number of AWS Areas utilizing a steady integration and steady supply (CI/CD) pipeline with GitLab Runners because the orchestrator. The GitFlow mannequin was used for branching and invoking automated deployments to the Roche AWS accounts.
Infrastructure as code and AWS CDK
Infrastructure as code (IaC) finest practices have been used to facilitate the creation of all infrastructure. The Roche group makes use of the Python AWS CDK to deploy, model, and keep any modifications that happen to the infrastructure of their AWS account.
AWS CDK venture construction
The highest degree of the venture construction in GitLab contains the next folders (whereas not restricted to simply these folders) with a purpose to preserve infrastructure and code multi functional location.
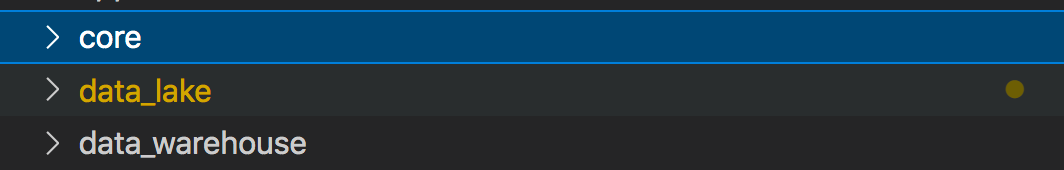
To facilitate the assorted assets which might be created within the Roche account, the deployment was damaged into the next AWS CDK apps, which embody a number of stacks:
coredata_lakedata_warehouse
The core app incorporates all of the stacks associated to account setup and account bootstrapping, similar to:
- VPC creation
- Preliminary IAM roles and insurance policies
- Safety guardrails
The data_lake app incorporates all of the stacks associated to creating the AWS information lake, similar to:
- Lake Formation setup and registration
- AWS Glue database creation
- S3 bucket creation
- Amazon AppFlow move creation
- AWS Glue job setup
The data_warehouse app incorporates all of the stacks associated to organising the info warehouse infrastructure, similar to:
- Amazon Redshift cluster
- Load balancer to Amazon Redshift cluster
- Logging
The AWS CDK venture construction described was chosen to maintain the deployment versatile and to logically group collectively stacks that relied on one another. This flexibility permits for deployments to be damaged out by operate and deployed solely when actually required and wanted. This decoupling of various components of the provisioning maintains flexibility when deploying.
AWS CDK venture configuration
Mission configurations are versatile and extrapolated away as YAML configuration recordsdata. For instance, Roche has simplified the method of making a brand new Amazon AppFlow move and might add or take away flows as wanted just by including a brand new entry into their YAML configuration. The subsequent time the GitLab runner deployment happens, it picks up the modifications on AWS CDK synthesis to generate a brand new change set with the brand new set of assets. This configuration and setup retains issues dynamic and versatile whereas decoupling configuration from code.
Community structure
The next diagram illustrates the community structure.
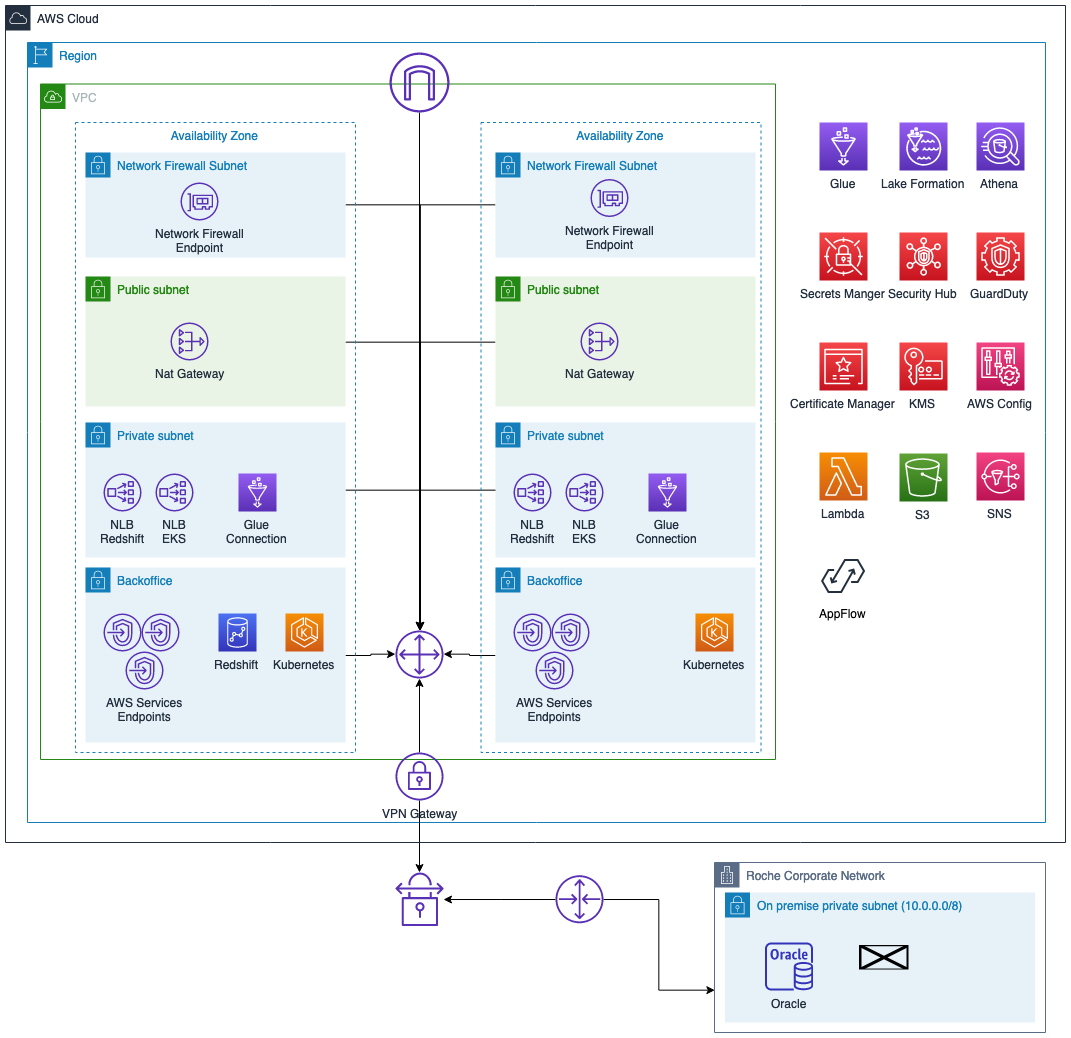
We are able to break down the structure into the next:
- All AWS providers are deployed in two Availability Zones (besides Amazon Redshift)
- Solely non-public subnets have entry to the on-premises Roche atmosphere
- Providers are deployed in backend subnets
- Perimeter safety utilizing AWS Community Firewall
- A community load balancer publishes providers to the on premises atmosphere
Community safety configurations
Infrastructure, configuration, and safety are outlined as code in AWS CDK, and Roche makes use of a CI/CD pipeline to handle and deploy them. Roche has an AWS CDK software to deploy the core providers of the venture: VPC, VPN connectivity, and AWS safety providers (AWS Config, Amazon GuardDuty, and AWS Safety Hub). The VPC incorporates 4 community layers deployed in two Availability Zones, and so they have VPC endpoints to entry AWS providers like Amazon S3, Amazon DynamoDB, and Amazon Easy Queue Service (Amazon SQS). They restrict web entry utilizing AWS Community Firewall.
The infrastructure is outlined as code and the configuration is segregated. Roche carried out the VPC setup by working the CI/CD pipeline to deploy their infrastructure. The configuration is in a particular exterior file; if Roche desires to vary any worth of the VPC, they should merely modify this file and run the pipeline once more (with out typing any new strains of code). If Roche desires to vary any configurations, they don’t need to have to vary any code. It makes it easy for Roche to make modifications and easily roll them out to their atmosphere, making the modifications extra clear and simpler to configure. Traceability of the configuration is extra clear and it makes it easier for approving the modifications.
The next code is an instance of the VPC configuration:
Some great benefits of this strategy are as follows:
- No want to change the AWS CDK constructor and construct new code to vary VPC configuration
- Central level to handle VPC configuration
- Traceability of modifications and historical past of the configuration by means of Git
- Redeploy all of the infrastructure in a matter of minutes in different Areas or accounts
Operations and alerting
Roche has developed an automatic alerting system if any a part of the end-to-end structure encounters any points, specializing in any points when loading information from AWS Glue or Amazon AppFlow. All logging is printed to CloudWatch by default for debugging functions.
The operational alerts have been constructed for the next workflow:
- AWS Glue jobs and Amazon AppFlow flows ingest information.
- If a job fails, it emits an occasion to a CloudWatch Occasions rule.
- The rule is triggered and invokes an Lambda operate to ship failure particulars to an Amazon Easy Notification Service (Amazon SNS) matter.
- The SNS matter has a Lambda subscriber that will get invoked:
- The Lambda operate reads out particular webhook URLs from AWS Secrets and techniques Supervisor.
- The operate fires off an alert to the particular exterior programs.
- The exterior programs obtain the message and the suitable events are notified of the difficulty with particulars.
The next structure outlines the alerting mechanisms constructed for the lake home platform.

Conclusion
The GTM (Go-To-Market) area has been profitable in enabling their enterprise stakeholders, information engineers and information scientists offering a platform that’s extendable to many use-cases that Roche faces. It’s a key enabler and an accelerator for the GTM group in Roche. Via a contemporary information platform, Roche is now capable of higher perceive prospects and finally create and ship invaluable providers that meet their wants. It extends past well being care professionals (HCPs) to a bigger healthcare ecosystem. The platform and infrastructure on this weblog assist to help and speed up each inside and exterior stakeholders of their decision-making processes by means of actionable insights.
The steps on this put up will help you propose to construct the same fashionable information technique utilizing AWS managed providers to ingest information from sources like Salesforce, routinely create metadata catalogs and share information seamlessly between the info lake and information warehouse, and create alerts within the occasion of an orchestrated information workflow failure. Partially 2 of this put up, you study how the info warehouse was constructed utilizing an agile information modeling sample and the way ELT jobs have been rapidly developed, orchestrated, and configured to carry out automated information high quality testing.
Particular thanks go to the Roche group: Joao Antunes, Krzysztof Slowinski, Krzysztof Romanowski, Bartlomiej Zalewski, Wojciech Kostka, Patryk Szczesnowicz, Igor Tkaczyk, Kamil Piotrowski, Michalina Mastalerz, Jakub Lanski, Chun Wei Chan, Andrzej Dziabowski for his or her venture supply and help with this put up.
About The Authors
 Dr. Yannick Misteli, Roche – Dr. Yannick Misteli is main cloud platform and ML engineering groups in international product technique (GPS) at Roche. He’s obsessed with infrastructure and operationalizing data-driven options, and he has broad expertise in driving enterprise worth creation by means of information analytics.
 Simon Dimaline, AWS – Simon Dimaline has specialised in information warehousing and information modelling for greater than 20 years. He presently works for the Knowledge & Analytics group inside AWS Skilled Providers, accelerating prospects’ adoption of AWS analytics providers.
 Matt Noyce, AWS – Matt Noyce is a Senior Cloud Software Architect in Skilled Providers at Amazon Net Providers. He works with prospects to architect, design, automate, and construct options on AWS for his or her enterprise wants.
 Chema Artal Banon, AWS – Chema Artal Banon is a Safety Advisor at AWS Skilled Providers and he works with AWS’s prospects to design, construct, and optimize their safety to drive enterprise. He makes a speciality of serving to firms speed up their journey to the AWS Cloud in probably the most safe method doable by serving to prospects construct the boldness and technical functionality.
A particular Thank You goes out to the next folks whose experience made this put up doable from AWS:
- Thiyagarajan Arumugam – Principal Analytics Specialist Options Architect
- Taz Sayed – Analytics Tech Chief
- Glenith Paletta – Enterprise Service Supervisor
- Mike Murphy – International Account Supervisor
- Natacha Maheshe – Senior Product Advertising Supervisor
- Derek Younger – Senior Product Supervisor
- Jamie Campbell – Amazon AppFlow Product Supervisor
- Kamen Sharlandjiev – Senior Options Architect – Amazon AppFlow
- Sunil Jethwani – Principal Buyer Supply Architect
- Vinay Shukla – Amazon Redshift Principal Product Supervisor
- Nausheen Sayed – Program Supervisor
[ad_2]

