


[ad_1]
Amazon Redshift is the cloud information warehouse of selection for tens of hundreds of shoppers who use it to investigate exabytes of information to achieve enterprise insights. Clients have requested for extra capabilities in Redshift to make it simpler, sooner, and safe to retailer, course of, and analyze all of their information. We introduced Redshift in 2012 as the primary cloud information warehouse to take away the complexity round provisioning, managing, and scaling information warehouses. Since then, now we have launched capabilities reminiscent of Concurrency scaling, Spectrum, and RA3 nodes to assist prospects analyze all of their information and assist rising analytics calls for throughout all customers within the group. We proceed to innovate with Redshift on our prospects’ behalf and launched greater than 50 important options in 2021. This publish covers a few of these options, together with use circumstances and advantages.
Working backwards from buyer necessities, we’re investing in Redshift to carry out new capabilities in three most important areas:
- Straightforward analytics for everybody
- Analyze your whole information
- Efficiency at any scale
Clients advised us that the info warehouse customers of their organizations are increasing from directors, builders, analysts, and information scientists to the Line of Enterprise (LoB) customers, so we proceed to take a position to make Redshift simpler to make use of for everybody. Clients additionally advised us that they need to break away from information silos and entry information throughout their information lakes, databases, and information warehouses and analyze that information with SQL and machine studying (ML). So we proceed to spend money on letting prospects analyze all of their information. And eventually, prospects advised us that they need the very best value efficiency for analytics at any scale from Terabytes to Petabytes of information. So we proceed to carry out new capabilities for efficiency at any scale. Let’s dive into every of those pillars and canopy the important thing capabilities that we launched in 2021.
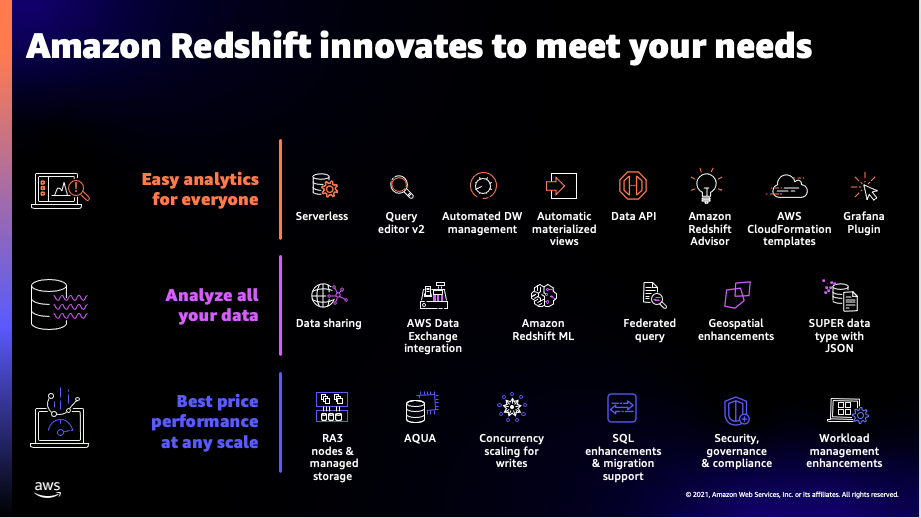
Amazon Redshift key improvements
Redshift delivers simple analytics for everybody
Straightforward analytics for everybody requires an easier getting-started expertise, automated manageability, and visible consumer interfaces that make is simpler, less complicated, and sooner for each technical and non-technical customers to shortly get began, function, and analyze information in a knowledge warehouse. We launched new options reminiscent of Redshift Serverless (in preview), Question Editor V2, and automatic materialized views (in preview), in addition to enhanced the Knowledge API in 2021 to make it simpler for purchasers to run their information warehouses.
Redshift Serverless (in preview) makes it simple to run and scale analytics in seconds with out having to provision and handle information warehouse clusters. The serverless possibility lets all customers, together with information analysts, builders, enterprise customers, and information scientists use Redshift to get insights from information in seconds by merely loading and querying information into the info warehouse. Clients can launch a knowledge warehouse and begin analyzing the info with the Redshift Serverless possibility by just some clicks within the AWS Administration Console. There is no such thing as a want to decide on node varieties, node depend, or different configurations. Clients can reap the benefits of pre-loaded pattern information units together with pattern queries to kick begin analytics instantly. They will create databases, schemas, tables, and cargo their very own information from their desktop, Amazon Easy Storage Service (S3), through Amazon Redshift information shares, or restore an present Amazon Redshift provisioned cluster snapshot. They will additionally instantly question information in open codecs, reminiscent of Parquet or ORC, of their Amazon S3 information lakes, in addition to information of their operational databases, reminiscent of Amazon Aurora and Amazon RDS. Clients pay just for what they use, and so they can handle their prices with granular price controls.
Redshift Question Editor V2 is a web-based device for information analysts, information scientists, and database builders to discover, analyze, and collaborate on information in Redshift information warehouses and information lake. Clients can use Question Editor’s visible interface to create and browse schema and tables, load information, creator SQL queries and saved procedures, and visualize question outcomes with charts. They will share and collaborate on queries and evaluation, as properly a monitor modifications with in-built model management. Question Editor V2 additionally helps SQL Notebooks (in preview), which supplies a brand new Pocket book interface that lets customers reminiscent of information analysts and information scientists creator queries, arrange a number of SQL queries and annotations on a single doc, and collaborate with their workforce members by sharing Notebooks.

Amazon Redshift Question Editor V2
Clients have lengthy used Amazon Redshift materialized views (MV) for precomputed consequence units, primarily based on an SQL question over a number of base tables to enhance question efficiency, notably for incessantly used queries reminiscent of these in dashboards and studies. In 2021, we launched Automated Materialized View (AutoMV) in preview to enhance the efficiency of queries (scale back the whole execution time) with none consumer effort by mechanically creating and sustaining materialized views. Clients advised us that whereas MVs supply important efficiency advantages, analyzing the schema, information, and workload to find out which queries may profit from having an MV or which MVs are now not helpful and needs to be dropped requires data, time, and energy. AutoMV lets Redshift frequently monitor the cluster to establish candidate MVs and evaluates the advantages vs prices. It creates MVs which have excessive benefit-to-cost ratios, whereas making certain present workloads should not negatively impacted by this course of. AutoMV frequently displays the system and can drop MVs which are now not helpful. All of those are clear to customers and purposes. Functions reminiscent of dashboards profit with none code change due to automated question re-write, which lets present queries profit from MVs even when not explicitly referenced. Clients also can set the MVs to autorefresh in order that MVs at all times have up-to-date information for added comfort.
Clients have additionally requested us to simplify and automate information warehouse upkeep duties, reminiscent of schema or desk design, in order that they’ll get optimum efficiency out of their clusters. Over the previous few years, now we have invested closely to automate these upkeep duties. For instance, Automated Desk Optimization (ATO) selects the very best type and distribution keys to find out the optimum bodily structure of information to maximise efficiency. We’ve prolonged ATO to change column compression encodings to attain excessive efficiency and scale back storage utilization. We now have additionally launched numerous options, reminiscent of auto vacuum delete and auto analyze, over the previous few years to be sure that buyer information warehouses proceed to function at peak efficiency.
Knowledge API, which launched in 2020, has additionally seen main enhancements, reminiscent of multi-statement question execution, assist for parameters to develop reusable code, and availability in additional areas in 2021 to make it simpler for purchasers to programmatically entry information in Redshift. Knowledge API lets Redshift allow prospects to painlessly entry information with all forms of conventional, cloud-native, and containerized, serverless internet services-based purposes and event-driven purposes. It simplifies information entry, ingest, and egress from programming languages and platforms supported by the AWS SDK, reminiscent of Python, Go, Java, Node.js, PHP, Ruby, and C++. The Knowledge API eliminates the necessity for configuring drivers and managing database connections. As a substitute, prospects can run SQL instructions to an Amazon Redshift cluster by merely calling a secured API endpoint supplied by the Knowledge API. The Knowledge API takes care of managing database connections and buffering information. The Knowledge API is asynchronous, so outcomes could be retrieved later and are saved for twenty-four hours.
Lastly in our simple analytics for everybody pillar, in 2021 we launched the Grafana Redshift Plugin to assist prospects acquire a deeper understanding of their cluster’s efficiency. Grafana is a well-liked open-source device for operating analytics and monitoring programs on-line. The Grafana Redshift Plugin lets prospects question system tables and views for essentially the most full set of operational metrics on their Redshift cluster. The Plugin is accessible within the Open Supply Grafana repository, in addition to in our Amazon Managed Grafana service. We additionally revealed a default in-depth operational dashboard to reap the benefits of this function.
Redshift makes it attainable for purchasers to investigate all of their information
Redshift offers prospects the very best of each information lakes and purpose-built information shops, reminiscent of databases and information warehouses. It allows prospects to retailer any quantity of information, at low price, and in open, standards-based information codecs reminiscent of parquet and JSON in information lakes, and run SQL queries in opposition to it with out loading or transformations. Moreover, it lets prospects run advanced analytic queries with excessive efficiency in opposition to terabytes to petabytes of structured and semi-structured information, utilizing refined question optimization, columnar storage on high-performance storage, and massively parallel question execution. Redshift lets prospects entry stay information from the transactional databases as a part of their enterprise intelligence (BI) and reporting purposes to allow operational analytics. Clients can break down information silos by seamlessly querying information within the information lakes, information warehouses, and databases; empower their groups to run analytics and ML utilizing their most popular device or approach; and handle who has entry to information with the correct safety and information governance controls. We launched new options in 2021, reminiscent of Knowledge Sharing, AWS Knowledge Change integration, and Redshift ML, to make it simpler for purchasers to investigate all of their information.
Amazon Redshift information sharing lets prospects lengthen the benefit of use, efficiency, and value advantages that Amazon Redshift affords in a single cluster to multi-cluster deployments whereas having the ability to share information. It allows prompt, granular, and quick information entry throughout Amazon Redshift clusters with out the necessity to copy or transfer information round. Knowledge sharing supplies stay entry to information in order that your customers at all times see essentially the most up-to-date and constant info because it’s up to date within the information warehouse. Clients can securely share stay information with Amazon Redshift clusters in the identical or completely different AWS accounts throughout the identical area or throughout areas. Knowledge sharing options a number of efficiency enhancements, together with consequence caching and concurrency scaling, which permit prospects to assist a broader set of analytics purposes and meet essential efficiency SLAs when querying shared information. Clients can use information sharing to be used circumstances reminiscent of workload isolation and supply chargeability, in addition to present safe and ruled collaboration inside and throughout groups and exterior events.
Clients additionally requested us to assist them with inside or exterior information marketplaces in order that they’ll allow use circumstances reminiscent of information as a service and onboard 3rd-party information. We launched the general public preview of AWS Knowledge Change for Amazon Redshift, a brand new function that permits prospects to seek out and subscribe to third-party information in AWS Knowledge Change that they’ll question in an Amazon Redshift information warehouse in minutes. Knowledge suppliers can record and supply merchandise containing Amazon Redshift information units within the AWS Knowledge Change catalog, granting subscribers direct, read-only entry to the info saved in Amazon Redshift. This function empowers prospects to shortly question, analyze, and construct purposes with these third-party information units. AWS Knowledge Change for Amazon Redshift lets prospects mix third-party information discovered on AWS Knowledge Change with their very own first-party information of their Amazon Redshift cloud information warehouse, with no ETL required. Since prospects are instantly querying supplier information warehouses, they are often sure that they’re utilizing the newest information being supplied. Moreover, entitlement, billing, and fee administration are all automated: entry to Amazon Redshift information is granted when a knowledge subscription begins and is eliminated when it ends, invoices are mechanically generated, and funds are mechanically collected and disbursed by AWS Market.
Clients additionally requested for our assist to make it simple to coach and deploy ML fashions reminiscent of prediction, pure language processing, object detection, and picture classification instantly on high of the info in purpose-built information shops with out having to carry out advanced information motion or study new instruments. We launched Redshift ML earlier this yr to allow prospects to create, practice, and deploy ML fashions utilizing acquainted SQL instructions. Amazon Redshift ML lets prospects leverage Amazon SageMaker, a totally managed ML service, with out shifting their information or studying new abilities. Moreover, Amazon Redshift ML powered by Amazon SageMaker lets prospects use SQL statements to create and practice ML fashions from their information in Amazon Redshift, after which use these fashions to be used circumstances reminiscent of churn prediction and fraud danger scoring instantly of their queries and studies. Amazon Redshift ML mechanically discovers the very best mannequin and tunes it primarily based on coaching information utilizing Amazon SageMaker Autopilot. SageMaker Autopilot chooses between regression, binary, or multi-class classification fashions. Alternatively, prospects can select a selected mannequin kind reminiscent of Xtreme Gradient Boosted tree (XGBoost) or multilayer perceptron (MLP), an issue kind like regression or classification, and preprocessors or hyperparameters. Amazon Redshift ML makes use of buyer parameters to construct, practice, and deploy the mannequin within the Amazon Redshift information warehouse. Clients can get hold of predictions from these skilled fashions utilizing SQL queries as in the event that they have been invoking a consumer outlined perform (UDF), and leverage all the advantages of Amazon Redshift, together with massively parallel processing capabilities. Clients also can import their pre-trained SageMaker Autopilot, XGBoost, or MLP fashions into their Amazon Redshift cluster for native inference. Redshift ML helps each supervised and unsupervised ML for superior analytics use circumstances starting from forecasting to personalization.
Clients need to mix stay information from operational databases with the info in Amazon Redshift information warehouse and the info in Amazon S3 information lake surroundings to get unified analytics views throughout all the information within the enterprise. We launched Amazon Redshift federated question to let prospects incorporate stay information from the transactional databases as a part of their BI and reporting purposes to allow operational analytics. The clever optimizer in Amazon Redshift pushes down and distributes a portion of the computation instantly into the distant operational databases to assist velocity up efficiency by decreasing information moved over the community. Amazon Redshift enhances subsequent execution of the question by leveraging its massively parallel processing capabilities for additional velocity up. Federated question additionally makes it simpler to ingest information into Amazon Redshift by letting prospects question operational databases instantly, making use of transformations on the fly, and loading information into the goal tables with out requiring advanced ETL pipelines. In 2021, we added assist for Amazon Aurora MySQL and Amazon RDS for MySQL databases along with the prevailing Amazon Aurora PostgreSQL and Amazon RDS for PostgreSQL databases for federated question to allow prospects to entry extra information sources for richer analytics.
Lastly in our analyze all of your information pillar in 2021, we added information varieties reminiscent of SUPER, GEOGRAPHY, and VARBYTE to allow prospects to retailer semi-structured information natively within the Redshift information warehouse in order that they’ll analyze all of their information at scale and with efficiency. The SUPER information kind lets prospects ingest and retailer JSON and semi-structured information of their Amazon Redshift information warehouses. Amazon Redshift additionally contains assist for PartiQL for SQL-compatible entry to relational, semi-structured, and nested information. Utilizing the SUPER information kind and PartiQL in Amazon Redshift, prospects can carry out superior analytics that mix traditional structured SQL information (reminiscent of string, numeric, and timestamp) with the semi-structured SUPER information (reminiscent of JSON) with superior efficiency, flexibility, and ease-of-use. The GEOGRAPHY information kind builds on Redshift’s assist of spatial analytics, opening-up assist for a lot of extra third-party spatial and GIS purposes. Furthermore, it provides to the GEOMETRY information kind and over 70 spatial features which are already accessible in Redshift. The GEOGRAPHY information kind is utilized in queries requiring greater precision outcomes for spatial information with geographic options that may be represented with a spheroid mannequin of the Earth and referenced utilizing latitude and longitude as a spatial coordinate system. VARBYTE is a variable dimension information kind for storing and representing variable-length binary strings.
Redshift delivers efficiency at any scale
Since we introduced Amazon Redshift in 2012, efficiency at any scale has been a foundational tenet for us to ship worth to tens of hundreds of shoppers who belief us day-after-day to achieve enterprise insights from their information. Our prospects span all industries and sizes, from startups to Fortune 500 firms, and we work to ship the very best value efficiency for any use case. Over time, now we have launched options reminiscent of dynamically including cluster capability whenever you want it with concurrency scaling, ensuring that you just use cluster sources effectively with automated workload administration (WLM), and mechanically adjusting information structure, distribution keys, and question plans to offer optimum efficiency for a given workload. In 2021, we launched capabilities reminiscent of AQUA, concurrency scaling for writes, and additional enhancements to RA3 nodes to proceed to enhance Redshift’ value efficiency.
We launched the RA3 node varieties in 2019 as a know-how that enables the unbiased scaling of compute and storage. We additionally described how prospects, together with Codeacademy, OpenVault, Yelp, and Nielsen, have taken benefit of Amazon Redshift RA3 nodes with managed storage to scale their cloud information warehouses and scale back prices. RA3 leverages Redshift Managed Storage (RMS) as its sturdy storage layer which permits near-unlimited storage capability the place information is dedicated again to Amazon S3. This enabled new capabilities, reminiscent of Knowledge Sharing and AQUA, the place RMS is used as a shared storage throughout a number of clusters. RA3 nodes can be found in three sizes (16XL, 4XL, and XLPlus) to steadiness value/efficiency. In 2021, we launched single node RA3 XLPlus clusters to assist prospects cost-effectively migrate their smaller information warehouse workloads to RA3s and reap the benefits of higher value efficiency. We additionally launched a self-service DS2 to RA3 RI migration functionality that lets RIs be transformed at a flat price between equal node varieties.
AQUA (Superior Question Accelerator) for Amazon Redshift is a brand new distributed and hardware-accelerated cache that permits Amazon Redshift to run an order of magnitude sooner than different enterprise cloud information warehouses by mechanically boosting sure question varieties. AQUA makes use of AWS-designed processors with AWS Nitro chips tailored to hurry up information encryption and compression, and customized analytics processors, applied in FPGAs, to speed up operations reminiscent of scans, filtering, and aggregation. AQUA is accessible with the RA3.16xlarge, RA3.4xlarge, or RA3.xlplus nodes at no further cost and requires no code modifications.
Concurrency Scaling was launched in 2019 to deal with spiky and unpredictable learn workloads with out having to pre-provision any capability. Redshift affords one hour of free Concurrency Scaling for each 24 hours of utilization that your most important cluster is operating. It additionally affords price controls to observe and restrict your utilization and related prices for Concurrency Scaling. Along with learn queries, supporting write queries has been an enormous ask from prospects to assist ETL workloads. In 2021, we launched Redshift Concurrency Scaling write queries assist in preview with widespread operations reminiscent of INSERT, DELETE, UPDATE, and COPY to deal with unpredictable spikes in ETL workloads. If you’re at present utilizing Concurrency Scaling, this new functionality is mechanically enabled in your cluster. You possibly can monitor your Concurrency Scaling utilization utilizing the Amazon Redshift Console and get alerts on any utilization exceeding your outlined limits. You may also create, modify, and delete utilization limits programmatically by utilizing the AWS Command Line Interface (CLI) and AWS API.
Lastly we proceed to make sure that AWS has complete safety capabilities to fulfill essentially the most demanding necessities, and Amazon Redshift continues to supplies information safety out-of-the-box at no additional price. We launched new security measures in 2021, reminiscent of cross-VPC assist and default IAM roles, to proceed to make Redshift safer for buyer workloads.
Abstract
With regards to making it simpler, less complicated, and sooner for purchasers to investigate all of their information, velocity issues and we’re innovating at a speedy tempo to carry new capabilities to Redshift. We proceed to make Redshift options accessible in additional AWS areas worldwide to be sure that all prospects have entry to all capabilities. We now have coated the important thing options above and the whole record is accessible right here. We stay up for how you’ll use a few of these capabilities to proceed innovating with information and analytics.
In regards to the Writer
 Manan Goel is a Product Go-To-Market Chief for AWS Analytics Providers together with Amazon Redshift & AQUA at AWS. He has greater than 25 years of expertise and is properly versed with databases, information warehousing, enterprise intelligence, and analytics. Manan holds a MBA from Duke College and a BS in Electronics & Communications engineering.
[ad_2]

