


[ad_1]
Apache HBase is a non-relational database. To make use of the info, functions want to question the database to tug the info and adjustments from tables. On this publish, we introduce a mechanism to stream Apache HBase edits into streaming providers akin to Apache Kafka or Amazon Kinesis Information Streams. On this method, adjustments to information are pushed and queued right into a streaming platform akin to Kafka or Kinesis Information Streams for real-time processing, utilizing a customized Apache HBase replication endpoint.
We begin with a quick technical background on HBase replication and evaluation a use case during which we retailer IoT sensor information into an HBase desk and enrich rows utilizing periodic batch jobs. We display how this resolution allows you to enrich the data in actual time and in a serverless approach utilizing AWS Lambda capabilities.
Widespread eventualities and use instances of this resolution are as follows:
- Auditing information, triggers, and anomaly detection utilizing Lambda
- Delivery WALEdits by way of Kinesis Information Streams to Amazon OpenSearch Service (successor to Amazon Elasticsearch Service) to index data asynchronously
- Triggers on Apache HBase bulk hundreds
- Processing streamed information utilizing Apache Spark Streaming, Apache Flink, Amazon Kinesis Information Analytics, or Kinesis analytics
- HBase edits or change information seize (CDC) replication into different storage platforms, akin to Amazon Easy Storage Service (Amazon S3), Amazon Relational Database Service (Amazon RDS), and Amazon DynamoDB
- Incremental HBase migration by replaying the edits from any cut-off date, primarily based on configured retention in Kafka or Kinesis Information Streams
This publish progresses into some frequent use instances you may encounter, together with their design choices and options. We evaluation and develop on these eventualities in separate sections, along with the issues and limits in our utility designs.
Introduction to HBase replication
At a really excessive degree, the precept of HBase replication is predicated on replaying transactions from a supply cluster to the vacation spot cluster. That is executed by replaying WALEdits or Write Forward Log entries on the RegionServers of the supply cluster into the vacation spot cluster. To clarify WALEdits, in HBase, all of the mutations in information like PUT or DELETE are written to MemStore of their particular area and are appended to a WAL file as WALEdits or entries. Every WALEdit represents a transaction and may carry a number of write operations on a row. As a result of the MemStore is an in-memory entity, in case a area server fails, the misplaced information may be replayed and restored from the WAL information. Having a WAL is optionally available, and a few operations could not require WALs or can request to bypass WALs for faster writes. For instance, data in a bulk load aren’t recorded in WAL.
HBase replication is predicated on transferring WALEdits to the vacation spot cluster and replaying them so any operation that bypasses WAL isn’t replicated.
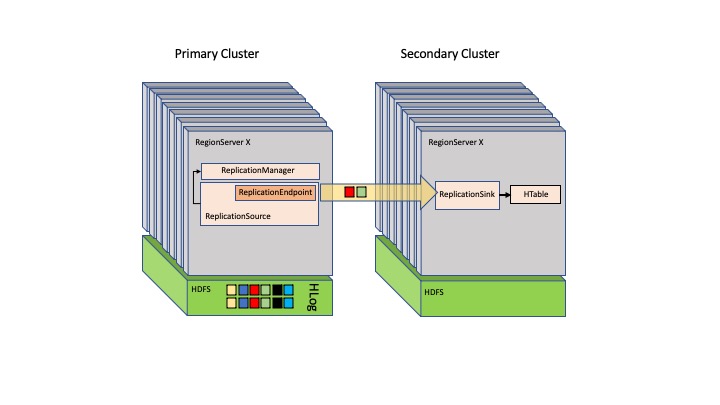
When organising a replication in HBase, a ReplicationEndpoint implementation must be chosen within the replication configuration when making a peer, and on each RegionServer, an occasion of ReplicationEndpoint runs as a thread. In HBase, a replication endpoint is pluggable for extra flexibility in replication and transport WALEdits to totally different variations of HBase. You can even use this to construct replication endpoints for sending edits to totally different platforms and environments. For extra details about organising replication, see Cluster Replication.
HBase bulk load replication HBASE-13153
In HBase, bulk loading is a technique to straight import HFiles or Retailer information into RegionServers. This avoids the conventional write path and WALEdits. In consequence, far much less CPU and community sources are used when importing massive parts of information into HBase tables.
You can even use HBase bulk hundreds to get better information when an error or outage causes the cluster to lose observe of areas and Retailer information.
As a result of bulk hundreds skip WAL creation, all new data aren’t replicated to the secondary cluster. In HBASE-13153, which is an enhancement, a bulk load is represented as a bulk load occasion, carrying the situation of the imported information. You possibly can activate this by setting hbase.replication.bulkload.enabled to true and setting hbase.replication.cluster.id to a novel worth as a prerequisite.
Customized streaming replication endpoint
We will use HBase’s pluggable endpoints to stream data into platforms akin to Kinesis Information Streams or Kafka. Transferred data may be consumed by Lambda capabilities, processed by a Spark Streaming utility or Apache Flink on Amazon EMR, Kinesis Information Analytics, or some other massive information platform.
On this publish, we display an implementation of a customized replication endpoint that permits replicating WALEdits in Kinesis Information Streams or Kafka matters.
In our instance, we constructed upon the BaseReplicationEndpoint summary class, inheriting the ReplicationEndpoint interface.
The principle technique to implement and override is the replicate technique. This technique replicates a set of things it receives each time it’s referred to as and blocks till all these data are replicated to the vacation spot.
For our implementation and configuration choices, see our GitHub repository.
Use case: Enrich data in actual time
We now use the customized streaming replication endpoint implementation to stream HBase edits to Kinesis Information Streams.
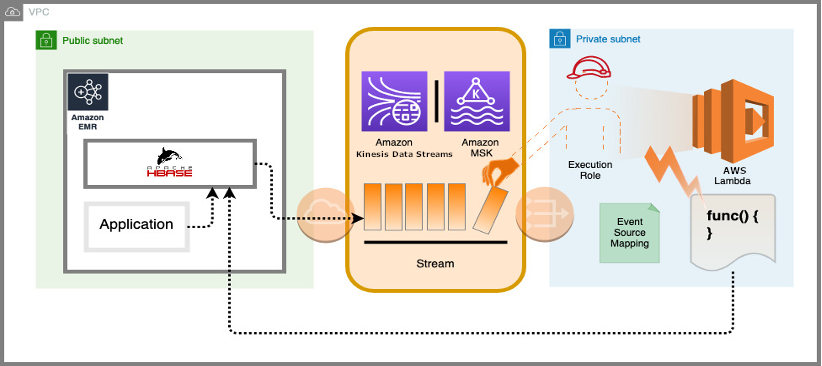
The offered AWS CloudFormation template demonstrates how we will arrange an EMR cluster with replication to both Kinesis Information Streams or Apache Kafka and eat the replicated data, utilizing a Lambda perform to complement information asynchronously, in actual time. In our pattern venture, we launch an EMR cluster with an HBase database. A pattern IoT visitors generator utility runs as a step within the cluster and places data, containing a registration quantity and an instantaneous pace, into a neighborhood HBase desk. Information are replicated in actual time right into a Kinesis stream or Kafka matter primarily based on the chosen possibility at launch, utilizing our customized HBase replication endpoint. When the step begins placing the data into the stream, a Lambda perform is provisioned and begins digesting data from the start of the stream and catches up with the stream. The perform calculates a rating per report, primarily based on a components on variation from minimal and most pace limits within the use case, and persists the end result as a rating qualifier into a distinct column household, out of replication scope within the supply desk, by operating HBase places on RowKey.
The next diagram illustrates this structure.
To launch our pattern surroundings, you should use our template on GitHub.
The template creates a VPC, private and non-private subnets, Lambda capabilities to eat data and put together the surroundings, an EMR cluster with HBase, and a Kinesis information stream or an Amazon Managed Streaming for Apache Kafka (Amazon MSK) cluster relying on the chosen parameters when launching the stack.
Architectural design patterns
Historically, Apache HBase tables are thought of as information shops, the place customers get or scan the data from tables. It’s quite common in trendy databases to react to database logs or CDC for real-time use instances and triggers. With our streaming HBase replication endpoint, we will venture desk adjustments into message supply programs like Kinesis Information Streams or Apache Kafka.
We will set off Lambda capabilities to eat messages and data from Apache Kafka or Kinesis Information Streams to eat the data in a serverless design or the broader Amazon Kinesis ecosystems akin to Kinesis Information Analytics or Amazon Kinesis Information Firehose for supply into Amazon S3. You might additionally pipe in Amazon OpenSearch Service.
A variety of client ecosystems, akin to Apache Spark, AWS Glue, and Apache Flink, is offered to eat from Kafka and Kinesis Information Streams.
Let’s evaluation few different frequent use instances.
Index HBase rows
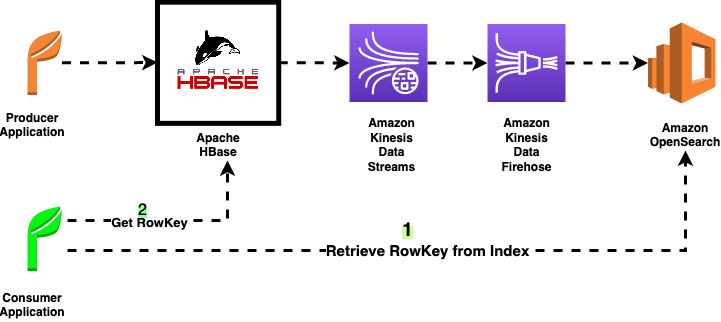
Apache HBase rows are retrievable by RowKey. Writing a row into HBase with the identical RowKey overwrites or creates a brand new model of the row. To retrieve a row, it must be fetched by the RowKey or a variety of rows must be scanned if the RowKey is unknown.
In some use instances, scanning the desk for a selected qualifier or worth is pricey if we index our rows in one other parallel system like Elasticsearch asynchronously. Functions can use the index to search out the RowKey. With out this resolution, a periodic job has to scan the desk and write them into an indexing service like Elasticsearch to hydrate the index, or the manufacturing utility has to jot down in each HBase and Elasticsearch straight, which provides overhead to the producer.
Enrich and audit information
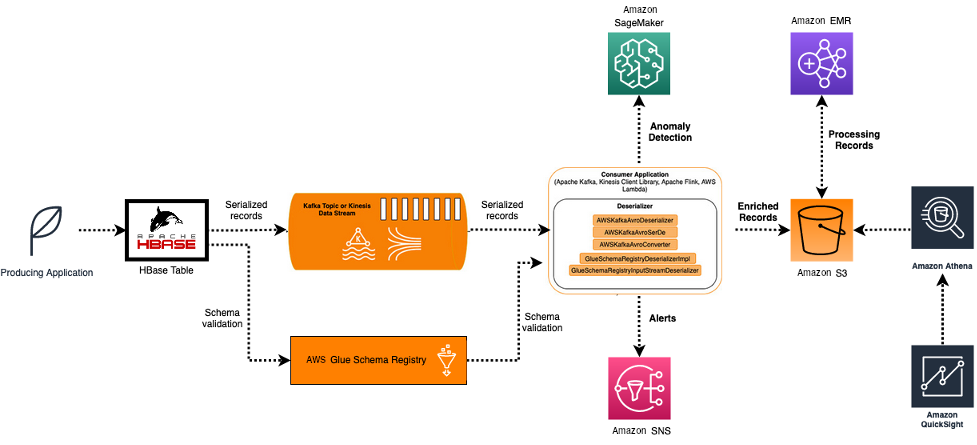
A quite common use case for HBase streaming endpoints is enriching information and storing the enriched data in an information retailer, akin to Amazon S3 or RDS databases. On this state of affairs, a customized HBase replication endpoint streams the data right into a message distribution system akin to Apache Kafka or Kinesis Information Streams. Information may be serialized, utilizing the AWS Glue Schema Registry for schema validation. A client on the opposite finish of the stream reads the data, enriches them, and validates in opposition to a machine studying mannequin in Amazon SageMaker for anomaly detection. The buyer persists the data in Amazon S3 and probably triggers an alert utilizing Amazon Easy Notification Service (Amazon SNS). Saved information on Amazon S3 may be additional digested on Amazon EMR, or we will create a dashboard on Amazon QuickSight, interfacing Amazon Athena for queries.
The next diagram illustrates our structure.
Retailer and archive information lineage
Apache HBase comes with the snapshot function. You possibly can freeze the state of tables into snapshots and export them to any distributed file system like HDFS or Amazon S3. Recovering snapshots restores the complete desk to the snapshot level.
Apache HBase additionally helps versioning on the row degree. You possibly can configure column households to maintain row variations, and the default versioning is predicated on timestamps.
Nevertheless, when utilizing this method to stream data into Kafka or Kinesis Information Streams, data are retained contained in the stream, and you may partially replay a interval. Recovering snapshots solely recovers as much as the snapshot level and the longer term data aren’t current.
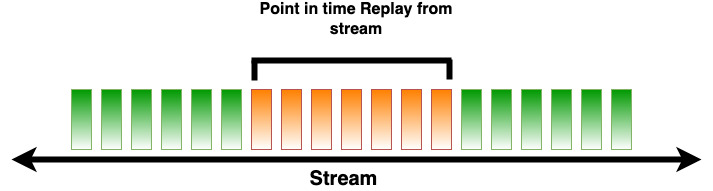
In Kinesis Information Streams, by default data of a stream are accessible for as much as 24 hours from the time they’re added to the stream. This restrict may be elevated to as much as 7 days by enabling prolonged information retention, or as much as one year by enabling long-term information retention. See Quotas and Limits for extra info.
In Apache Kafka, report retention has nearly no limits primarily based on obtainable sources and disk house configured on the Kafka cluster, and may be configured by setting log.retention.
Set off on HBase bulk load
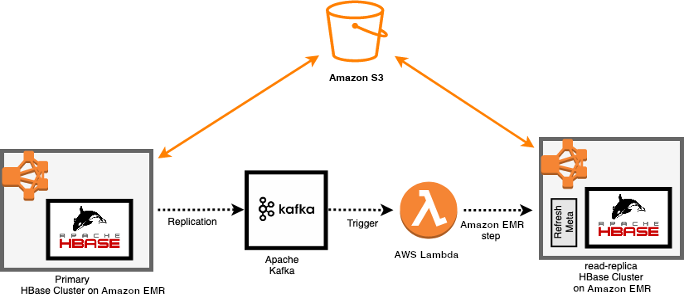
The HBase bulk load function makes use of a MapReduce job to output desk information in HBase’s inside information format, after which straight hundreds the generated Retailer information into the operating cluster. Utilizing bulk load makes use of much less CPU and community sources than loading by way of the HBase API, as HBase bulk load bypasses WALs within the write path and the data aren’t seen by replication. Nevertheless, since HBASE-13153, you may configure HBase to duplicate a meta report as a sign of a bulk load occasion.
A Lambda perform processing replicated WALEdits can take heed to this occasion to set off actions, akin to routinely refreshing a learn duplicate HBase cluster on Amazon S3 at any time when a bulk load occurs. The next diagram illustrates this workflow.
Concerns for replication into Kinesis Information Streams
Kinesis Information Streams is a massively scalable and sturdy real-time information streaming service. Kinesis Information Streams can repeatedly seize gigabytes of information per second from a whole lot of hundreds of sources with very low latency. Kinesis is absolutely managed and runs your streaming functions with out requiring you to handle any infrastructure. It’s sturdy, as a result of data are synchronously replicated throughout three Availability Zones, and you may improve information retention to one year.
When contemplating Kinesis Information Streams for any resolution, it’s necessary to think about service limits. As an example, as of this writing, the utmost dimension of the info payload of a report earlier than base64-encoding is as much as 1 MB, so we should ensure that the data or serialized WALEdits stay throughout the Kinesis report dimension restrict. To be extra environment friendly, you may allow the hbase.replication.compression-enabled attribute to GZIP compress the data earlier than sending them to the configured stream sink.
Kinesis Information Streams retains the order of the data throughout the shards as they arrive, and data may be learn or processed in the identical order. Nevertheless, on this pattern customized replication endpoint, a random partition key’s used in order that the data are evenly distributed between the shards. We will additionally use a hash perform to generate a partition key when placing data into the stream, for instance primarily based on the Area ID so that every one the WALEdits from the identical Area land in the identical shard and customers can assume Area locality per shards.
For delivering data in KinesisSinkImplemetation, we use the Amazon Kinesis Producer Library (KPL) to place data into Kinesis information streams. The KPL simplifies producer utility improvement; we will obtain excessive write throughput to a Kinesis information stream. We will use the KPL in both synchronous or asynchronous use instances. We advise utilizing the upper efficiency of the asynchronous interface until there’s a particular purpose to make use of synchronous habits. KPL may be very configurable and has retry logic inbuilt. You can even carry out report aggregation for optimum throughput. In KinesisSinkImplemetation, by default data are asynchronously replicated to the stream. We will change to synchronous mode by setting hbase.replication.kinesis.syncputs to true. We will allow report aggregation by setting hbase.replication.kinesis.aggregation-enabled to true.
The KPL can incur an extra processing delay as a result of it buffers data earlier than sending them to the stream primarily based on a user-configurable attribute of RecordMaxBufferedTime. Bigger values of RecordMaxBufferedTime ends in larger packing efficiencies and higher efficiency. Nevertheless, functions that may’t tolerate this extra delay might have to make use of the AWS SDK straight.
Kinesis Information Streams and the Kinesis household are absolutely managed and simply combine with the remainder of the AWS ecosystem with minimal improvement effort with providers such because the AWS Glue Schema Registry and Lambda. We advocate contemplating Kinesis Information Streams for low-latency, real-time use instances on AWS.
Concerns for replication into Apache Kafka
Apache Kafka is a high-throughput, scalable, and extremely obtainable open-source distributed occasion streaming platform utilized by hundreds of firms for high-performance information pipelines, streaming analytics, information integration, and mission-critical functions.
AWS provides Amazon MSK as a completely managed Kafka service. Amazon MSK gives the management airplane operations and runs open-source variations of Apache Kafka. Present functions, tooling, and plugins from companions and the Apache Kafka group are supported with out requiring adjustments to utility code.
You possibly can configure this pattern venture for Apache Kafka brokers straight or simply level in the direction of an Amazon MSK ARN for replication.
Though there’s nearly no restrict on the scale of the messages in Kafka, the default most message dimension is about to 1 MB by default, so we should ensure that the data, or serialized WALEdits, stay throughout the most message dimension for matters.
The Kafka producer tries to batch data collectively at any time when potential to restrict the variety of requests for extra effectivity. That is configurable by setting batch.dimension, linger.ms, and supply.timeout.ms.
In Kafka, matters are partitioned, and partitions are distributed between totally different Kafka brokers. This distributed placement permits for load balancing of customers and producers. When a brand new occasion is revealed to a subject, it’s appended to one of many matter’s partitions. Occasions with the identical occasion key are written to the identical partition, and Kafka ensures that any client of a given matter partition can all the time learn that partition’s occasions in precisely the identical order as they had been written. KafkaSinkImplementation makes use of a random partition key to distribute the messages evenly between the partitions. This might be primarily based on a heuristic perform, for instance primarily based on Area ID, if the order of the WALEdits or report locality is necessary by the customers.
Semantic ensures
Like several streaming utility, it’s necessary to think about semantic assure from the producer of messages, to acknowledge or fail the standing of supply of messages within the message queue and checkpointing on the buyer’s aspect. Primarily based on our use instances, we have to think about the next:
- At most as soon as supply – Messages are by no means delivered greater than as soon as, and there’s a probability of dropping messages
- At the least as soon as supply – Messages may be delivered greater than as soon as, with no lack of messages
- Precisely as soon as supply – Each message is delivered solely as soon as, and there’s no lack of messages
After adjustments are continued as WALs and in MemStore, the replicate technique in ReplicationEnpoint is named to duplicate a set of WAL entries and returns a Boolean (true/false) worth. If the returned worth is true, the entries are thought of efficiently replicated by HBase and the replicate technique is named for the subsequent batch of WAL entries. Relying on configuration, each KPL and Kafka producers may buffer the data for longer if configured for asynchronous writes. Failures may cause lack of entries, retries, and duplicate supply of data to the stream, which might be determinantal for synchronous or asynchronous message supply.
If our operations aren’t idempotent, you may checkpoint or test for distinctive sequence numbers on the buyer aspect. For a easy HBase report replication, RowKey operations are idempotent they usually carry a timestamp and sequence ID.
Abstract
Replication of HBase WALEdits into streams is a strong instrument that you should use in a number of use instances and together with different AWS providers. You possibly can create sensible options to additional course of data in actual time, audit the info, detect anomalies, set triggers on ingested information, or archive information in streams to be replayed on different HBase databases or storage providers from a cut-off date. This publish outlined some frequent use instances and options, together with some greatest practices when implementing your customized HBase streaming replication endpoints.
Evaluation, clone, and take a look at our HBase replication endpoint implementation from our GitHub repository and launch our pattern CloudFormation template.
We prefer to study your use instances. You probably have questions or recommendations, please depart a remark.
In regards to the Authors
 Amir Shenavandeh is a Senior Hadoop programs engineer and Amazon EMR subject material knowledgeable at Amazon Net Providers. He helps prospects with architectural steerage and optimization. He leverages his expertise to assist individuals deliver their concepts to life, specializing in distributed processing and large information architectures.
 Maryam Tavakoli is a Cloud Engineer and Amazon OpenSearch subject material knowledgeable at Amazon Net Providers. She helps prospects with their Analytics and Streaming workload optimization and is keen about fixing complicated issues with simplistic person expertise that may empower prospects to be extra productive.
[ad_2]

