



[ad_1]
Amazon Redshift is a quick, scalable, safe, and totally managed cloud information warehouse that makes it easy and cost-effective to research all of your information utilizing customary SQL. Amazon Redshift presents as much as 3 times higher value efficiency than every other cloud information warehouse, and might develop to petabyte scale. Immediately, tens of 1000’s of AWS prospects use Amazon Redshift to run mission-critical enterprise intelligence dashboards, analyze real-time streaming information, and run predictive analytics jobs.
Many options in Amazon Redshift entry different companies, for instance, when loading information from Amazon Easy Storage Service (Amazon S3). This requires you to create an AWS Identification and Entry Administration (IAM) function and grant that function to the Amazon Redshift cluster. Traditionally, this has required some extent of experience to arrange entry configuration with different AWS companies. For particulars about IAM roles and how one can use them, see Create an IAM function for Amazon Redshift.
This put up discusses the introduction of the default IAM function, which simplifies the usage of different companies resembling Amazon S3, Amazon SageMaker, AWS Lambda, Amazon Aurora, and AWS Glue by permitting you to create an IAM function from the Amazon Redshift console and assign it because the default IAM function to new or current Amazon Redshift cluster. The default IAM function simplifies SQL operations that entry different AWS companies (resembling COPY, UNLOAD, CREATE EXTERNAL FUNCTION, CREATE EXTERNAL SCHEMA, CREATE MODEL, or CREATE LIBRARY) by eliminating the necessity to specify the Amazon Useful resource Identify (ARN) for the IAM function.
Overview of resolution
The Amazon Redshift SQL instructions for COPY, UNLOAD, CREATE EXTERNAL FUNCTION, CREATE EXTERNAL TABLE, CREATE EXTERNAL SCHEMA, CREATE MODEL, or CREATE LIBRARY traditionally require the function ARN to be handed as an argument. Normally, these roles and accesses are arrange by admin customers. Most information analysts and information engineers utilizing these instructions aren’t licensed to view cluster authentication particulars. To get rid of the necessity to specify the ARN for the IAM function, Amazon Redshift now supplies a brand new managed IAM coverage AmazonRedshiftAllCommandsFullAccess, which has required privileges to make use of different associated companies resembling Amazon S3, SageMaker, Lambda, Aurora, and AWS Glue. This coverage is used for creating the default IAM function by way of the Amazon Redshift console. Finish-users can use the default IAM function by specifying IAM_ROLE with the DEFAULT key phrase. If you use the Amazon Redshift console to create IAM roles, Amazon Redshift retains monitor of all IAM roles created and preselects the latest default function for all new cluster creations and restores from snapshots.
The Amazon Redshift default IAM function simplifies authentication and authorization with the next advantages:
- It permits customers to run SQL instructions with out offering the IAM function’s ARN
- It avoids the necessity to use a number of AWS Administration Console pages to create the Amazon Redshift cluster and IAM function
- You don’t must reconfigure default IAM roles each time Amazon Redshift introduces a brand new function, which requires extra permission, as a result of Amazon Redshift can modify or lengthen the AWS managed coverage, which is hooked up to the default IAM function, as required
To show this, first we create an IAM function via the Amazon Redshift console that has a coverage with permissions to run SQL instructions resembling COPY, UNLOAD, CREATE EXTERNAL FUNCTION, CREATE EXTERNAL TABLE, CREATE EXTERNAL SCHEMA, CREATE MODEL, or CREATE LIBRARY. We additionally show how one can make an current IAM function the default function, and take away a task as default. Then we present you how one can use the default function with numerous SQL instructions, and how one can limit entry to the function.
Create a brand new cluster and arrange the IAM default function
The default IAM function is supported in each Amazon Redshift clusters and Amazon Redshift Serverless (preview). To create a brand new cluster and configure our IAM function because the default function, full the next steps:
- On the Amazon Redshift console, select Clusters within the navigation pane.
This web page lists the clusters in your account within the present Area. A subset of properties of every cluster can also be displayed.
- Select Create cluster.
- Comply with the directions to enter the properties for cluster configuration.
- If you already know the required dimension of your cluster (that’s, the node sort and variety of nodes), select I’ll select.
- Select the node sort and variety of nodes.
If you happen to don’t know the way giant to dimension your cluster, select Assist me select. Doing this begins a sizing calculator that asks you questions in regards to the dimension and question traits of the information that you just plan to retailer in your information warehouse.
- Comply with the directions to enter properties for database configurations.
- Underneath Related IAM roles, on the Handle IAM roles menu, select Create IAM function.
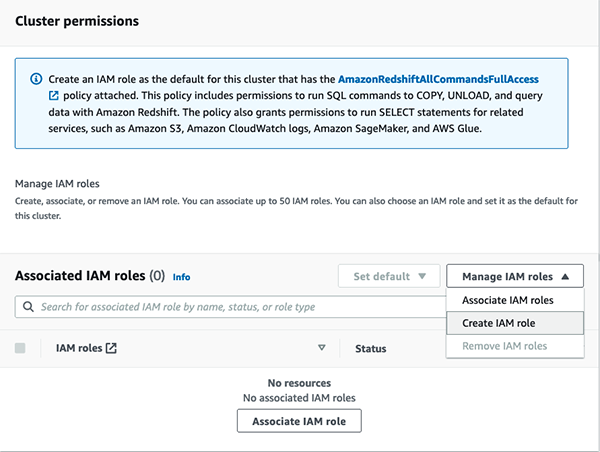
- To specify an S3 bucket for the IAM function to entry, select one of many following strategies:
- Select No extra S3 bucket to create the IAM function with out specifying particular S3 buckets.
- Select Any S3 bucket to permit customers which have entry to your Amazon Redshift cluster to additionally entry any S3 bucket and its contents in your AWS account.
- Select Particular S3 buckets to specify a number of S3 buckets that the IAM function being created has permission to entry. Then select a number of S3 buckets from the desk.
- Select Create IAM function as default.

Amazon Redshift robotically creates and units the IAM function because the default in your cluster.
- Select Create cluster to create the cluster.
The cluster may take a number of minutes to be prepared to make use of. You possibly can confirm the brand new default IAM function below Cluster permissions.

You possibly can solely have one IAM function set because the default for the cluster. If you happen to try and create one other IAM function because the default for the cluster when an current IAM function is at the moment assigned because the default, the brand new IAM function replaces the opposite IAM function as default.
Make an current IAM function the default in your new or current cluster
You can even connect your current function to the cluster and make it default IAM function for extra granular management of permissions with personalized managed polices.
- On the Amazon Redshift console, select Clusters within the navigation pane.
- Select the cluster you need to affiliate IAM roles with.
- Underneath Related IAM roles, on the Handle IAM roles menu, select Related IAM roles.
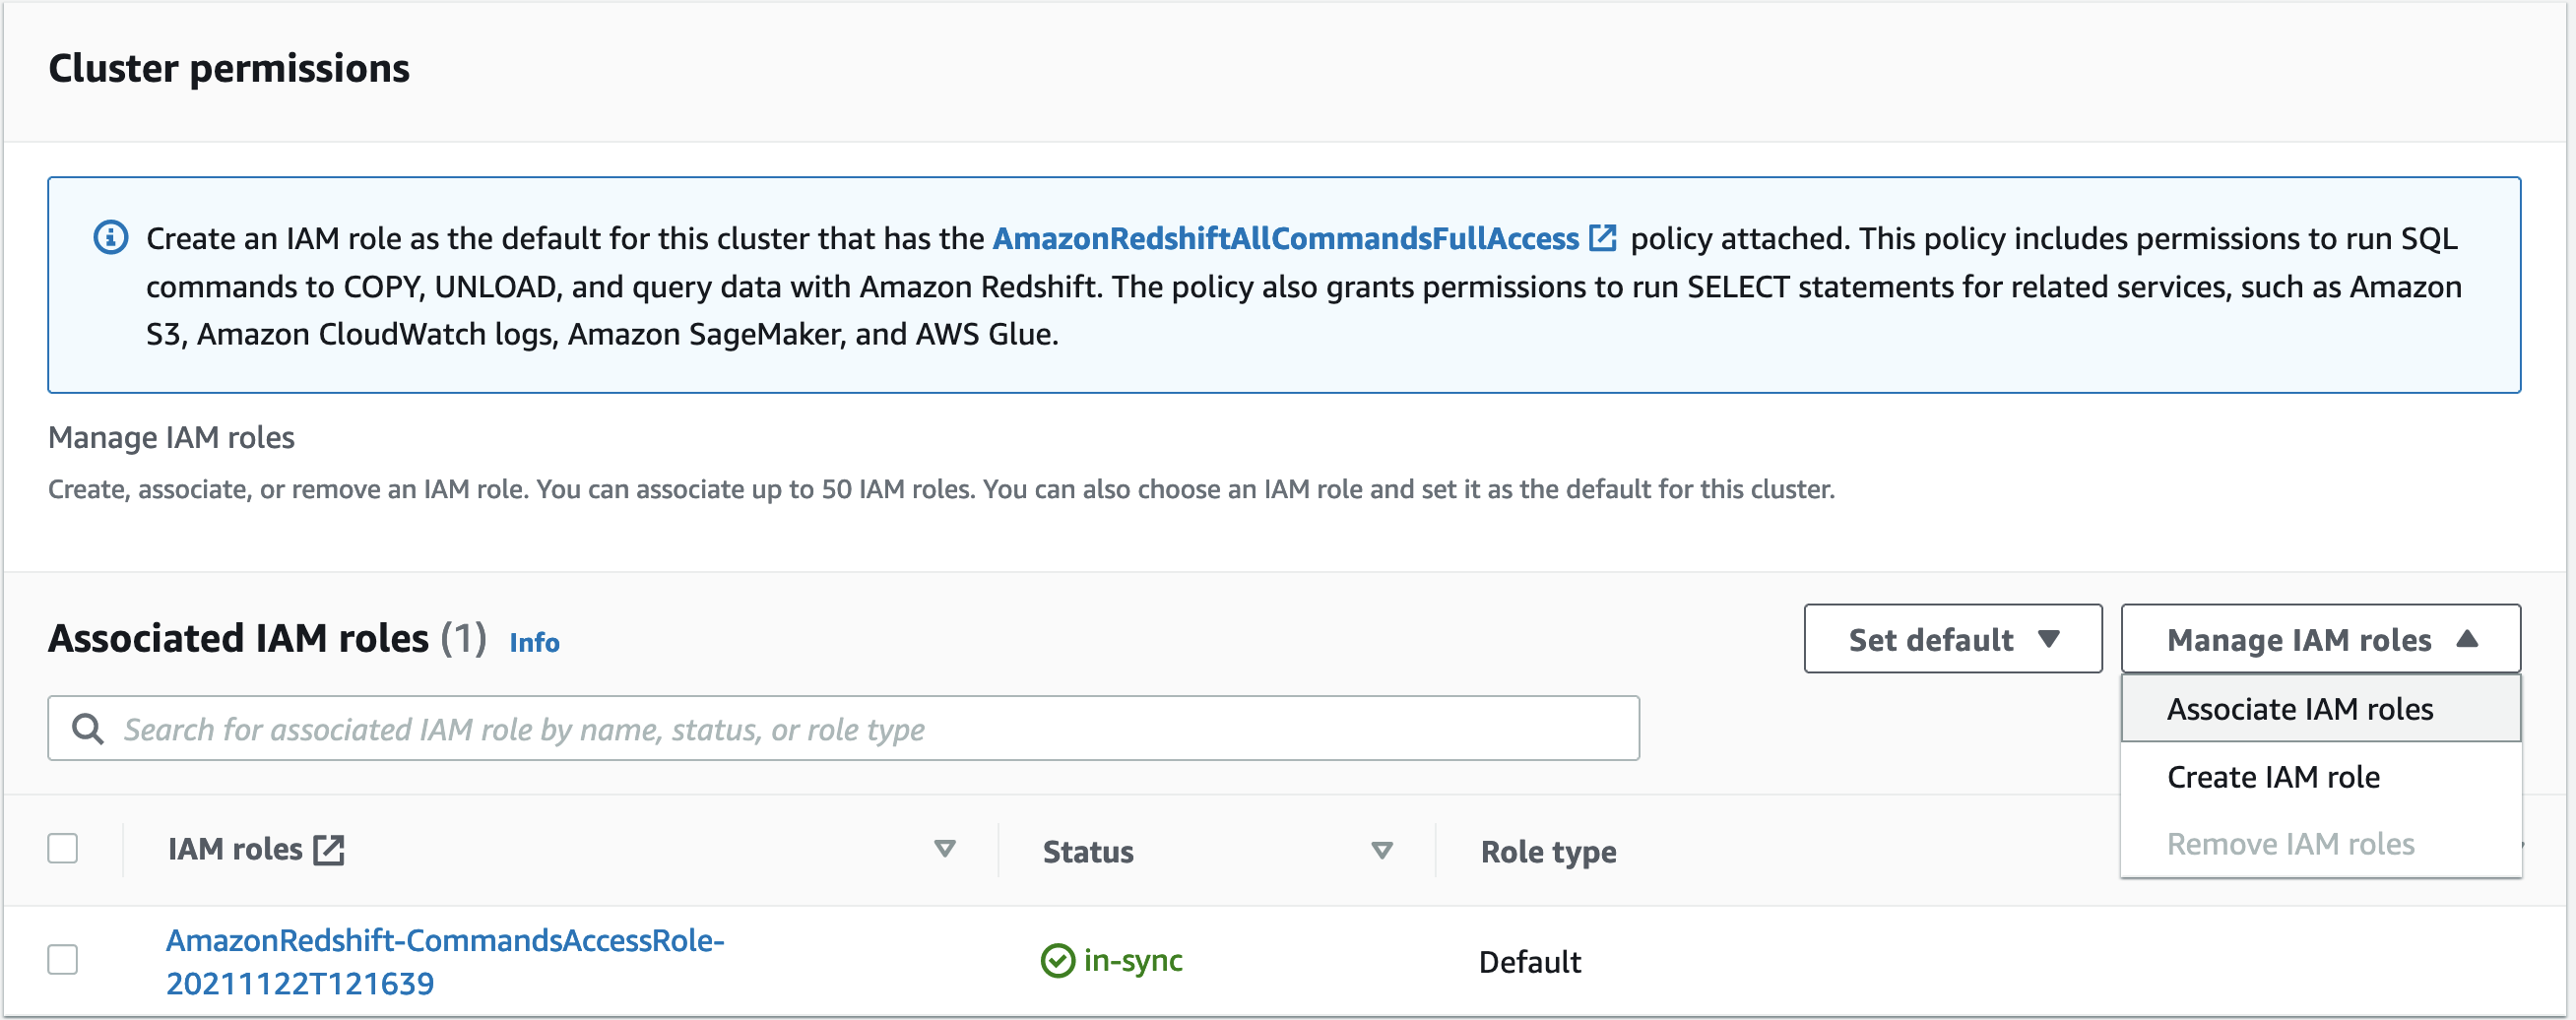
- Choose an IAM function that you really want make the default for the cluster.
- Select Affiliate IAM roles.

- Underneath Related IAM roles, on the Set default menu, select Make default.

- When prompted, select Set default to verify making the required IAM function the default.
- Select Affirm.

Your IAM function is now listed as default.

Make an IAM function now not default in your cluster
You may make an IAM function now not the default function by altering the cluster permissions.
- On the Amazon Redshift console, select Clusters within the navigation pane.
- Select the cluster that you just need to affiliate IAM roles with.
- Underneath Related IAM roles, choose the default IAM function.
- On the Set default menu, select Clear default.

- When prompted, select Clear default to verify.
Use the default IAM function to run SQL instructions
Now we show how one can use the default IAM function in SQL instructions like COPY, UNLOAD, CREATE EXTERNAL FUNCTION, CREATE EXTERNAL TABLE, CREATE EXTERNAL SCHEMA, and CREATE MODEL utilizing Amazon Redshift ML.
To run SQL instructions, we use Amazon Redshift Question Editor V2, a web-based software that you need to use to discover, analyze, share, and collaborate on information saved on Amazon Redshift. It helps information warehouses on Amazon Redshift and information lakes via Amazon Redshift Spectrum. Nonetheless, you need to use the default IAM function with any instruments of your alternative.
For extra data, see Introducing Amazon Redshift Question Editor V2, a Free Internet-based Question Authoring Instrument for Knowledge Analysts.
First confirm the cluster is utilizing the default IAM function, as proven within the following screenshot.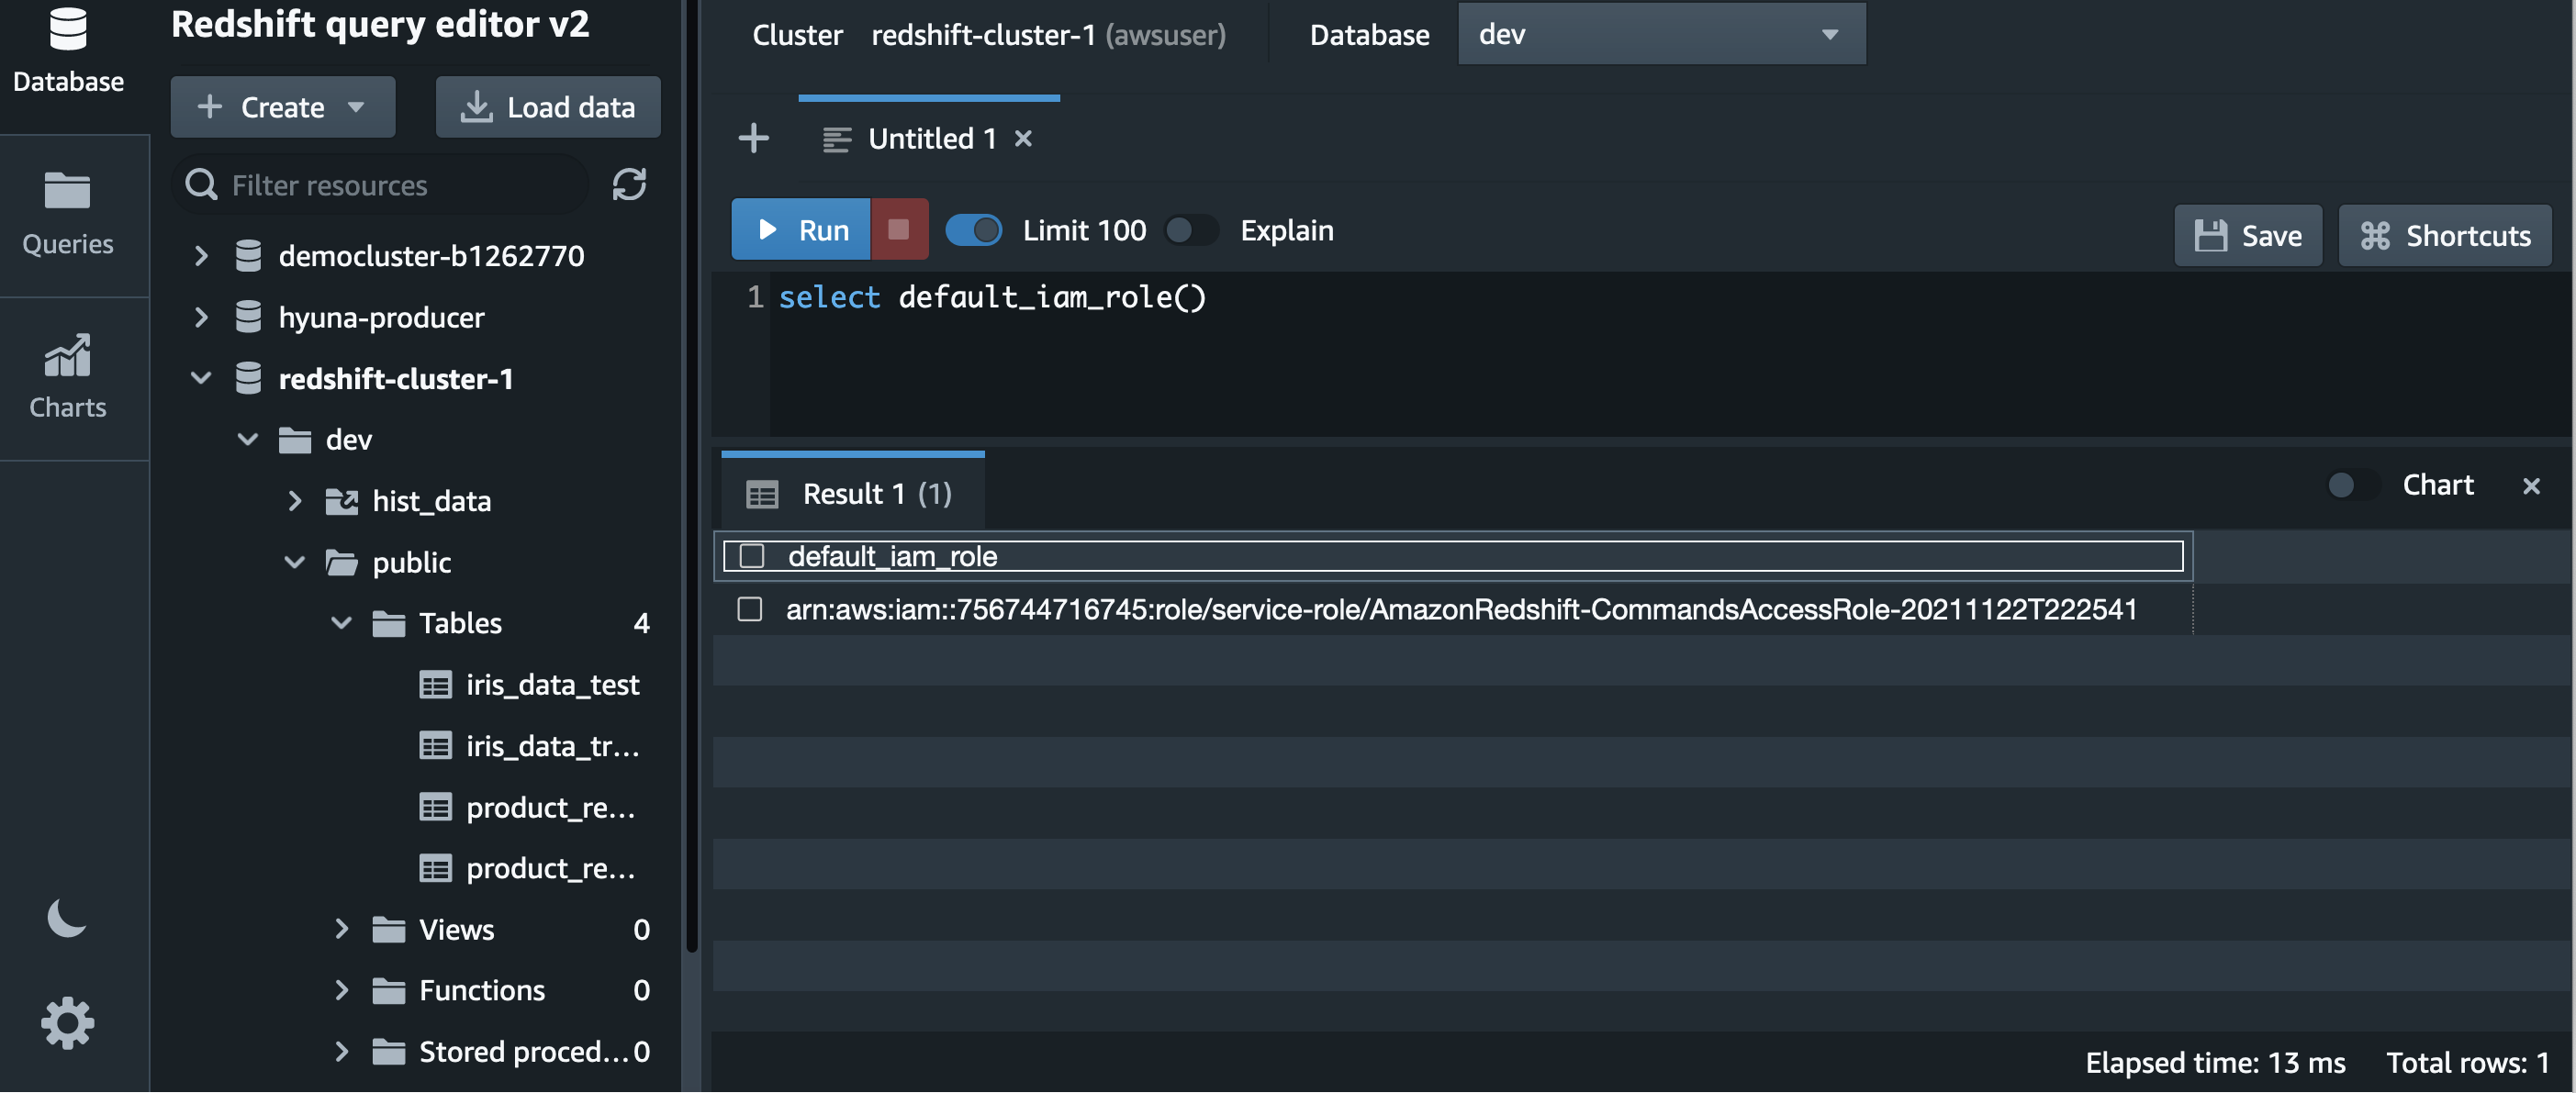
Load information from Amazon S3
The SQL within the following screenshot describes how one can load information from Amazon S3 utilizing the default IAM function.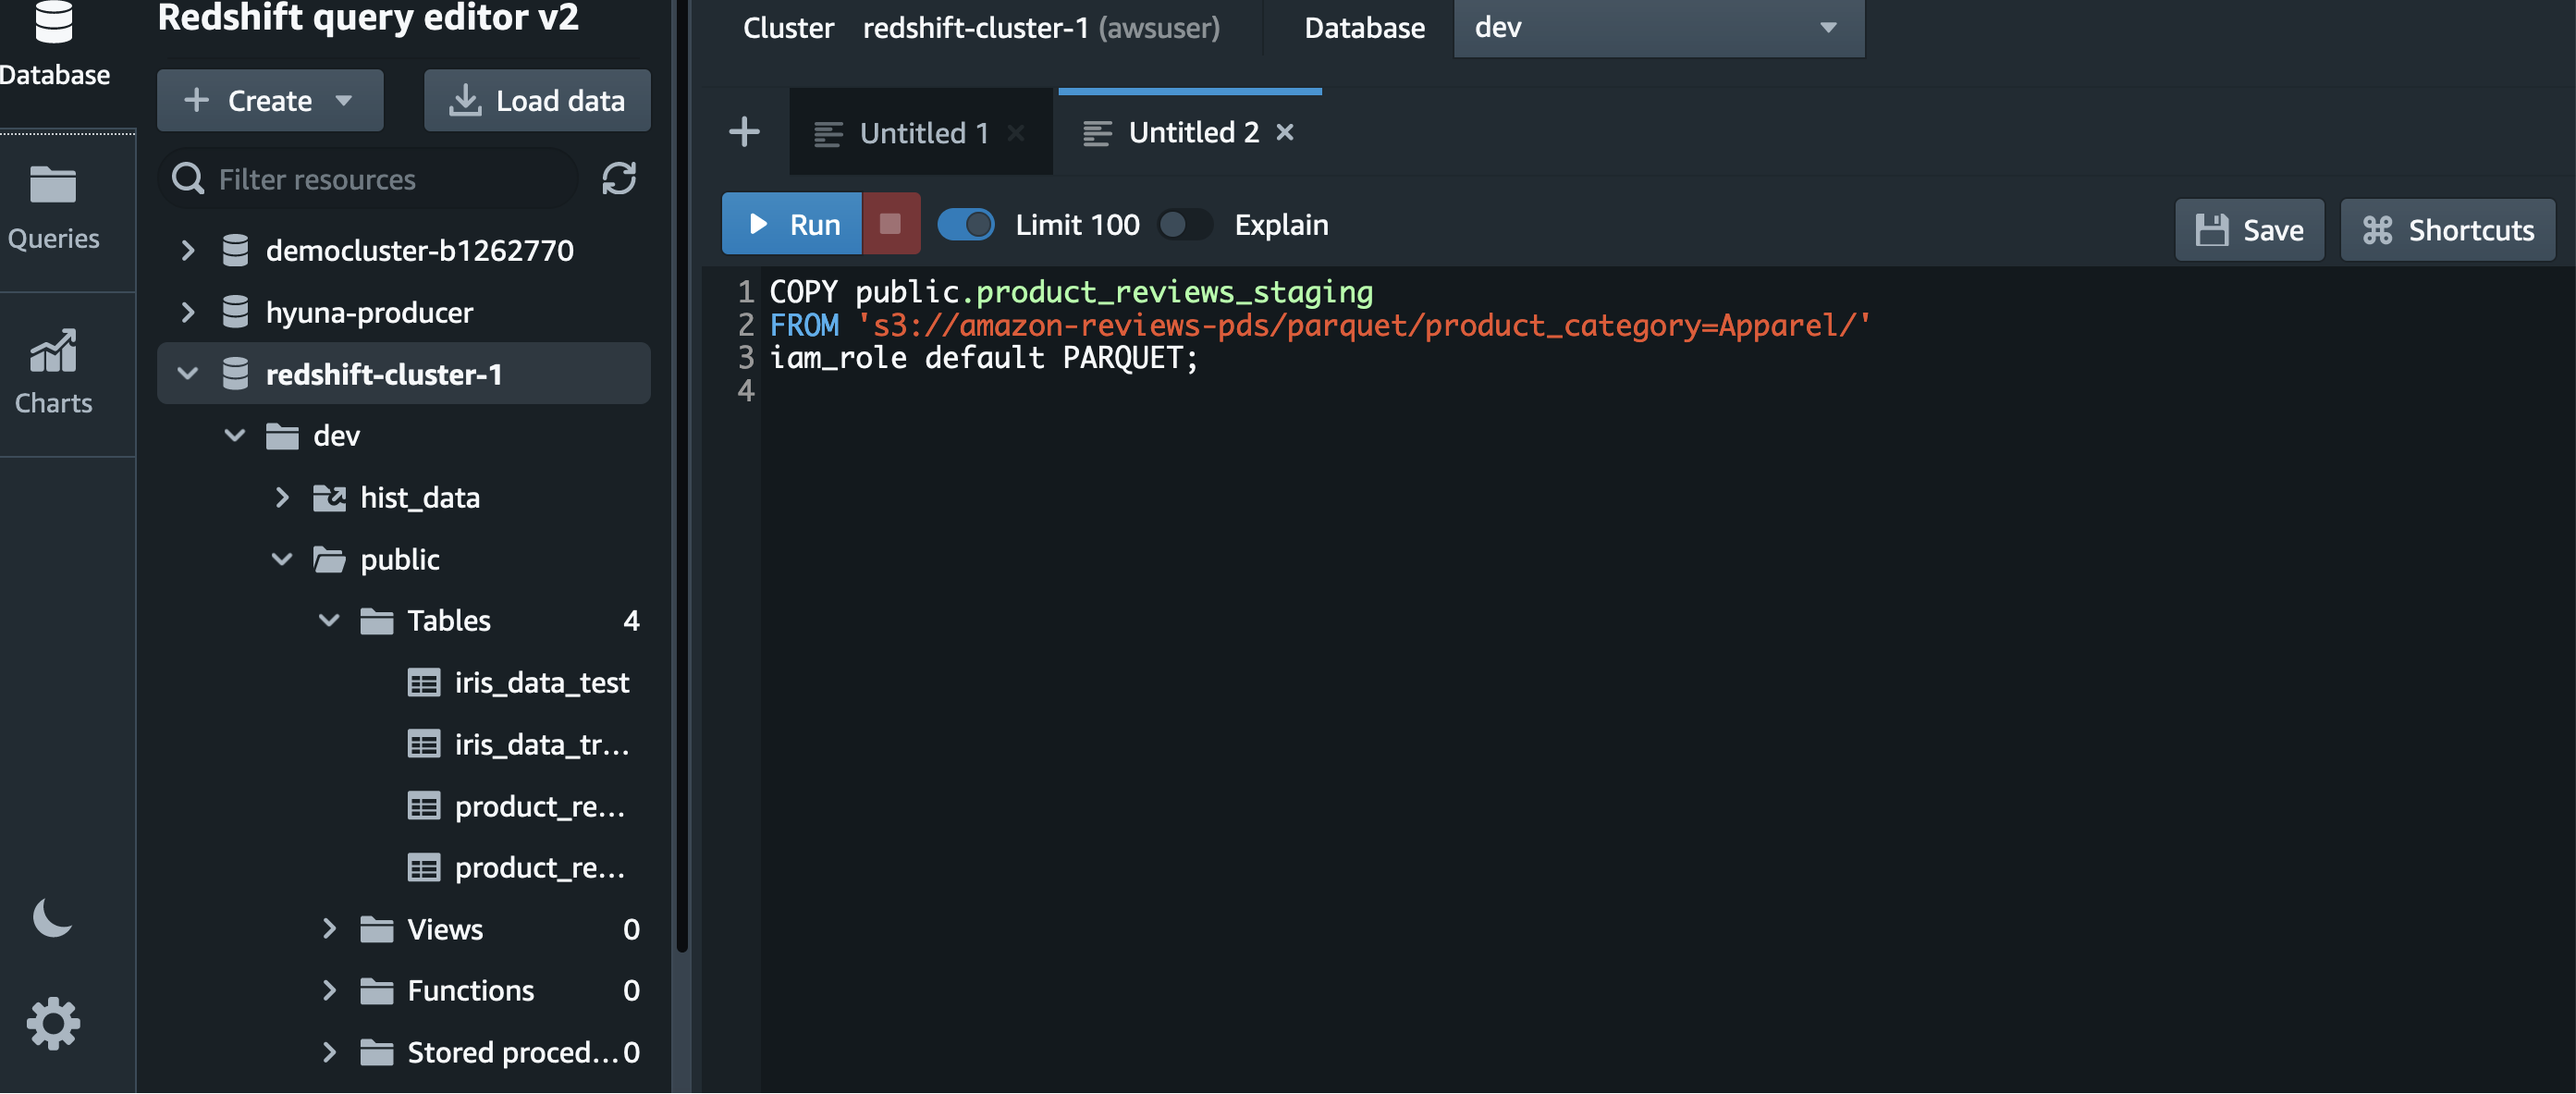
Unload information to Amazon S3
With an Amazon Redshift lake home structure, you’ll be able to question information in your information lake and write information again to your information lake in open codecs utilizing the UNLOAD command. After the information recordsdata are in Amazon S3, you’ll be able to share the information with different companies for additional processing.
The SQL within the following screenshot describes how one can unload information to Amazon S3 utilizing the default IAM function.
Create an ML mannequin
Redshift ML allows SQL customers to create, prepare, and deploy machine studying (ML) fashions utilizing acquainted SQL instructions. The SQL within the following screenshot describes how one can construct an ML mannequin utilizing the default IAM function. We use the Iris dataset from the UCI Machine Studying Repository.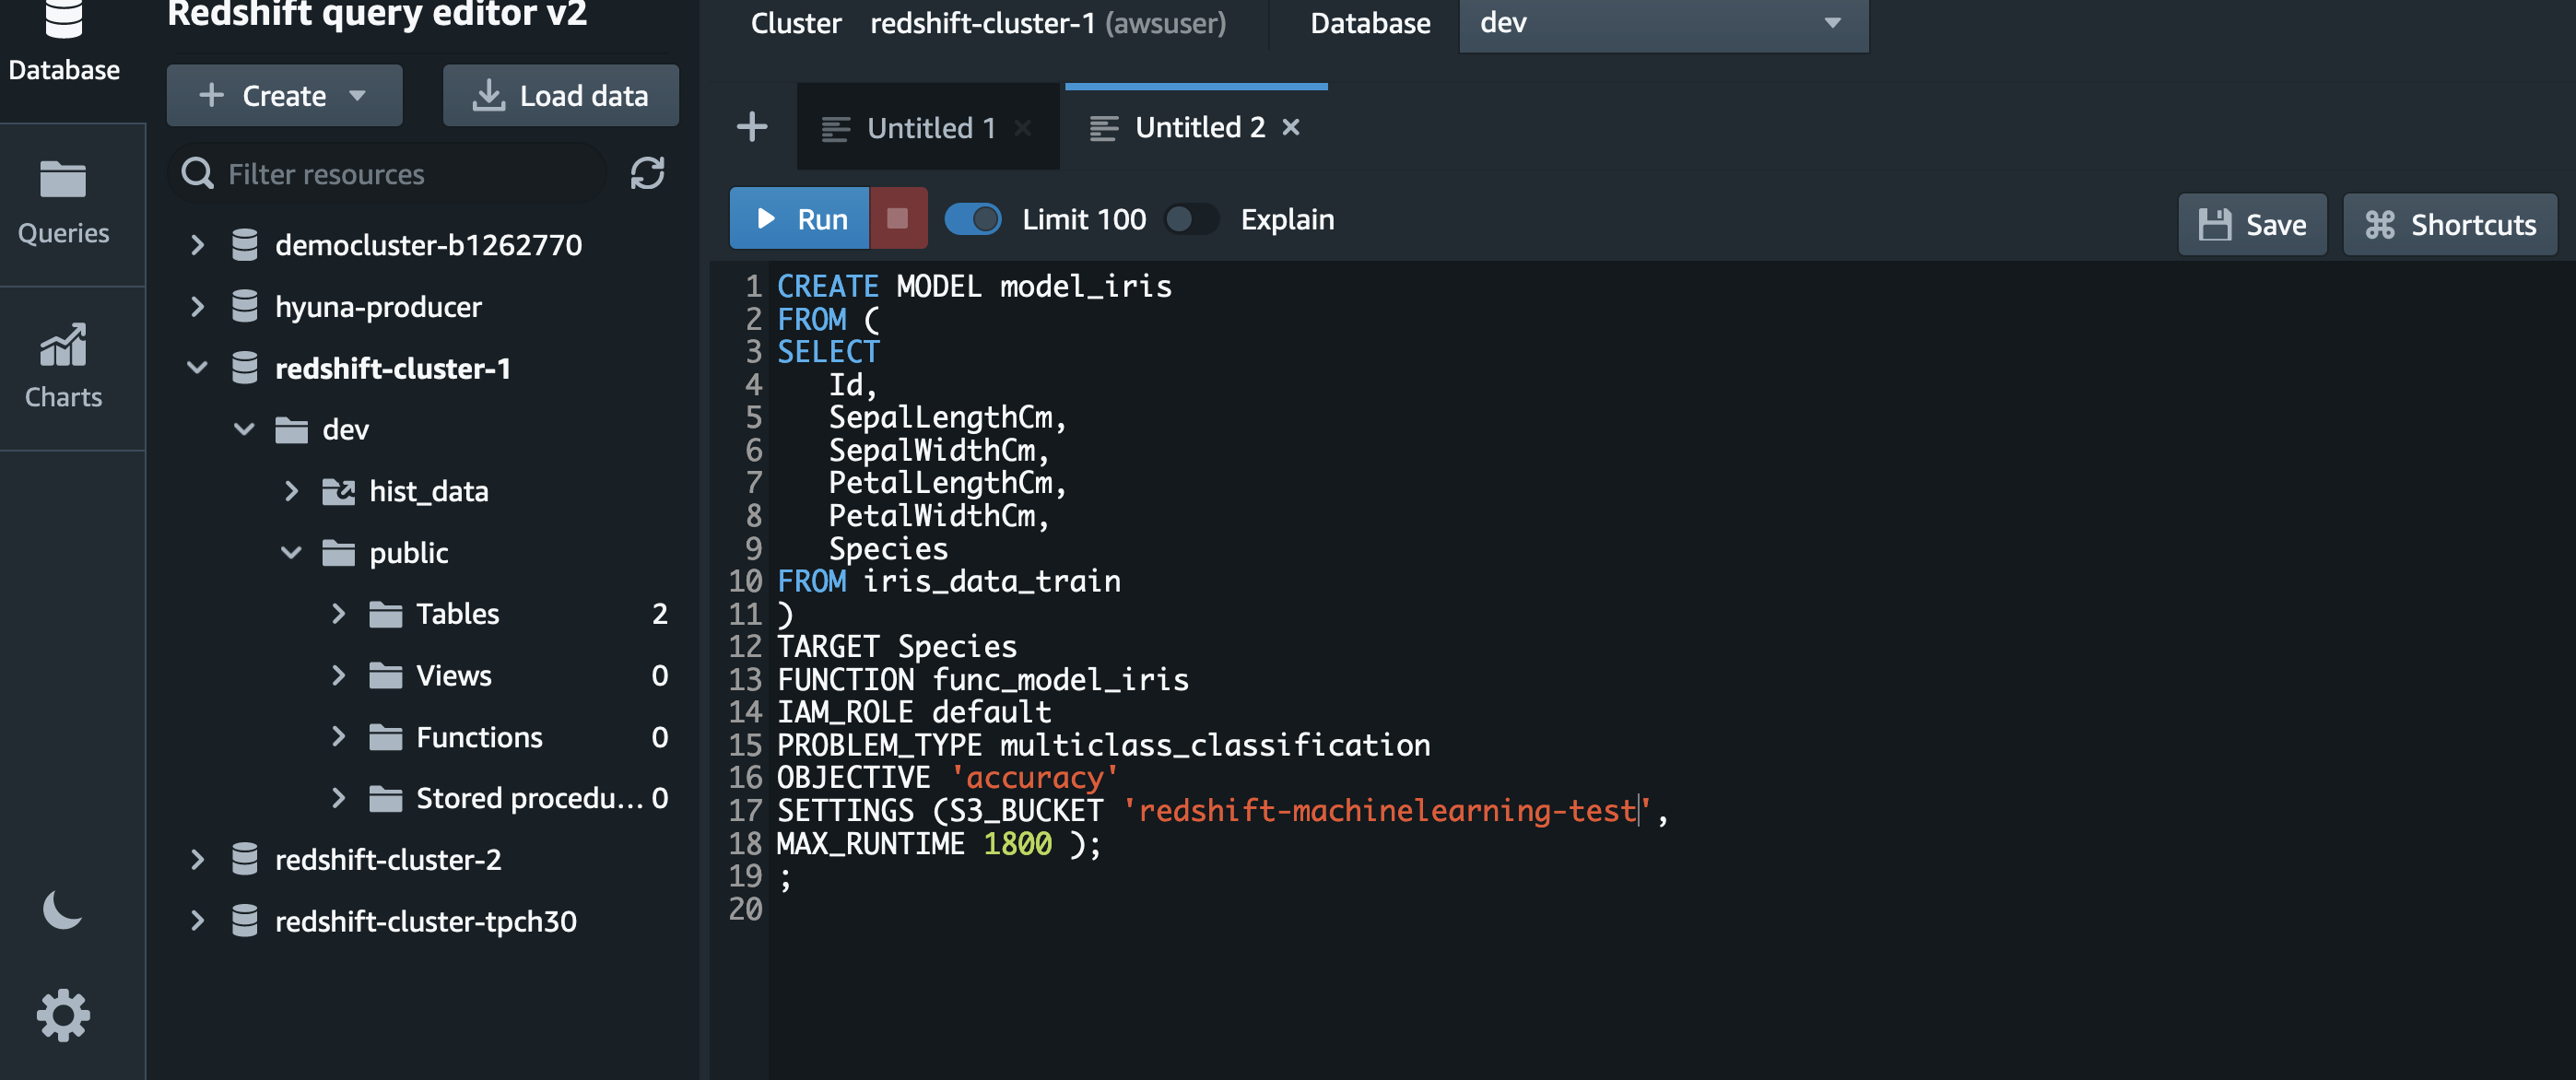
Create an exterior schema and exterior desk
Redshift Spectrum is a function of Amazon Redshift that lets you carry out SQL queries on information saved in S3 buckets utilizing exterior schema and exterior tables. This eliminates the necessity to transfer information from a storage service to a database, and as a substitute straight queries information inside an S3 bucket. Redshift Spectrum additionally expands the scope of a given question as a result of it extends past a consumer’s current Amazon Redshift information warehouse nodes and into giant volumes of unstructured S3 information lakes.
The next SQL describes how one can use the default IAM function within the CREATE EXTERNAL SCHEMA command. For extra data, see Querying exterior information utilizing Amazon Redshift Spectrum
The default IAM function requires redshift as a part of the catalog database title or sources tagged with the Amazon Redshift service tag because of safety issues. You possibly can customise the coverage hooked up to default function as per your safety requirement. Within the following instance, we use the AWS Glue Knowledge Catalog title redshift_data.
Limit entry to the default IAM function
To regulate entry privileges of the IAM function created and set it as default in your Amazon Redshift cluster, use the ASSUMEROLE privilege. This entry management applies to database customers and teams once they run instructions resembling COPY and UNLOAD. After you grant the ASSUMEROLE privilege to a consumer or group for the IAM function, the consumer or group can assume that function when operating these instructions. With the ASSUMEROLE privilege, you’ll be able to grant entry to the suitable instructions as required.
Finest practices
Amazon Redshift makes use of the AWS safety frameworks to implement industry-leading safety within the areas of authentication, entry management, auditing, logging, compliance, information safety, and community safety. For extra data, consult with Safety in Amazon Redshift and Safety finest practices in IAM.
Conclusion
This put up confirmed you the way the default IAM function simplifies SQL operations that entry different AWS companies by eliminating the necessity to specify the ARN for the IAM function. This new performance helps make Amazon Redshift simpler than ever to make use of, and reduces reliance on an administrator to wrangle these permissions.
As an administrator, you can begin utilizing the default IAM function to grant IAM permissions to your Redshift cluster and permit your end-users resembling information analysts and builders to make use of default IAM function with their SQL instructions with out having to supply the ARN for the IAM function.
Concerning the Authors
 Nita Shah is an Analytics Specialist Options Architect at AWS based mostly out of New York. She has been constructing information warehouse options for over 20 years and makes a speciality of Amazon Redshift. She is targeted on serving to prospects design and construct enterprise-scale well-architected analytics and determination assist platforms.
 Evgenii Rublev is a Software program Improvement Engineer on the AWS Redshift workforce. He has labored on constructing end-to-end functions for over 10 years. He’s obsessed with improvements in constructing high-availability and high-performance functions to drive a greater buyer expertise. Exterior of labor, Evgenii enjoys spending time along with his household, touring, and studying books.
 Debu Panda, a Principal Product Supervisor at AWS, is an {industry} chief in analytics, software platform, and database applied sciences, and has greater than 25 years of expertise within the IT world. Debu has printed quite a few articles on analytics, enterprise Java, and databases and has introduced at a number of conferences resembling re:Invent, Oracle Open World, and Java One. He’s lead creator of the EJB 3 in Motion (Manning Publications 2007, 2014) and Middleware Administration (Packt).
[ad_2]

