


[ad_1]
Introduction
I’m joyful to report a brand new main launch of lime has landed on CRAN. lime is an R port of the Python library of the identical title by Marco Ribeiro that permits the consumer to pry open black field machine studying fashions and clarify their outcomes on a per-observation foundation. It really works by modelling the end result of the black field within the native neighborhood across the commentary to elucidate and utilizing this native mannequin to elucidate why (not how) the black field did what it did. For extra details about the idea of lime I’ll direct you to the article introducing the methodology.
New options
The meat of this launch facilities round two new options which are considerably linked: Native assist for keras fashions and assist for explaining picture fashions.
keras and pictures
J.J. Allaire was sort sufficient to namedrop lime throughout his keynote introduction of the tensorflow and keras packages and I felt compelled to assist them natively. As keras is by far the most well-liked solution to interface with tensorflow it’s first in line for build-in assist. The addition of keras signifies that lime now straight helps fashions from the next packages:
If you happen to’re engaged on one thing too obscure or leading edge to not be capable to use these packages it’s nonetheless potential to make your mannequin lime compliant by offering predict_model() and model_type() strategies for it.
keras fashions are used similar to every other mannequin, by passing it into the lime() perform together with the coaching information in an effort to create an explainer object. As a result of we’re quickly going to speak about picture fashions, we’ll be utilizing one of many pre-trained ImageNet fashions that’s obtainable from keras itself:
Mannequin
______________________________________________________________________________________________
Layer (kind)                              Output Form                         Param #
==============================================================================================
input_1 (InputLayer)                      (None, 224, 224, 3)                  0
______________________________________________________________________________________________
block1_conv1 (Conv2D)                     (None, 224, 224, 64)                 1792
______________________________________________________________________________________________
block1_conv2 (Conv2D)                     (None, 224, 224, 64)                 36928
______________________________________________________________________________________________
block1_pool (MaxPooling2D)                (None, 112, 112, 64)                 0
______________________________________________________________________________________________
block2_conv1 (Conv2D)                     (None, 112, 112, 128)                73856
______________________________________________________________________________________________
block2_conv2 (Conv2D)                     (None, 112, 112, 128)                147584
______________________________________________________________________________________________
block2_pool (MaxPooling2D)                (None, 56, 56, 128)                  0
______________________________________________________________________________________________
block3_conv1 (Conv2D)                     (None, 56, 56, 256)                  295168
______________________________________________________________________________________________
block3_conv2 (Conv2D)                     (None, 56, 56, 256)                  590080
______________________________________________________________________________________________
block3_conv3 (Conv2D)                     (None, 56, 56, 256)                  590080
______________________________________________________________________________________________
block3_pool (MaxPooling2D)                (None, 28, 28, 256)                  0
______________________________________________________________________________________________
block4_conv1 (Conv2D)                     (None, 28, 28, 512)                  1180160
______________________________________________________________________________________________
block4_conv2 (Conv2D)                     (None, 28, 28, 512)                  2359808
______________________________________________________________________________________________
block4_conv3 (Conv2D)                     (None, 28, 28, 512)                  2359808
______________________________________________________________________________________________
block4_pool (MaxPooling2D)                (None, 14, 14, 512)                  0
______________________________________________________________________________________________
block5_conv1 (Conv2D)                     (None, 14, 14, 512)                  2359808
______________________________________________________________________________________________
block5_conv2 (Conv2D)                     (None, 14, 14, 512)                  2359808
______________________________________________________________________________________________
block5_conv3 (Conv2D)                     (None, 14, 14, 512)                  2359808
______________________________________________________________________________________________
block5_pool (MaxPooling2D)                (None, 7, 7, 512)                    0
______________________________________________________________________________________________
flatten (Flatten)                         (None, 25088)                        0
______________________________________________________________________________________________
fc1 (Dense)                               (None, 4096)                         102764544
______________________________________________________________________________________________
fc2 (Dense)                               (None, 4096)                         16781312
______________________________________________________________________________________________
predictions (Dense)                       (None, 1000)                         4097000
==============================================================================================
Whole params: 138,357,544
Trainable params: 138,357,544
Non-trainable params: 0
______________________________________________________________________________________________
The vgg16 mannequin is a picture classification mannequin that has been construct as a part of the ImageNet competitors the place the objective is to categorise photos into 1000 classes with the best accuracy. As we will see it’s pretty sophisticated.
To be able to create an explainer we might want to go within the coaching information as effectively. For picture information the coaching information is admittedly solely used to inform lime that we’re coping with a picture mannequin, so any picture will suffice. The format for the coaching information is solely the trail to the pictures, and since the web runs on kitten photos we’ll use certainly one of these:

As with textual content fashions the explainer might want to know how one can put together the enter information for the mannequin. For keras fashions this implies formatting the picture information as tensors. Fortunately keras comes with a variety of instruments for reshaping picture information:
image_prep <- perform(x) {
  arrays <- lapply(x, perform(path) {
    img <- image_load(path, target_size = c(224,224))
    x <- image_to_array(img)
    x <- array_reshape(x, c(1, dim(x)))
    x <- imagenet_preprocess_input(x)
  })
  do.name(abind::abind, c(arrays, listing(alongside = 1)))
}
explainer <- lime(img_path, mannequin, image_prep)
We now have an explainer mannequin for understanding how the vgg16 neural community makes its predictions. Earlier than we go alongside, lets see what the mannequin consider our kitten:
res <- predict(mannequin, image_prep(img_path))
imagenet_decode_predictions(res)
[[1]]
  class_name class_description      rating
1  n02124075      Egyptian_cat 0.48913878
2  n02123045             tabby 0.15177219
3  n02123159         tiger_cat 0.10270492
4  n02127052              lynx 0.02638111
5  n03793489             mouse 0.00852214
So, it’s fairly certain about the entire cat factor. The rationale we have to use imagenet_decode_predictions() is that the output of a keras mannequin is at all times only a anonymous tensor:
[1] 1 1000NULLWe’re used to classifiers figuring out the category labels, however this isn’t the case for keras. Motivated by this, lime now have a solution to outline/overwrite the category labels of a mannequin, utilizing the as_classifier() perform. Let’s redo our explainer:
model_labels <- readRDS(system.file('extdata', 'imagenet_labels.rds', bundle = 'lime'))
explainer <- lime(img_path, as_classifier(mannequin, model_labels), image_prep)
There’s additionally an
as_regressor()perform which tellslime, undoubtedly, that the mannequin is a regression mannequin. Most fashions may be introspected to see which kind of mannequin they’re, however neural networks doesn’t actually care.limeguesses the mannequin kind from the activation used within the final layer (linear activation == regression), but when that heuristic fails thenas_regressor()/as_classifier()can be utilized.
We at the moment are able to poke into the mannequin and discover out what makes it assume our picture is of an Egyptian cat. However… first I’ll have to speak about yet one more idea: superpixels (I promise I’ll get to the reason half in a bit).
To be able to create significant permutations of our picture (keep in mind, that is the central concept in lime), now we have to outline how to take action. The permutations must be substantial sufficient to have an effect on the picture, however not a lot that the mannequin utterly fails to recognise the content material in each case – additional, they need to result in an interpretable outcome. The idea of superpixels lends itself effectively to those constraints. Briefly, a superpixel is a patch of an space with excessive homogeneity, and superpixel segmentation is a clustering of picture pixels into various superpixels. By segmenting the picture to elucidate into superpixels we will flip space of contextual similarity on and off through the permutations and discover out if that space is necessary. It’s nonetheless essential to experiment a bit because the optimum variety of superpixels rely on the content material of the picture. Keep in mind, we want them to be massive sufficient to have an effect however not so massive that the category chance turns into successfully binary. lime comes with a perform to evaluate the superpixel segmentation earlier than starting the reason and it is strongly recommended to play with it a bit — with time you’ll possible get a really feel for the appropriate values:
# default
plot_superpixels(img_path)

# Altering some settings
plot_superpixels(img_path, n_superpixels = 200, weight = 40)

The default is ready to a reasonably low variety of superpixels — if the topic of curiosity is comparatively small it could be essential to extend the variety of superpixels in order that the complete topic doesn’t find yourself in a single, or a couple of superpixels. The weight parameter will will let you make the segments extra compact by weighting spatial distance increased than color distance. For this instance we’ll persist with the defaults.
Bear in mind that explaining picture fashions is way heavier than tabular or textual content information. In impact it can create 1000 new photographs per clarification (default permutation dimension for photographs) and run these by way of the mannequin. As picture classification fashions are sometimes fairly heavy, this can lead to computation time measured in minutes. The permutation is batched (default to 10 permutations per batch), so that you shouldn’t be afraid of operating out of RAM or hard-drive house.
clarification <- clarify(img_path, explainer, n_labels = 2, n_features = 20)
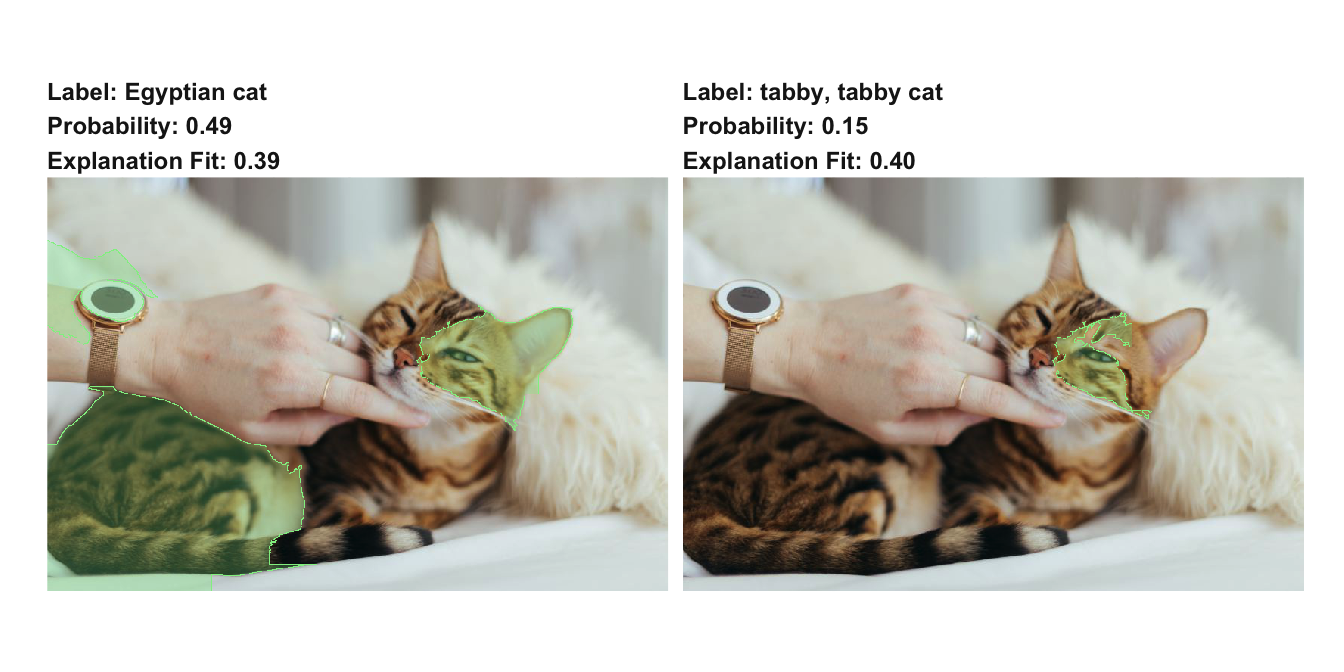
The output of a picture clarification is an information body of the identical format as that from tabular and textual content information. Every function will likely be a superpixel and the pixel vary of the superpixel will likely be used as its description. Normally the reason will solely make sense within the context of the picture itself, so the brand new model of lime additionally comes with a plot_image_explanation() perform to just do that. Let’s see what our clarification have to inform us:
plot_image_explanation(clarification)

We are able to see that the mannequin, for each the most important predicted lessons, focuses on the cat, which is good since they’re each totally different cat breeds. The plot perform acquired a couple of totally different features that will help you tweak the visible, and it filters low scoring superpixels away by default. An alternate view that places extra give attention to the related superpixels, however removes the context may be seen by utilizing show = 'block':
plot_image_explanation(clarification, show = 'block', threshold = 0.01)

Whereas not as frequent with picture explanations it’s also potential to have a look at the areas of a picture that contradicts the category:
plot_image_explanation(clarification, threshold = 0, show_negative = TRUE, fill_alpha = 0.6)

As every clarification takes longer time to create and must be tweaked on a per-image foundation, picture explanations are usually not one thing that you just’ll create in massive batches as you would possibly do with tabular and textual content information. Nonetheless, a couple of explanations would possibly will let you perceive your mannequin higher and be used for speaking the workings of your mannequin. Additional, because the time-limiting think about picture explanations are the picture classifier and never lime itself, it’s sure to enhance as picture classifiers turns into extra performant.
Seize again
Aside from keras and picture assist, a slew of different options and enhancements have been added. Right here’s a fast overview:
- All clarification plots now embrace the match of the ridge regression used to make the reason. This makes it simple to evaluate how good the assumptions about native linearity are saved.
- When explaining tabular information the default distance measure is now
'gower'from thegowerbundle.gowermakes it potential to measure distances between heterogeneous information with out changing all options to numeric and experimenting with totally different exponential kernels. - When explaining tabular information numerical options will not be sampled from a standard distribution throughout permutations, however from a kernel density outlined by the coaching information. This could be certain that the permutations are extra consultant of the anticipated enter.
Wrapping up
This launch represents an necessary milestone for lime in R. With the addition of picture explanations the lime bundle is now on par or above its Python relative, feature-wise. Additional growth will give attention to enhancing the efficiency of the mannequin, e.g. by including parallelisation or enhancing the native mannequin definition, in addition to exploring various clarification sorts akin to anchor.
Joyful Explaining!
[ad_2]

