



[ad_1]
Amazon Redshift is the quickest, most generally used, totally managed, and petabyte-scale cloud information warehouse. Tens of 1000’s of consumers use Amazon Redshift to course of exabytes of knowledge on daily basis to energy their analytics workloads. Information analysts and database builders wish to use this information to coach machine studying (ML) fashions, which may then be used to generate insights to be used circumstances resembling forecasting income, predicting buyer churn, and detecting anomalies.
Amazon Redshift ML makes it straightforward for SQL customers to create, prepare, and deploy ML fashions utilizing acquainted SQL instructions. In earlier posts, we lined how Amazon Redshift helps supervised studying that features regression, binary classification, and multiclass classification, in addition to coaching fashions utilizing XGBoost and offering superior choices resembling preprocessors, drawback sort, and hyperparameters.
On this put up, we use Redshift ML to carry out unsupervised studying on unlabeled coaching information utilizing the Ok-means algorithm. This algorithm solves clustering issues the place you wish to uncover groupings within the information. Unlabeled information is grouped and partitioned primarily based on their similarities and variations. By grouping, the Ok-means algorithm iteratively determines the perfect centroids and assigns every member to the closest centroid. Information factors nearest the identical centroid belong to the identical group. Members of a bunch are as related as attainable to different members in the identical group, and as totally different as attainable from members of different teams. To study extra about Ok-means clustering, see Ok-means clustering with Amazon SageMaker.
Resolution overview
The next are some use circumstances for Ok-means:
- Ecommerce and retail – Section your prospects by buy historical past, shops they visited, or clickstream exercise.
- Healthcare – Group related photographs for picture detection. For instance, you’ll be able to detect patterns for ailments or profitable remedy eventualities.
- Finance – Detect fraud by detecting anomalies within the dataset. For instance, you’ll be able to detect bank card fraud by irregular buy patterns.
- Expertise – Construct a community intrusion detection system that goals to establish assaults or malicious exercise.
- Meteorology – Detect anomalies in sensor information assortment resembling storm forecasting.
In our instance, we use Ok-means on the International Database of Occasions, Language, and Tone (GDELT) dataset, which displays world information internationally, and the info is saved for each second of on daily basis. This info is freely obtainable as a part of the Registry of Open Information on AWS.
The info is saved as a number of information on Amazon Easy Storage Service (Amazon S3), with two totally different codecs: historic, which covers the years 1979–2013, and every day updates, which cowl the years 2013 and later. For this instance, we use the historic format and herald 1979 information.
For our use case, we use a subset of the info’s attributes:
- EventCode – The uncooked CAMEO motion code describing the motion that
Actor1carried out uponActor2. - NumArticles – The full variety of supply paperwork containing a number of mentions of this occasion. You should use this to evaluate the significance of an occasion. The extra dialogue of that occasion, the extra probably it’s to be vital.
- AvgTone – The typical tone of all paperwork containing a number of mentions of this occasion. The rating ranges from -100 (extraordinarily damaging) to +100 (extraordinarily constructive). Widespread values vary between -10 and +10, with 0 indicating impartial.
- Actor1Geo_Lat – The centroid latitude of the
Actor1landmark for mapping. - Actor1Geo_Long – The centroid longitude of the
Actor1landmark for mapping. - Actor2Geo_Lat – The centroid latitude of the
Actor2landmark for mapping. - Actor2Geo_Long – The centroid longitude of the
Actor2landmark for mapping.
Every row corresponds to an occasion at a selected location. For instance, rows 53-57 within the file 1979.csv which we’ll use under, appear to all seek advice from interactions between FRA and AFR, coping with session and diplomatic relations with a principally constructive tone. It’s onerous, if not unimaginable for us to make sense of such information at scale. Clusters of occasions, both with the same tone, occurring in related areas or between related actors, are helpful in visualizing and deciphering the info. Clustering may also reveal non-obvious constructions resembling potential widespread causes for various occasions, or the propagation of a root occasion throughout the globe, or the change in tone towards a standard occasion over time. Nonetheless, we have no idea what makes two occasions related – is it the placement, the 2 actors, the tone, the time or some mixture of those? Clustering algorithms can study from information and decide 1) what makes totally different datapoints related, 2) which datapoints are associated to which different datapoints and three) what are the widespread traits of those associated datapoints.
Conditions
To get began, we’d like an Amazon Redshift cluster with model 1.0.33433 or increased and an AWS Identification and Entry Administration (IAM) function connected that gives entry to Amazon SageMaker and permissions to an S3 bucket.
For an introduction to Redshift ML and directions on setting it up, see Create, prepare, and deploy machine studying fashions in Amazon Redshift utilizing SQL with Amazon Redshift ML.
To create a easy cluster, full the next steps:
- On the Amazon Redshift console, select Clusters within the navigation pane.
- Select Create cluster.
- Present the configuration parameters resembling cluster identify, consumer identify, and password.
- For Related IAM roles, on the menu Handle IAM roles, select Create IAM function.
You probably have an present function with the required parameters, you’ll be able to select Affiliate IAM roles.
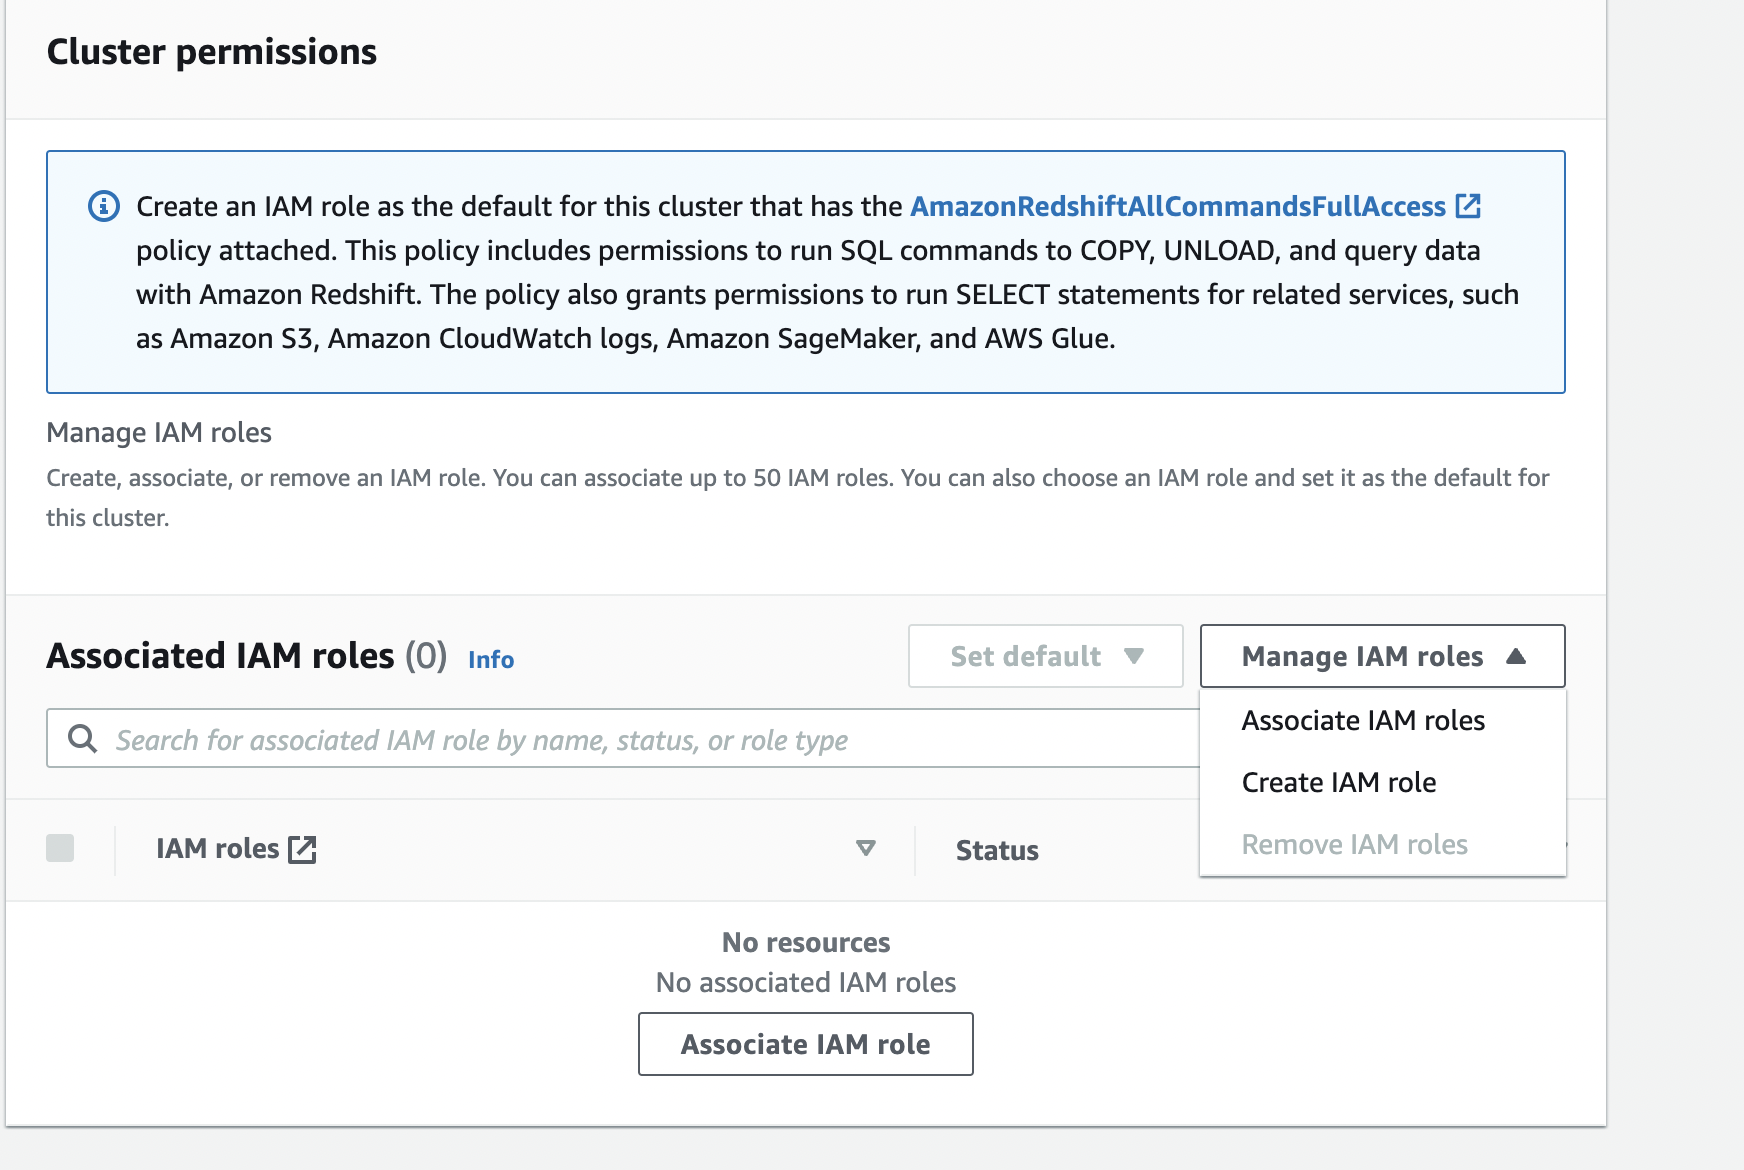
- Choose Particular S3 buckets and select a bucket for storing the artifacts generated by Redshift ML.
- Select Create IAM function as default.

A default IAM function is created for you and mechanically related to the cluster.
- Select Create cluster.

Put together the info
Load the GDELT information into Amazon Redshift utilizing the next SQL. You should use the Amazon Redshift Question Editor v2 or your favourite SQL software to run these instructions.
To create the desk, use the next instructions:
To load information into the desk, use the next command:
Create a mannequin in Redshift ML
When utilizing the Ok-means algorithm, you need to specify an enter Ok that specifies the variety of clusters to search out within the information. The output of this algorithm is a set of Ok centroids, one for every cluster. Every information level belongs to one of many Ok clusters that’s closest to it. Every cluster is described by its centroid, which may be regarded as a multi-dimensional illustration of the cluster. The Ok-means algorithm compares the distances between centroids and information factors to learn the way totally different the clusters are from one another. A bigger distance usually signifies a better distinction between the clusters.
Earlier than we create the mannequin, let’s study the coaching information by working the next SQL code in Amazon Redshift Question Editor v2:
The next screenshot reveals our outcomes.
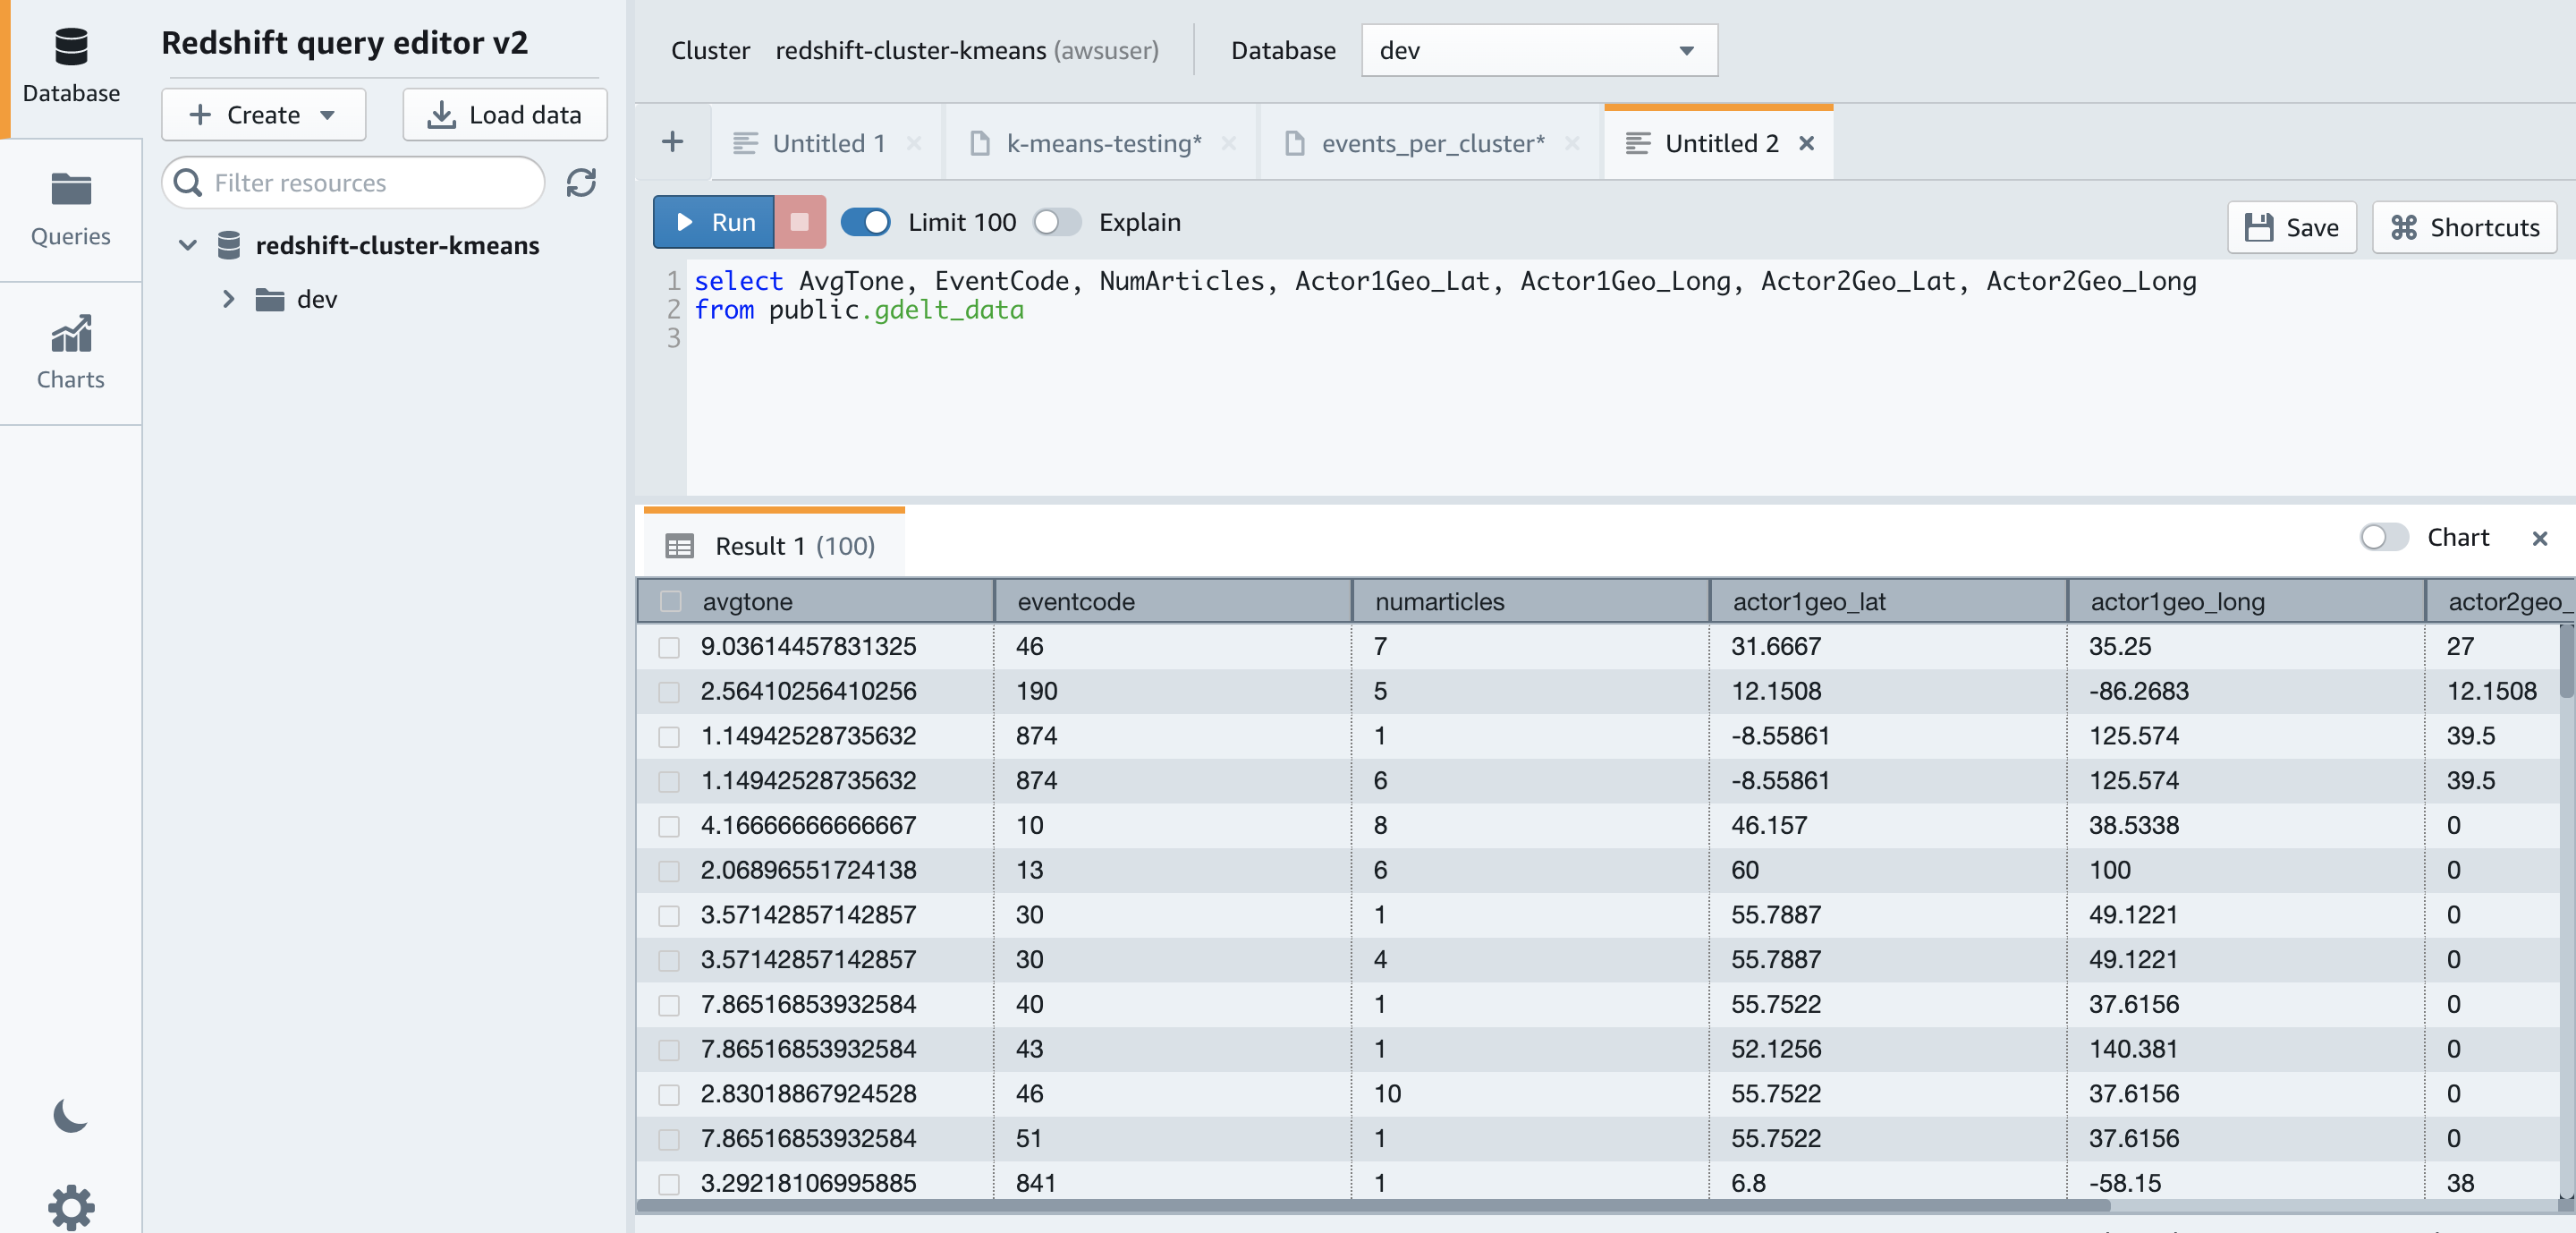
We create a mannequin with seven clusters from this information (see the next code). You’ll be able to experiment by altering the Ok worth and creating totally different fashions. The SageMaker Ok-means algorithm can get hold of a great clustering with solely a single cross over the info with very quick runtimes.
For extra details about mannequin coaching, see Machine studying overview. For an inventory of different hyper-parameters Ok-means helps, see Ok-means Hyperparameters, for the complete syntax of CREATE MODEL see our documentation.
You should use the SHOW MODEL command to view the standing of the mannequin:
The outcomes present that our mannequin is within the READY state.
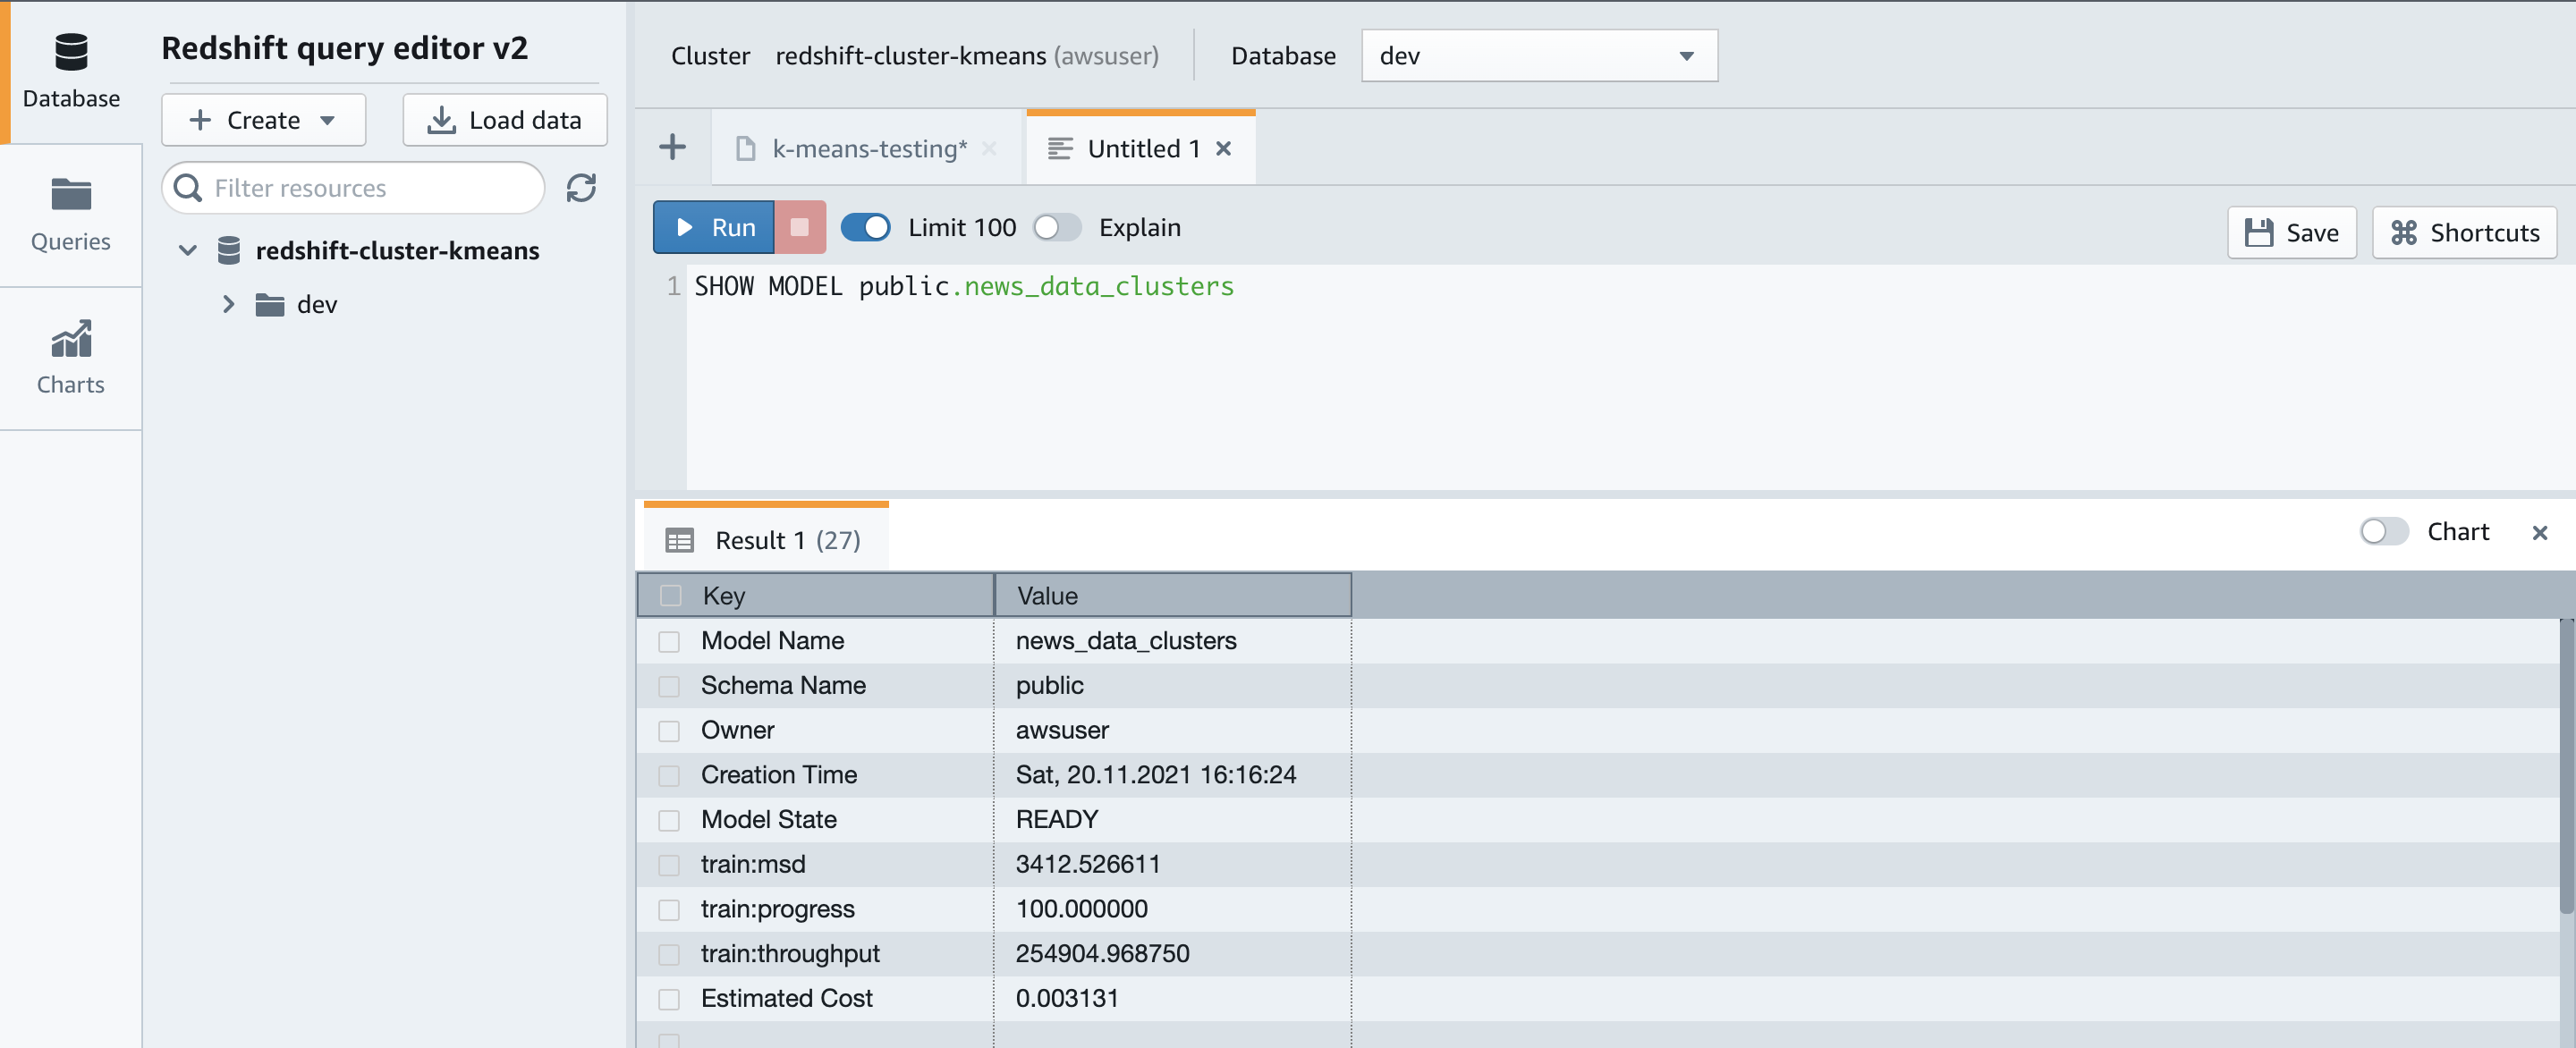
We will now run the question to establish the clusters. The next question reveals the cluster related to every GlobelEventId:
We get the next outcomes.
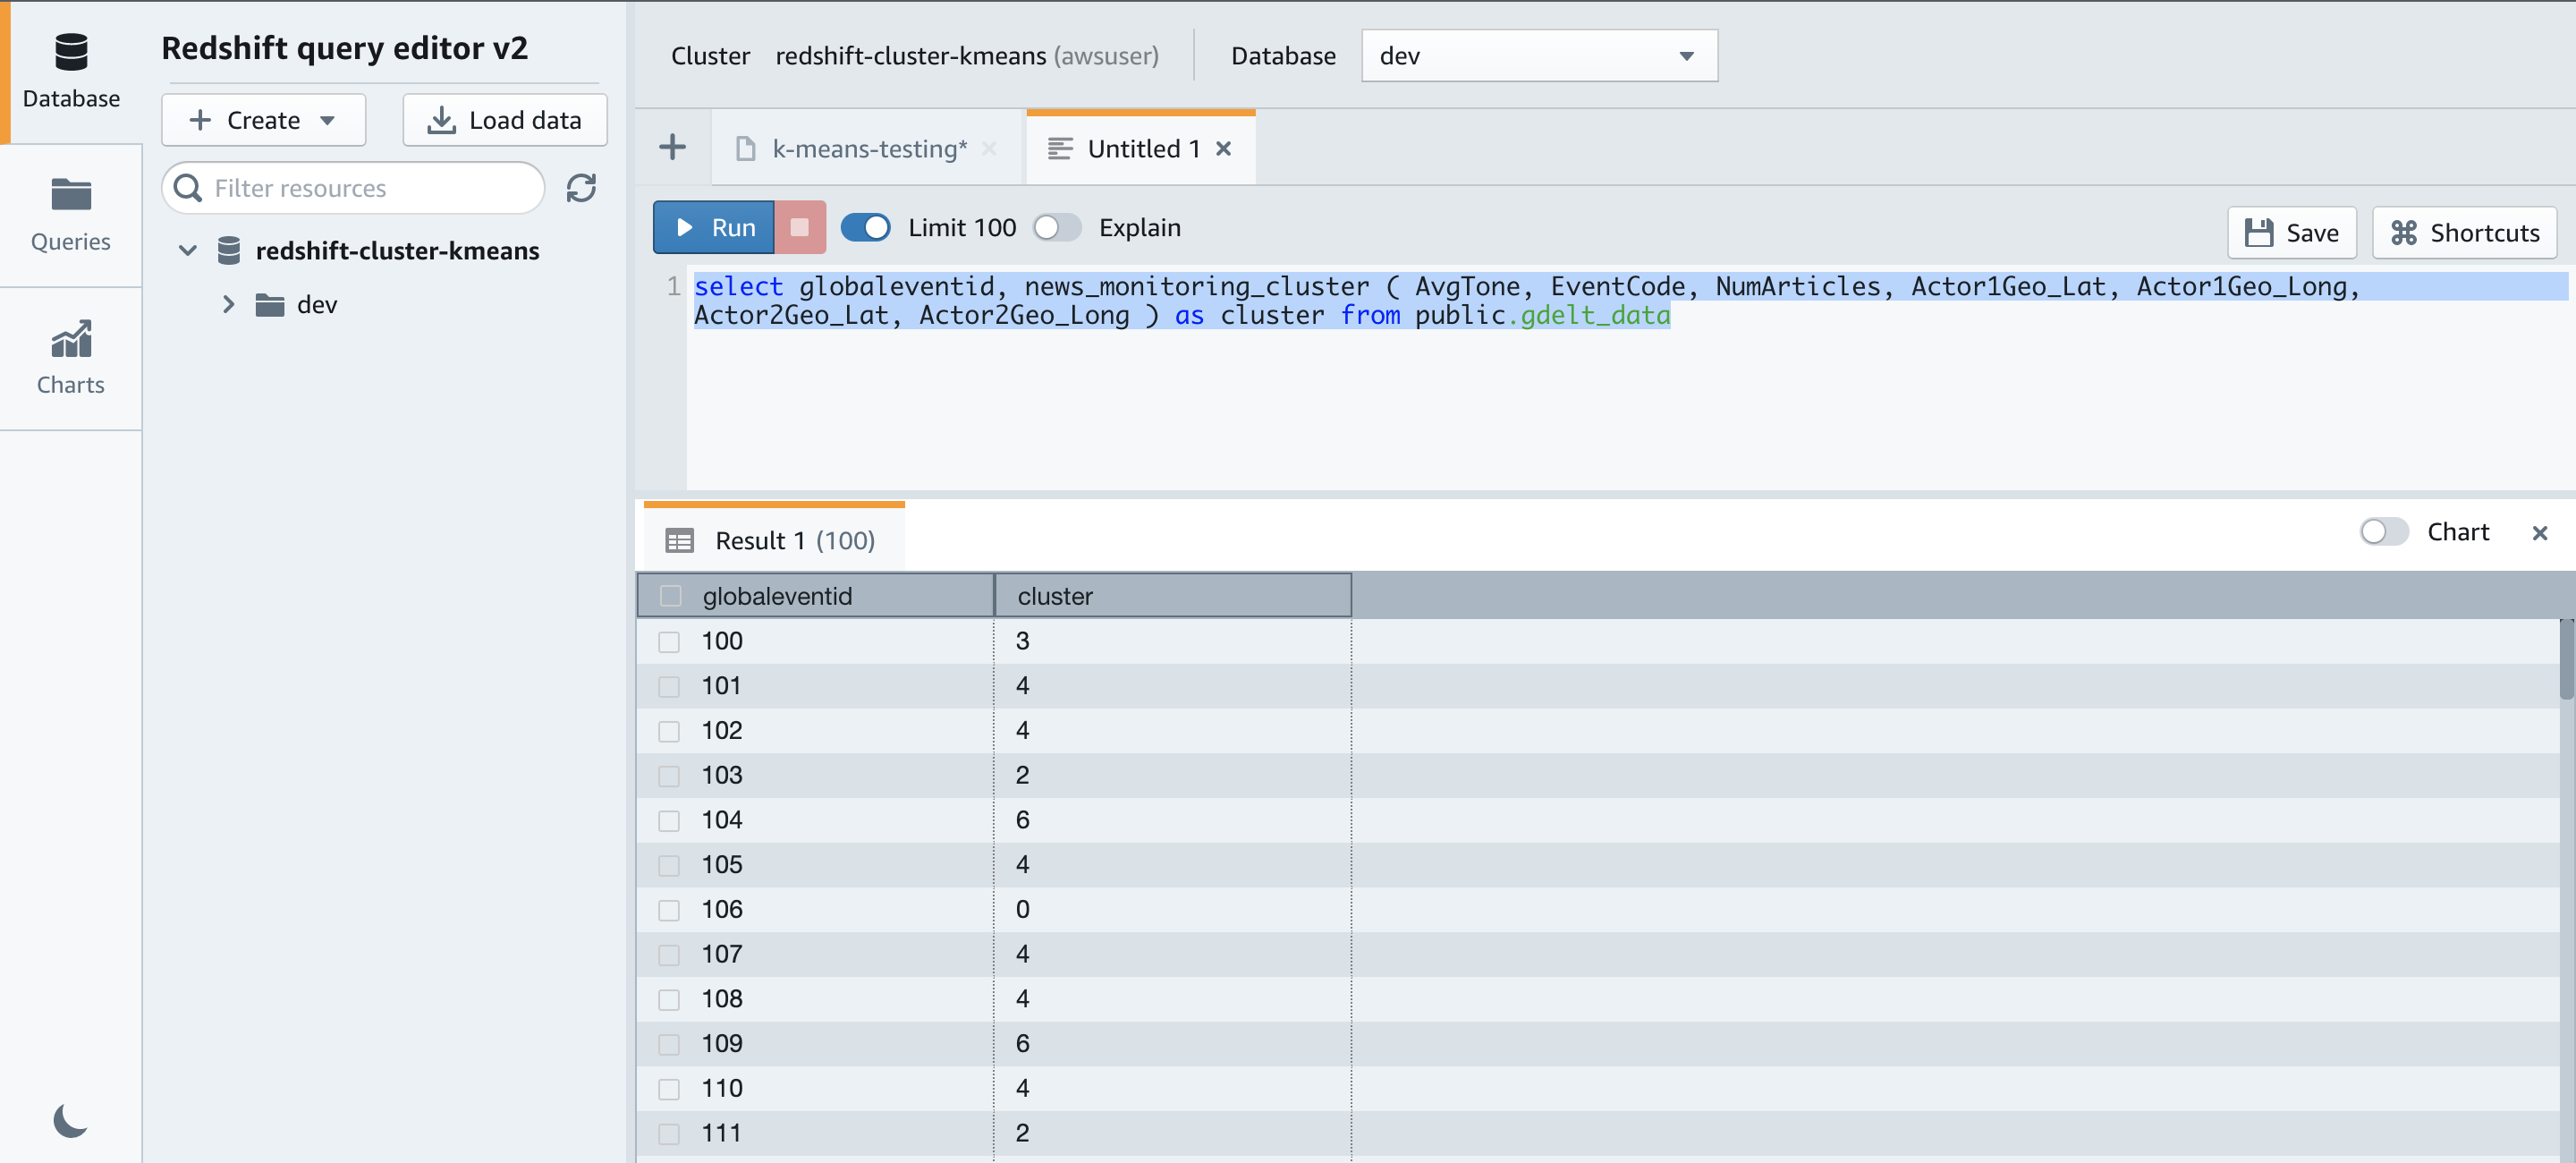
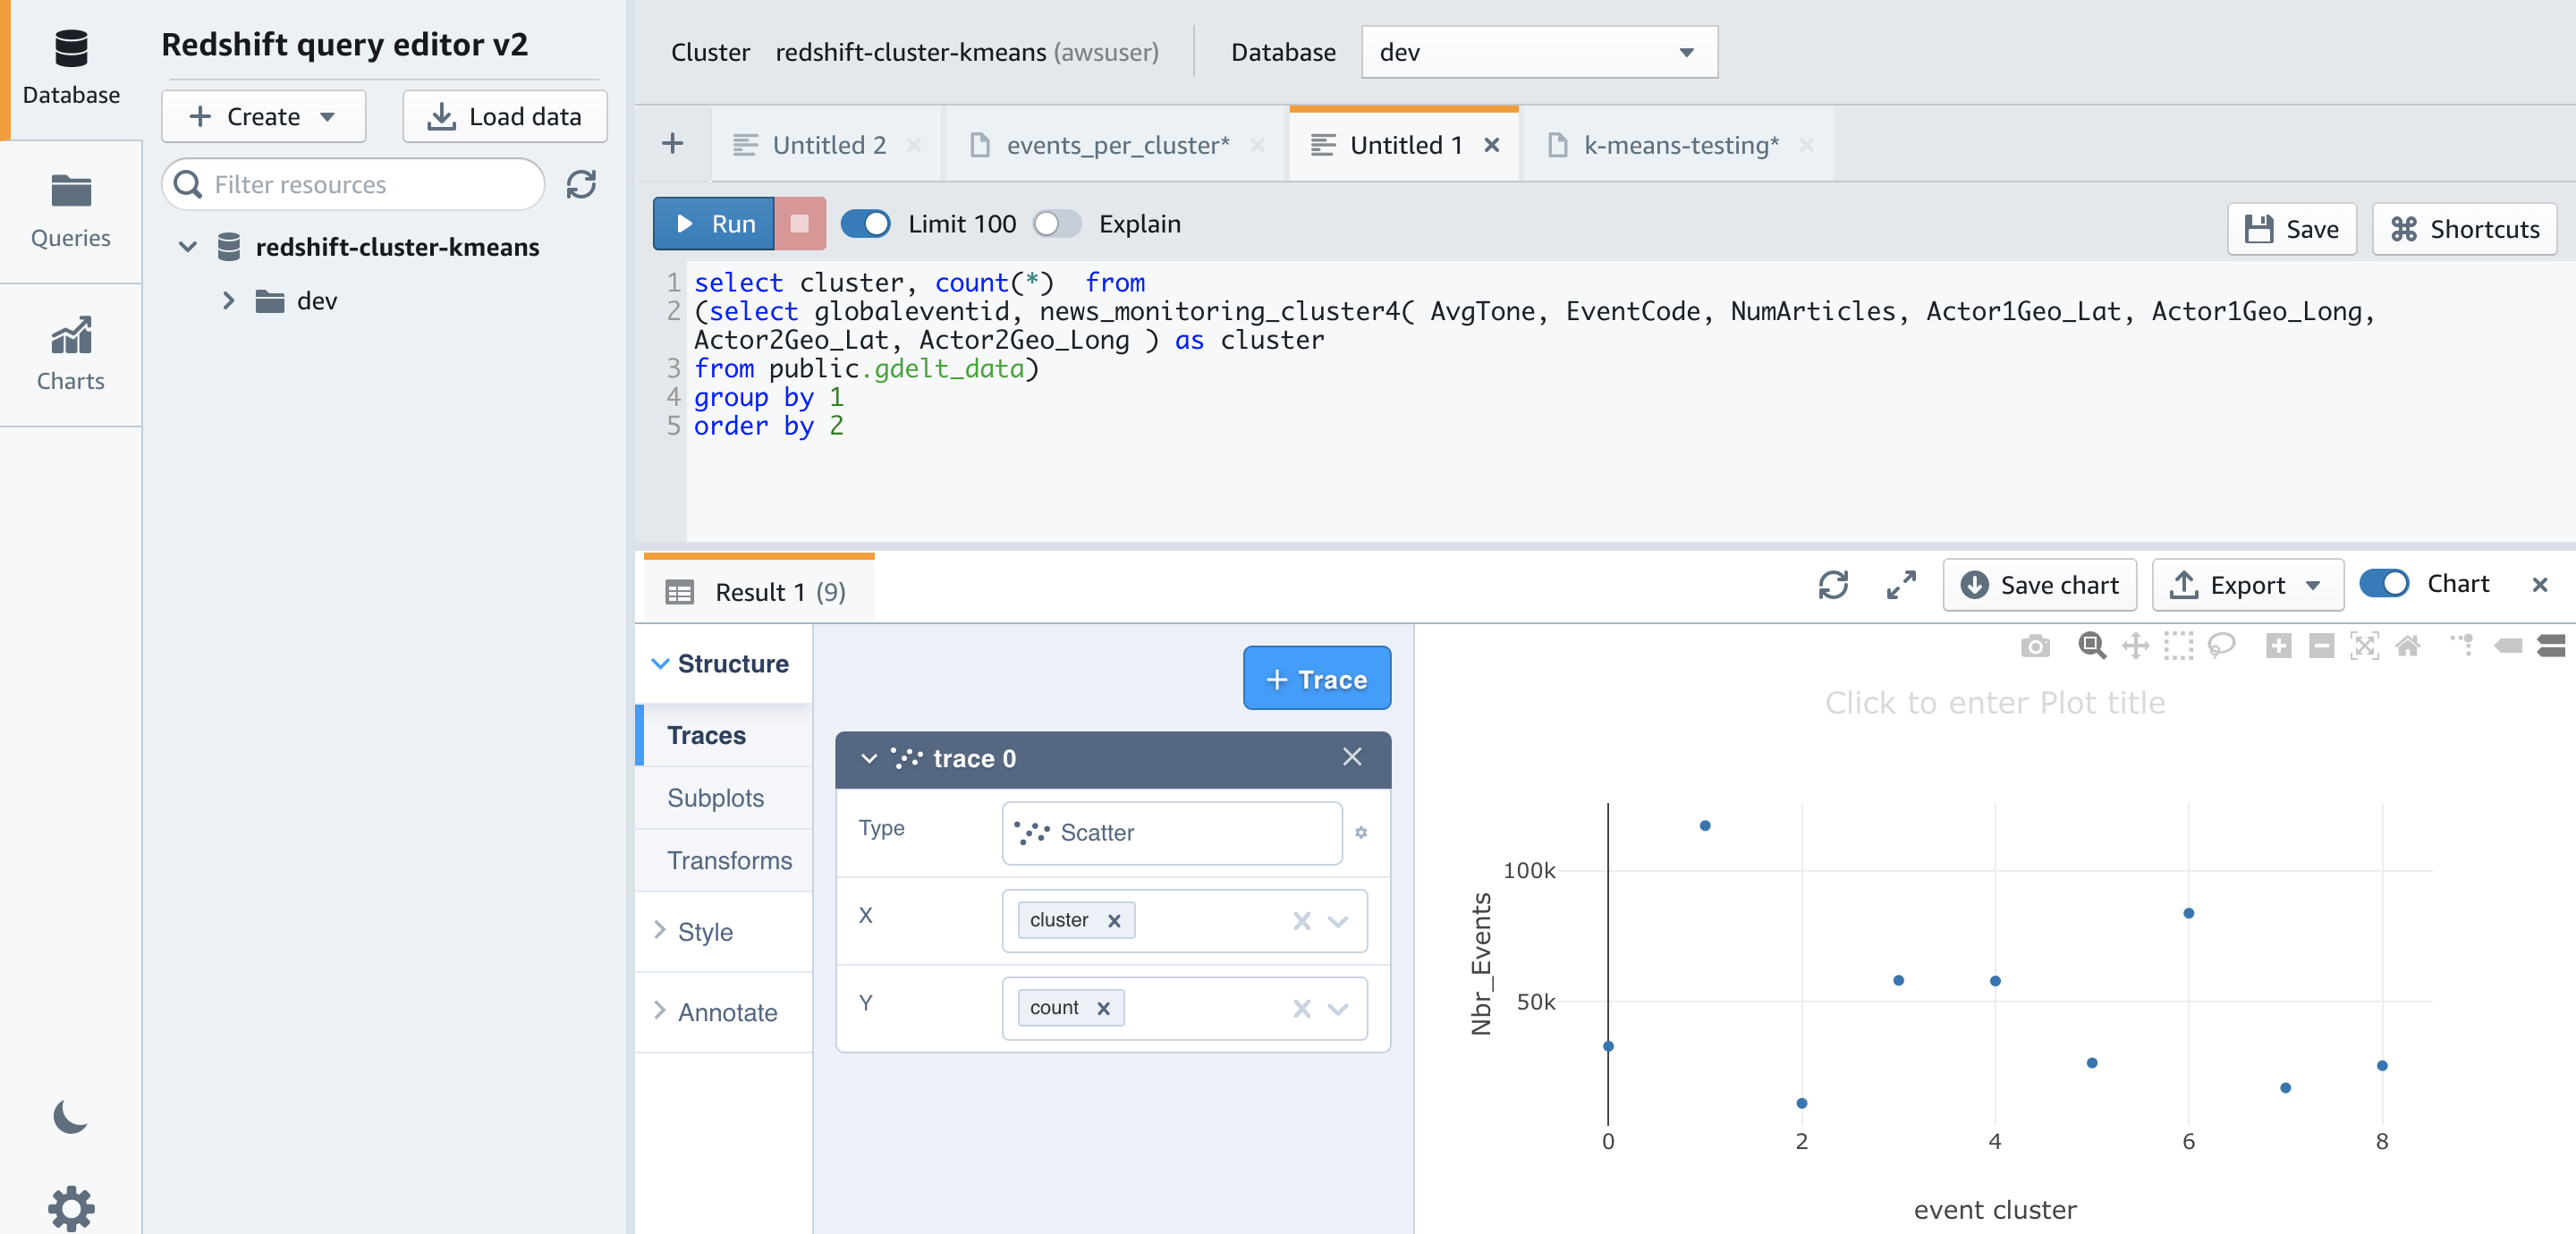
Now let’s run a question to verify the distribution of knowledge throughout our clusters to see if seven is the suitable cluster measurement for this dataset:
The outcomes present that only a few occasions are assigned to clusters 1 and three.
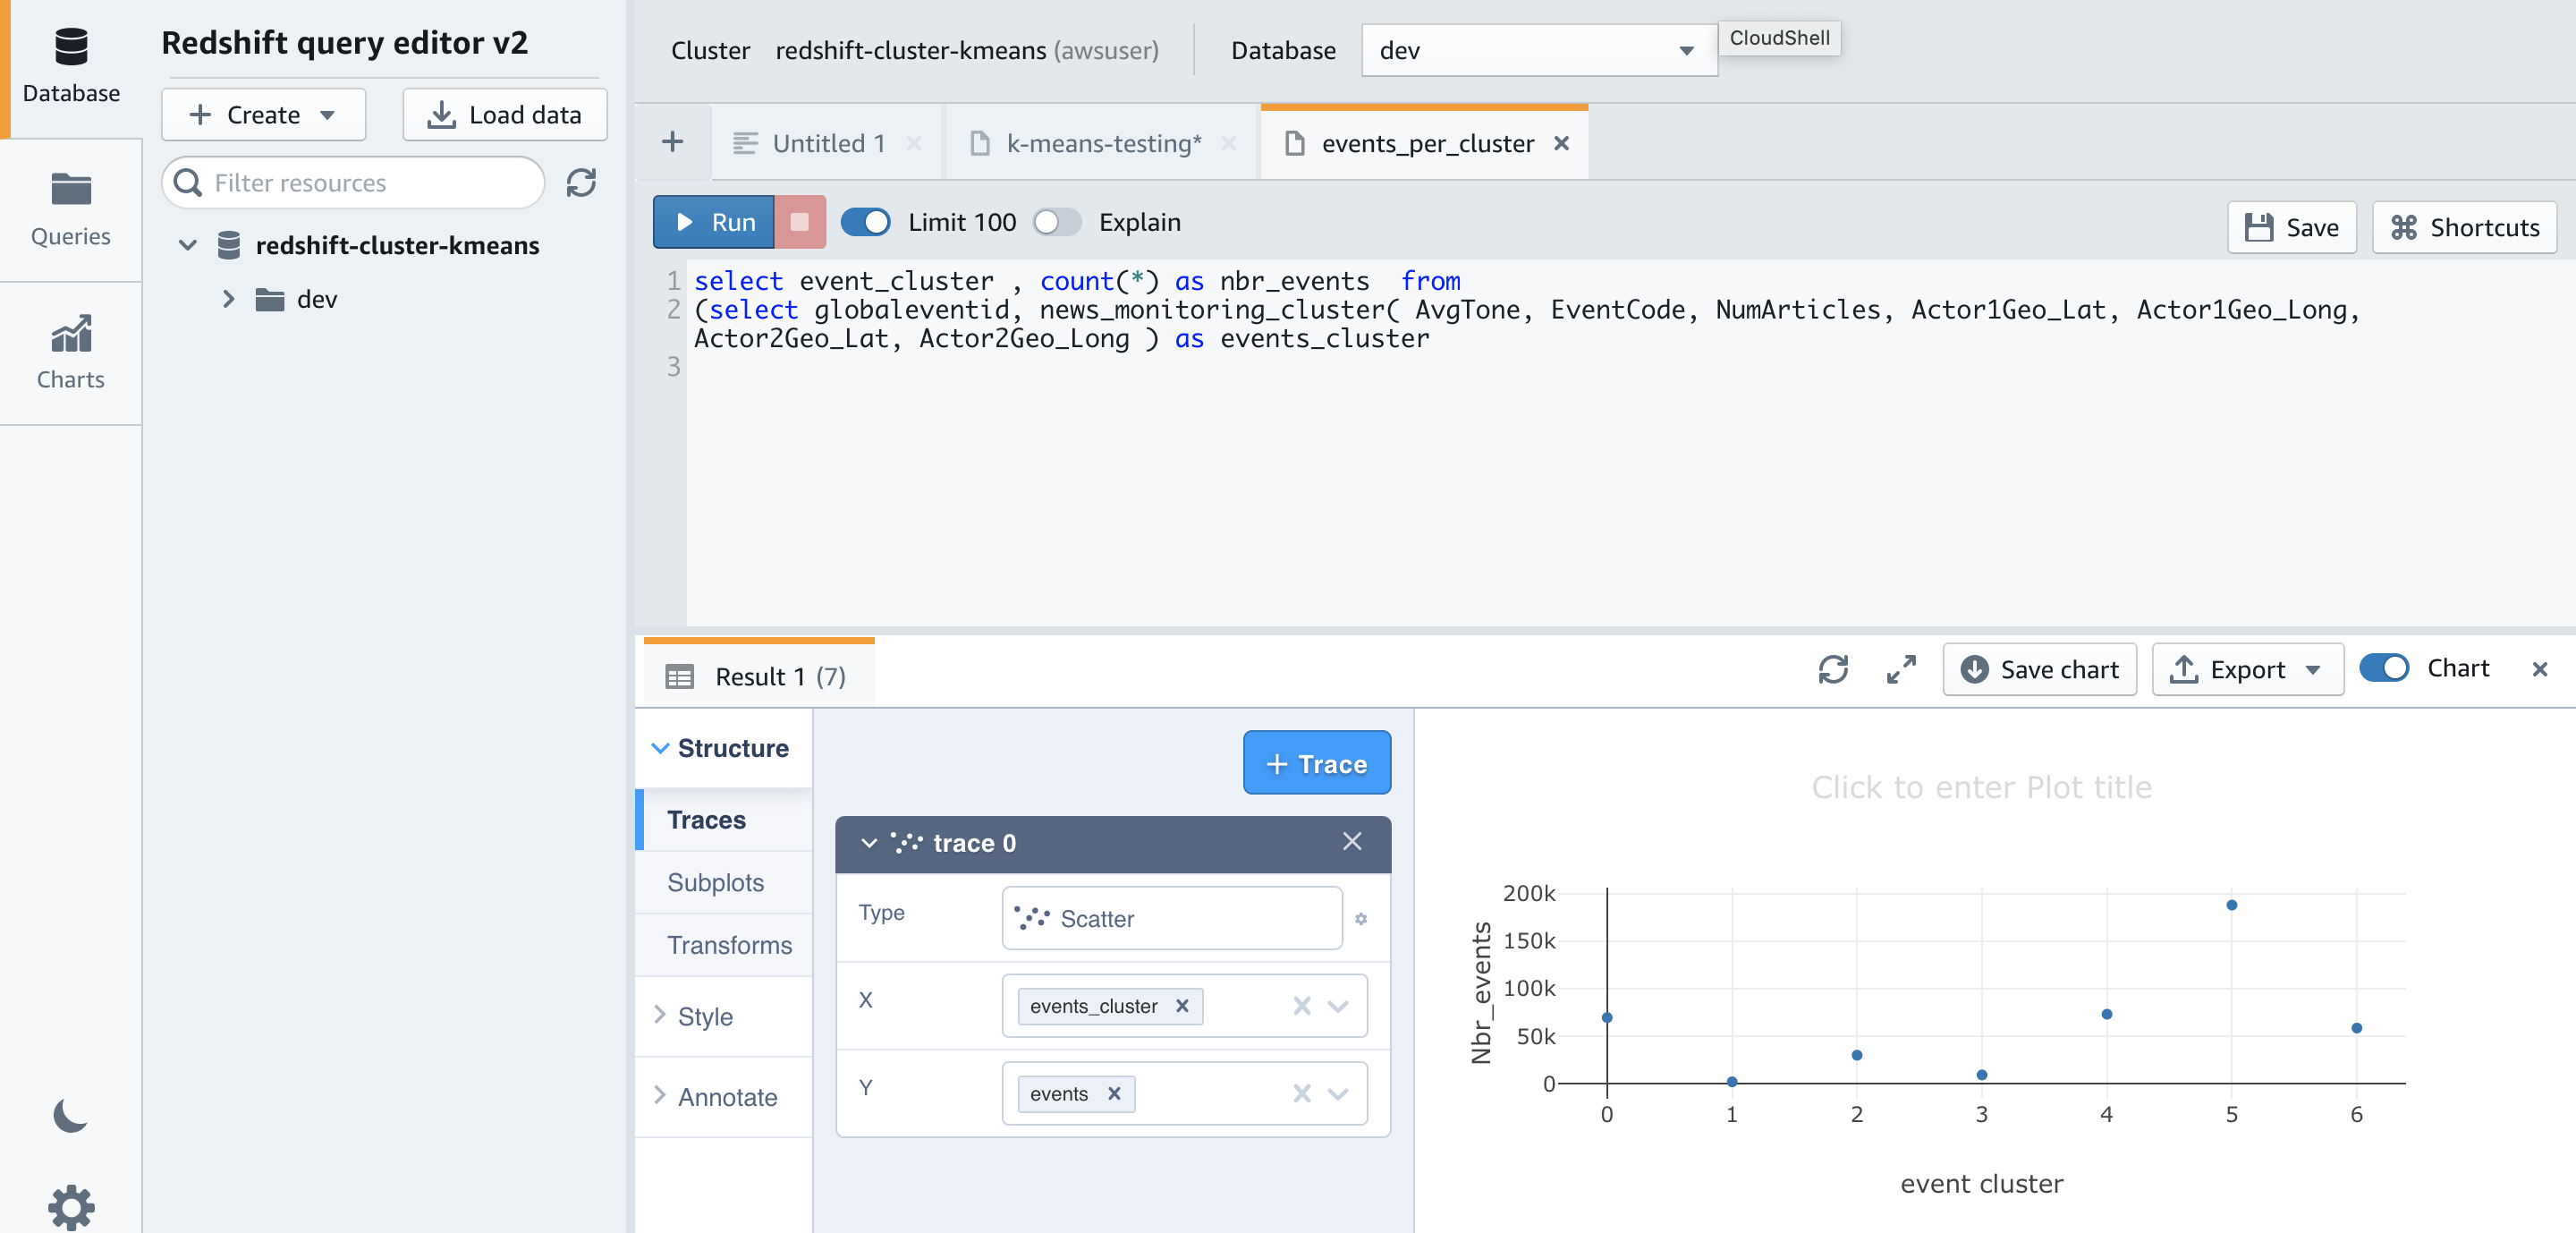
Let’s attempt working the above question once more after re-creating the mannequin with 9 clusters by altering the Ok worth to 9.
Utilizing 9 clusters helps easy out the cluster sizes. The smallest is now roughly 11,000 and the biggest is roughly 117,000, in comparison with 188,000 when utilizing seven clusters.
Now, let’s run the next question to find out the facilities of the clusters primarily based on variety of articles by occasion code:
Let’s run the next question to get extra insights into the datapoints assigned to one of many clusters:
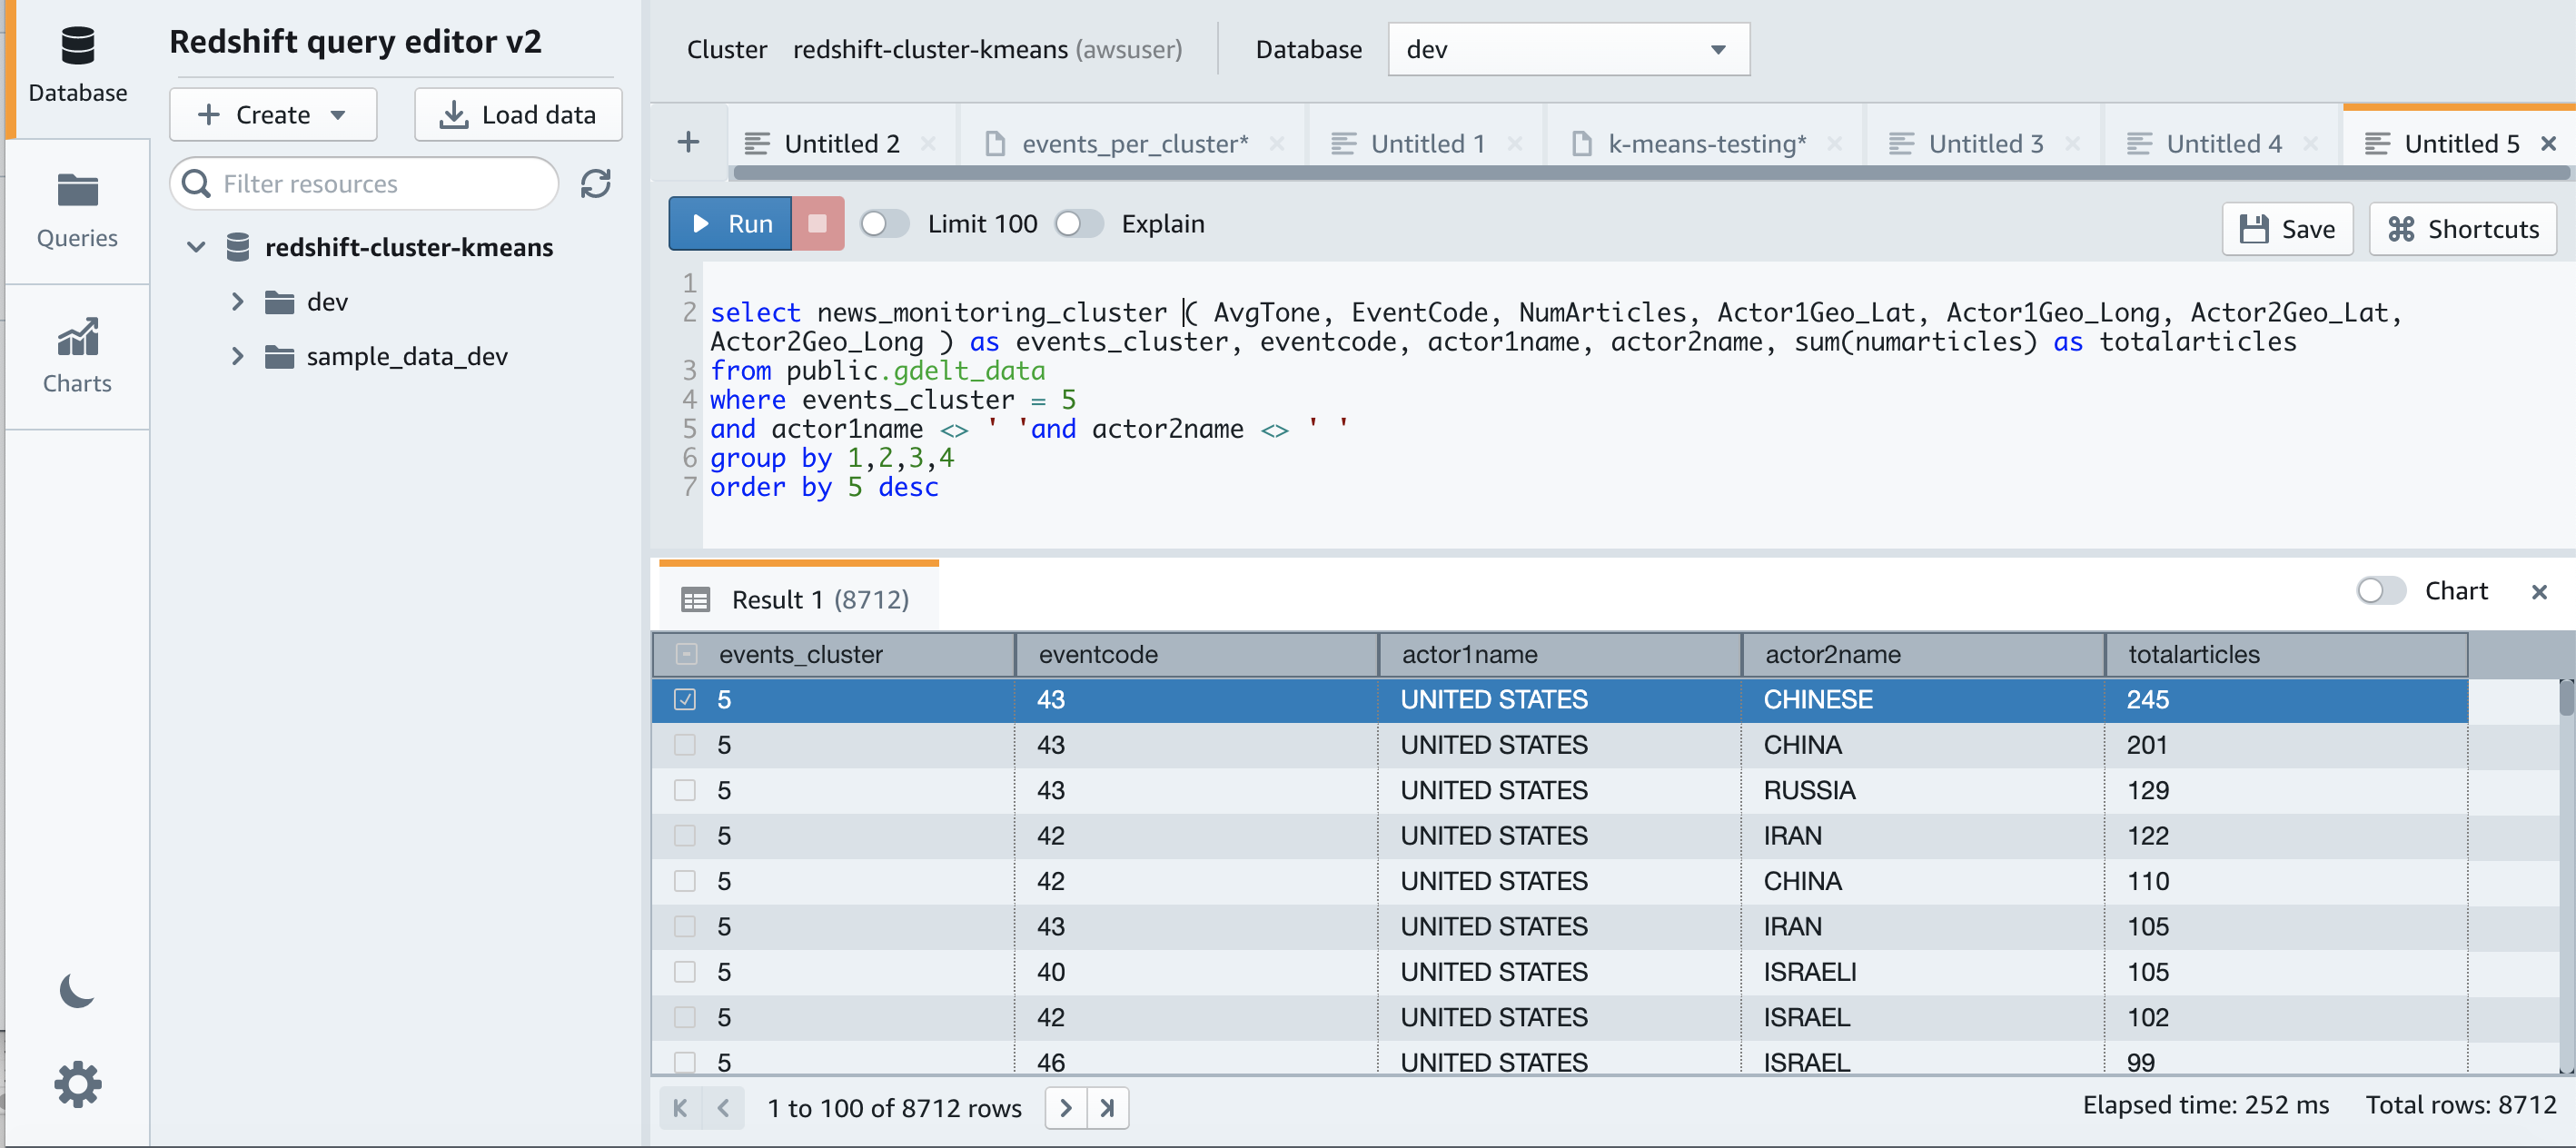
Observing the datapoints assigned to the clusters, we see clusters of occasions similar to interactions between US and China – most likely as a result of institution of diplomatic relations, between US and RUS – most likely similar to the SALT II Treaty and people involving Iran– most likely similar to the Iranian Revolution. Thus, clustering may help us make sense of the info, and present us the way in which as we proceed to discover and use it.
Conclusion
Redshift ML makes it straightforward for customers of all talent ranges to make use of ML know-how. With no prior ML data, you should use Redshift ML to realize enterprise insights in your information. You’ll be able to reap the benefits of ML approaches resembling supervised and unsupervised studying to categorise your labeled and unlabeled information, respectively. On this put up, we walked you thru the best way to carry out unsupervised studying with Redshift ML by creating an ML mannequin that makes use of the Ok-means algorithm to find grouping in your information.
For extra details about constructing totally different fashions, see Amazon Redshift ML.
Concerning the Authors
 Phil Bates is a Senior Analytics Specialist Options Architect at AWS with over 25 years of knowledge warehouse expertise.
 Debu Panda, a Principal Product Supervisor at AWS, is an business chief in analytics, software platform, and database applied sciences, and has greater than 25 years of expertise within the IT world. Debu has revealed quite a few articles on analytics, enterprise Java, and databases and has offered at a number of conferences resembling re:Invent, Oracle Open World, and Java One. He’s lead creator of the EJB 3 in Motion (Manning Publications 2007, 2014) and Middleware Administration (Packt).
 Akash Gheewala is a Options Architect at AWS. He helps world enterprises throughout the excessive tech business of their journey to the cloud. He does this by means of his ardour for accelerating digital transformation for purchasers and constructing extremely scalable and cost-effective options within the cloud. Akash additionally enjoys psychological fashions, creating content material and vagabonding concerning the world.
 Murali Narayanaswamy is a principal machine studying scientist in AWS. He obtained his PhD from Carnegie Mellon College and works on the intersection of ML, AI, optimization, studying and inference to fight uncertainty in real-world purposes together with personalization, forecasting, provide chains and enormous scale programs.
[ad_2]

