


[ad_1]
MongoDB.stay came about final week, and Rockset had the chance to take part alongside members of the MongoDB neighborhood and share about our work to make MongoDB knowledge accessible by way of real-time exterior indexing. In our session, we mentioned the necessity for contemporary data-driven purposes to carry out real-time aggregations and joins, and the way Rockset makes use of MongoDB change streams and Converged Indexing to ship quick queries on knowledge from MongoDB.
Information-Pushed Purposes Want Actual-Time Aggregations and Joins
Builders of data-driven purposes face many challenges. Purposes of in the present day usually function on knowledge from a number of sources—databases like MongoDB, streaming platforms, and knowledge lakes. And the information volumes these purposes want to research usually scale into a number of terabytes. Above all, purposes want quick queries on stay knowledge to personalize consumer experiences, present real-time buyer 360s, or detect anomalous conditions, because the case could also be.

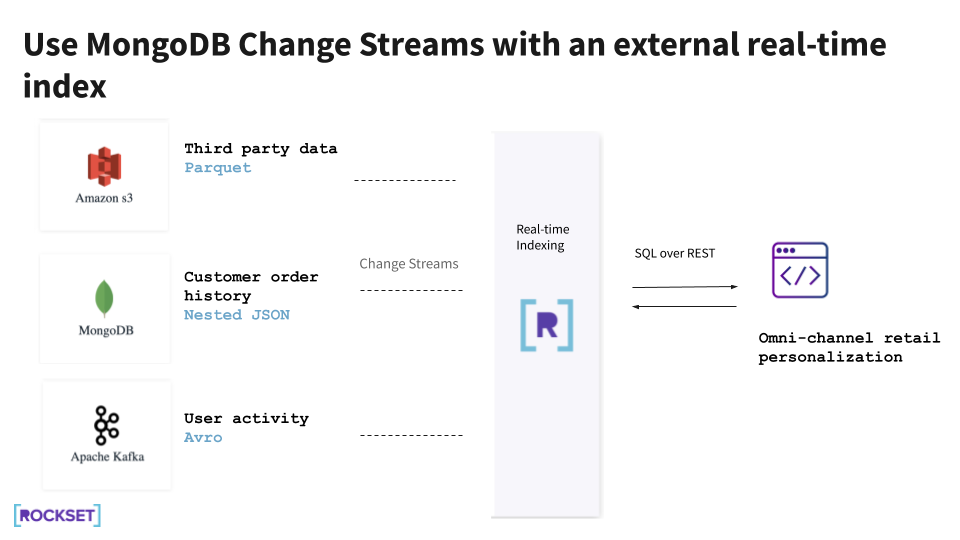
An omni-channel retail personalization utility, for instance, could require order knowledge from MongoDB, consumer exercise streams from Kafka, and third-party knowledge from a knowledge lake. The applying should decide what product suggestion or supply to ship to clients in actual time, whereas they’re on the web site.
Actual-Time Structure At present
One among two choices is often used to assist these real-time data-driven purposes in the present day.
- We are able to repeatedly ETL all new knowledge from a number of knowledge sources, equivalent to MongoDB, Kafka, and Amazon S3, into one other system, like PostgreSQL, that may assist aggregations and joins. Nonetheless, it takes effort and time to construct and preserve the ETL pipelines. Not solely would now we have to replace our pipelines usually to deal with new knowledge units or modified schemas, the pipelines would add latency such that the information can be stale by the point it could possibly be queried within the second system.
- We are able to load new knowledge from different knowledge sources—Kafka and Amazon S3—into our manufacturing MongoDB occasion and run our queries there. We might be liable for constructing and sustaining pipelines from these sources to MongoDB. This resolution works properly at smaller scale, however scaling knowledge, queries, and efficiency can show troublesome. This may require managing a number of indexes in MongoDB and writing application-side logic to assist complicated queries like joins.
A Actual-Time Exterior Indexing Method
We are able to take a unique strategy to assembly the necessities of data-driven purposes.

Utilizing Rockset for real-time indexing permits us to create APIs merely utilizing SQL for search, aggregations, and joins. This implies no additional application-side logic is required to assist complicated queries. As a substitute of making and managing our personal indexes, Rockset routinely builds indexes on ingested knowledge. And Rockset ingests knowledge with out requiring a pre-defined schema, so we will skip ETL pipelines and question the most recent knowledge.
Rockset gives built-in connectors to MongoDB and different frequent knowledge sources, so we don’t should construct our personal. For MongoDB Atlas, the Rockset connector makes use of MongoDB change streams to repeatedly sync from MongoDB with out affecting manufacturing MongoDB.

On this structure, there isn’t a want to change MongoDB to assist data-driven purposes, as all of the heavy reads from the purposes are offloaded to Rockset. Utilizing full-featured SQL, we will construct several types of microservices on high of Rockset, such that they’re remoted from the manufacturing MongoDB workload.
How Rockset Does Actual-Time Indexing
Rockset was designed to be a quick indexing layer, synced to a major database. A number of points of Rockset make it well-suited for this position.
Converged Indexing
Converged Indexing is a Rockset-specific characteristic through which all fields are listed routinely. There is no such thing as a have to create and preserve indexes or fear about which fields to index. Rockset indexes each single area, together with nested fields.
Rockset shops each area of each doc in an inverted index (like Elasticsearch does), a column-based index (like many knowledge warehouses do), and in a row-based index (like MongoDB or PostgreSQL). Every index is optimized for several types of queries.

Rockset is ready to index the whole lot effectively by shredding paperwork into key-value pairs, storing them in RocksDB, a key-value retailer. Not like different indexing options, like Elasticsearch, every area is mutable, that means new fields might be added or particular person fields up to date with out having to reindex your complete doc.
The inverted index helps for level lookups, whereas the column-based index makes it simple to scan by column values for aggregations. The question optimizer is ready to choose essentially the most acceptable indexes to make use of when scheduling the question execution.

Schemaless Ingest
One other key requirement for real-time indexing is the power to ingest knowledge with no pre-defined schema. This makes it attainable to keep away from ETL processing steps when indexing knowledge from MongoDB, which equally has a versatile schema.
Nonetheless, schemaless ingest alone isn’t notably helpful if we’re not in a position to question the information being ingested. To unravel this, Rockset routinely creates a schema on the ingested knowledge in order that it may be queried utilizing SQL, an idea termed Sensible Schema. On this method, Rockset permits SQL queries to be run on NoSQL knowledge, from MongoDB, knowledge lakes, or knowledge streams.

Disaggregated Aggregator-Leaf-Tailer Structure
For real-time indexing, it’s important to ship real-time efficiency for ingest and question. To take action, Rockset makes use of a disaggregated Aggregator-Leaf-Tailer structure that takes benefit of cloud elasticity.

Tailers ingest knowledge repeatedly, leaves index and retailer the listed knowledge, and aggregators serve queries on the information. Every part of this structure is decoupled from the others. Virtually, which means compute and storage might be scaled independently, relying on whether or not the appliance workload is compute- or storage-biased.
Additional, inside the compute portion, ingest compute might be individually scaled from question compute. On a bulk load, we will spin up extra tailers to attenuate the time required to ingest. Equally, throughout spikes in utility exercise, we will spin up extra aggregators to deal with the next price of queries. Rockset is then in a position to make full use of cloud efficiencies to attenuate latencies within the system.
Utilizing MongoDB and Rockset Collectively
MongoDB and Rockset just lately partnered to ship a absolutely managed connector between MongoDB Atlas and Rockset. Utilizing the 2 companies collectively brings a number of advantages to customers:
- Use any knowledge in actual time with schemaless ingest – Index repeatedly from MongoDB, different databases, knowledge streams, and knowledge lakes with build-in connectors.
- Create APIs in minutes utilizing SQL – Create APIs utilizing SQL for complicated queries, like search, aggregations, and joins.
- Scale higher by offloading heavy reads to a pace layer – Scale to hundreds of thousands of quick API calls with out impacting manufacturing MongoDB efficiency.

Placing MongoDB and Rockset collectively takes a couple of easy steps. We recorded a step-by-step walkthrough right here to indicate the way it’s carried out. It’s also possible to try our full MongoDB.stay session right here.
Able to get began? Create your Rockset account now!
Different MongoDB assets:
[ad_2]

