


[ad_1]
Database efficiency is a vital facet of guaranteeing an internet utility or service stays quick and steady. Because the service scales up, there are sometimes challenges with scaling the first database together with it. Whereas MongoDB is usually used as a major on-line database and might meet the calls for of very massive scale internet functions, it does typically grow to be the bottleneck as properly.
I had the chance to function MongoDB at scale as a major database at Foursquare, and encountered many of those bottlenecks. It will probably typically be the case when utilizing MongoDB as a major on-line database for a closely trafficked internet utility that entry patterns reminiscent of joins, aggregations, and analytical queries that scan massive or whole parts of a set can’t be run as a result of hostile impacts they’ve on efficiency. Nonetheless, these entry patterns are nonetheless required to construct many utility options.
We devised many methods to take care of these conditions at Foursquare. The principle technique to alleviate a number of the stress on the first database is to dump a number of the work to a secondary information retailer, and I’ll share a number of the frequent patterns of this technique on this weblog collection. On this weblog we are going to simply proceed to solely use MongoDB, however break up up the work from a single cluster to a number of clusters. In future articles I’ll talk about offloading to different forms of programs.
Use A number of MongoDB Clusters
One solution to get extra predictable efficiency and isolate the impacts of querying one assortment from one other is to separate them into separate MongoDB clusters. If you’re already utilizing service oriented structure, it could make sense to additionally create separate MongoDB clusters for every main service or group of providers. This fashion you may decrease the influence of an incident to a MongoDB cluster to simply the providers that must entry it. If your whole microservices share the identical MongoDB backend, then they aren’t actually unbiased of one another.
Clearly if there may be new improvement you may select to begin any new collections on a model new cluster. Nonetheless you can even resolve to maneuver work at the moment accomplished by present clusters to new clusters by both simply migrating a set wholesale to a different cluster, or creating new denormalized collections in a brand new cluster.
Migrating a Assortment
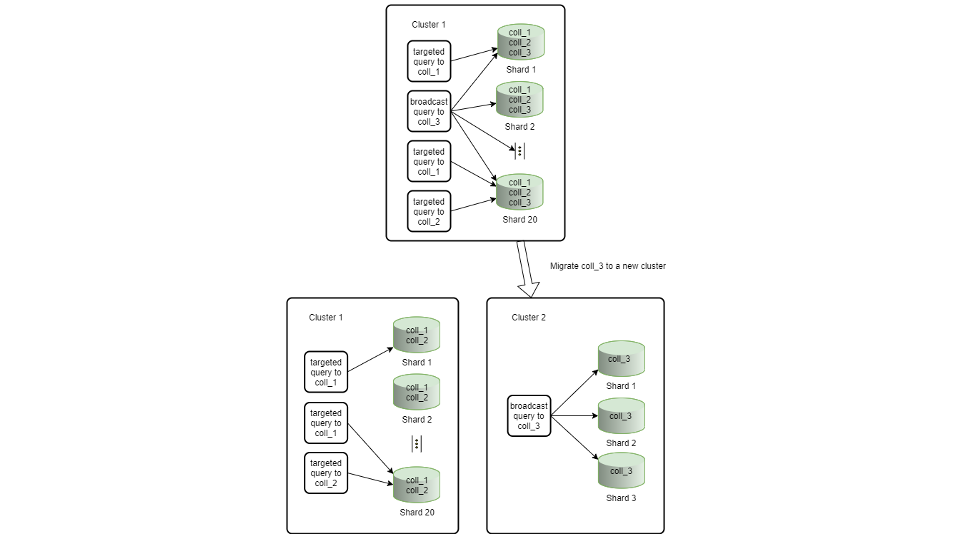
The extra comparable the question patterns are for a specific cluster, the better it’s to optimize and predict its efficiency. If in case you have collections with very totally different workload traits, it could make sense to separate them into totally different clusters as a way to higher optimize cluster efficiency for every kind of workload.
For instance, you may have a extensively sharded cluster the place a lot of the queries specify the shard key so they’re focused to a single shard. Nonetheless, there may be one assortment the place a lot of the queries don’t specify the shard key, and thus lead to being broadcast to all shards. Since this cluster is extensively sharded, the work amplification of those broadcast queries turns into bigger with each extra shard. It could make sense to maneuver this assortment to its personal cluster with many fewer shards as a way to isolate the load of the published queries from the opposite collections on the unique cluster. It’s also very probably that the efficiency of the published question will even enhance by doing this as properly. Lastly, by separating the disparate question patterns, it’s simpler to motive concerning the efficiency of the cluster since it’s typically not clear when a number of sluggish question patterns which one causes the efficiency degradation on the cluster and which of them are sluggish as a result of they’re affected by efficiency degradations on the cluster.

Denormalization
Denormalization can be utilized inside a single cluster to scale back the variety of reads your utility must make to the database by embedding further data right into a doc that’s steadily requested with it, thus avoiding the necessity for joins. It may also be used to separate work into a very separate cluster by making a model new assortment with aggregated information that steadily must be computed.
For instance, if we’ve an utility the place customers could make posts about sure matters, we would have three collections:
customers:

{
    _id: ObjectId('AAAA'),
    identify: 'Alice'
},
{
    _id: ObjectId('BBBB'),
    identify: 'Bob'
}

matters:

{
    _id: ObjectId('CCCC'),
    identify: 'cats'
},
{
    _id: ObjectId('DDDD'),
    identify: 'canine'
}

posts:

{
    _id: ObjectId('PPPP'),
    identify: 'My first put up - cats',
    consumer: ObjectId('AAAA'),
    matter: ObjectId('CCCC')
},
{
    _id: ObjectId('QQQQ'),
    identify: 'My second put up - canine',
    consumer: ObjectId('AAAA'),
    matter: ObjectId('DDDD')
},
{
    _id: ObjectId('RRRR'),
    identify: 'My first put up about canine',
    consumer: ObjectId('BBBB'),
    matter: ObjectId('DDDD')
},
{
    _id: ObjectId('SSSS'),
    identify: 'My second put up about canine',
    consumer: ObjectId('BBBB'),
    matter: ObjectId('DDDD')
}
Your utility might wish to know what number of posts a consumer has ever made a few sure matter. If these are the one collections accessible, you would need to run a rely on the posts assortment filtering by consumer and matter. This might require you to have an index like {'matter': 1, 'consumer': 1} as a way to carry out properly. Even with the existence of this index, MongoDB would nonetheless must do an index scan of all of the posts made by a consumer for a subject. So as to mitigate this, we will create a brand new assortment user_topic_aggregation:
user_topic_aggregation:

{
    _id: ObjectId('TTTT'),
    consumer: ObjectId('AAAA'),
    matter: ObjectId('CCCC')
    post_count: 1,
    last_post: ObjectId('PPPP')
},
{
    _id: ObjectId('UUUU'),
    consumer: ObjectId('AAAA'),
    matter: ObjectId('DDDD')
    post_count: 1,
    last_post: ObjectId('QQQQ')
},
{
    _id: ObjectId('VVVV'),
    consumer: ObjectId('BBBB'),
    matter: ObjectId('DDDD')
    post_count: 2,
    last_post: ObjectId('SSSS')
}
This assortment would have an index {'matter': 1, 'consumer': 1}. Then we might have the ability to get the variety of posts made by a consumer for a given matter with scanning only one key in an index. This new assortment can then additionally dwell in a very separate MongoDB cluster, which isolates this workload out of your authentic cluster.
What if we additionally needed to know the final time a consumer made a put up for a sure matter? This can be a question that MongoDB struggles to reply. You may make use of the brand new aggregation assortment and retailer the ObjectId of the final put up for a given consumer/matter edge, which then enables you to simply discover the reply by operating the ObjectId.getTimestamp() operate on the ObjectId of the final put up.
The tradeoff to doing that is that when making a brand new put up, it’s good to replace two collections as an alternative of 1, and it can’t be accomplished in a single atomic operation. This additionally means the denormalized information within the aggregation assortment can grow to be inconsistent with the info within the authentic two collections. There would then must be a mechanism to detect and proper these inconsistencies.
It solely is sensible to denormalize information like this if the ratio of reads to updates is excessive, and it’s acceptable to your utility to typically learn inconsistent information. If you may be studying the denormalized information steadily, however updating it a lot much less steadily, then it is sensible to incur the price of costlier and complicated updates.
Abstract
As your utilization of your major MongoDB cluster grows, fastidiously splitting the workload amongst a number of MongoDB clusters will help you overcome scaling bottlenecks. It will probably assist isolate your microservices from database failures, and likewise enhance efficiency of queries of disparate patterns. In subsequent blogs, I’ll discuss utilizing programs aside from MongoDB as secondary information shops to allow question patterns that aren’t doable to run in your major MongoDB cluster(s).

Different MongoDB sources:
[ad_2]

