


[ad_1]
Initially revealed on July 8, 2020
Yesterday I learn an analyst report that the serverless structure market shall be $21B by 2025. I additionally lately met with Alex DeBrie, writer of the DynamoDB e book and loved studying about his serverless philosophy. He wrote an excellent publish about the important thing components for selecting serverless databases right here, and we had an interesting dialog about serverless indexing techniques that complement them. Final week Bob Muglia, newly appointed govt chairman of FaunaDB, wrote an equally fascinating article about how client-serverless is basically the 4th technology of software mannequin.
From datacenter to cloud
Throughout my early days at VMware, we spent plenty of time enthusiastic about admin controls. Why? As a result of enterprise IT groups at all times requested us for higher methods to handle datacenter infrastructure and management spend. Alongside got here AWS, turning the mannequin on its head, unlocking developer agility by way of self-service. The current period of cloud agility noticed corporations migrate their present stacks to the cloud, however there’s solely a lot you are able to do once you migrate software program constructed for knowledge facilities into the cloud. Carry-and-shift cloud migration is a foul thought – you find yourself bringing alongside all the prevailing datacenter complexity and making an attempt to drive suit your software program stack to perform in a completely new surroundings.
From cloud to serverless
If you concentrate on it, what’s the level of manually sizing clusters, provisioning servers and managing cloud infrastructure when your software program is the perfect decide of precisely what assets it wants at any given level? Manually configuring software program within the cloud is plenty of ops overhead, entails a bunch of sizing assumptions, over-provisioned compute/storage and nonetheless causes operational fires when issues begin to scale.
For this reason the world is transferring from cloud-hosted structure to serverless structure – its the next-generation of cloud infrastructure providers that automates capability planning, deployment and scaling. The result’s that your software program is less complicated to construct, keep and way more cost-efficient. No surprise the JAM stack and GraphQL are all the trend in the present day. However what’s the preferrred knowledge stack for serverless architectures?
Serverless knowledge stack for low ops, excessive velocity groups
An information administration system is serverless, if one can load knowledge, persist knowledge, and run queries merely utilizing an information API –without ever having to consider servers. A number of the key points of a serverless knowledge administration system are:
- No database connections – Customers shouldn’t must handle database connections. It must be accessible by way of knowledge APIs.
- No provisioning – Customers should not have to decide on what kind of {hardware} to provision for his or her datastore.
- No capability planning – Customers should not must plan cluster capability at any level throughout the lifetime of the applying.
- No scaling limits – Customers should not have to fret about hitting a wall with their knowledge footprint development. It ought to really feel like its infinitely scalable and limitless.
- No server upkeep – Customers should not have to consider safety patching, upgrading dependent modules, or monitoring servers—all of the duties required to assist 24 x 7 server uptime.
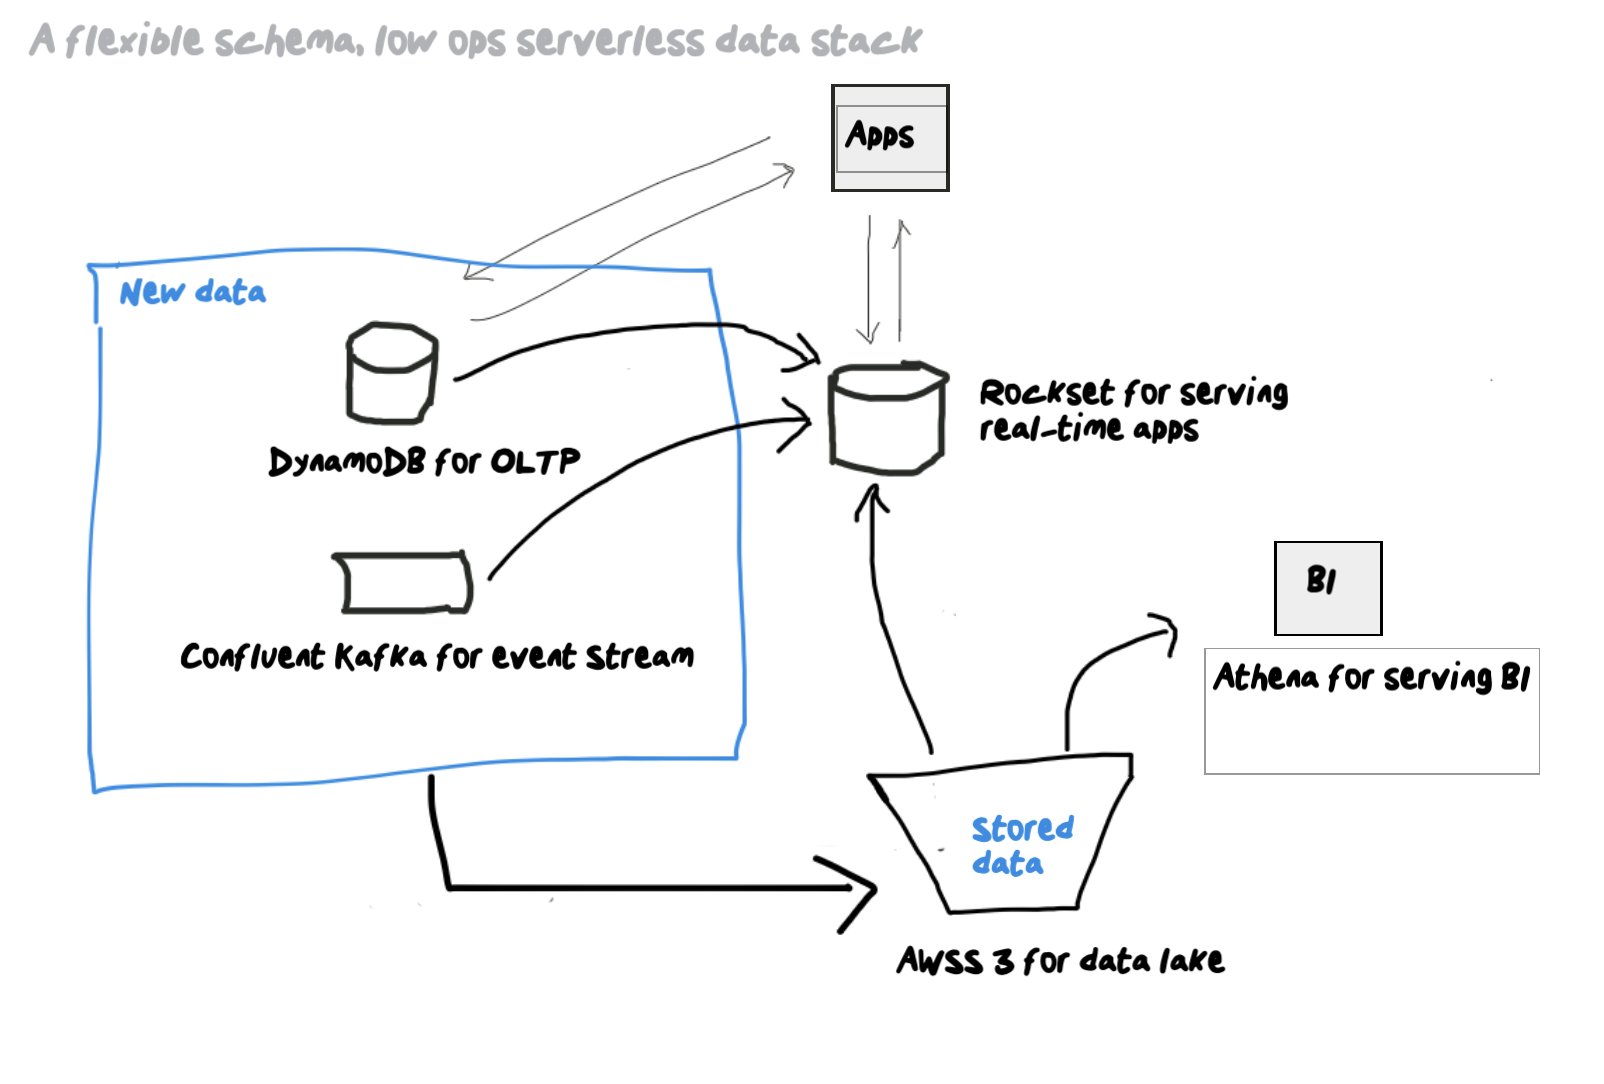
If you’re enthusiastic about your transactional database, there are some fashionable serverless choices it’s best to think about, together with DynamoDB, Aurora serverless and FaunaDB. However what about your total knowledge structure – what concerning the different knowledge shops you want and the way do you serve your BI and apps? Your knowledge stack is 10x extra streamlined once you mix the the low ops strategy of serverless with flexibility of NoSQL knowledge mannequin Any such trendy knowledge stack within the cloud makes use of a serverless transactional database for OLTP, an information stream for occasions, an information lake with question engine for BI and a real-time indexing layer for serving functions. Here’s a reference structure – discover that DynamoDB, Kafka, S3, Athena and Rockset are all JSON-compatible serverless knowledge shops so you have got a versatile schema, low ops knowledge stack that unleashes developer agility like by no means earlier than.

What components of your present software stack are serverless? How a lot of your knowledge structure has gone serverless? In case you’re new to serverless, here’s a curated checklist of superior serverless occasions taking place round you.
[ad_2]

