


[ad_1]
In accordance with over 40,000 builders, MongoDB is the hottest NOSQL database in use proper now. The instrument’s meteoric rise is probably going as a result of its JSON construction which makes it simple for Javascript builders to make use of. From a developer perspective, MongoDB is a superb answer for supporting trendy knowledge purposes. However, builders typically want to drag particular workflows out of MongoDB and combine them right into a secondary system whereas persevering with to trace any adjustments to the underlying MongoDB knowledge.
Monitoring knowledge adjustments, additionally known as “change knowledge seize” (CDC), may help present priceless insights into enterprise workflows and help different real-time purposes. There are a selection of strategies your workforce can make use of to assist monitor knowledge adjustments. This weblog put up will have a look at three of them: tailing MongoDB with an oplog, utilizing MongoDB change streams, and utilizing a Kafka connector.
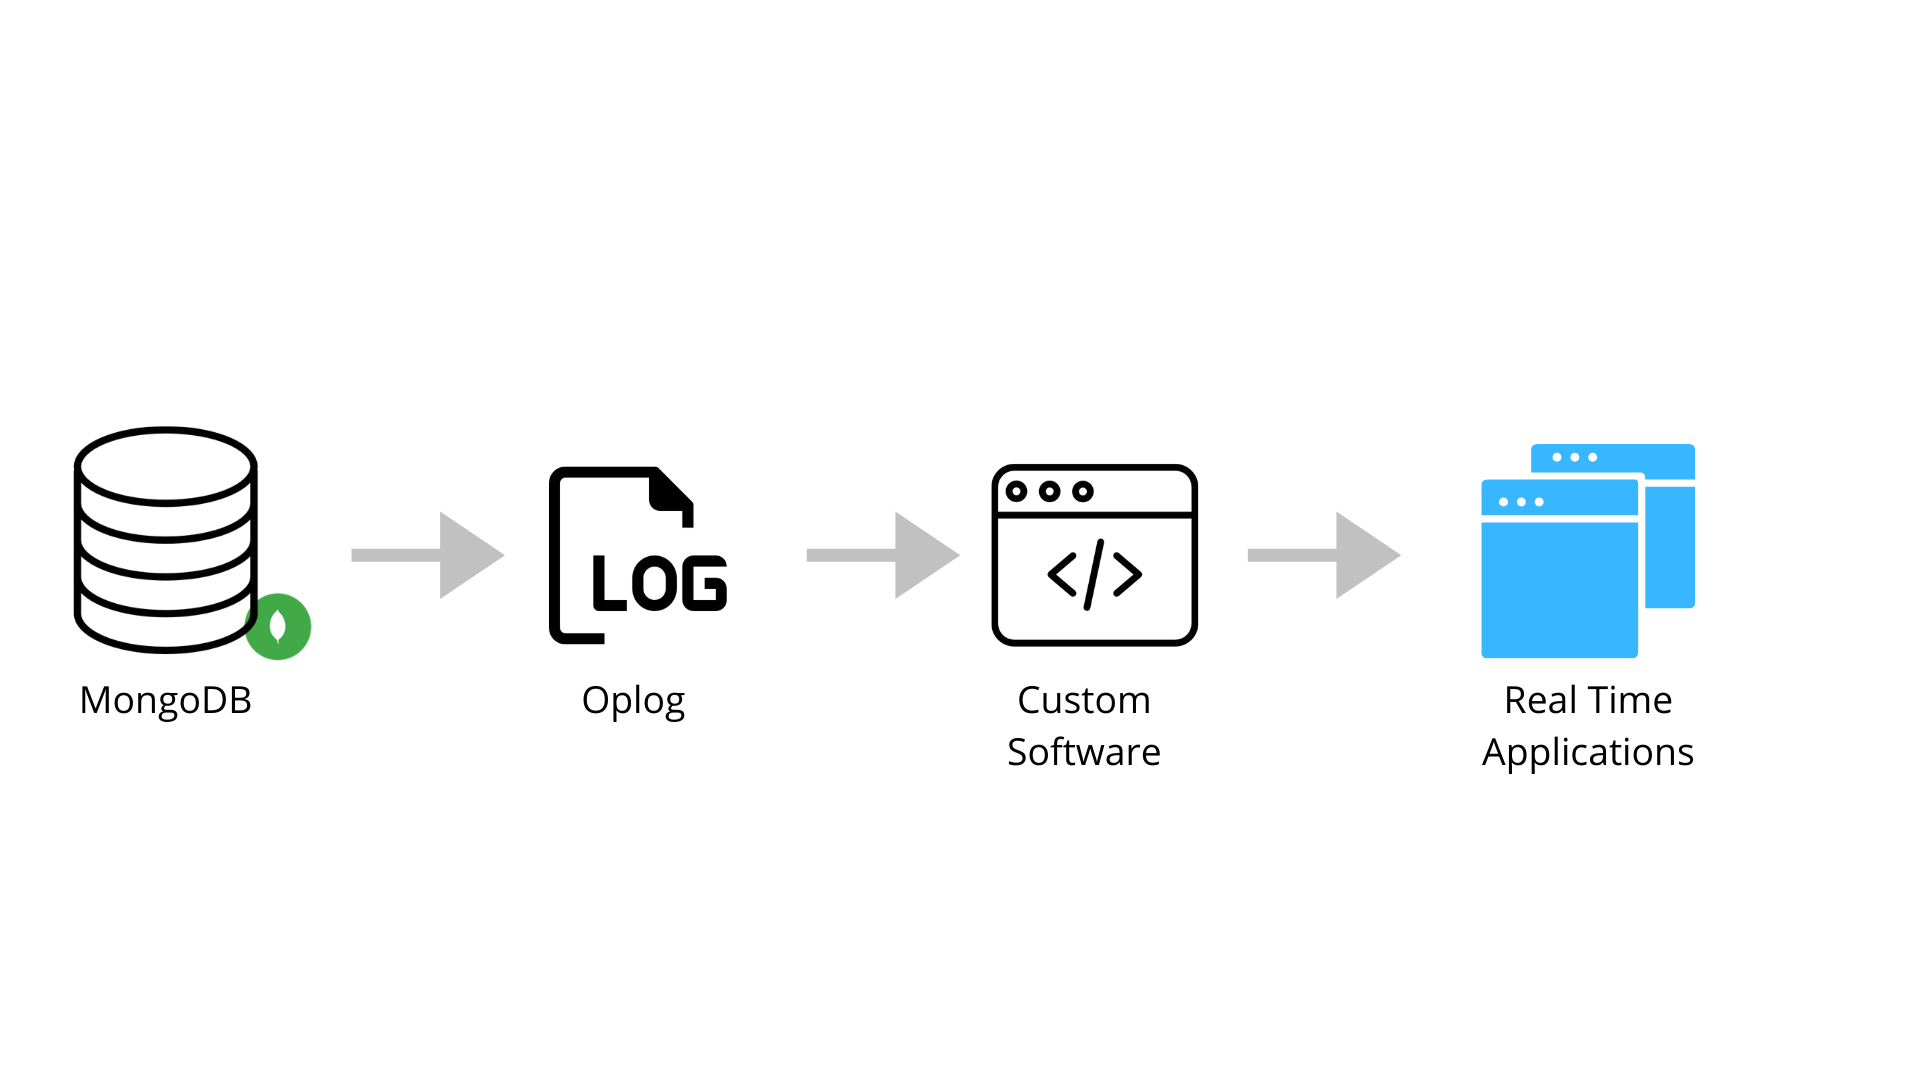
Tailing the MongoDB Oplog

Determine 1: Tailing MongoDB’s oplog to an software
An oplog is a log that tracks all the operations occurring in a database. In the event you’ve replicated MongoDB throughout a number of areas, you’ll want a mum or dad oplog to maintain all of them in sync. Tail this oplog with a tailable cursor that may observe the oplog to the newest change. A tailable cursor can be utilized like a publish-subscribe paradigm. Which means, as new adjustments are available, the cursor will publish them to some exterior subscriber that may be related to another stay database occasion.
You may arrange a tailable cursor utilizing a library like PyMongo in Python and code related to what’s supplied within the instance under. What you’ll discover is there’s a clause that states whereas cursor.alive:. This whereas assertion permits your code to maintain checking to see in case your cursor continues to be alive and doc references the completely different paperwork that captured the change within the oplog.
import time
import pymongo

import redis

redis_uri=”redis://:hostname.redislabs.com@mypassword:12345/0”
r = redis.StrictRedis(url=redis_uri)

shopper = pymongo.MongoClient()
oplog = shopper.native.oplog.rs
first = oplog.discover().kind('$pure', pymongo.DESCENDING).restrict(-1).subsequent()
row_ts = first['ts']
whereas True:
    cursor = oplog.discover({'ts': {'$gt': ts}}, tailable=True, await_data=True)
    cursor.add_option(8)
    whereas cursor.alive:
        for doc in cursor:
            row_ts = doc['ts']
            r.set(doc['h'], doc)

        time.sleep(1)
MongoDB shops its knowledge, together with the information in MongoDB’s oplog, in what it references as paperwork.
Within the code above, the paperwork are referenced within the for loop for doc in cursor:. This loop will can help you entry the person adjustments on a doc by doc foundation.
The ts is the important thing that represents a brand new row. You may see the ts key instance doc under, in JSON format:
{ "ts" : Timestamp(1422998574, 1), "h" : NumberLong("-6781014703318499311"), "v" : 2, "op" : "i", "ns" : "take a look at.mycollection", "o" : { "_id" : 1, "knowledge" : "good day" } }
Tailing the oplog does pose a number of challenges which floor after you have a scaled software requiring secondary and first cases of MongoDB. On this case, the first occasion acts because the mum or dad database that all the different databases use as a supply of reality.
Issues come up in case your main database wasn’t correctly replicated and a community outage happens. If a brand new main database is elected and that main database hasn’t correctly replicated, your tailing cursor will begin in a brand new location, and the secondaries will roll again any unsynced operations. Which means your database will drop these operations. It’s attainable to seize knowledge adjustments when the first database fails; nonetheless, to take action, your workforce should develop a system to handle failovers.
Utilizing MongoDB Change Streams
Tailing the oplog is each code-heavy and extremely dependent upon the MongoDB infrastructure’s stability. As a result of tailing the oplog creates a variety of danger and might result in your knowledge changing into disjointed, utilizing MongoDB change streams is commonly a greater choice for syncing your knowledge.

Determine 2: Utilizing MongoDB change streams to load knowledge into an software
The change streams instrument was developed to supply easy-to-track stay streams of MongoDB adjustments, together with updates, inserts, and deletes. This instrument is far more sturdy throughout community outages, when it makes use of resume tokens that assist maintain monitor of the place your change stream was final pulled from. Change streams don’t require using a pub-sub (publish-subscribe) mannequin like Kafka and RabbitMQ do. MongoDB change streams will monitor your knowledge adjustments for you and push them to your goal database or software.
You may nonetheless use the PyMongo library to interface with MongoDB. On this case, you’ll create a change_stream that acts like a client in Kafka and serves because the entity that watches for adjustments in MongoDB. This course of is proven under:
import os
import pymongo
from bson.json_util import dumps

shopper = pymongo.MongoClient(os.environ['CHANGE_STREAM_DB'])
change_stream = shopper.changestream.assortment.watch()
for change in change_stream:
    print(dumps(change))
    print('') # for readability solely
Utilizing change streams is an effective way to keep away from the problems encountered when tailing the oplog. Moreover, change streams is a superb alternative for capturing knowledge adjustments, since that’s what it was developed to do.
That mentioned, basing your real-time software on MongoDB change streams has one massive disadvantage: You’ll must design and develop knowledge units which might be seemingly listed in an effort to help your exterior purposes. Consequently, your workforce might want to tackle extra advanced technical work that may decelerate growth. Relying on how heavy your software is, this problem may create an issue. Regardless of this disadvantage, utilizing change streams does pose much less danger total than tailing the oplog does.
Utilizing Kafka Connector
As a 3rd choice, you need to use Kafka to hook up with your mum or dad MongoDB occasion and monitor adjustments as they arrive. Kafka is an open-source knowledge streaming answer that enables builders to create real-time knowledge feeds. MongoDB has a Kafka connector that may sync knowledge in each instructions. It may each present MongoDB with updates from different techniques and publish adjustments to exterior techniques.

Determine 3: Streaming knowledge with Kafka from MongoDB to an software
For this selection, you’ll must replace the configuration of each your Kafka occasion and your MongoDB occasion to arrange the CDC. The Kafka connector will put up the doc adjustments to Kafka’s REST API interface. Technically, the information is captured with MongoDB change streams within the MongoDB cluster itself after which revealed to the Kafka matters. This course of is completely different from utilizing Debezium’s MongoDB connector, which makes use of MongoDB’s replication mechanism. The necessity to use MongoDB’s replication mechanism could make the Kafka connector a neater choice to combine.
You may set the Kafka connector to trace on the assortment stage, the database stage, and even the deployment stage. From there, your workforce can use the stay knowledge feed as wanted.
Utilizing a Kafka connector is a superb choice if your organization is already utilizing Kafka for different use instances. With that in thoughts, utilizing a Kafka connector is arguably one of many extra technically advanced strategies for capturing knowledge adjustments. You need to handle and preserve a Kafka occasion that’s operating exterior to all the things else, in addition to another system and database that sits on high of Kafka and pulls from it. This requires technical help and introduces a brand new level of failure. Not like MongoDB change streams, which had been created to immediately help MongoDB, this methodology is extra like a patch on the system, making it a riskier and extra advanced choice.
Managing CDC with Rockset and MongoDB Change Streams
MongoDB change streams presents builders an alternative choice for capturing knowledge adjustments. Nevertheless, this selection nonetheless requires your purposes to immediately learn the change streams, and the instrument doesn’t index your knowledge. That is the place Rockset is available in. Rockset offers real-time indexing that may assist velocity up purposes that depend on MongoDB knowledge.

Determine 4: Utilizing change streams and Rockset to index your knowledge
By pushing knowledge to Rockset, you offload your purposes’ reads whereas benefiting from Rocket’s search, columnar, and row-based indexes, making your purposes’ reads quicker. Rockset layers these advantages on high of MongoDB’s change streams, rising the velocity and ease of entry to MongoDB’s knowledge adjustments.
Abstract
MongoDB is a very fashionable choice for software databases. Its JSON-based construction makes it simple for frontend builders to make use of. Nevertheless, it’s typically helpful to dump read-heavy analytics to a different system for efficiency causes or to mix knowledge units. This weblog introduced three of those strategies: tailing the oplog, utilizing MongoDB change streams, and utilizing the Kafka connector. Every of those strategies has its advantages and disadvantages.
In the event you’re making an attempt to construct quicker real-time purposes, Rockset is an exterior indexing answer you need to take into account. Along with having a built-in connector to seize knowledge adjustments from MongoDB, it offers real-time indexing and is straightforward to question. Rockset ensures that your purposes have up-to-date info, and it permits you to run advanced queries throughout a number of knowledge techniques—not simply MongoDB.
Different MongoDB assets:
Ben has spent his profession centered on all types of knowledge. He has centered on growing algorithms to detect fraud, cut back affected person readmission and redesign insurance coverage supplier coverage to assist cut back the general price of healthcare. He has additionally helped develop analytics for advertising and marketing and IT operations in an effort to optimize restricted assets equivalent to staff and price range. Ben privately consults on knowledge science and engineering issues. He has expertise each working hands-on with technical issues in addition to serving to management groups develop methods to maximise their knowledge.
[ad_2]

