


[ad_1]
With tons of of builders and hundreds of thousands of strains of code, Databricks is likely one of the largest Scala outlets round. This put up shall be a broad tour of Scala at Databricks, from its inception to utilization, type, tooling and challenges. We’ll cowl subjects starting from cloud infrastructure and bespoke language tooling to the human processes round managing our massive Scala codebase. From this put up, you’ll find out about every little thing huge and small that goes into making Scala at Databricks work, a helpful case examine for anybody supporting the usage of Scala in a rising group.
Utilization
Databricks was constructed by the unique creators of Apache Spark™, and commenced as distributed Scala collections. Scala was picked as a result of it is likely one of the few languages that had serializable lambda capabilities, and since its JVM runtime permits straightforward interop with the Hadoop-based big-data ecosystem. Since then, each Spark and Databricks have grown far past anybody’s preliminary creativeness. The small print of that development are past the scope of this put up, however the preliminary Scala basis remained.
Language breakdown
Scala is at the moment a type of lingua franca inside Databricks. our codebase, the most well-liked language is Scala, with hundreds of thousands of strains, adopted by Jsonnet (for configuration administration), Python (scripts, ML, PySpark) and Typescript (Net). We use Scala in all places: in distributed big-data processing, backend companies, and even some CLI tooling and script/glue code. Databricks isn’t averse to writing non-Scala code; we even have high-performance C++ code, some Jenkins Groovy, Lua working inside Nginx, bits of Go and different issues. However the massive bulk of code stays in Scala.

Scala type
Scala is a versatile language; it may be written as a Java-like object-oriented language, a Haskell-like useful language, or a Python-like scripting language. If I needed to describe the type of Scala written at Databricks, I’d put it at 50% Java-ish, 30% Python-ish, 20% useful:
- Backend companies are inclined to rely closely on Java libraries: Netty, Jetty, Jackson, AWS/Azure/GCP-Java-SDK, and many others.
- Script-like code typically makes use of libraries from the com-lihaoyi ecosystem: os-lib, requests-scala, upickle, and many others.
- We use fundamental useful programming options all through: issues like operate literals, immutable knowledge, case-class hierarchies, sample matching, assortment transformations, and many others.
- Zero utilization of “archetypical” Scala frameworks: Play, Akka, Scalaz, Cats, ZIO, and many others.
Whereas the Scala type varies all through the codebase, it usually stays someplace between a better-Java and type-safe-Python type, with some fundamental useful options. Newcomers to Databricks usually wouldn’t have any concern studying the code even with zero Scala background or coaching and may instantly begin making contributions. Databricks’ advanced programs have their very own barrier to understanding and contribution (writing large-scale high-performance multi-cloud programs is non-trivial!) however studying sufficient Scala to be productive is mostly not an issue.
Scala proficiency
Nearly everybody at Databricks writes some Scala, however few persons are fans. We do no formal Scala coaching. Folks are available with all kinds of backgrounds and write Scala on their first day and slowly decide up extra useful options as time goes on. The resultant Java-Python-ish type is the pure results of this.
Regardless of virtually everybody writing some Scala, most people at Databricks don’t go too deep into the language. Persons are first-and-foremost infrastructure engineers, knowledge engineers, ML engineers, product engineers, and so forth. Every so often, we’ve got to dive deep to take care of one thing difficult (e.g., shading, reflection, macros, and many others.), however that’s far outdoors the norm of what most Databricks engineers must take care of.
Native tooling
By and huge, most Databricks code lives in a mono-repo. Databricks makes use of the Bazel construct software for every little thing within the mono-repo: Scala, Python, C++, Groovy, Jsonnet config information, Docker containers, Protobuf code mills, and many others. Provided that we began with Scala, this was once all SBT, however we largely migrated to Bazel for its higher assist for big codebases. We nonetheless preserve some smaller open-source repos on SBT or Mill, and a few code has parallel Bazel/SBT builds as we attempt to full the migration, however the bulk of our code and infrastructure is constructed round Bazel.
Bazel at Databricks
Bazel is superb for big groups. It’s the solely construct software that runs all of your construct steps and assessments inside separate LXC containers by default, which helps keep away from surprising interactions between elements of your construct. By default, it’s parallel and incremental, one thing that’s of accelerating significance as the dimensions of the codebase grows. As soon as arrange and dealing, it tends to work the identical on everybody’s laptop computer or construct machines. Whereas not 100% airtight, in observe it’s ok to largely keep away from an enormous class of issues associated to inter-test interference or unintended dependencies, which is essential for maintaining the construct dependable because the codebase grows. We focus on utilizing Bazel to parallelize and pace up take a look at runs within the weblog put up Quick Parallel Testing with Bazel at Databricks.
The draw back of Bazel is it requires a big workforce. Bazel encapsulates 20 years of evolution from python-generating-makefiles, and it exhibits: there’s loads of accrued cruft and sharp edges and complexity. Whereas it tends to work effectively as soon as arrange, configuring Bazel to do what you need could be a problem. It’s to the purpose the place you mainly want a 2-4 individual workforce specializing in Bazel to get it working effectively.
Moreover, through the use of Bazel you surrender on loads of the prevailing open-source tooling and data. Some library tells you to pip set up one thing? Supplies an SBT/Maven/Gradle/Mill plugin to work with? Some executable needs to be apt-get set uped? With Bazel you should utilize none of that, and would wish to write down loads of integrations your self. Whereas any particular person integration is just not too troublesome to arrange, you typically find yourself needing loads of them, which provides as much as turn into fairly a big time funding.
Whereas these downsides are an appropriate price for a bigger group, it makes Bazel a complete non-starter for solo tasks and small groups. Even Databricks has some small open-source codebases nonetheless on SBT or Mill the place Bazel doesn’t make sense. For the majority of our code and builders, nevertheless, they’re all on Bazel.
Compile instances
Scala compilation pace is a typical concern, and we put in vital effort to mitigate the issue:
- Arrange Bazel to compile Scala utilizing a long-lived background compile employee to maintain the compiler JVM sizzling and quick.
- Arrange incremental compilation (by way of Zinc) and parallel compilation (by way of Hydra) on an opt-in foundation for individuals who wish to use it.
- Upgraded to a newer model of Scala 2.12, which is far sooner than earlier variations.
Extra particulars on the work are within the weblog put up Speedy Scala Builds with Bazel at Databricks. Whereas the Scala compiler continues to be not significantly quick, our funding in which means that Scala compile instances will not be among the many prime ache factors confronted by our engineers.
Cross constructing
Cross constructing is one other frequent concern for Scala groups: Scala is binary incompatible between main variations, which means code meant to assist a number of variations must be individually compiled for each. Even ignoring Scala, supporting a number of Spark variations has related necessities. Databricks’ Bazel-Scala integration has cross-building in-built, the place each construct goal (equal to a “module” or “subproject”) can specify a listing of Scala variations it helps:
cross_scala_lib( base_name = "my_lib", cross_scala_versions = ["2.11", "2.12"], cross_deps = ["other_lib"], srcs = ["Test.scala"], )With the above inputs, our cross_scala_lib operate generates my_lib_2.11 and my_lib_2.12 variations of the construct goal, with dependencies on the corresponding other_lib_2.11 and other_lib_2.12 targets. Successfully, every Scala model will get its personal sub-graph of construct targets throughout the bigger Bazel construct graph.
This type of duplicating the construct graph for cross-building has a number of benefits over the extra conventional mechanism for cross-building, which includes a worldwide configuration flag set within the construct software (e.g., ++2.12.12 in SBT):

- Totally different variations of the identical construct goal are robotically constructed and examined in parallel since they’re all part of the identical huge Bazel construct graph.
- A developer can clearly see which construct targets assist which Scala variations.
- We are able to work with a number of Scala variations concurrently, e.g., deploying a multi-JVM software the place a backend service on Scala 2.12 interacts with a Spark driver on Scala 2.11.
- We are able to incrementally roll out assist for a brand new Scala model, which significantly simplifies migrations since there’s no “huge bang” cut-over from the previous model to the brand new.
Whereas this system for cross-building originated at Databricks for our personal inside construct, it has unfold elsewhere: to the Mill construct software’s cross-build assist, and even the previous SBT construct software by way of SBT-CrossProject.
Managing third-party dependencies
Third-party dependencies are pre-resolved and mirrored; dependency decision is faraway from the “sizzling” edit-compile-test path and solely must be re-run when you replace/add a dependency. It is a frequent sample throughout the Databricks’ codebase.
Each exterior obtain location we use inevitably goes down; whether or not it’s Maven Central being flaky, PyPI having an outage, and even www.7-zip.org returning 500s. Someway it doesn’t appear to matter who we’re downloading what from: exterior downloads inevitably cease working, which causes downtime and frustration for Databricks builders.
The way in which we mirror dependencies resembles a lockfile, frequent in some ecosystems: if you change a third-party dependency, you run a script that updates the lockfile to the most recent resolved set of dependencies. However we add just a few twists:
- Somewhat than simply recording dependency variations, we mirror the respective dependency to our inside package deal repository. Thus we not solely keep away from relying on third-party package deal hosts for model decision however we additionally keep away from relying on them for downloads as effectively.
- Somewhat than recording a flat listing of dependencies, we additionally report the dependency graph between them. This permits any inside construct goal relying on a third-party package deal to tug in precisely the transitive dependencies with out reaching out over the community.
- We are able to handle a number of incompatible units of dependencies in the identical codebase by resolving a number of lockfiles. This offers us the pliability for coping with incompatible ecosystems, e.g., Spark 2.4 and Spark 3.0, whereas nonetheless having the assure that so long as somebody sticks to dependencies from a single lockfile, they received’t have any surprising dependency conflicts.

As you possibly can see, whereas the “maven/replace” course of to change exterior dependencies (dashed arrows) requires entry to the third-party package deal repos, the extra frequent “bazel construct” course of (stable arrows) takes locations completely inside code and infrastructure that we management.
This fashion of managing exterior dependencies provides us the perfect of each worlds. We get the fine-grained dependency decision that instruments like Maven or SBT present, whereas additionally offering the pinned dependency variations that lock-file-based instruments like Pip or Npm present, in addition to the hermeticity of working our personal package deal mirror. That is totally different from how most open-source construct instruments handle third-party dependencies, however in some ways it’s higher. Vendoring dependencies on this manner is quicker, extra dependable, and fewer prone to be affected by third-party service outages than the traditional manner of instantly utilizing the third-party package deal repositories as a part of your construct.
Linting workflows
Maybe the final fascinating a part of our native growth expertise is linting: issues which can be most likely a good suggestion, however for which there are sufficient exceptions that you may’t simply flip them into errors. This class consists of Scalafmt, Scalastyle, compiler warnings, and many others. To deal with these, we:
- Don’t implement linters throughout native growth, which helps streamline the dev loop maintaining it quick.
- Implement linters when merging into grasp; this ensures that code in grasp is of top of the range.
- Present escape hatches for eventualities through which the linters are fallacious and should be overruled.
This technique applies equally to all linters, simply with minor syntactic variations (e.g., // scalafmt:off vs // scalastyle:off vs @SuppressWarnings because the escape hatch). This turns warnings from transient issues that scrolled previous within the terminal to long-lived artifacts that seem within the code:
 @SupressWarnings(Array(“match will not be exhaustive”))
val targetCapacityType = fleetSpec.fleetOption match {
  case FleetOption.SpotOption(_) => “spot”
  case FleetOption.OnDemandOption(_) => “on-demand”
}
The objective of all this ceremony round linting is to power individuals to concentrate to lint errors. By their nature, linters all the time have false positives, however a lot of the time, they spotlight actual code smells and points. Forcing individuals to silence the linter with an annotation forces each creator and reviewer to think about every warning and resolve whether or not it’s actually false optimistic or whether or not it’s highlighting an actual downside. This method additionally avoids the frequent failure mode of warnings piling up within the console output unheeded. Lastly, we could be extra aggressive in rolling out new linters, as even with out 100% accuracy the false positives can all the time be overridden after correct consideration.
Distant infrastructure
Other than the construct software that runs domestically in your machine, Scala growth at Databricks is supported by just a few key companies. These run in our AWS dev and take a look at setting and are essential for growth work at Databricks to make progress.
Bazel distant cache
The concept of the Bazel Distant Cache is straightforward: by no means compile the identical factor twice, company-wide. If you’re compiling one thing that your colleague compiled on their laptop computer, utilizing the identical inputs, you need to be capable to merely obtain the artifact they compiled earlier.

Distant Caching is a characteristic of the Bazel construct software, however requires a backing server implementing the Bazel Distant Cache Protocol. On the time, there have been no good open-source implementations, so we constructed our personal: a tiny golang server constructed on prime of GroupCache and S3. This significantly accelerates work, particularly when you’re engaged on incremental modifications from a current grasp model and virtually every little thing has been compiled already by some colleague or CI machine.
The Bazel Distant Cache is just not problem-free. It’s one more service we have to baby-sit. Generally dangerous artifacts get cached, inflicting the construct to fail. Nonetheless, the pace advantages of the Bazel Distant Cache are sufficient that our growth course of can not stay with out it.
Devbox
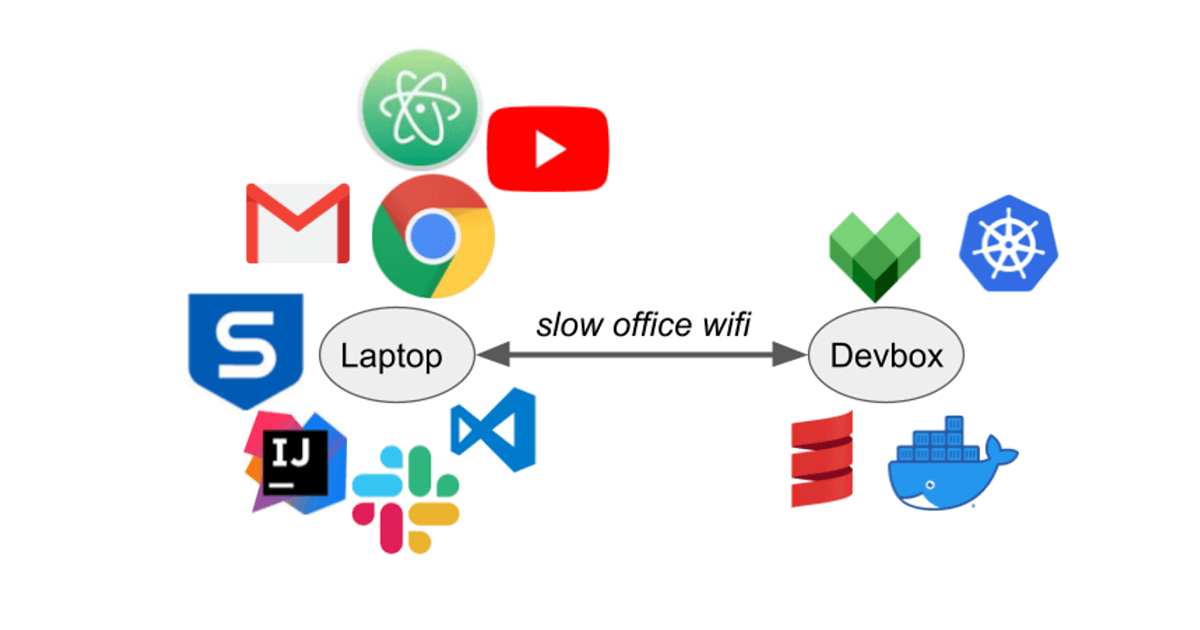
The concept of the Databricks Devbox is straightforward: edit code domestically, run it on a beefy cloud VM co-located with all of your cloud infrastructure.
A typical workflow is to edit code in Intellij, run bash instructions to construct/take a look at/deploy on devbox. Under you possibly can see the devbox in motion: each time the consumer edits code in IntelliJ, the inexperienced “tick” icon within the menu bar briefly flashes to a blue “sync” icon earlier than flashing again to inexperienced, indicating that sync has accomplished:
The Devbox has a bespoke high-performance file synchronizer to convey code modifications out of your native laptop computer to the distant VM. Hooking into fsevents on OS-X and inotify on Linux, it could actually reply to code modifications in real-time. By the point you click on over out of your editor to your console, your code is synced and prepared for use.
This has a number of benefits over creating domestically in your laptop computer:
- The Devbox runs Linux, which is similar to our CI environments, and nearer to our manufacturing environments than builders’ Mac-OSX laptops. This helps guarantee your code behaves the identical in dev, CI, and prod.

- Devbox lives in EC2 with our Kubernetes-clusters, remote-cache, and docker-registries. This implies nice community efficiency between the devbox and something you care about.

- Bazel/Docker/Scalac don’t must combat with IntelliJ/Youtube/Hangouts for system sources. Your laptop computer doesn’t get so sizzling, your followers don’t spin up, and your working system (principally Mac-OSX for Databricks builders) doesn’t get laggy.

- The Devbox is customizable and may run any EC2 occasion kind. Need RAID0-ed ephemeral disks for higher filesystem perf? 96 cores and 384gb of RAM to check one thing compute-heavy? Go for it! We shut down cases when not in use, so much more costly cases received’t break the financial institution when used for a brief time frame.

- The Devbox is disposable. apt-get set up the fallacious factor? By accident rm some system information you shouldn’t? Some third-party installer left your system in a nasty state? It’s simply an EC2 occasion, so throw it away and get a brand new one.

The pace distinction from doing issues on the Devbox is dramatic: multi-minute uploads or downloads reduce down to some seconds. Have to deploy to Kubernetes? Add containers to a docker registry? Obtain huge binaries from the distant cache? Doing it on the Devbox with 10G knowledge heart networking is orders of magnitudes sooner than doing it out of your laptop computer over dwelling or workplace wifi. Even native compute/disk-bound workflows are sometimes sooner working on the Devbox as in comparison with working them on a developer’s laptop computer.
Runbot
Runbot is a bespoke CI platform, written in Scala, managing our elastic “naked EC2” cluster with 100s of cases and 10,000s of cores. Mainly a handmade Jenkins, however with all of the issues we wish, and with out all of the issues we don’t need. It’s about 10K-LOC of Scala, and serves to validate all pull requests that merge into Databricks’ major repositories.

Runbot leverages the Bazel construct graph to selectively run assessments on pull requests relying on what code was modified, aiming to return significant CI outcomes to the developer as quickly as doable. Runbot additionally integrates with the remainder of our dev infrastructure:
- We deliberately maintain the Runbot CI take a look at setting and the Devbox distant dev environments as related as doable – even working the identical AMIs – to attempt to keep away from eventualities the place code behaves in a different way in a single or the opposite.
- Runbot’s employee cases make full use of the Bazel Distant Cache, permitting them to skip “boilerplate” construct steps and solely re-compiling and re-testing issues which will have been affected by a pull request.
A extra detailed dive into the Runbot system could be discovered within the weblog put up Growing Databricks’ Runbot CI Answer.
Check Shards
Check Shards let a developer simply spin up a hermetic-ish Databricks-in-a-box, letting you run integration assessments or handbook assessments by way of the browser or API. As Databricks is a multi-cloud product supporting Amazon/Azure/Google cloud platforms, Databricks’ Check Shards can equally be spun up on any cloud to offer you a spot for integration-testing and manual-testing of your code modifications.

A take a look at shard more-or-less includes the whole lot of the Databricks platform – all our backend companies – simply with lowered useful resource allocations and a few simplified infrastructure. Most of those are Scala companies, though we’ve got another languages combined in as effectively.
Sustaining Databricks’ Check Shards is a continuing problem:
- Our Check Shards are supposed to precisely replicate the present manufacturing setting with as excessive constancy as doable.
- As Check Shards are used as a part of the iterative growth loop, creating and updating them must be as quick as doable.
- We’ve got tons of of builders utilizing take a look at shards, it’s unfeasible to spin up a full-sized manufacturing deployment for every one, and we should discover methods to chop corners whereas preserving constancy.
- Our manufacturing setting is quickly evolving, with new companies, new infrastructural parts, even new cloud platforms typically, and our Check Shards must sustain.
Check shards require infrastructure that’s massive scale and sophisticated, and we hit all kinds of limitations we by no means imagined existed. What do you do when your Azure account runs out of useful resource teams? When AWS load balancer creation turns into a bottleneck? When the variety of pods makes your Kubernetes cluster begin misbehaving? Whereas “Databricks in a field” sounds easy, the practicality of offering such an setting to 100s of builders is an ongoing problem. Numerous inventive strategies are used to take care of the 4 constraints above and make sure the expertise of Databricks’ builders utilizing take a look at shards stays as easy as doable.
Databricks at present runs tons of of take a look at shards unfold over a number of clouds and areas. Regardless of the problem of sustaining such an setting, take a look at shards are non-negotiable. They supply a vital integration and handbook testing setting earlier than your code is merged into grasp and shipped to staging and manufacturing.
Good elements
Scala/JVM efficiency is mostly nice
Databricks has had no scarcity of efficiency points, some previous and a few ongoing. Nonetheless, nearly none of those points had been attributable to Scala or the JVM.
That’s to not say Databricks doesn’t have efficiency points typically. Nevertheless, they are typically within the database queries, within the RPCs, or within the total system structure. Whereas typically some inefficiently-written application-level code could cause slowdowns, that form of factor is often simple to type out with a profiler and a few refactoring.
Scala lets us write some surprisingly high-performance code, e.g., our Sjsonnet configuration compiler is orders of magnitude sooner than the C++ implementation it changed, as mentioned in our earlier weblog put up Writing a Sooner Jsonnet Compiler.
However total, the principle advantage of Scala/JVM’s good efficiency is how little we take into consideration the compute efficiency of our Scala code. Whereas efficiency could be a difficult matter in large-scale distributed programs, the compute efficiency of our Scala code working on the JVM simply isn’t an issue.
A versatile lingua franca makes it straightforward to share tooling and experience
With the ability to share tooling all through the group is nice. We are able to use the identical build-tool integration, IDE integration, profilers, linters, code type, and many others. on backend net companies, our high-performance huge knowledge runtime, and our small scripts and executables.
Whilst code type varies all through the org, all the identical tooling nonetheless applies, and it’s acquainted sufficient that the language poses no barrier for somebody leaping in.
That is particularly vital when manpower is restricted. Sustaining a single toolchain with the wealthy assortment of instruments described above is already an enormous funding. Even with the small variety of languages we’ve got, it’s clear that the “secondary” language toolchains will not be as polished as our toolchain for Scala, and the issue of bringing them as much as the identical stage is clear. Having to duplicate our Scala toolchain funding N instances to assist all kinds of various languages can be a really expensive endeavor we’ve got to date managed to keep away from.
Scala is surprisingly good for scripting/glue!
Folks often consider Scala as a language for compilers or Severe Enterprise™ backend companies. Nevertheless, we’ve got discovered that Scala can be a superb language for script-like glue code! By this, I imply code juggling subprocesses, speaking to HTTP APIs, mangling JSON, and many others. Whereas the high-performance of Scala’s JVM runtime doesn’t matter for scripting, many different platform advantages nonetheless apply:
- Scala is concise. Relying on the libraries you employ, it may be as or much more concise than “conventional” scripting languages like Python or Ruby, and is simply as readable.
- Scripting/glue code is commonly the toughest to unit take a look at. Integration testing, whereas doable, is commonly gradual and painful; greater than as soon as we’ve had third-party companies throttle us for working too many integration assessments! In this sort of setting, having a fundamental stage of compile-time checking is a godsend.
- Deployment is nice: meeting jars are much better than Python PEXs, for instance, as they’re extra normal, easy, airtight, performant, and many others. Attempting to deploy Python code throughout totally different environments has been a relentless headache, with somebody all the time brew set up or apt-get set uping one thing that might trigger our deployed-and-tested Python executables to interrupt. This doesn’t occur with Scala meeting jars.
Scala/JVM isn’t good for scripting: there’s a 0.5-1s JVM startup overhead for any non-trivial program, reminiscence utilization is excessive, and the iteration loop of edit/compile/working a Scala program is relatively gradual. Nonetheless, we’ve got discovered that there are many advantages of utilizing Scala over a conventional scripting language like Python, and we’ve got launched Scala in various eventualities the place somebody would naturally count on a scripting language for use. Even Scala’s REPL has confirmed to be a priceless software for interacting with companies, each inside and third-party, in a handy and versatile method.
Conclusion
Scala at Databricks has confirmed to be a stable basis for us to construct upon
Scala is just not with out its challenges or issues, however neither would every other language or platform. Massive organizations working dynamic languages inevitably put big effort into rushing them up or including compile-time checking; massive organizations on different static languages inevitably put effort into DSLs or different instruments to attempt to pace up growth. Whereas Scala doesn’t undergo from both downside, it has its personal points, which we needed to put within the effort to beat.
One focal point is how generic a lot of our instruments and strategies are. Our CI system, devboxes, distant cache, take a look at shards, and many others. will not be Scala-specific. Neither is our technique for dependency administration or linting. A lot of those apply no matter language or platform and profit our builders writing Python or Typescript or C++ as a lot as these writing Scala. It seems Scala is just not particular; Scala builders face most of the identical issues builders utilizing different languages face, with most of the identical options.
One other fascinating factor is how separate Databricks is from the remainder of the Scala ecosystem; we’ve got by no means actually purchased into the “reactive” mindset or the “hardcore-functional-programming” mindset. We do issues like cross-building, dependency administration, and linting very in a different way from most locally. Regardless of that, or even perhaps due to that, we’ve got been in a position to scale our Scala-using engineering groups with out concern and reap the advantages of utilizing Scala as a lingua franca throughout the group.
Databricks is just not significantly dogmatic about Scala. We’re firstly huge knowledge engineers, infrastructure engineers, and product engineers. Our engineers need issues like sooner compile instances, higher IDE assist, or clearer error messages, and are usually bored with pushing the boundaries of the Scala language. We use totally different languages the place they make sense, whether or not configuration administration by way of Jsonnet, machine studying in Python, or high-performance knowledge processing in C++. Because the enterprise and workforce grows, it’s inevitable that we see a point of divergence and fragmentation. Nonetheless, we’re reaping the advantages of a unified platform and tooling round Scala on the JVM, and hope to stretch that profit for so long as doable.
Databricks is likely one of the largest Scala outlets round nowadays, with a rising workforce and a rising enterprise. Should you assume our method to Scala and growth on the whole resonates, you need to undoubtedly come work with us!
[ad_2]

