

[ad_1]
It’s been roughly 23 years since one of many first robotic animals trotted on the scene, defying classical notions of our cuddly four-legged associates. Since then, a barrage of the strolling, dancing, and door-opening machines have commanded their presence, a glossy combination of batteries, sensors, steel, and motors. Lacking from the listing of cardio actions was one each beloved and loathed by people (relying on whom you ask), and which proved barely trickier for the bots: studying to run.
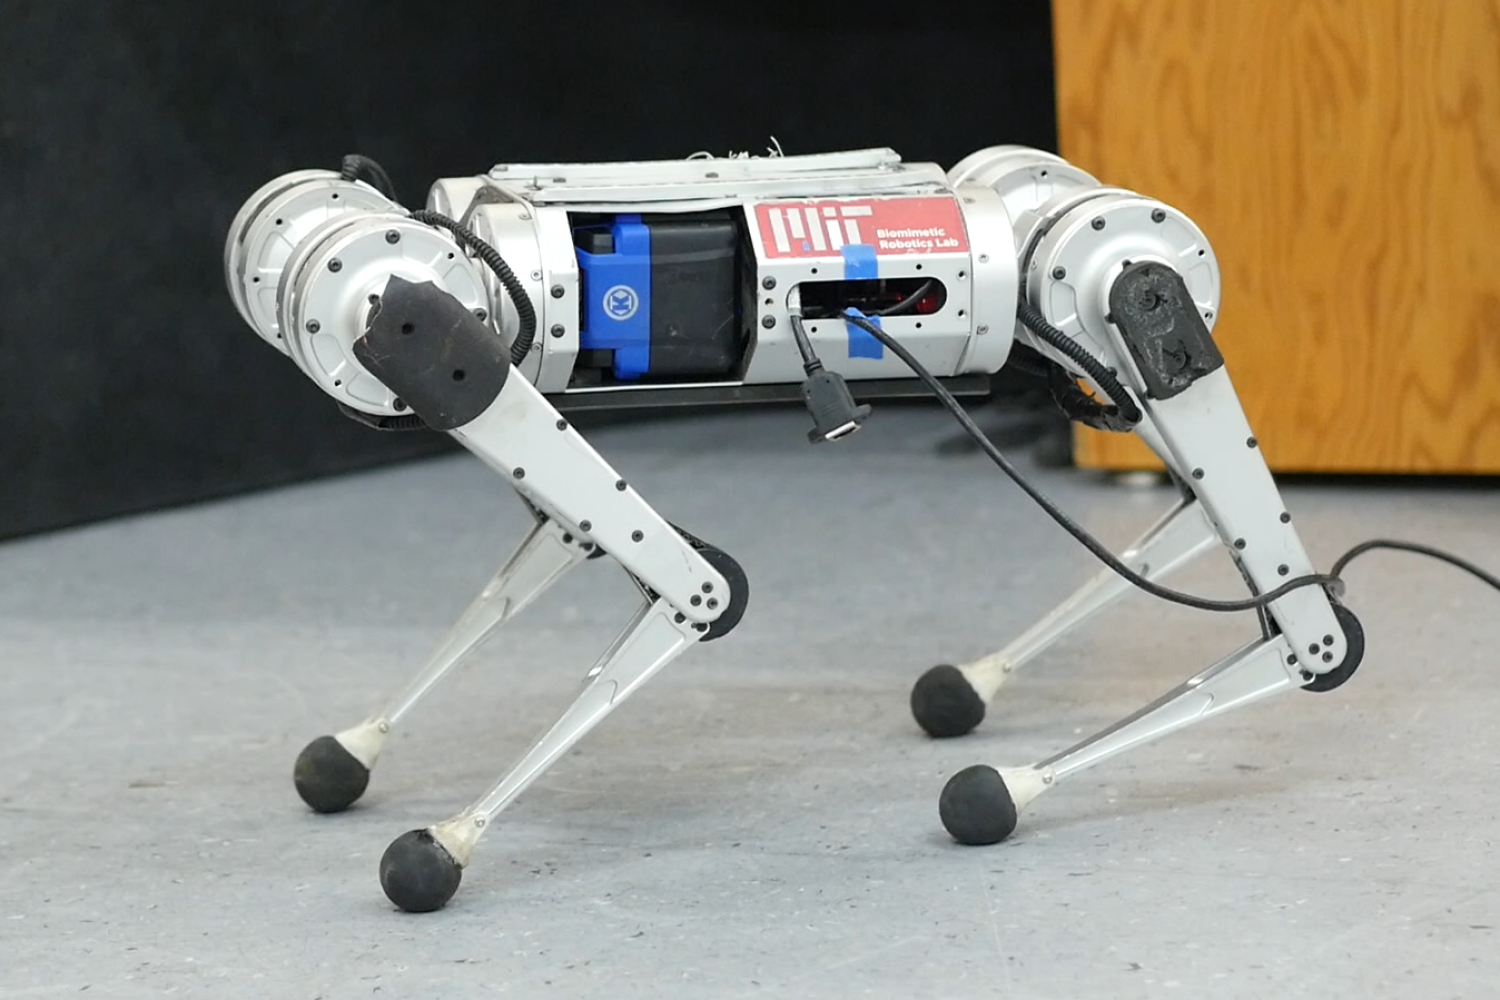
Researchers from MIT’s Unbelievable AI Lab, a part of the Pc Science and Synthetic Intelligence Laboratory (CSAIL) and directed by MIT Assistant Professor Pulkit Agrawal, in addition to the Institute of AI and Basic Interactions (IAIFI) have been engaged on fast-paced strides for a robotic mini cheetah — and their model-free reinforcement studying system broke the file for the quickest run recorded. Right here, MIT PhD scholar Gabriel Margolis and IAIFI postdoc Ge Yang focus on simply how briskly the cheetah can run.
Q: We’ve seen movies of robots working earlier than. Why is working tougher than strolling?
A: Reaching quick working requires pushing the {hardware} to its limits, for instance by working close to the utmost torque output of motors. In such situations, the robotic dynamics are exhausting to analytically mannequin. The robotic wants to reply rapidly to modifications within the setting, such because the second it encounters ice whereas working on grass. If the robotic is strolling, it’s transferring slowly and the presence of snow will not be sometimes a problem. Think about should you had been strolling slowly, however fastidiously: you possibly can traverse nearly any terrain. Immediately’s robots face a similar drawback. The issue is that transferring on all terrains as should you had been strolling on ice could be very inefficient, however is frequent amongst at present’s robots. People run quick on grass and decelerate on ice — we adapt. Giving robots an analogous functionality to adapt requires fast identification of terrain modifications and rapidly adapting to forestall the robotic from falling over. In abstract, as a result of it’s impractical to construct analytical (human-designed) fashions of all doable terrains prematurely, and the robotic’s dynamics develop into extra advanced at high-velocities, high-speed working is tougher than strolling.
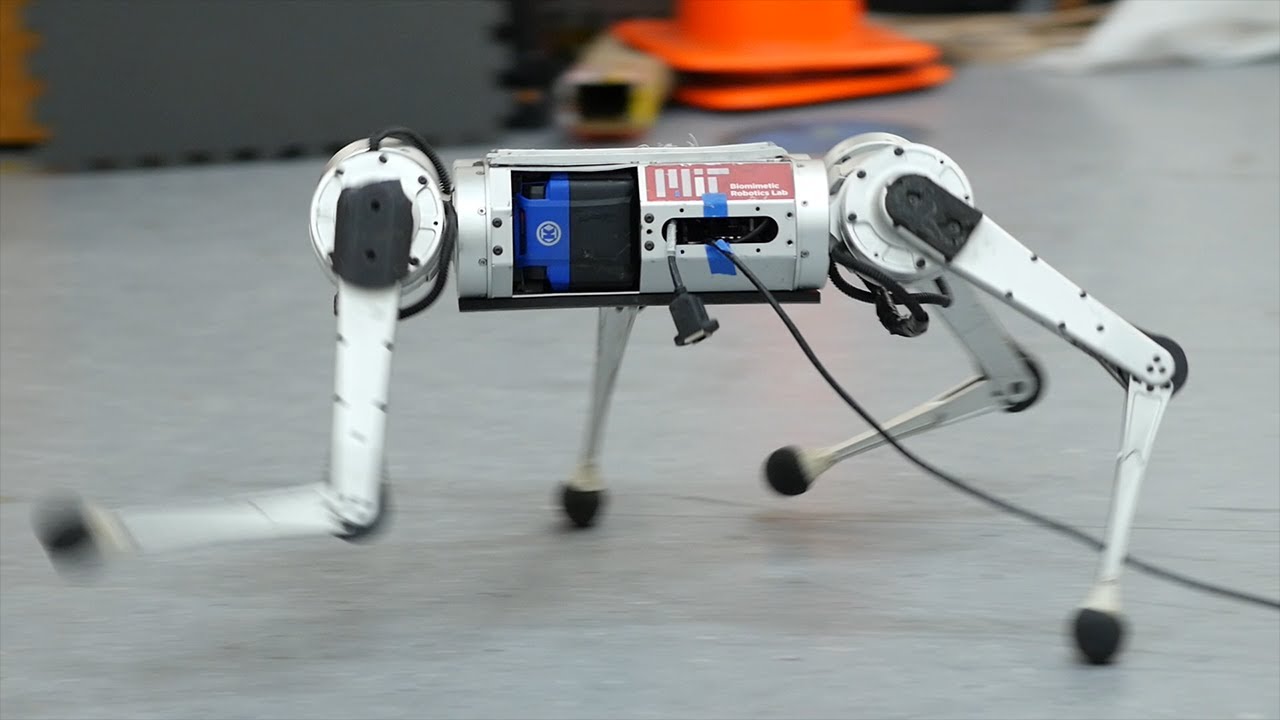
The MIT mini cheetah learns to run sooner than ever, utilizing a studying pipeline that’s fully trial and error in simulation.
Q: Earlier agile working controllers for the MIT Cheetah 3 and mini cheetah, in addition to for Boston Dynamics’ robots, are “analytically designed,” counting on human engineers to investigate the physics of locomotion, formulate environment friendly abstractions, and implement a specialised hierarchy of controllers to make the robotic stability and run. You employ a “learn-by-experience mannequin” for working as an alternative of programming it. Why?
A: Programming how a robotic ought to act in each doable scenario is just very exhausting. The method is tedious, as a result of if a robotic had been to fail on a selected terrain, a human engineer would want to determine the reason for failure and manually adapt the robotic controller, and this course of can require substantial human time. Studying by trial and error removes the necessity for a human to specify exactly how the robotic ought to behave in each scenario. This is able to work if: (1) the robotic can expertise an especially wide selection of terrains; and (2) the robotic can mechanically enhance its conduct with expertise.
Due to trendy simulation instruments, our robotic can accumulate 100 days’ price of expertise on numerous terrains in simply three hours of precise time. We developed an strategy by which the robotic’s conduct improves from simulated expertise, and our strategy critically additionally allows profitable deployment of these discovered behaviors in the true world. The instinct behind why the robotic’s working expertise work nicely in the true world is: Of all of the environments it sees on this simulator, some will educate the robotic expertise which can be helpful in the true world. When working in the true world, our controller identifies and executes the related expertise in real-time.
Q: Can this strategy be scaled past the mini cheetah? What excites you about its future functions?
A: On the coronary heart of synthetic intelligence analysis is the trade-off between what the human must construct in (nature) and what the machine can study by itself (nurture). The normal paradigm in robotics is that people inform the robotic each what process to do and how one can do it. The issue is that such a framework will not be scalable, as a result of it might take immense human engineering effort to manually program a robotic with the talents to function in lots of numerous environments. A extra sensible approach to construct a robotic with many numerous expertise is to inform the robotic what to do and let it determine the how. Our system is an instance of this. In our lab, we’ve begun to use this paradigm to different robotic methods, together with palms that may decide up and manipulate many various objects.
This work is supported by the DARPA Machine Frequent Sense Program, Naver Labs, MIT Biomimetic Robotics Lab, and the NSF AI Institute of AI and Basic Interactions. The analysis was performed on the Unbelievable AI Lab.
[ad_2]

