


[ad_1]
Final Up to date on July 13, 2022
Convolutional neural networks have been discovered profitable in pc imaginative and prescient purposes. Numerous community architectures are proposed and they’re neither magical nor laborious to grasp.
On this tutorial, we’ll make sense of the operation of convolutional layers and their position in a bigger convolutional neural community.
After ending this tutorial, you’ll be taught:
- How convolutional layers extract options from picture
- How totally different convolutional layers can stack as much as construct a neural community
Let’s get began.
Understanding the Design of a Convolutional Neural Community
Picture by Kin Shing Lai. Some rights reserved.
Overview
This text is break up into three sections; they’re:
- An Instance Community
- Exhibiting the Characteristic Maps
- Impact of the Convolutional Layers
An Instance Community
The next is a program to do picture classification on the CIFAR-10 dataset:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 |
import matplotlib.pyplot as plt import numpy as np import tensorflow as tf from tensorflow.keras.fashions import Sequential from tensorflow.keras.layers import Conv2D, Dropout, MaxPooling2D, Flatten, Dense from tensorflow.keras.constraints import MaxNorm from tensorflow.keras.datasets.cifar10 import load_data
(X_train, y_train), (X_test, y_test) = load_data()
# rescale picture X_train_scaled = X_train / 255.0 X_test_scaled = X_test / 255.0
mannequin = Sequential([ Conv2D(32, (3,3), input_shape=(32, 32, 3), padding=“same”, activation=“relu”, kernel_constraint=MaxNorm(3)), Dropout(0.3), Conv2D(32, (3,3), padding=“same”, activation=“relu”, kernel_constraint=MaxNorm(3)), MaxPooling2D(), Flatten(), Dense(512, activation=“relu”, kernel_constraint=MaxNorm(3)), Dropout(0.5), Dense(10, activation=“sigmoid”) ])
mannequin.compile(optimizer=“adam”, loss=“sparse_categorical_crossentropy”, metrics=“sparse_categorical_accuracy”)
mannequin.match(X_train_scaled, y_train, validation_data=(X_test_scaled, y_test), epochs=25, batch_size=32) |
This community ought to be capable of obtain round 70% accuracy in classification. The pictures are in 32×32 pixels in RGB colour. They’re in 10 totally different lessons, which the labels are integers from 0 to 9.
We will print the community utilizing Keras’ abstract() perform:
On this community, the next will probably be proven on the display:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 |
Mannequin: “sequential” _________________________________________________________________ Layer (kind) Output Form Param # ================================================================= conv2d (Conv2D) (None, 32, 32, 32) 896
dropout (Dropout) (None, 32, 32, 32) 0
conv2d_1 (Conv2D) (None, 32, 32, 32) 9248
max_pooling2d (MaxPooling2D (None, 16, 16, 32) 0 )
flatten (Flatten) (None, 8192) 0
dense (Dense) (None, 512) 4194816
dropout_1 (Dropout) (None, 512) 0
dense_1 (Dense) (None, 10) 5130
================================================================= Complete params: 4,210,090 Trainable params: 4,210,090 Non-trainable params: 0 _________________________________________________________________ |
It’s typical in a community for picture classification to comprise of convolutional layers at early stage, with dropout and pooling layers interleaved. At later stage, the output from convolutional layers are flattened and processed by some absolutely linked layers.
Exhibiting the Characteristic Maps
Within the above community, we used two convolutional layers (Conv2D). The primary layer is outlined as follows:
|
Conv2D(32, (3,3), input_shape=(32, 32, 3), padding=“similar”, activation=“relu”, kernel_constraint=MaxNorm(3)) |
which suggests the convolutional layer could have a 3×3 kernel and apply on an enter picture of 32×32 pixels and three channels (the RGB colours). The output of this layer will probably be 32 channels.
To make sense of the convolutional layer, we are able to try its kernel. The variable mannequin holds the community and we are able to discover the kernel of the primary convolutional layer with the next:
|
... print(mannequin.layers[0].kernel) |
and this prints:
|
<tf.Variable ‘conv2d/kernel:0’ form=(3, 3, 3, 32) dtype=float32, numpy= array([[[[-2.30068922e-01, 1.41024575e-01, -1.93124503e-01, -2.03153938e-01, 7.71819279e-02, 4.81446862e-01, -1.11971676e-01, -1.75487325e-01, -4.01797555e-02, … 4.64215249e-01, 4.10646647e-02, 4.99733612e-02, -5.22711873e-02, -9.20209661e-03, -1.16479330e-01, 9.25614685e-02, -4.43541892e-02]]]], dtype=float32)> |
We will inform that mannequin.layers[0] is the proper layer by evaluating the identify conv2d from the above output to the output of mannequin.abstract(). This layer has a kernel of form (3, 3, 3, 32), that are respectively the peak, width, enter channels, and output characteristic maps.
Assume the kernel is a NumPy array okay. A convolutional layer will take its kernel okay[:, :, 0, n] (a 3×3 array) and apply on the primary channel of the picture. Then apply okay[:, :, 1, n] on the second channel of the picture, and so forth. Afterwards, the results of the convolution on all of the channels are added as much as develop into characteristic map n of output, which n on this case will run from 0 to 31 for the 32 output characteristic maps.
In Keras, we are able to extract the output of every layer utilizing an extractor mannequin. Within the following, we create a batch with one enter picture and ship to the community. Then we have a look at the characteristic maps of the primary convolutional layer:
|
... # Extract output from every layer extractor = tf.keras.Mannequin(inputs=mannequin.inputs, outputs=[layer.output for layer in model.layers]) options = extractor(np.expand_dims(X_train[7], 0))
# Present the 32 characteristic maps from the primary layer l0_features = options[0].numpy()[0]
fig, ax = plt.subplots(4, 8, sharex=True, sharey=True, figsize=(16,8)) for i in vary(0, 32): row, col = i//8, ipercent8 ax[row][col].imshow(l0_features[..., i])
plt.present() |
The above code will print the characteristic maps like the next: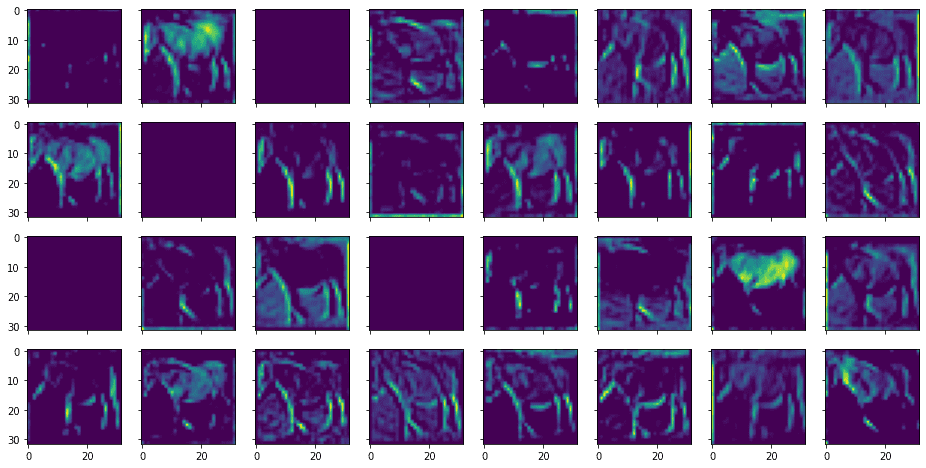
That is comparable to the next enter picture: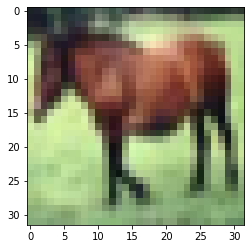
We will see that we name them the characteristic maps as a result of they’re highlighting sure options from the enter picture. A characteristic is recognized utilizing a small window (on this case, over a 3×3 pixels filter). The enter picture has 3 colour channels. Every channel has a special filter utilized, which their outcomes are mixed for an output characteristic.
We will equally show the characteristic map from the output of the second convolutional layer, as follows:
|
... # Present the 32 characteristic maps from the third layer l2_features = options[2].numpy()[0]
fig, ax = plt.subplots(4, 8, sharex=True, sharey=True, figsize=(16,8)) for i in vary(0, 32): row, col = i//8, ipercent8 ax[row][col].imshow(l2_features[..., i])
plt.present() |
Which exhibits the next: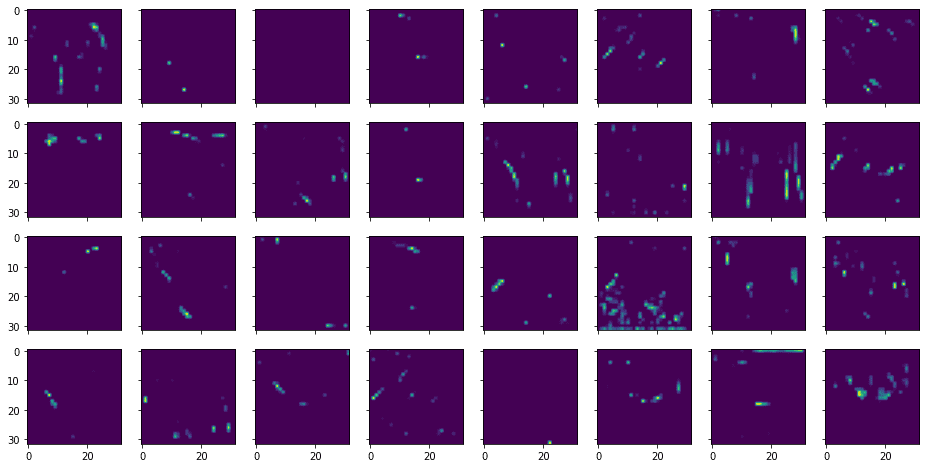
From the above, you’ll be able to see that the options extracted are extra summary and fewer recognizable.
Impact of the Convolutional Layers
An important hyperparameter to a convolutional layer is the dimensions of the filter. Often it’s in a sq. form and we are able to take into account that as a window or receptive area to take a look at the enter picture. Due to this fact, the upper decision of the picture, we’d anticipate a bigger filter.
However, a filter too massive will blur the detailed options as a result of all pixels from the receptive area by means of the filter will probably be mixed into one pixel on the output characteristic map. Due to this fact, there’s a commerce off for the suitable dimension of the filter.
Stacking two convolutional layers (with out some other layers in between) is equal to a single convolutional layer with bigger filter. However this can be a typical design these days to make use of two layers with small filters stacked collectively slightly than one bigger with bigger filter, as there are fewer parameters to coach.
The exception can be convolutional layer with 1×1 filter. It’s often discovered as the start layer of a community. The aim of such a convolutional layer is to mix the enter channels into one slightly than remodeling the pixels. Conceptually, this will convert a colour picture into grayscale, however often we make a number of methods of conversion to create extra enter channels than merely RGB for the community.
Additionally be aware that within the above community, we’re utilizing Conv2D, for a 2D filter. There may be additionally a Conv3D layer for a 3D filter. The distinction is whether or not we apply the filter individually for every channel or characteristic map, or to think about the enter characteristic maps stacked up as a 3D array and apply a single filter rework it altogether. Often the previous is used as it’s extra cheap to think about no specific order the characteristic maps ought to be stacked.
Additional Studying
This part gives extra assets on the subject in case you are seeking to go deeper.
Articles
Tutorials
Abstract
On this put up, you’ve seen how we are able to visualize the characteristic maps from a convolutional neural community and the way it works to extract the characteristic maps
Particularly, you discovered:
- The construction of a typical convolutional neural networks
- What’s the impact of the filter dimension to a convolutional layer
- What’s the impact of stacking convolutional layers in a community
Develop Deep Studying Tasks with Python!
What If You Might Develop A Community in Minutes
…with only a few strains of Python
Uncover how in my new E-book:
Deep Studying With Python
It covers end-to-end initiatives on matters like:
Multilayer Perceptrons, Convolutional Nets and Recurrent Neural Nets, and extra…
Lastly Convey Deep Studying To
Your Personal Tasks
Skip the Teachers. Simply Outcomes.
[ad_2]

