


[ad_1]
We’re excited to announce DataRobot’s integration with Apache Airflow, a preferred open supply orchestration device and workflow scheduler utilized by greater than 12,000 organizations* throughout industries like monetary providers, healthcare, retail, and manufacturing. Airflow is an ideal device to orchestrate levels of the DataRobot machine studying (ML) pipeline, as a result of it supplies a simple however highly effective answer to combine DataRobot capabilities into larger pipelines, mix it with different providers, in addition to to scrub your information, and retailer or publish the outcomes.
To put a robust basis for machine studying operations (MLOps) in your group, it’s important that you just set up a repeatable, reproducible, maintainable, and dependable ML workflow for coaching and deploying fashions and scoring predictions. Managing your ML pipeline with an orchestration answer like Apache Airflow makes it straightforward to observe, debug, and rerun the person levels of your workflow.
Combine DataRobot and Apache Airflow for Retraining and Redeploying Fashions
When mixed, the capabilities of DataRobot MLOps and Apache Airflow present a dependable answer for retraining and redeploying your fashions. You’ll be able to, for instance, retrain and redeploy your fashions on a schedule, on mannequin efficiency degradation, or utilizing a sensor that triggers the pipeline in presence of recent information. This sort of ML orchestration can present the best-informed predictions out of your group’s fashions, commonly skilled on the latest information.
This tutorial will clarify the DataRobot Airflow Supplier setup and configuration course of, serving to you implement an Apache Airflow DAG (Directed Acyclic Graph) to orchestrate an end-to-end DataRobot ML pipeline. This pipeline contains making a undertaking, coaching fashions, deploying a mannequin and scoring predictions.
In case you are new to working with DataRobot, you’re welcome to take a look at our documentation, the place you will discover the UI docs, API docs, and tutorials.
DataRobot Supplier Modules
There are a number of DataRobot operators and sensors that automate the DataRobot ML pipeline steps. Every operator initiates a selected job, and every sensor waits for a predetermined motion to finish:
| Operator | Job |
CreateProjectOperator |
Creates a DataRobot undertaking and returns its ID |
TrainModelsOperator |
Triggers DataRobot Autopilot to coach fashions |
DeployModelOperator |
Deploys a specified mannequin and returns the deployment ID |
DeployRecommendedModelOperator |
Deploys a really useful mannequin and returns the deployment ID |
ScorePredictionsOperator |
Scores predictions in opposition to the deployment and returns a batch prediction job ID |
AutopilotCompleteSensor |
Checks whether or not the Autopilot has accomplished |
ScoringCompleteSensor |
Checks whether or not batch scoring has accomplished |
Getting Began with DataRobot and Airflow
The DataRobot supplier for Apache Airflow is a Python package deal constructed from supply code obtainable in a public GitHub repository and revealed in PyPi (The Python Package deal Index). It’s also listed within the Astronomer Registry.
The combination makes use of the DataRobot Python API Consumer, which communicates with DataRobot cases through REST API. You’re welcome to take a look at the documentation to study extra about it.
For extra data on utilizing and creating suppliers packages, please verify the Apache Airflow documentation.
Pre-requisites
The DataRobot supplier for Apache Airflow requires an surroundings with the next dependencies put in:
On this tutorial, we’ll use the Astro CLI device to handle the native Airflow occasion. Ensure that to put in this command line device earlier than following the steps beneath:
curl -sSL https://set up.astronomer.io | sudo bash
Set up the supplier
First, we’ll create a brand new Airflow undertaking. For that, create a brand new listing and run the next command inside it to initialize the undertaking recordsdata:
astro dev init
Add the next to your necessities.txt file:
airflow-provider-datarobot
The instance DataRobot pipeline DAG doesn’t seem on the DAGs web page by default. To make it obtainable, obtain the DAG file from the repository to the dags/ listing in your undertaking (browse GitHub tags to obtain to the identical supply code model as your put in DataRobot supplier) and refresh the web page.
Run the next command to begin the Airflow occasion:
astro dev begin
As soon as the set up is full, it’s best to have the ability to entry Airflow (wait approx. 30 seconds for the online server to begin) and login with the default credentials (username: admin, password: admin):
The datarobot_pipeline DAG ought to seem on the DAGs web page:

Create a connection from Airflow to DataRobot
The following step is to create a connection from Airflow to DataRobot. Click on Admin > Connections, after which, on the Checklist Connection web page, click on Add a brand new file. Fill within the following fields:
The connection setup web page appears like this:

You’ll be able to take a look at the connection by clicking the Take a look at button. Then, click on the Save button.
Configuration
Every operator within the DataRobot pipeline requires particular parameters. We outline these parameters in a configuration JSON file and supply it when working the DAG.
The overall construction of the configuration is that this:
{
    "training_data": "",
    "project_name": "Challenge created from Airflow - Diabetes10k",
    "unsupervised_mode": false,
    "use_feature_discovery": false,
    "autopilot_settings": {
        "goal": "readmitted",
        "mode": "fast",
        "max_wait": 3600
    },
    "deployment_label": "Deployment from Airflow primarily based on diabetes10k",
    "deployment_description": "",
    "score_settings": {}
}
Values within the training_data and score_settings rely upon the consumption/output kind. We clarify the development of those settings within the sections beneath.
As all of the parameters from autopilot_settings are handed straight into the Challenge.set_target() technique, any parameter obtainable on this technique could also be set within the config.
Native file consumption/output
In case of the native file consumption, it’s best to present the trail to coaching information, e.g.:
"training_data": "embody/Diabetes10k.csv"And for the scoring settings, present the next:
    "score_settings": {
        "intake_settings": {
            "kind": "localFile",
            "file": "embody/Diabetes_scoring_data.csv"
        },
        "output_settings": {
            "kind": "localFile",
            "path": "embody/Diabetes_predictions.csv"
        }
    }
Because the parameters from score_settings are handed straight into the BatchPredictionJob.rating() technique, any parameter obtainable on this technique could also be set within the config.
When you’re utilizing the Astro CLI device to run Airflow, be certain to position the enter recordsdata within the embody/ listing which is accessible to the Airflow utility contained in the docker container.
Amazon AWS S3 consumption/output
In case of the S3 consumption, it’s good to generate a pre-signed URL for the coaching information file on S3:
- Within the S3 bucket, click on the csv file
- Click on Object Actions on the prime proper nook of the display and click on Share with a pre-signed URL.
- Set the expiration time interval and click on Create presigned URL. The URL is saved to your clipboard
- Paste the URL within the config file because the
training_dataworth.
For scoring information that’s on AWS S3, your AWS credentials should be added to DataRobot to attach together with your AWS account. It’s possible you’ll add your credentials utilizing the DataRobot Python API shopper:
import datarobot as dr

dr.shopper.Consumer(token="<your-api-token>", endpoint="https://app.datarobot.com/api/v2")

credential = dr.Credential.create_s3(
    title="My AWS credentials",
    aws_access_key_id="<aws_access_key_id>",
    aws_secret_access_key="<aws_secret_access_key>",
    aws_session_token="<aws_session_token>",
)
credential.credential_id
This credential entry seems within the DataRobot Credentials Administration web page (learn extra about credential administration in our platform docs).
Afterwards, it’s good to add the credential.credential_id worth each to intake_settings and output_settings within the config. As well as, it’s best to present the URLs for consumption and output places on S3:
    "score_settings": {
        "intake_settings": {
            "kind": "s3",
            "url": "s3://my-bucket-name/Diabetes1k.csv",
            "credential_id": "<worth from credential.credential_id>"
        },
        "output_settings": {
            "kind": "s3",
            "url": "s3://my-bucket-name/Diabetes1k_predictions.csv",
            "credential_id": "<worth from credential.credential_id>"
        }
    }
Run DataRobot Pipeline
After finishing all of the above setup, it’s best to have the ability to run the DataRobot Pipeline DAG following these steps:
- Copy the config file content material.
- On the Airflow DAGs web page, click on the run icon within the “datarobot_pipeline” entry and choose Set off DAG w/ config.
- Paste the config.
- Choose Unpause DAG when triggered.
- Click on Set off.
The graph view of the DAG appears like this:
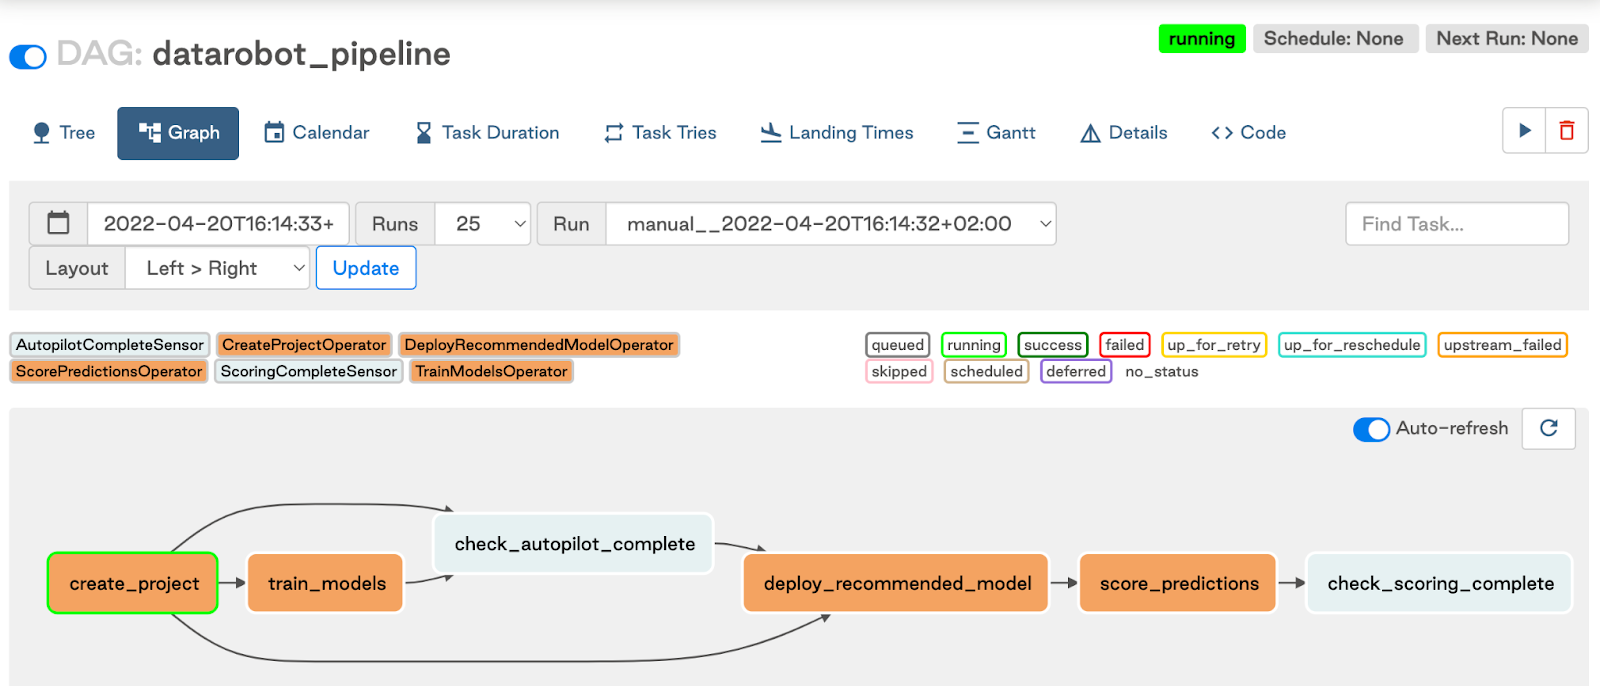
Notice: In case you are working Airflow in a Docker container (e.g., utilizing the Astro CLI device), count on the predictions file created contained in the container. To make the predictions obtainable within the host machine, specify the output location within the embody/ listing.
Getting Began with DataRobot and Airflow
DataRobot MLOps automates the capabilities to deploy, handle, monitor, and govern fashions in manufacturing environments. Orchestrating ML workflow takes it a step additional and permits combining the ML levels inside your information analytics pipeline, like information ingestion, information validation, information preparation, mannequin analysis, and many others.
DataRobot and Airflow are the proper tandem to attain this degree of automation in your group and have the very best MLOps expertise.
We encourage you to affix the discussions and put up questions on MLOPs orchestration within the DataRobot Neighborhood discussion board.
References
*HG Insights, Might 2022
In regards to the writer
Senior Software program Engineer, DataRobot
Andrius Senulis is a senior software program engineer with 9+ years of expertise within the IT trade, having labored in cybersecurity and AI corporations. Andrius joined DataRobot in 2019 and has labored on totally different groups and tasks within the firm, together with the COVID Simulator, Accomplice Integrations and Predictions.
[ad_2]

