

[ad_1]
Final Up to date on June 15, 2022
You’ve in all probability been instructed to standardize or normalize inputs to your mannequin to enhance efficiency. However what’s normalization and the way can we implement it simply in our deep studying fashions to enhance efficiency? Normalizing our inputs goals to create a set of options which can be on the identical scale as one another, which we’ll discover extra on this article.
Additionally, fascinated with it, in neural networks, the output of every layer serves because the inputs into the subsequent layer, so a pure query to ask is: If normalizing inputs to the mannequin helps enhance mannequin efficiency, does standardizing the inputs into every layer assist to enhance mannequin efficiency too?
The reply more often than not is sure! Nonetheless, not like normalizing our inputs to the mannequin as an entire, it’s barely extra difficult to normalize the inputs to intermediate layers because the activations are continuously altering. As such, it’s infeasible, or no less than, computationally costly to constantly compute statistics over the complete practice set again and again. On this article, we’ll be exploring normalization layers to normalize your inputs to your mannequin in addition to batch normalization, a way to standardize the inputs into every layer throughout batches.
Let’s get began!
Utilizing Normalization Layers to Enhance Deep Studying Fashions
Photograph by Matej. Some rights reserved.
Overview
This tutorial is break up into 6 elements; they’re:
- What’s normalization and why is it useful?
- Utilizing Normalization layer in TensorFlow
- What’s batch normalization and why ought to we use it?
- Batch normalization: Beneath the hood
- Normalization and Batch Normalization in Motion
What’s Normalization and Why is It Useful?
Normalizing a set of knowledge transforms the set of knowledge to be on an analogous scale. For machine studying fashions, our objective is often to recenter and rescale our information such that’s between 0 and 1 or -1 and 1, relying on the info itself. One widespread technique to accomplish that is to calculate the imply and the usual deviation on the set of knowledge and remodel every pattern by subtracting the imply and dividing by the usual deviation, which is nice if we assume that the info follows a standard distribution as this technique helps us standardize the info and obtain an ordinary regular distribution.
Normalization may also help coaching of our neural networks because the totally different options are on an analogous scale, which helps to stabilize the gradient descent step, permitting us to make use of bigger studying charges or assist fashions converge sooner for a given studying fee.
Utilizing Normalization Layer in Tensorflow
To normalize inputs in TensorFlow, we will use Normalization layer in Keras. First, let’s outline some pattern information,
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 |
sample1 = np.array([ [1, 1, 1], [1, 1, 1], [1, 1, 1] ], dtype=np.float32)
sample2 = np.array([ [2, 2, 2], [2, 2, 2], [2, 2, 2] ], dtype=np.float32)
sample3 = np.array([ [3, 3, 3], [3, 3, 3], [3, 3, 3] ], dtype=np.float32) |
Then we initialize our Normalization layer.
|
normalization_layer = Normalization() |
After which to get the imply and commonplace deviation of the dataset and set our Normalization layer to make use of these parameters, we will name Normalization.adapt() technique on our information.
|
combined_batch = tf.fixed(np.expand_dims(np.stack([sample1, sample2, sample3]), axis=–1), dtype=tf.float32)
normalization_layer = Normalization()
normalization_layer.adapt(combined_batch) |
For this case, we used expand_dims so as to add an additional dimension because the Normalization layer normalizes alongside the final dimension by default (every index within the final dimension will get its personal imply and variance parameters computed on the practice set) as that’s assumed to be the characteristic dimension, which for RGB pictures is often simply the totally different shade dimensions.
After which to normalize our information, we will name normalization layer on that information, as such:
|
normalization_layer(sample1) |
which provides the output
|
<tf.Tensor: form=(1, 1, 3, 3), dtype=float32, numpy= array([[[[–1.2247449, –1.2247449, –1.2247449], [–1.2247449, –1.2247449, –1.2247449], [–1.2247449, –1.2247449, –1.2247449]]]], dtype=float32)> |
And we will confirm that that is the anticipated conduct by working np.imply and np.std on our authentic information which provides us a imply of two.0 and an ordinary deviation of 0.8164966.
Now that we’ve seen the right way to normalize our inputs, let’s check out one other normalization technique, batch normalization.
What’s batch normalization and why ought to we use it?
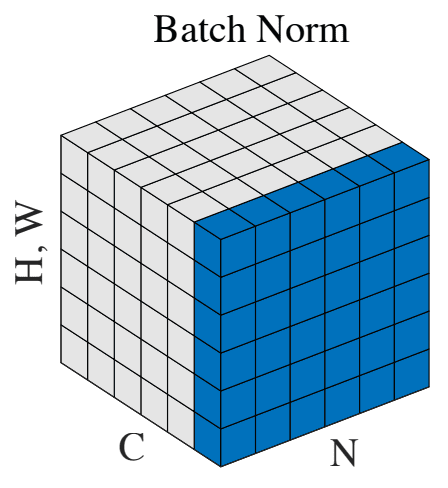
Supply: https://arxiv.org/pdf/1803.08494.pdf
From the title, you may in all probability guess that batch normalization will need to have one thing to do with batches throughout coaching. Merely put, batch normalization standardizes the enter of a layer throughout a single batch.
You could be considering, why can’t we simply calculate the imply and variance at a given layer and normalize it that manner? The issue comes after we practice our mannequin because the parameters change throughout coaching, therefore activations within the intermediate layers are continuously altering and calculating imply and variance throughout the complete coaching set for every iteration could be time consuming and probably pointless for the reason that activations are going to vary at every iteration anyway. That’s the place batch normalization is available in.
Launched in “Batch Normalization: Accelerating Deep Community Coaching by Decreasing Inside Covariate Shift” by Ioffe and Szegedy over at Google, batch normalization seems to be at standardizing the inputs to a layer with a purpose to scale back the issue of inner covariate shift. Within the paper, inner covariate shift is outlined as the issue of “the distribution of every layer’s inputs modifications throughout coaching, because the parameters of the earlier layers change.”
The thought of batch normalization fixing the issue of inner covariate shift has been disputed, notably in “How Does Batch Normalization Assist Optimization?” by Santurkar, et al. the place it was proposed that batch normalization helps to smoothen the loss perform over the parameter area as an alternative. Whereas it won’t all the time be clear how batch normalization does it, however it has achieved good empirical outcomes on many various issues and fashions.
There may be additionally some proof that batch normalization can contribute considerably to addressing the vanishing gradient drawback widespread with deep studying fashions. Within the authentic ResNet paper, He, et al. point out of their evaluation of ResNet vs plain networks that “backward propagated gradients exhibit wholesome norms with BN (batch normalization)” even in plain networks.
It has additionally been advised that batch normalization has different advantages as nicely equivalent to permitting us to make use of increased studying charges as batch normalization may also help to stabilize parameter development. It may possibly additionally assist to regularize the mannequin. From the unique batch normalization paper,
“When coaching with Batch Normalization, a coaching instance is seen at the side of different examples within the mini-batch, and the coaching community now not producing deterministic values for a given coaching instance In our experiments, we discovered this impact to be advantageous to the generalization of the community”
Batch Normalization: Beneath the Hood
So, what does batch normalization really do?
First, we have to calculate batch statistics, specifically, the imply and variance for every of the totally different activations throughout a batch. Since every layer’s output serves as an enter into the subsequent layer in a neural community, by standardizing the output of the layers, we’re additionally standardizing the inputs to the subsequent layer in our mannequin (although in apply, it was advised within the authentic paper to implement batch normalization earlier than the activation perform, nevertheless there’s some debate over this).
So, we calculate
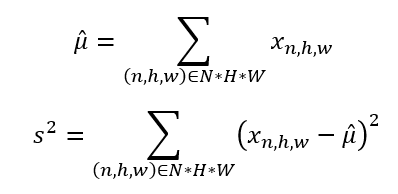
Pattern imply and variance on batch
Then, for every of the activation maps, we normalization every worth utilizing the respective statistics
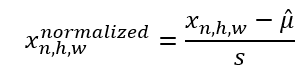
For Convolutional Neural Networks (CNNs) specifically, we calculate these statistics over all places of the identical channel. From the unique bathtub normalization paper,
“For convolutional layers, we moreover need the normalization to obey the convolutional property – in order that totally different parts of the identical characteristic map, at totally different places, are normalized in the identical manner”
Now that we’ve seen the right way to calculate the normalized activation maps, let’s discover how this may be carried out utilizing Numpy arrays.
Suppose we had these activation maps with all of them representing a single channel,
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 |
import numpy as np
activation_map_sample1 = np.array([ [1, 1, 1], [1, 1, 1], [1, 1, 1] ], dtype=np.float32)
activation_map_sample2 = np.array([ [1, 2, 3], [4, 5, 6], [7, 8, 9] ], dtype=np.float32)
activation_map_sample3 = np.array([ [9, 8, 7], [6, 5, 4], [3, 2, 1] ], dtype=np.float32) |
Then, we need to standardize every factor within the activation map throughout all places and throughout the totally different samples. To standardize, we compute their imply and commonplace deviation utilizing
|
#get imply throughout the totally different samples in batch for every activation activation_mean_bn = np.imply([activation_map_sample1, activation_map_sample2, activation_map_sample3], axis=0)
#get commonplace deviation throughout totally different samples in batch for every activation activation_std_bn = np.std([activation_map_sample1, activation_map_sample2, activation_map_sample3], axis=0)
print (activation_mean_bn) print (activation_std_bn) |
which outputs
Then, we will standardize an activation map by doing
|
#get batch normalized activation map for pattern 1 activation_map_sample1_bn = (activation_map_sample1 – activation_mean_bn) / activation_std_bn |
and these retailer the outputs
|
activation_map_sample1_bn: [[–0.94280916 –0.94280916 –0.94280916] [–0.94280916 –0.94280916 –0.94280916] [–0.94280916 –0.94280916 –0.94280916]]
activation_map_sample2_bn: [[–0.94280916 –0.58925575 –0.2357023 ] [ 0.11785112 0.47140455 0.82495797] [ 1.1785114 1.5320647 1.8856182 ]]
activation_map_sample3_bn: [[ 1.8856182 1.5320647 1.1785114 ] [ 0.82495797 0.47140455 0.11785112] [–0.2357023 –0.58925575 –0.94280916]] |
However we hit a snag in the case of inference time. What if we don’t have batches of examples at inference time and even when we did, it might nonetheless be preferable if the output is computed from the enter deterministically. So, we have to calculate a set set of parameters for use at inference time. For this objective, we retailer a shifting common for the means and variances as an alternative which we use at inference time to compute the outputs of the layers.
Nonetheless, one other drawback with merely standardizing the inputs to a mannequin on this manner additionally modifications the representational capacity of the layers. One instance introduced up within the batch normalization paper was the sigmoid nonlinear perform, the place normalizing the inputs would constrain it to the linear regime of the sigmoid perform. To deal with this, one other linear layer is added to scale and recenter the values, together with 2 trainable parameters to study the suitable scale and heart that needs to be used.
Implementing Batch Normalization in TensorFlow
Now that we perceive what goes on with batch normalization below the hood, let’s see how we will use Keras’ batch normalization layer as a part of our deep studying fashions.
To implement batch normalization as a part of our deep studying fashions in Tensorflow, we will use the keras.layers.BatchNormalization layer. Utilizing the Numpy arrays from our earlier instance, we will implement the BatchNormalization on them.
|
import tensorflow as tf import tensorflow.keras as keras from tensorflow.keras.layers import BatchNormalization import numpy as np
#develop dims to create the channels activation_maps = tf.fixed(np.expand_dims(np.stack([activation_map_sample1, activation_map_sample2, activation_map_sample3]), axis=0), dtype=tf.float32)
print (f“activation_maps: n{activation_maps}n”)
print (BatchNormalization(axis=0)(activation_maps, coaching=True)) |
which provides us the output
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 |
activation_maps: [[[[1. 1. 1.] [1. 1. 1.] [1. 1. 1.]]
[[1. 2. 3.] [4. 5. 6.] [7. 8. 9.]]
[[9. 8. 7.] [6. 5. 4.] [3. 2. 1.]]]]
tf.Tensor( [[[[–0.9427501 –0.9427501 –0.9427501 ] [–0.9427501 –0.9427501 –0.9427501 ] [–0.9427501 –0.9427501 –0.9427501 ]]
[[–0.9427501 –0.5892188 –0.2356875 ] [ 0.11784375 0.471375 0.82490635] [ 1.1784375 1.5319688 1.8855002 ]]
[[ 1.8855002 1.5319688 1.1784375 ] [ 0.82490635 0.471375 0.11784375] [–0.2356875 –0.5892188 –0.9427501 ]]]], form=(1, 3, 3, 3), dtype=float32) |
By default, the BatchNormalization layer makes use of a scale of 1 and heart of 0 for the linear layer, therefore these values are much like the values that we computed earlier utilizing Numpy features.
Normalization and Batch Normalization in Motion
Now that we’ve seen the right way to implement the normalization and batch normalization layers in Tensorflow, let’s discover a LeNet-5 mannequin that makes use of the normalization and batch normalization layers, in addition to evaluate it to a mannequin that doesn’t use both of those layers.
First, let’s get our dataset, we’ll use CIFAR-10 for this instance.
|
(trainX, trainY), (testX, testY) = keras.datasets.cifar10.load_data() |
Utilizing a LeNet-5 mannequin with ReLU activation,
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 |
from tensorflow.keras.layers import Dense, Enter, Flatten, Conv2D, MaxPool2D from tensorflow.keras.fashions import Mannequin import tensorflow as tf
class LeNet5(tf.keras.Mannequin): def __init__(self): tremendous(LeNet5, self).__init__() def name(self, input_tensor): self.conv1 = Conv2D(filters=6, kernel_size=(5,5), padding=“identical”, activation=“relu”)(input_tensor) self.maxpool1 = MaxPool2D(pool_size=(2,2))(self.conv1) self.conv2 = Conv2D(filters=16, kernel_size=(5,5), padding=“identical”, activation=“relu”)(self.maxpool1) self.maxpool2 = MaxPool2D(pool_size=(2, 2))(self.conv2) self.flatten = Flatten()(self.maxpool2) self.fc1 = Dense(items=120, activation=“relu”)(self.flatten) self.fc2 = Dense(items=84, activation=“relu”)(self.fc1) self.fc3 = Dense(items=10, activation=“sigmoid”)(self.fc2) return self.fc3
input_layer = Enter(form=(32,32,3,)) x = LeNet5()(input_layer)
mannequin = Mannequin(inputs=input_layer, outputs=x)
mannequin.compile(optimizer=“adam”, loss=tf.keras.losses.SparseCategoricalCrossentropy(), metrics=“acc”)
historical past = mannequin.match(x=trainX, y=trainY, batch_size=256, epochs=10, validation_data=(testX, testY)) |
Coaching the mannequin offers us the output,
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 |
Epoch 1/10 196/196 [==============================] – 14s 15ms/step – loss: 3.8905 – acc: 0.2172 – val_loss: 1.9656 – val_acc: 0.2853 Epoch 2/10 196/196 [==============================] – 2s 12ms/step – loss: 1.8402 – acc: 0.3375 – val_loss: 1.7654 – val_acc: 0.3678 Epoch 3/10 196/196 [==============================] – 2s 12ms/step – loss: 1.6778 – acc: 0.3986 – val_loss: 1.6484 – val_acc: 0.4039 Epoch 4/10 196/196 [==============================] – 2s 12ms/step – loss: 1.5663 – acc: 0.4355 – val_loss: 1.5644 – val_acc: 0.4380 Epoch 5/10 196/196 [==============================] – 2s 12ms/step – loss: 1.4815 – acc: 0.4712 – val_loss: 1.5357 – val_acc: 0.4472 Epoch 6/10 196/196 [==============================] – 2s 12ms/step – loss: 1.4053 – acc: 0.4975 – val_loss: 1.4883 – val_acc: 0.4675 Epoch 7/10 196/196 [==============================] – 2s 12ms/step – loss: 1.3300 – acc: 0.5262 – val_loss: 1.4643 – val_acc: 0.4805 Epoch 8/10 196/196 [==============================] – 2s 12ms/step – loss: 1.2595 – acc: 0.5531 – val_loss: 1.4685 – val_acc: 0.4866 Epoch 9/10 196/196 [==============================] – 2s 12ms/step – loss: 1.1999 – acc: 0.5752 – val_loss: 1.4302 – val_acc: 0.5026 Epoch 10/10 196/196 [==============================] – 2s 12ms/step – loss: 1.1370 – acc: 0.5979 – val_loss: 1.4441 – val_acc: 0.5009 |
Subsequent, let’s check out what occurs if we added normalization and batch normalization layers. We often add layer normalization. Amending our LeNet-5 mannequin,
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 |
class LeNet5_Norm(tf.keras.Mannequin): def __init__(self, norm_layer, *args, **kwargs): tremendous(LeNet5_Norm, self).__init__() self.conv1 = Conv2D(filters=6, kernel_size=(5,5), padding=“identical”) self.norm1 = norm_layer(*args, **kwargs) self.relu = relu self.max_pool2x2 = MaxPool2D(pool_size=(2,2)) self.conv2 = Conv2D(filters=16, kernel_size=(5,5), padding=“identical”) self.norm2 = norm_layer(*args, **kwargs) self.flatten = Flatten() self.fc1 = Dense(items=120) self.norm3 = norm_layer(*args, **kwargs) self.fc2 = Dense(items=84) self.norm4 = norm_layer(*args, **kwargs) self.fc3 = Dense(items=10, activation=“softmax”) def name(self, input_tensor): conv1 = self.conv1(input_tensor) conv1 = self.norm1(conv1) conv1 = self.relu(conv1) maxpool1 = self.max_pool2x2(conv1) conv2 = self.conv2(maxpool1) conv2 = self.norm2(conv2) conv2 = self.relu(conv2) maxpool2 = self.max_pool2x2(conv2) flatten = self.flatten(maxpool2) fc1 = self.fc1(flatten) fc1 = self.norm3(fc1) fc1 = self.relu(fc1) fc2 = self.fc2(fc1) fc2 = self.norm4(fc2) fc2 = self.relu(fc2) fc3 = self.fc3(fc2) return fc3 |
And working the coaching once more, this time with the normalization layer added.
|
normalization_layer = Normalization() normalization_layer.adapt(trainX)
input_layer = Enter(form=(32,32,3,)) x = LeNet5_Norm(BatchNormalization)(normalization_layer(input_layer))
mannequin = Mannequin(inputs=input_layer, outputs=x)
mannequin.compile(optimizer=“adam”, loss=tf.keras.losses.SparseCategoricalCrossentropy(), metrics=“acc”)
historical past = mannequin.match(x=trainX, y=trainY, batch_size=256, epochs=10, validation_data=(testX, testY)) |
And we see that the mannequin converges sooner and will get a better validation accuracy.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 |
Epoch 1/10 196/196 [==============================] – 5s 17ms/step – loss: 1.4643 – acc: 0.4791 – val_loss: 1.3837 – val_acc: 0.5054 Epoch 2/10 196/196 [==============================] – 3s 14ms/step – loss: 1.1171 – acc: 0.6041 – val_loss: 1.2150 – val_acc: 0.5683 Epoch 3/10 196/196 [==============================] – 3s 14ms/step – loss: 0.9627 – acc: 0.6606 – val_loss: 1.1038 – val_acc: 0.6086 Epoch 4/10 196/196 [==============================] – 3s 14ms/step – loss: 0.8560 – acc: 0.7003 – val_loss: 1.0976 – val_acc: 0.6229 Epoch 5/10 196/196 [==============================] – 3s 14ms/step – loss: 0.7644 – acc: 0.7325 – val_loss: 1.1073 – val_acc: 0.6153 Epoch 6/10 196/196 [==============================] – 3s 15ms/step – loss: 0.6872 – acc: 0.7617 – val_loss: 1.1484 – val_acc: 0.6128 Epoch 7/10 196/196 [==============================] – 3s 14ms/step – loss: 0.6229 – acc: 0.7850 – val_loss: 1.1469 – val_acc: 0.6346 Epoch 8/10 196/196 [==============================] – 3s 14ms/step – loss: 0.5583 – acc: 0.8067 – val_loss: 1.2041 – val_acc: 0.6206 Epoch 9/10 196/196 [==============================] – 3s 15ms/step – loss: 0.4998 – acc: 0.8300 – val_loss: 1.3095 – val_acc: 0.6071 Epoch 10/10 196/196 [==============================] – 3s 14ms/step – loss: 0.4474 – acc: 0.8471 – val_loss: 1.2649 – val_acc: 0.6177 |
Plotting the practice and validation accuracies of each fashions,

Practice and validation accuracy of LeNet-5
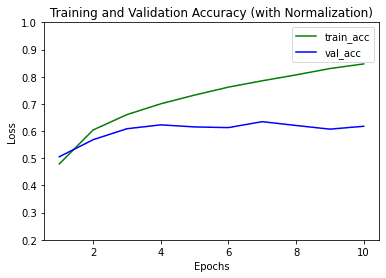
Practice and validation accuracy of LeNet-5 with normalization and batch normalization added
Some warning when utilizing batch normalization, it’s usually not suggested to make use of batch normalization along with dropout as batch normalization has a regularizing impact. Additionally, too small batch sizes could be a difficulty for batch normalization as the standard of the statistics (imply and variance) calculated is affected by the batch measurement and really small batch sizes might result in points, with the acute case being one pattern have all activations as 0 if easy neural networks. Think about using layer normalization (extra assets in additional studying part beneath) in case you are contemplating utilizing small batch sizes.
Right here’s the entire code for the mannequin with normalization too.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 |
from tensorflow.keras.layers import Dense, Enter, Flatten, Conv2D, BatchNormalization, MaxPool2D, Normalization from tensorflow.keras.fashions import Mannequin import tensorflow as tf import tensorflow.keras as keras
class LeNet5_Norm(tf.keras.Mannequin): def __init__(self, norm_layer, *args, **kwargs): tremendous(LeNet5_Norm, self).__init__() self.conv1 = Conv2D(filters=6, kernel_size=(5,5), padding=“identical”) self.norm1 = norm_layer(*args, **kwargs) self.relu = relu self.max_pool2x2 = MaxPool2D(pool_size=(2,2)) self.conv2 = Conv2D(filters=16, kernel_size=(5,5), padding=“identical”) self.norm2 = norm_layer(*args, **kwargs) self.flatten = Flatten() self.fc1 = Dense(items=120) self.norm3 = norm_layer(*args, **kwargs) self.fc2 = Dense(items=84) self.norm4 = norm_layer(*args, **kwargs) self.fc3 = Dense(items=10, activation=“softmax”) def name(self, input_tensor): conv1 = self.conv1(input_tensor) conv1 = self.norm1(conv1) conv1 = self.relu(conv1) maxpool1 = self.max_pool2x2(conv1) conv2 = self.conv2(maxpool1) conv2 = self.norm2(conv2) conv2 = self.relu(conv2) maxpool2 = self.max_pool2x2(conv2) flatten = self.flatten(maxpool2) fc1 = self.fc1(flatten) fc1 = self.norm3(fc1) fc1 = self.relu(fc1) fc2 = self.fc2(fc1) fc2 = self.norm4(fc2) fc2 = self.relu(fc2) fc3 = self.fc3(fc2) return fc3
# load dataset, utilizing cifar10 to point out higher enchancment in accuracy (trainX, trainY), (testX, testY) = keras.datasets.cifar10.load_data()
normalization_layer = Normalization() normalization_layer.adapt(trainX)
input_layer = Enter(form=(32,32,3,)) x = LeNet5_Norm(BatchNormalization)(normalization_layer(input_layer))
mannequin = Mannequin(inputs=input_layer, outputs=x)
mannequin.compile(optimizer=“adam”, loss=tf.keras.losses.SparseCategoricalCrossentropy(), metrics=“acc”)
historical past = mannequin.match(x=trainX, y=trainY, batch_size=256, epochs=10, validation_data=(testX, testY)) |
Additional Studying
Listed below are a number of the several types of normalization which you could implement in your mannequin:
Tensorflow layers:
Conclusion
On this put up, you’ve found how normalization and batch normalization works, in addition to the right way to implement them in TensorFlow. You will have additionally seen how utilizing these layers may also help to considerably enhance the efficiency of our machine studying fashions.
Particularly, you’ve discovered:
- What normalization and batch normalization does
- The right way to use normalization and batch normalization in TensorFlow
- Some suggestions when utilizing batch normalization in your machine studying mannequin
Develop Deep Studying Tasks with Python!
What If You May Develop A Community in Minutes
…with only a few strains of Python
Uncover how in my new E book:
Deep Studying With Python
It covers end-to-end tasks on subjects like:
Multilayer Perceptrons, Convolutional Nets and Recurrent Neural Nets, and extra…
Lastly Deliver Deep Studying To
Your Personal Tasks
Skip the Teachers. Simply Outcomes.
Develop Higher Deep Studying Fashions At this time!
Practice Quicker, Cut back Overftting, and Ensembles
…with only a few strains of python code
Uncover how in my new E book:
Higher Deep Studying
It offers self-study tutorials on subjects like:
weight decay, batch normalization, dropout, mannequin stacking and way more…
Deliver higher deep studying to your tasks!
Skip the Teachers. Simply Outcomes.
[ad_2]

