



[ad_1]
When individuals converse with each other, context and references play a crucial function in driving their dialog extra effectively. For example, if one asks the query “Who wrote Romeo and Juliet?” and, after receiving a solution, asks “The place was he born?”, it’s clear that ‘he’ is referring to William Shakespeare with out the necessity to explicitly point out him. Or if somebody mentions “python” in a sentence, one can use the context from the dialog to find out whether or not they’re referring to a kind of snake or a pc language. If a digital assistant can not robustly deal with context and references, customers could be required to adapt to the limitation of the know-how by repeating beforehand shared contextual data of their follow-up queries to make sure that the assistant understands their requests and might present related solutions.
On this publish, we current a know-how at the moment deployed on Google Assistant that permits customers to talk in a pure method when referencing context that was outlined in earlier queries and solutions. The know-how, based mostly on the newest machine studying (ML) advances, rephrases a consumer’s follow-up question to explicitly point out the lacking contextual data, thus enabling it to be answered as a stand-alone question. Whereas Assistant considers many sorts of context for decoding the consumer enter, on this publish we’re specializing in short-term dialog historical past.
Context Dealing with by Rephrasing
One of many approaches taken by Assistant to know contextual queries is to detect if an enter utterance is referring to earlier context after which rephrase it internally to explicitly embrace the lacking data. Following on from the earlier instance through which the consumer requested who wrote Romeo and Juliet, one could ask follow-up questions like “When?”. Assistant acknowledges that this query is referring to each the topic (Romeo and Juliet) and reply from the earlier question (William Shakespeare) and might rephrase “When?” to “When did William Shakespeare write Romeo and Juliet?”
Whereas there are different methods to deal with context, as an example, by making use of guidelines on to symbolic representations of the that means of queries, like intents and arguments, the benefit of the rephrasing method is that it operates horizontally on the string degree throughout any question answering, parsing, or motion success module.
 |
| Dialog on a wise show machine, the place Assistant understands a number of contextual follow-up queries, permitting the consumer to have a extra pure dialog. The phrases showing on the backside of the show are strategies for follow-up questions that the consumer can choose. Nonetheless, the consumer can nonetheless ask totally different questions. |
A Vast Number of Contextual Queries
The pure language processing subject, historically, has not put a lot emphasis on a basic method to context, specializing in the understanding of stand-alone queries which might be absolutely specified. Precisely incorporating context is a difficult downside, particularly when contemplating the big number of contextual question sorts. The desk under incorporates instance conversations that illustrate question variability and a few of the many contextual challenges that Assistant’s rephrasing technique can resolve (e.g., differentiating between referential and non-referential circumstances or figuring out what context a question is referencing). We show how Assistant is now in a position to rephrase follow-up queries, including contextual data earlier than offering a solution.
 |
System Structure
At a excessive degree, the rephrasing system generates rephrasing candidates through the use of various kinds of candidate turbines. Every rephrasing candidate is then scored based mostly on plenty of indicators, and the one with the best rating is chosen.
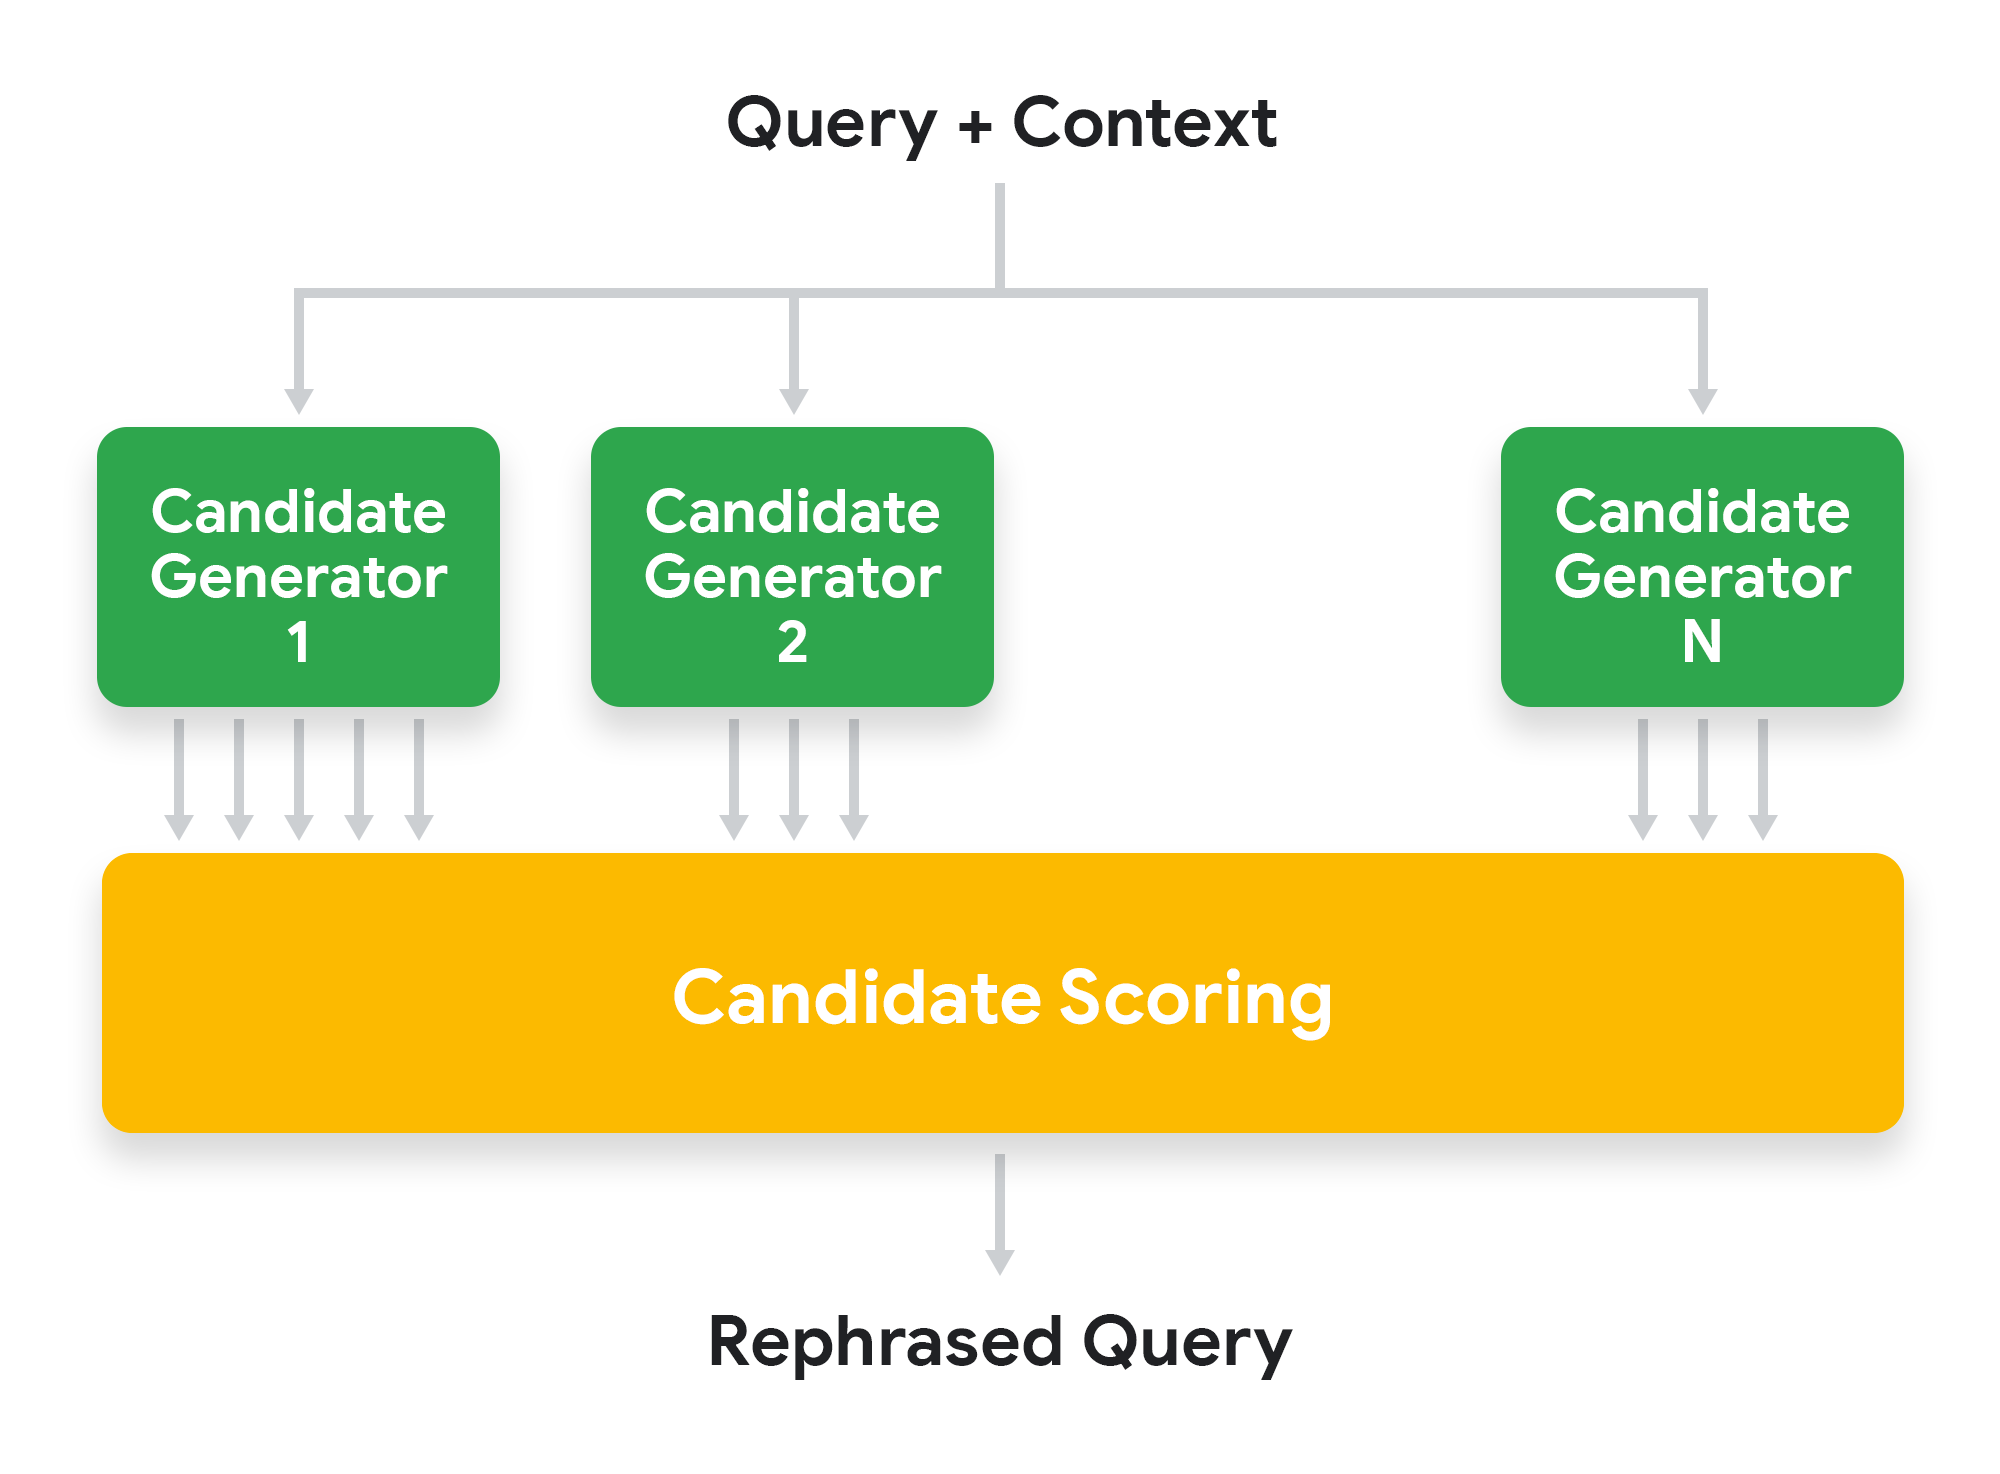 |
| Excessive degree structure of Google Assistant contextual rephraser. |
Candidate Technology
To generate rephrasing candidates we use a hybrid method that applies totally different methods, which we classify into three classes:
- Mills based mostly on the evaluation of the linguistic construction of the queries use grammatical and morphological guidelines to carry out particular operations — as an example, the alternative of pronouns or different sorts of referential phrases with antecedents from the context.
- Mills based mostly on question statistics mix key phrases from the present question and its context to create candidates that match common queries from historic information or widespread question patterns.
- Mills based mostly on Transformer applied sciences, reminiscent of MUM, study to generate sequences of phrases based on plenty of coaching samples. LaserTagger and FELIX are applied sciences appropriate for duties with excessive overlap between the enter and output texts, are very quick at inference time, and are usually not susceptible to hallucination (i.e., producing textual content that isn’t associated to the enter texts). As soon as offered with a question and its context, they’ll generate a sequence of textual content edits to remodel the enter queries right into a rephrasing candidate by indicating which parts of the context needs to be preserved and which phrases needs to be modified.
Candidate Scoring
We extract plenty of indicators for every rephrasing candidate and use an ML mannequin to pick essentially the most promising candidate. Among the indicators rely solely on the present question and its context. For instance, is the subject of the present question just like the subject of the earlier question? Or, is the present question a superb stand-alone question or does it look incomplete? Different indicators rely on the candidate itself: How a lot of the knowledge of the context does the candidate protect? Is the candidate well-formed from a linguistic perspective? And many others.
Just lately, new indicators generated by BERT and MUM fashions have considerably improved the efficiency of the ranker, fixing about one-third of the recall headroom whereas minimizing false positives on question sequences that aren’t contextual (and subsequently don’t require a rephrasing).
 |
| Instance dialog on a telephone the place Assistant understands a sequence of contextual queries. |
Conclusion
The answer described right here makes an attempt to resolve contextual queries by rephrasing them in an effort to make them absolutely answerable in a stand-alone method, i.e., with out having to narrate to different data in the course of the success section. The advantage of this method is that it’s agnostic to the mechanisms that might fulfill the question, thus making it usable as a horizontal layer to be deployed earlier than any additional processing.
Given the number of contexts naturally utilized in human languages, we adopted a hybrid method that mixes linguistic guidelines, massive quantities of historic information by way of logs, and ML fashions based mostly on state-of-the-art Transformer approaches. By producing plenty of rephrasing candidates for every question and its context, after which scoring and rating them utilizing quite a lot of indicators, Assistant can rephrase and thus appropriately interpret most contextual queries. As Assistant can deal with most sorts of linguistic references, we’re empowering customers to have extra pure conversations. To make such multi-turn conversations even much less cumbersome, Assistant customers can activate Continued Dialog mode to allow asking follow-up queries with out the necessity to repeat “Hey Google” between every question. We’re additionally utilizing this know-how in different digital assistant settings, as an example, decoding context from one thing proven on a display screen or taking part in on a speaker.
Acknowledgements
This publish displays the mixed work of Aliaksei Severyn, André Farias, Cheng-Chun Lee, Florian Thöle, Gabriel Carvajal, Gyorgy Gyepesi, Julien Cretin, Liana Marinescu, Martin Bölle, Patrick Siegler, Sebastian Krause, Victor Ähdel, Victoria Fossum, Vincent Zhao. We additionally thank Amar Subramanya, Dave Orr, Yury Pinsky for useful discussions and help.
[ad_2]

