


[ad_1]
People observe the world by way of a mixture of various modalities, like imaginative and prescient, listening to, and our understanding of language. Machines, however, interpret the world by way of information that algorithms can course of.
So, when a machine “sees” a photograph, it should encode that photograph into information it might probably use to carry out a activity like picture classification. This course of turns into extra sophisticated when inputs are available a number of codecs, like movies, audio clips, and pictures.
“The principle problem right here is, how can a machine align these totally different modalities? As people, that is simple for us. We see a automotive after which hear the sound of a automotive driving by, and we all know these are the identical factor. However for machine studying, it isn’t that simple,” says Alexander Liu, a graduate pupil within the Pc Science and Synthetic Intelligence Laboratory (CSAIL) and first writer of a paper tackling this downside.
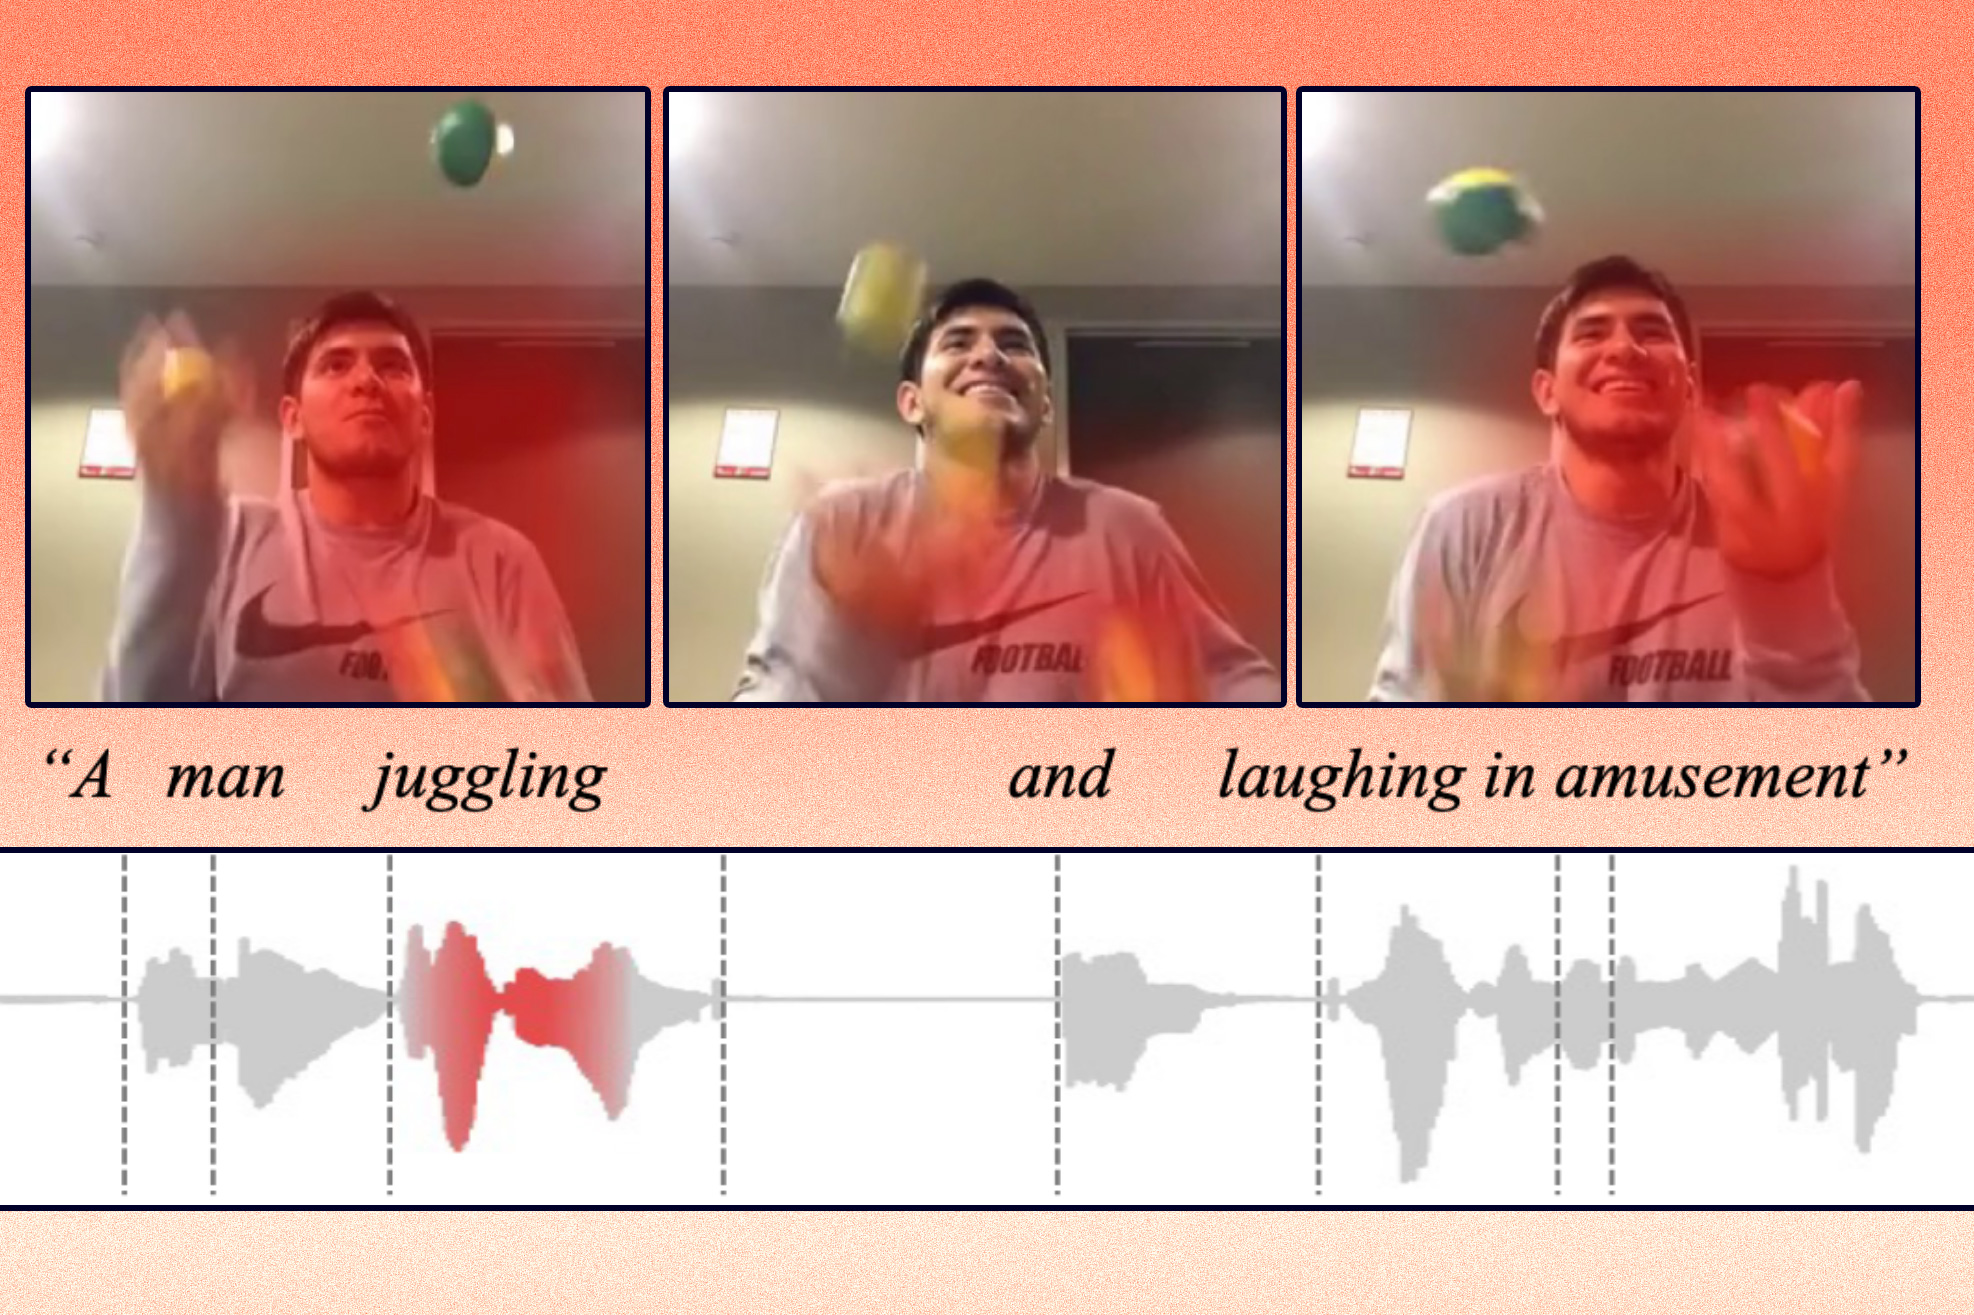
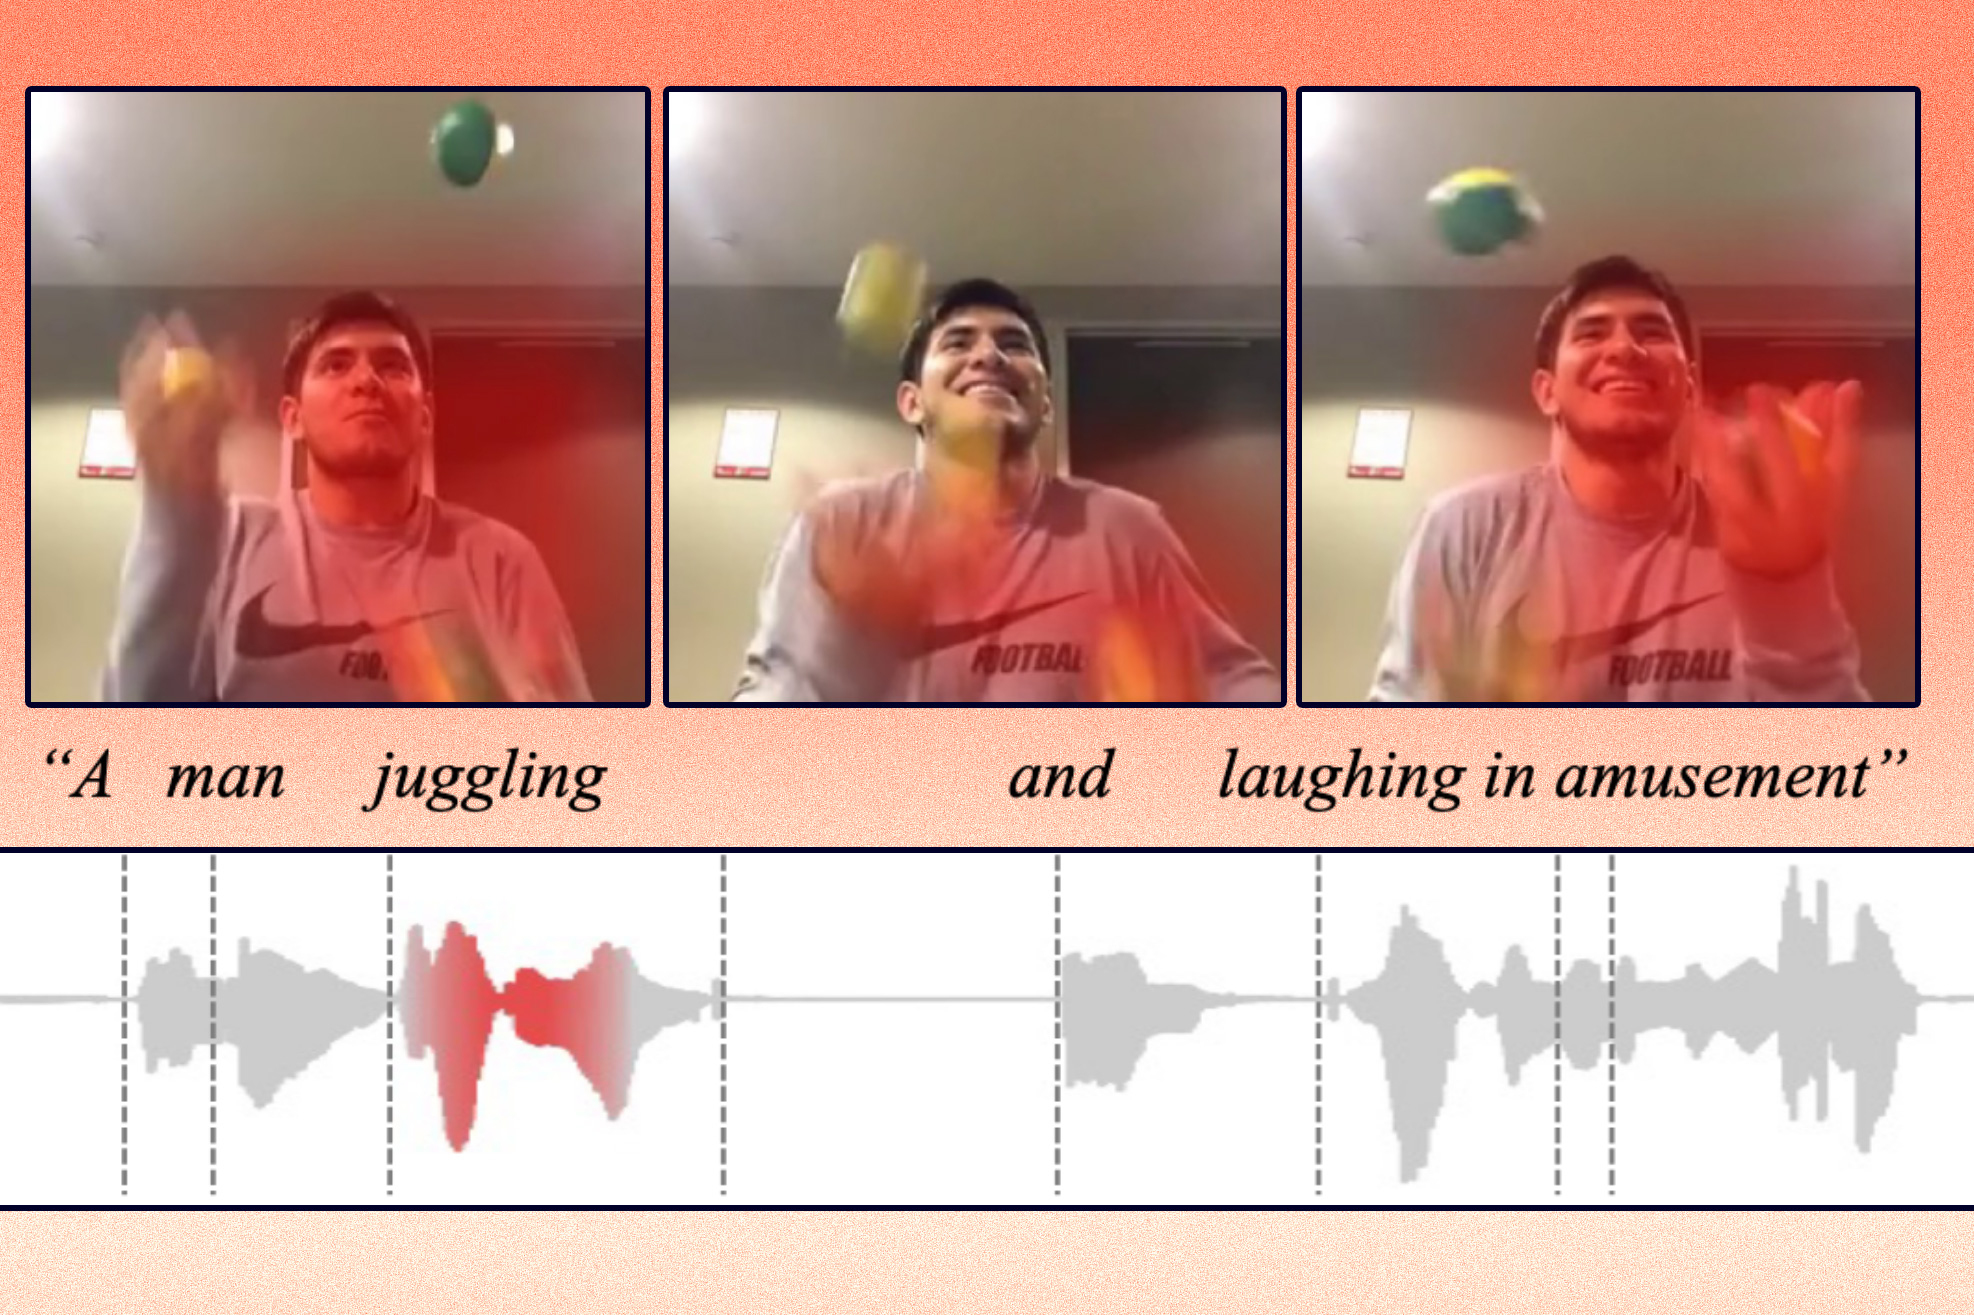
Liu and his collaborators developed a man-made intelligence method that learns to signify information in a means that captures ideas that are shared between visible and audio modalities. As an example, their methodology can study that the motion of a child crying in a video is said to the spoken phrase “crying” in an audio clip.
Utilizing this data, their machine-learning mannequin can determine the place a sure motion is going down in a video and label it.
It performs higher than different machine-learning strategies at cross-modal retrieval duties, which contain discovering a chunk of information, like a video, that matches a person’s question given in one other type, like spoken language. Their mannequin additionally makes it simpler for customers to see why the machine thinks the video it retrieved matches their question.
This method might sometime be utilized to assist robots study ideas on this planet by way of notion, extra like the way in which people do.
Becoming a member of Liu on the paper are CSAIL postdoc SouYoung Jin; grad college students Cheng-I Jeff Lai and Andrew Rouditchenko; Aude Oliva, senior analysis scientist in CSAIL and MIT director of the MIT-IBM Watson AI Lab; and senior writer James Glass, senior analysis scientist and head of the Spoken Language Methods Group in CSAIL. The analysis shall be introduced on the Annual Assembly of the Affiliation for Computational Linguistics.
Studying representations
The researchers focus their work on illustration studying, which is a type of machine studying that seeks to remodel enter information to make it simpler to carry out a activity like classification or prediction.
The illustration studying mannequin takes uncooked information, corresponding to movies and their corresponding textual content captions, and encodes them by extracting options, or observations about objects and actions within the video. Then it maps these information factors in a grid, often known as an embedding area. The mannequin clusters related information collectively as single factors within the grid. Every of those information factors, or vectors, is represented by a person phrase.
As an example, a video clip of an individual juggling is likely to be mapped to a vector labeled “juggling.”
The researchers constrain the mannequin so it might probably solely use 1,000 phrases to label vectors. The mannequin can determine which actions or ideas it desires to encode right into a single vector, however it might probably solely use 1,000 vectors. The mannequin chooses the phrases it thinks finest signify the information.
Moderately than encoding information from totally different modalities onto separate grids, their methodology employs a shared embedding area the place two modalities might be encoded collectively. This permits the mannequin to study the connection between representations from two modalities, like video that exhibits an individual juggling and an audio recording of somebody saying “juggling.”
To assist the system course of information from a number of modalities, they designed an algorithm that guides the machine to encode related ideas into the identical vector.
“If there’s a video about pigs, the mannequin would possibly assign the phrase ‘pig’ to one of many 1,000 vectors. Then if the mannequin hears somebody saying the phrase ‘pig’ in an audio clip, it ought to nonetheless use the identical vector to encode that,” Liu explains.
A greater retriever
They examined the mannequin on cross-modal retrieval duties utilizing three datasets: a video-text dataset with video clips and textual content captions, a video-audio dataset with video clips and spoken audio captions, and an image-audio dataset with photos and spoken audio captions.
For instance, within the video-audio dataset, the mannequin selected 1,000 phrases to signify the actions within the movies. Then, when the researchers fed it audio queries, the mannequin tried to search out the clip that finest matched these spoken phrases.
“Identical to a Google search, you kind in some textual content and the machine tries to let you know probably the most related issues you might be trying to find. Solely we do that within the vector area,” Liu says.
Not solely was their method extra more likely to discover higher matches than the fashions they in contrast it to, additionally it is simpler to know.
As a result of the mannequin might solely use 1,000 whole phrases to label vectors, a person can extra see simply which phrases the machine used to conclude that the video and spoken phrases are related. This might make the mannequin simpler to use in real-world conditions the place it’s vital that customers perceive the way it makes selections, Liu says.
The mannequin nonetheless has some limitations they hope to handle in future work. For one, their analysis targeted on information from two modalities at a time, however in the actual world people encounter many information modalities concurrently, Liu says.
“And we all know 1,000 phrases works on this type of dataset, however we don’t know if it may be generalized to a real-world downside,” he provides.
Plus, the photographs and movies of their datasets contained easy objects or easy actions; real-world information are a lot messier. Additionally they need to decide how nicely their methodology scales up when there’s a wider range of inputs.
This analysis was supported, partly, by the MIT-IBM Watson AI Lab and its member firms, Nexplore and Woodside, and by the MIT Lincoln Laboratory.
[ad_2]

