



[ad_1]
I cherished my first automobile, a 1970’s-era Mini Cooper, however from my perspective at the moment as a software program engineer, I do know that from each an observability and monitoring perspective, it was a catastrophe.
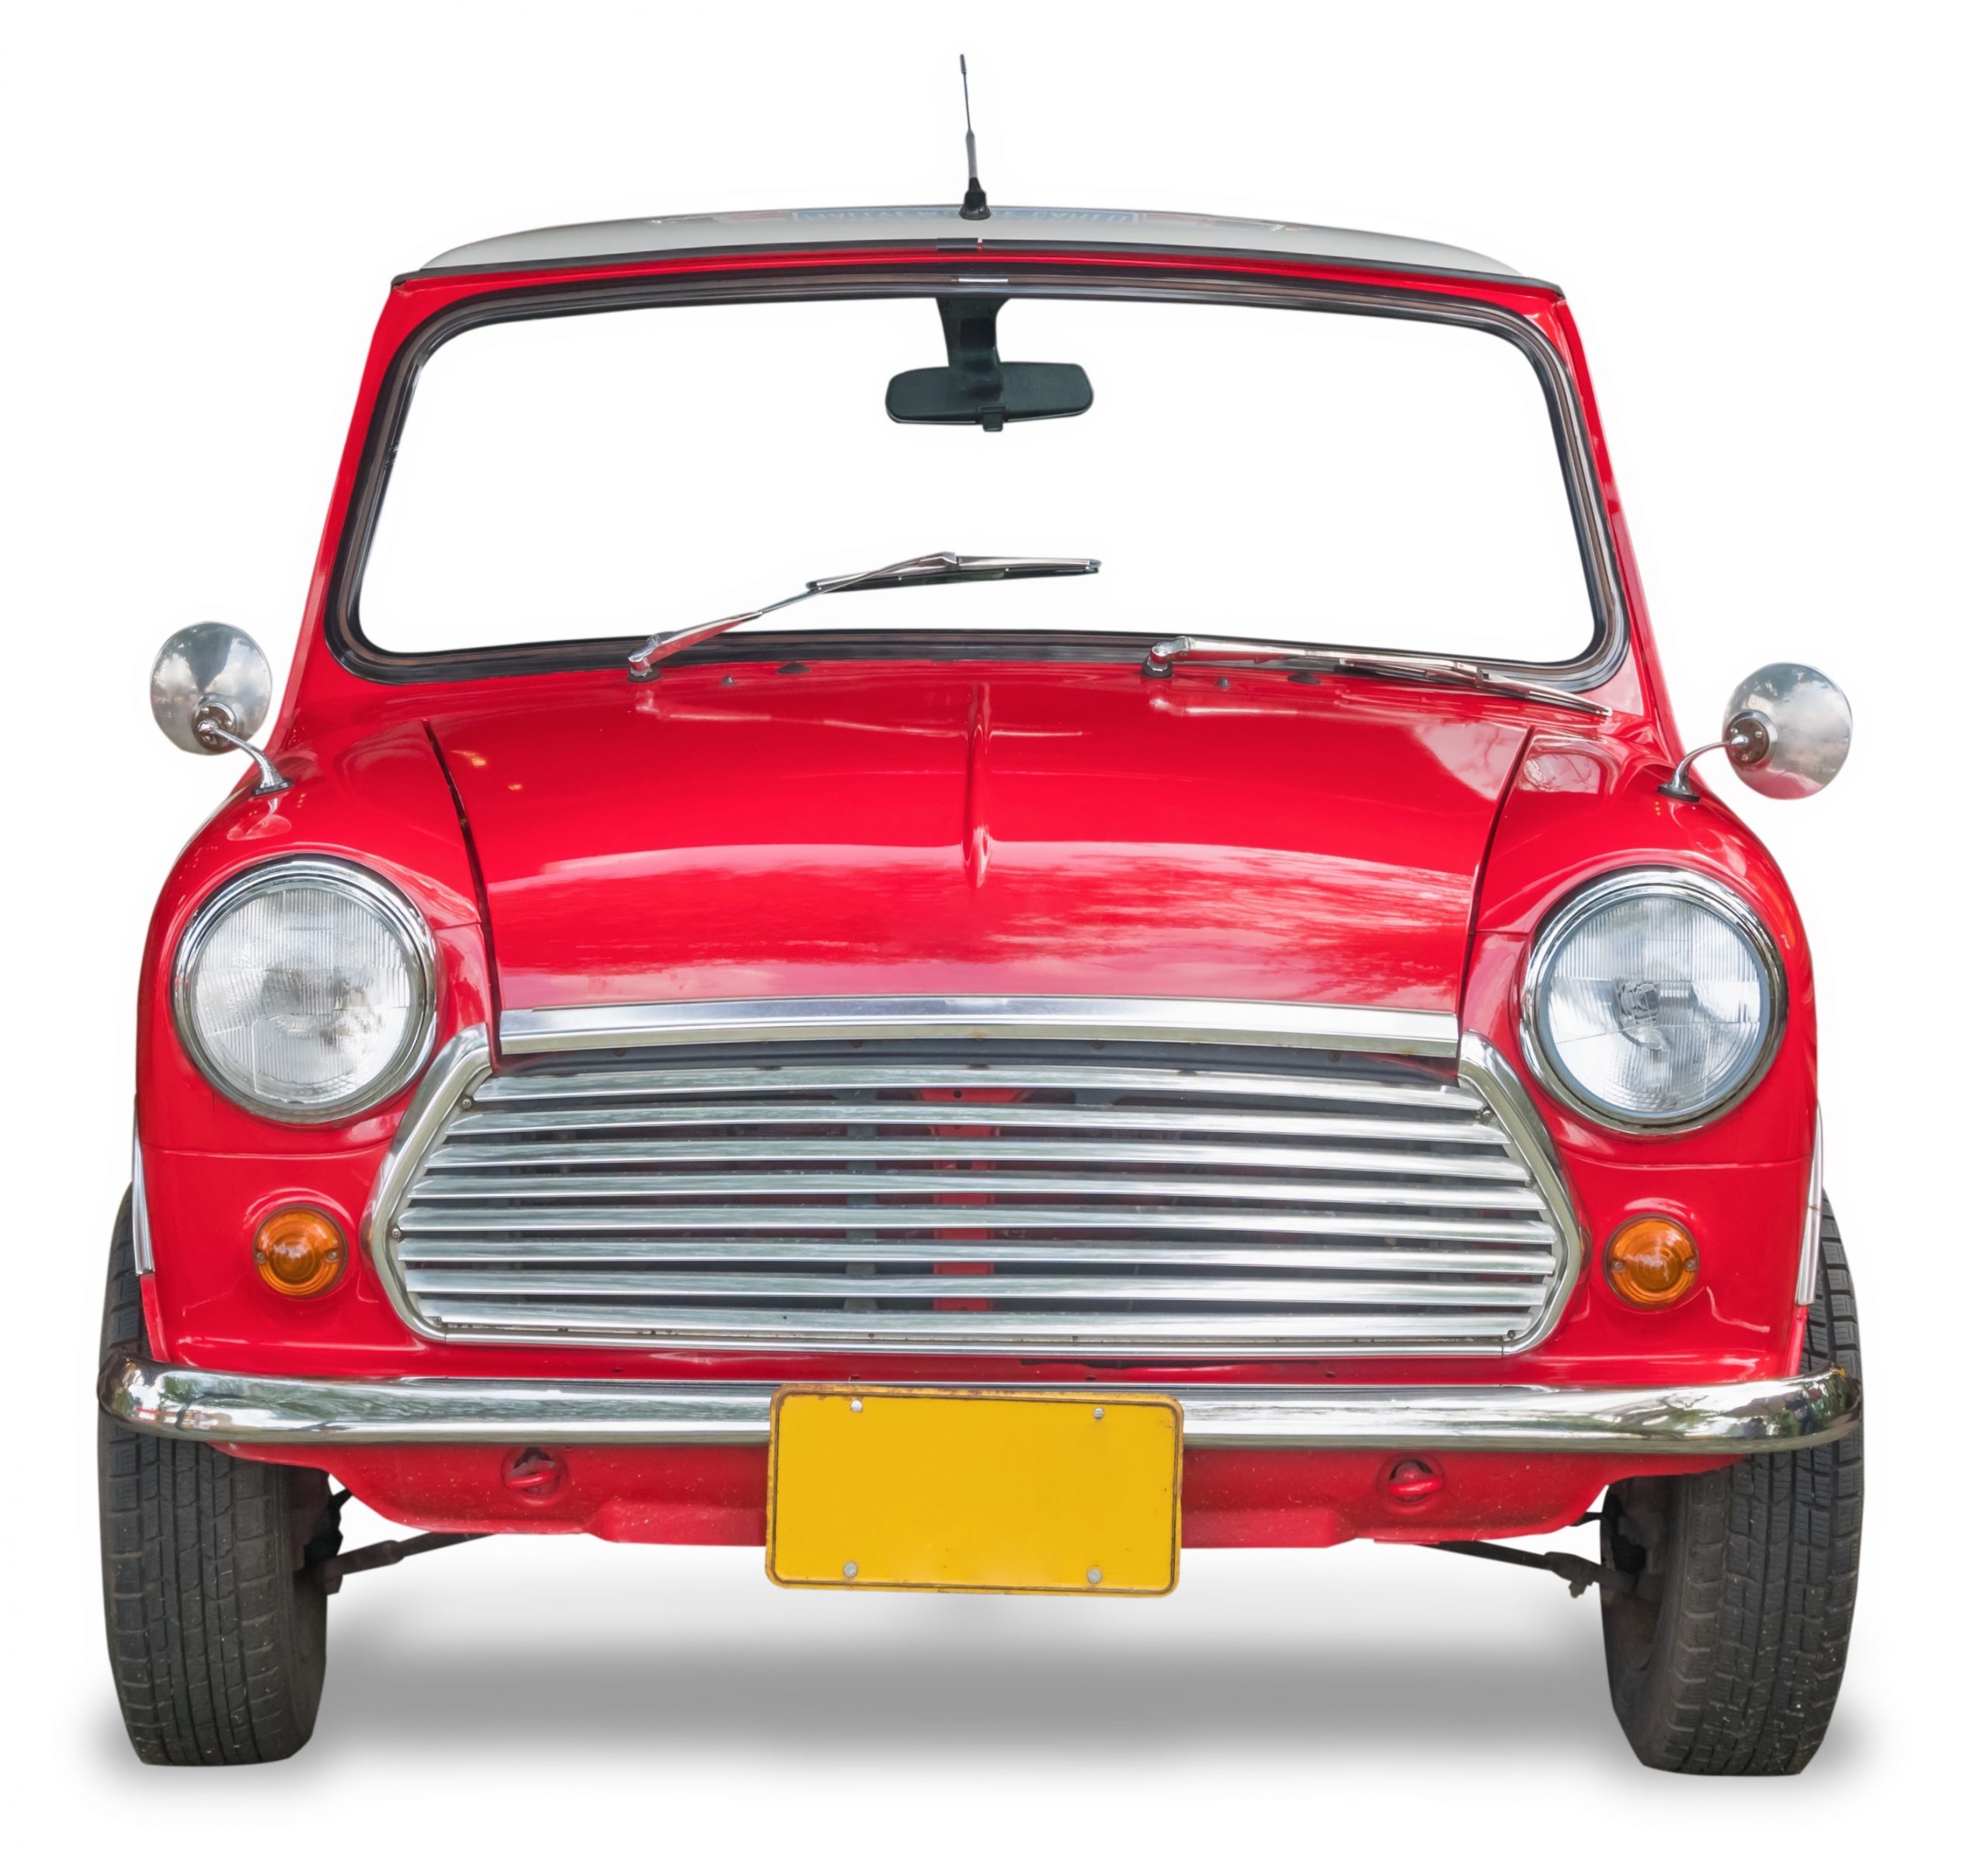
We will’t drive fashionable IT methods with out each observability and monitoring, not until we like being stunned when our methods fail.
Thankfully for drivers, fashionable vehicles have higher monitoring instruments than they did in 1970. Even the dreaded “test engine” mild, which my 1970-era Mini Cooper lacked, gives helpful info to the tip consumer. In my outdated Mini you solely knew one thing was improper with the engine while you discovered your self coasting to the facet of the street with out energy.
Clearly, for those who’re engaged on an enterprise utility or service, the equal lack of service – shock downtime or degradation – can have severe penalties.
A automobile laptop that has the test engine output mild for monitoring works by observing the state of assorted methods the car. In different phrases, monitoring is what you do after a system is observable. With out some stage of observability, monitoring is just about unattainable.
We’d like each monitoring and observability within the devOps world – much more than in vintage Minis. Let’s take a look at these two ideas in additional element.
Monitoring
Monitoring may be reactive, which isn’t all the time a foul factor. Normally, monitoring methods on networks and SaaS merchandise present an alert by way of a software program element which manages units. These methods preserve the information for the merchandise and report, as wanted, to different managing methods. The element offered helps engineering groups cut back restore time when an incident occurred.
Along with answering the query, “what’s damaged, and why?, ” monitoring can present what element utilization seems like. Monitoring can present an excessive amount of perception into the well being of networks, apps and methods. It’s additionally an amazing useful resource for taking a look at historic knowledge.
Nevertheless, monitoring by itself won’t nonetheless forestall failure or downtime.
Conventional monitoring options do have a job to play for a lot of environments, however they provide solely restricted, siloed visibility throughout distributed functions that impression the general digital expertise. For instance, there may be restricted visibility for utility companies, networks, infrastructure, clouds, databases, and logs. Sometimes, the restricted view from monitoring methods is insufficient for managing companies in cloud native architectures.
Observability
The idea of observability originates from management principle. It refers back to the diploma to which the inner situation of a fancy system may be understood if you already know simply its outputs. In line with the idea, the upper the diploma of observability, the simpler it’s to seek out and subject’s trigger after which resolve the issue. Observability differs from area monitoring by enabling customers to trace a number of processes throughout advanced working environments as an observability instruments can determine the components that contribute to issues occurring inside a distributed system, making them simpler to resolve.
Essentially the most complete options present full-stack observability to offer acquire perception into potential issues throughout a complete array of functions and infrastructure.
Observability instruments accumulate and analyze a broad spectrum of knowledge, together with utility well being and efficiency, enterprise metrics like conversion charges, consumer expertise mapping, and infrastructure and community telemetry — to resolve points earlier than they impression enterprise KPIs.
The three pillars of observability
Observability is broen down into three essential elements:
- Metrics are numerical representations of knowledge that can be utilized to find out a service or element’s total habits over time, for instance how a lot of the whole quantity of reminiscence is utilized by a way, or what number of requests a service handles per second, system uptime, response time and the way a lot processing energy an utility is utilizing, for instance. Engineering groups and ops engineers use metrics to set off alerts each time a system worth goes above a specified threshold.
- Logs are structured and unstructured traces of textual content a system produces when sure processes run (or fail). Most utility frameworks, libraries, and languages include assist for logging. Log information can present complete system particulars, equivalent to a fault, and the particular time when the fault occurred. By analyzing the logs, you’ll be able to troubleshoot code and determine the place (and typically why) an error occurred.
- A Hint represents your complete journey of a request or motion because it strikes by way of all of the nodes of a system. Traces permit you to profile and observe methods, particularly containerized functions, serverless architectures, or microservices structure. Traces permit you to get into the small print of requests to find out which elements trigger system errors, monitor move by way of modules, and discover efficiency bottlenecks. Traces are a key pillar of observability as a result of they’ll present context for the opposite elements of observability.
Instruments for observability
You can not repair what you can’t see, and the extra you see, the extra you resolve.
To handle distributed system infrastructures, arrange a devoted set of instruments to visualise your operational states and alert engineer groups when a failure happens. Irrespective of how fastidiously you construct a system, there’ll all the time be one thing that may go improper. Cisco has a number of full-stack observability architectures to assist remodel your operations at the moment, and there are integrations throughout instruments, together with AppDynamics, Cisco ThousandEyes, Cisco Intersight, and Cisco Safe Utility.
- AppDynamics Permits builders to construct higher internet and cell functions with deep efficiency visibility in check, pre-production, and manufacturing environments.
- ThousandEyes integrations allow utility efficiency to be correlated to the community elements that connects customers and companies.
- Utility efficiency integrations with Cisco Intersight gives full-stack visibility and multicloud useful resource administration, from bare-metal servers, hypervisors, to Kubernetes clusters, serverless and functions elements..
Observability options like these might help groups transfer past siloed area monitoring to realize insights that may result in insights and motion. Full-stack observability options allow supply of unmatched utility experiences and streamlined operations. By centralizing and correlating utility efficiency analytics throughout the complete stack, groups can higher collaborate to isolate points and optimize utility experiences.
Full-stack observability and enterprise telemetry offers us the ability to prioritize actions and ship flawless experiences that drive income streams — whereas accelerating digital transformation.
We’d love to listen to what you assume. Ask a query or go away a remark under.
And keep related with Cisco DevNet on social!
LinkedIn | Twitter @CiscoDevNet | Fb | Developer Video Channel
Share:
[ad_2]

