


[ad_1]
Whereas the skilled VFX group is intrigued – and sometimes feels just a little threatened – by new improvements in picture and video synthesis, the dearth of temporal continuity in most AI-based video enhancing tasks relegates many of those efforts to the ‘psychedelic’ sphere, with shimmering and quickly altering textures and constructions, inconsistent results and the sort of crude technology-wrangling that recollects the photochemical period of visible results.
If you wish to change one thing very particular in a video that doesn’t fall into the realm of deepfakes (i.e., imposing a brand new identification on present footage of an individual), a lot of the present options function below fairly extreme limitations, by way of the precision required for production-quality visible results.
One exception is the continuing work of a free affiliation of teachers from the Weizmann Institute of Science. In 2021, three of its researchers, in affiliation with Adobe, introduced a novel methodology for decomposing video and superimposing a constant inside mapping – a layered neural atlas – right into a composited output, full with alpha channels and temporally cohesive output.
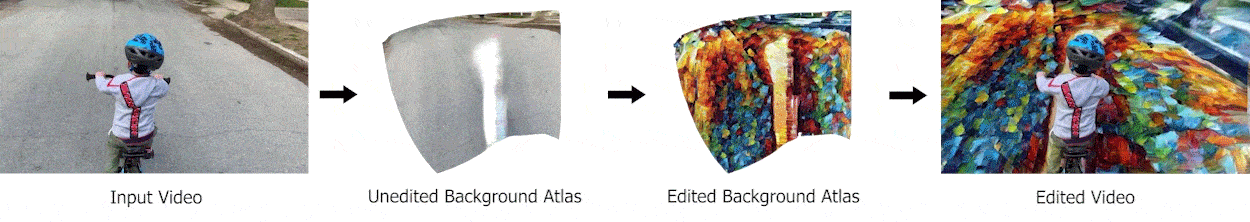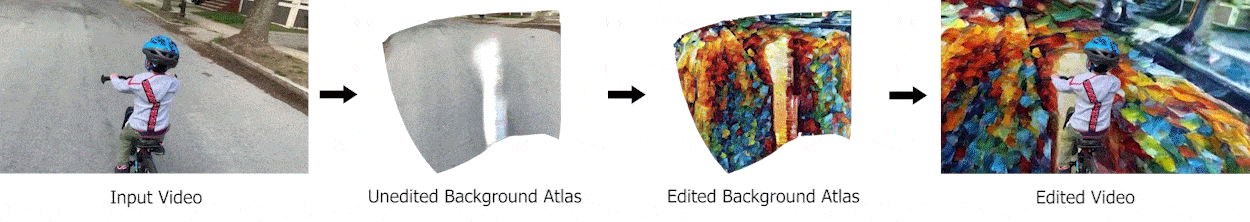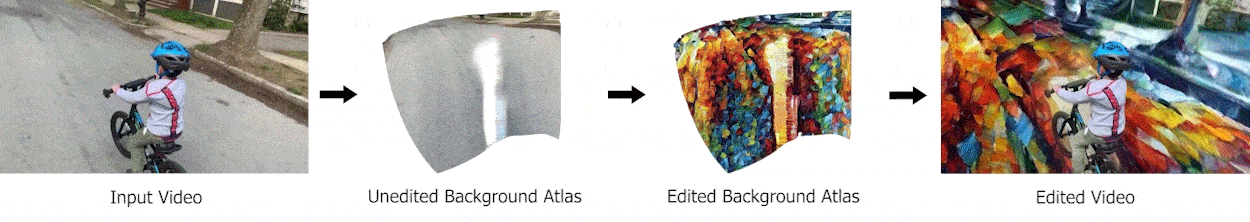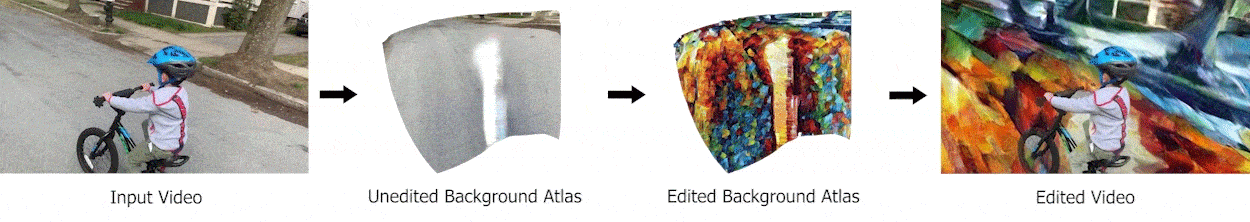
From the 2021 paper: an estimation of the whole traversal of the highway within the supply clip is edited through a neural community in a fashion which historically would require intensive rotoscoping and match-moving. For the reason that background and foreground parts are dealt with by totally different networks, masks are really ‘computerized’. Supply: https://layered-neural-atlases.github.io/
Although it falls someplace into the realm lined by optical movement in VFX pipelines, the layered atlas has no direct equal in conventional CGI workflows, because it primarily constitutes a ‘temporal texture map’ that may be produced and edited by conventional software program strategies. Within the second picture within the illustration above, the background of the highway floor is represented (figuratively) throughout the complete runtime of the video. Altering that base picture (third picture from left within the illustration above) produces a constant change within the background.
The photographs of the ‘unfolded’ atlas above solely symbolize particular person interpreted frames; constant modifications in any goal video body are mapped again to the unique body, retaining any essential occlusions and different requisite scene results, equivalent to shadows or reflections.
The core structure makes use of a Multilayer Perceptron (MLP) to symbolize the unfolded atlases, alpha channels and mappings, all of that are optimized in live performance, and fully in a 2D area, obviating NeRF-style prior data of 3D geometry factors, depth maps, and related CGI-style trappings.
The reference atlas of particular person objects may also be reliably altered:
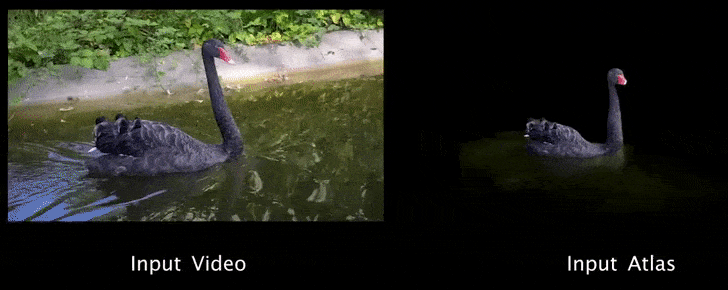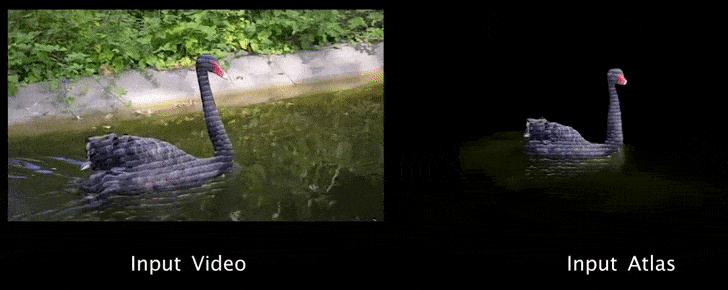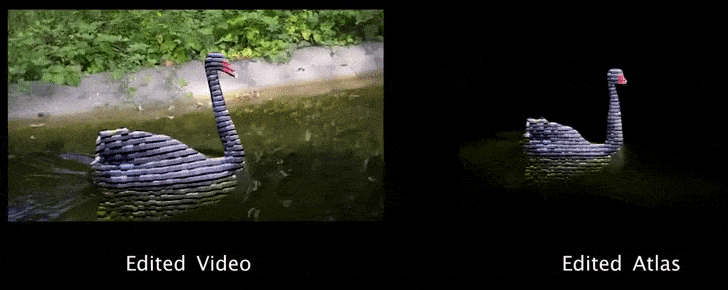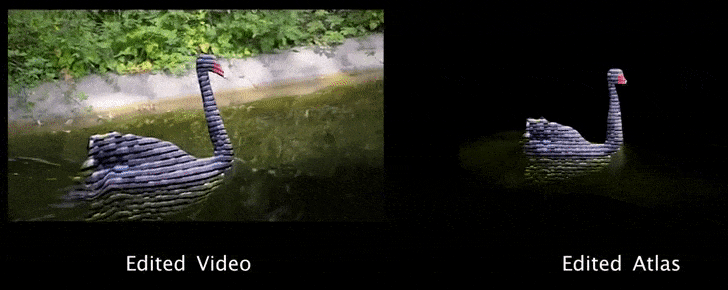
Constant change to a shifting object below the 2021 framework. Supply: https://www.youtube.com/watch?v=aQhakPFC4oQ
Basically the 2021 system combines geometry alignment, match-moving, mapping, re-texturizing and rotoscoping right into a discrete neural course of.
Text2Live
The three authentic researchers of the 2021 paper, along with NVIDIA analysis, are among the many contributors to a brand new innovation on the approach that mixes the facility of layered atlases with the sort of text-guided CLIP expertise that has come again to prominence this week with OpenAI’s launch of the DALL-E 2 framework.
The brand new structure, titled Text2Live, permits an finish consumer to create localized edits to precise video content material primarily based on textual content prompts:
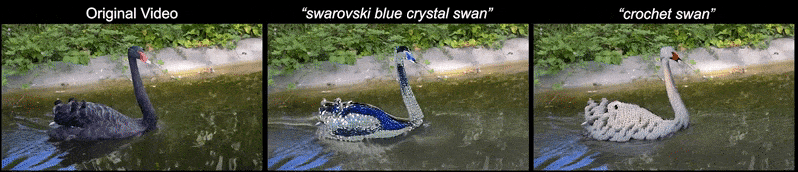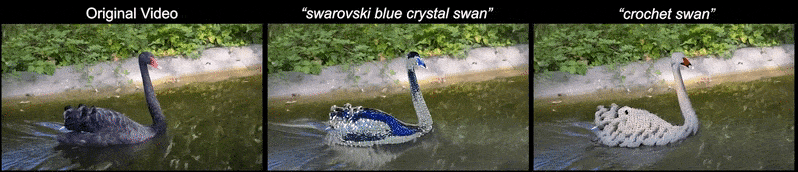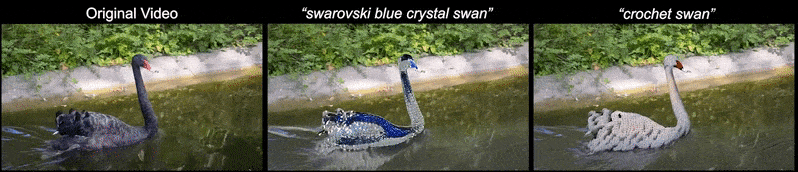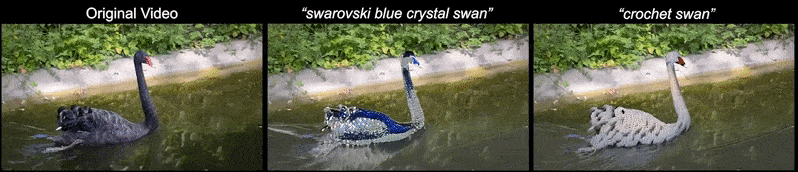
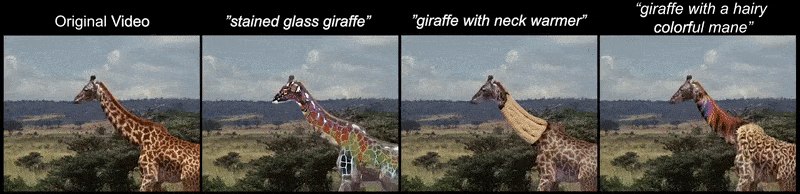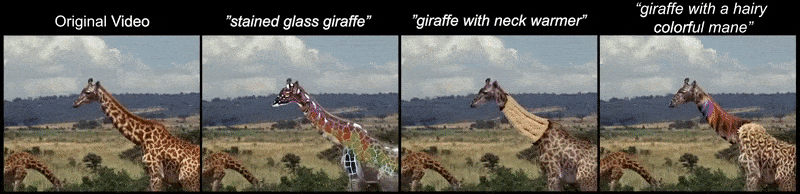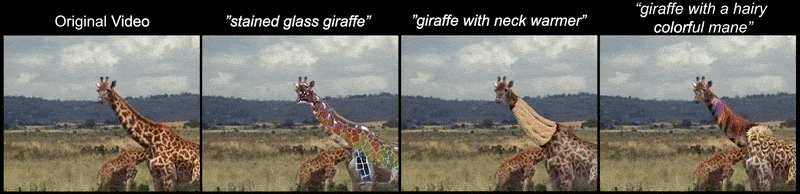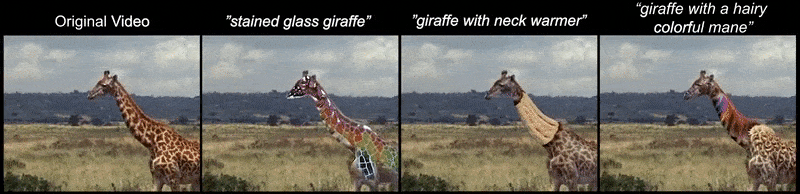
Two examples of foreground enhancing. For higher decision and definition, try the unique movies at https://text2live.github.io/sm/pages/video_results_atlases.html
Text2Live presents semantic and extremely localized enhancing with out using a pre-trained generator, by making use of an inside database that’s particular to the video clip being affected.

Background and foreground (object) transformations below Text2Live. Supply: https://text2live.github.io/sm/pages/video_results_atlases.html
The approach doesn’t require user-provided masks, equivalent to a typical rotoscoping or green-screen workflow, however quite estimates relevancy maps by a bootstrapping approach primarily based on 2021 analysis from The College of Laptop Science at Tel Aviv College and Fb AI Analysis (FAIR).

Output maps generated through a transformer-based generic consideration mannequin.
The brand new paper is titled Text2LIVE: Textual content-Pushed Layered Picture and Video Enhancing. The unique 2021 group is joined by Weizmann’s Omer Bar-Tal, and Yoni Kasten of NVIDIA Analysis.
Structure
Text2Live contains a generator educated on a sole enter picture and goal textual content prompts. A Contrastive Language-Picture Pretraining (CLIP) mannequin pre-trained on 400 million textual content/picture pairs offers related visible materials from which user-input transformations may be interpreted.


The generator accepts an enter picture (body) and outputs a goal RGBA layer containing colour and opacity data. This layer is then composited into the unique footage with extra augmentations.

The alpha channel within the generated RGBA layer offers an inside compositing operate with out recourse to conventional pipelines involving pixel-based software program equivalent to After Results.
By coaching on inside pictures related to the goal video or picture, Text2Live avoids the requirement both to invert the enter picture into the latent area of a Generative Adversarial Community (GAN), a observe which is at present removed from precise sufficient for manufacturing video enhancing necessities, or else use a Diffusion mannequin that’s extra exact and configurable, however can’t keep constancy to the goal video.

Sundry prompt-based transformation edits from Text2Live.
Prior approaches have both used propagation-based strategies or optical flow-based approaches. Since these methods are to some or different extent frame-based, neither is able to making a constant temporal look of modifications in output video. A neural layered atlas, as an alternative, offers a single area wherein to handle modifications, which may then stay devoted to the dedicated change because the video progresses.
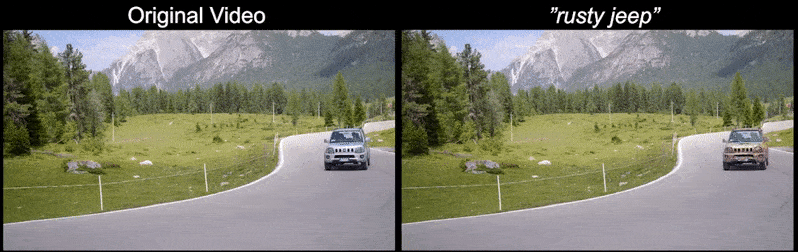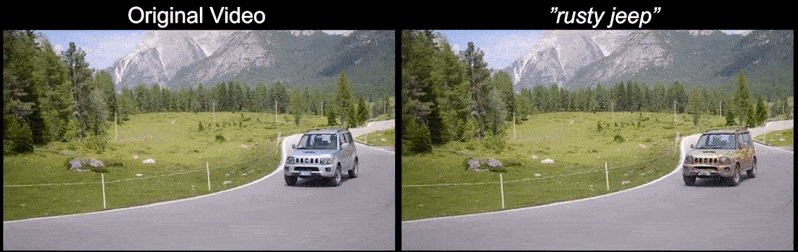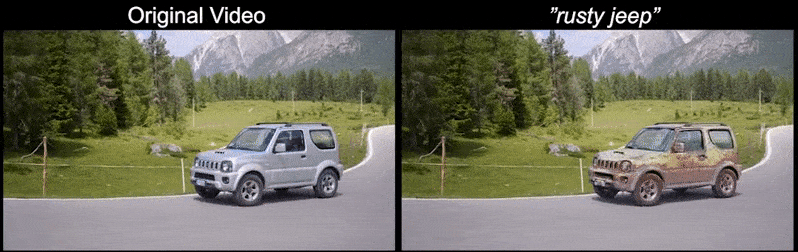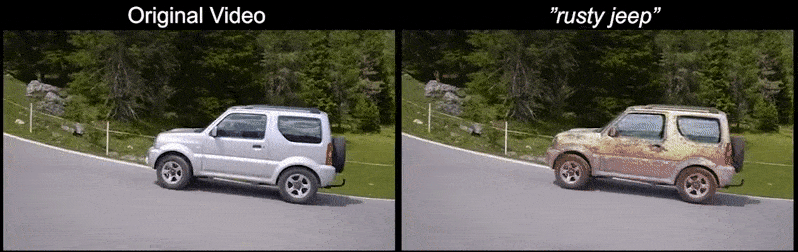
No ‘scorching’ or random hallucinations: Text2Live obtains an interpretation of the textual content immediate ‘rusty jeep’, and applies it as soon as to the neural layered atlas of the automobile within the video, as an alternative of restarting the transformation for every interpreted body.

Workflow of Text2Live’s constant transformation of a Jeep right into a rusty relic.
Text2Live is nearer to a breakthrough in AI-based compositing, quite than within the fertile text-to-image area which has attracted a lot consideration this week with the discharge of the second era of OpenAI’s DALL-E framework (which may incorporate goal pictures as a part of the transformative course of, however stays restricted in its capacity to immediately intervene in a photograph, along with the censoring of supply coaching information and imposition of filters, designed to stop consumer abuse).
Relatively, Text2Live permits the tip consumer to extract an atlas after which edit it in a single cross in high-control pixel-based environments equivalent to Photoshop (and arguably much more summary picture synthesis frameworks equivalent to NeRF), earlier than feeding it again right into a correctly-oriented setting that nonetheless doesn’t depend on 3D estimation or backwards-looking CGI-based approaches.
Moreover, Text2Live, the authors declare, is the primary comparable framework to realize masking and compositing in a completely computerized method.
First printed seventh April 2022.
[ad_2]

