



[ad_1]
Not all deepfake practitioners share the identical goal: the impetus of the picture synthesis analysis sector – backed by influential proponents similar to Adobe, NVIDIA and Fb – is to advance the state-of-the-art in order that machine studying strategies can ultimately recreate or synthesize human exercise at excessive decision and beneath probably the most difficult circumstances (constancy).
Against this, the target of those that want to use deepfake applied sciences to unfold disinformation is to create believable simulations of actual folks by many different strategies than the mere veracity of deepfaked faces. On this state of affairs, adjunct elements similar to context and plausibility are nearly equal to a video’s potential to simulate faces (realism).
This ‘sleight-of-hand’ method extends to the degradation of ultimate picture high quality of a deepfake video, in order that all the video (and never simply the misleading portion represented by a deepfaked face) has a cohesive ‘look’ that’s correct to the anticipated high quality for the medium.
‘Cohesive’ doesn’t need to imply ‘good’ – it’s sufficient that the standard is constant throughout the unique and the inserted, adulterated content material, and adheres to expectations. When it comes to VOIP streaming output on platforms similar to Skype and Zoom, the bar may be remarkably low, with stuttering, jerky video, and an entire vary of potential compression artifacts, in addition to ‘smoothing’ algorithms designed to scale back their results – which in themselves represent a further vary of ‘inauthentic’ results that we now have accepted as corollaries to the constraints and eccentricities of stay streaming.
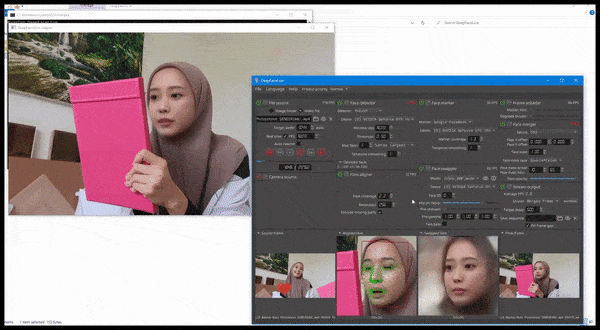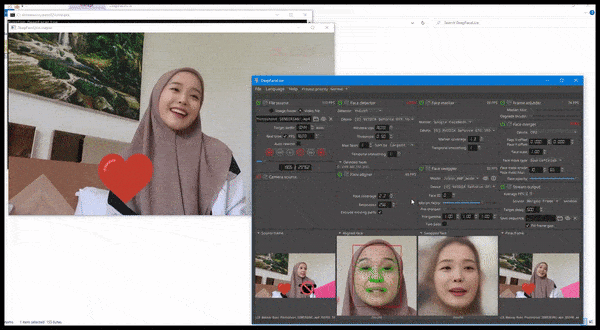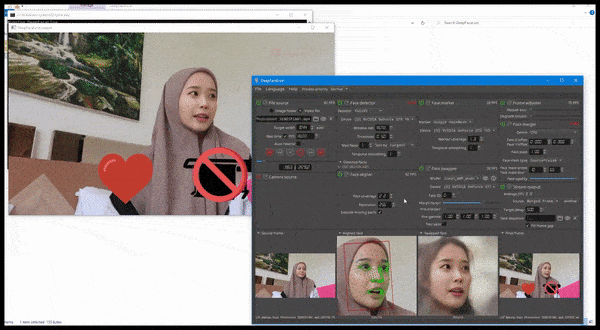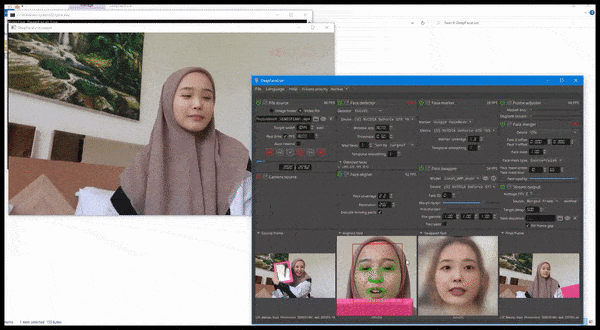
DeepFaceLive in motion: this streaming model of premier deepfake software program DeepFaceLab can present contextual realism by presenting fakes within the context of restricted video high quality, full with playback points and different recurrent connection artifacts. Supply: https://www.youtube.com/watch?v=IL517EgYH8U
Constructed-In Degradation
Certainly, the 2 hottest deepfake packages (each derived from the controversial 2017 supply code) comprise parts meant to combine the deepfaked face into the context of ‘historic’ or lower-quality video by degrading the generated face. In DeepFaceLab, the bicubic_degrade_power parameter accomplishes this, and in FaceSwap, the ‘grain’ setting within the Ffmpeg configuration likewise helps integration of the false face.

The ‘grain’ setting in FaceSwap aids genuine integration into non-HQ video content material, and legacy content material that will function movie grain results which are comparatively uncommon nowadays.
Usually, as a substitute of a whole and built-in deepfake video, deepfakers will output an remoted collection of PNG recordsdata with alpha channels, every picture displaying solely the artificial face output, in order that the picture stream may be transformed into video in platforms with extra subtle ‘degrading’ results capabilities, similar to Adobe After Results, earlier than the pretend and actual parts are joined collectively for the ultimate video.
Moreover these intentional degradations, the content material of deepfake work is often recompressed, both algorithmically (the place social media platforms search to avoid wasting bandwidth by producing lighter variations of customers’ uploads) in platforms similar to YouTube and Fb, or by reprocessing of the unique work into animated GIFs, element sections, or different diversely motivated workflows that deal with the unique launch as a place to begin, and subsequently introduce further compression.
Real looking Deepfake Detection Contexts
With this in thoughts, a brand new paper from Switzerland has proposed a revamping of the methodology behind deepfake detection approaches, by instructing detection programs to study the traits of deepfake content material when it’s introduced in intentionally degraded contexts.

Stochastic knowledge augmentation utilized to one of many datasets used within the new paper, that includes Gaussian noise, gamma correction, and Gaussian blur, in addition to artifacts from JPEG compression. Supply: https://arxiv.org/pdf/2203.11807.pdf
Within the new paper, the researchers argue that vanguard deepfake detection packages are counting on unrealistic benchmark circumstances for the context of the metrics that they apply, and that ‘degraded’ deepfake output can fall under the minimal high quality threshold for detection, though their realistically ‘grungy’ content material is more likely to deceive viewers as a consequence of an accurate consideration to context.
The researchers have instituted a novel ‘actual world’ knowledge degradation course of that succeeds in enhancing the generalizability of main deepfake detectors, with solely marginal lack of accuracy on the unique detection charges obtained by ‘clear’ knowledge. In addition they provide a brand new evaluation framework that may consider the robustness of deepfake detectors in actual world circumstances, supported by in depth ablation research.
The paper is titled A New Method to Enhance Studying-based Deepfake Detection in Real looking Circumstances, and comes from researchers on the Multimedia Sign Processing Group (MMSPG) and the Ecole Polytechnique Federale de Lausanne (EPFL), each primarily based in Lausanne.
Helpful Confusion
Prior efforts to include degraded output into deepfake detection approaches embrace the Mixup neural community, a 2018 providing from MIT and FAIR, and AugMix, a 2020 collaboration between DeepMind and Google, each knowledge augmentation strategies that try and ‘muddy’ the coaching materials in a manner that’s inclined to assist generalization.
The researchers of the brand new work additionally observe prior research that utilized Gaussian noise and compression artifacts to coaching knowledge to be able to set up the boundaries of the connection between a derived function and the noise wherein it’s embedded.
The brand new research affords a pipeline that simulates the compromised circumstances of each the acquisition course of for imaging and the compression and various different algorithms that may additional degrade picture output within the distribution course of. By incorporating this real-world workflow into an evaluative framework, it’s doable to provide coaching knowledge for deepfake detectors that’s extra proof against artifacts.

The conceptual logic and workflow for the brand new method.
The degradation course of was utilized to 2 fashionable and profitable datasets used for deepfake detection: FaceForensics++ and Celeb-DFv2. Moreover, main deepfake detector frameworks Capsule-Forensics and XceptionNet have been skilled on the adulterated variations of the 2 datasets.
The detectors have been skilled with the Adam optimizer for 25 and 10 epochs respectively. For the dataset transformation, 100 frames have been randomly sampled from every coaching video, with 32 frames extracted for testing, previous to the addition of degrading processes.
The distortions thought-about for the workflow have been noise, the place zero-mean Gaussian noise was utilized at six various ranges; resizing, to simulate the diminished decision of typical outside footage, which might usually have an effect on detectors; compression, the place diverse JPEG compression ranges have been utilized throughout the info; smoothing, the place three typical smoothing filters utilized in ‘denoising’ are evaluated for the framework; enhancement, the place distinction and brightness have been adjusted; and mixtures, the place any mixture of three of the aforementioned strategies have been concurrently utilized to a single picture.
Testing and Outcomes
In testing the info, the researchers adopted three metrics: Accuracy (ACC); Space Beneath Receiver Working Attribute Curve (AUC); and F1-score.
The researchers examined the standard-trained variations of the 2 deepfake detectors towards the adulterated knowledge, and located them missing:
‘Normally, most of lifelike distortions and processing are exceedingly dangerous to usually skilled learning-based deepfake detectors. For example, Capsule-Forensics methodology exhibits very excessive AUC scores on each uncompressed FFpp and Celeb-DFv2 take a look at set after coaching on respective datasets, however then suffers from drastic efficiency drop on modified knowledge from our evaluation framework. Comparable developments have been noticed with the XceptionNet detector.’
Against this, the efficiency of the 2 detectors was notably improved by being skilled on the reworked knowledge, with every detector now extra able to detecting unseen misleading media.
‘The info augmentation scheme considerably improves the robustness of the 2 detectors and in the meantime they nonetheless preserve excessive efficiency on authentic unaltered knowledge.’

Efficiency comparisons between the uncooked and augmented datasets used throughout the 2 deepfake detectors evaluated within the research.
The paper concludes:
‘Present detection strategies are designed to realize as excessive efficiency as doable on particular benchmarks. This typically ends in sacrificing generalization means to extra lifelike situations. On this paper, a rigorously conceived knowledge augmentation scheme primarily based on pure picture degradation course of is proposed.
‘In depth experiments present that the easy however efficient method considerably improves the mannequin robustness towards numerous lifelike distortions and processing operations in typical imaging workflows.’
First printed twenty ninth March 2022.
[ad_2]

