



[ad_1]
You have got most likely heard in regards to the previous adage “Correlation doesn’t suggest causation”. This concept that one can not deduce a causal relationship between two occasions merely as a result of they happen in affiliation has a cool latin title: cum hoc ergo propter hoc (“with this, subsequently due to this”), which hints at the truth that this adage is even older than you would possibly suppose.
What most individuals don’t know is that each one the cool deep studying algorithms on the market really fall prey to this fallacy. Irrespective of how fancy they’re, these algorithms merely depend on affiliation, however they don’t have any frequent sense (which will be considered some form of causal mannequin of the world).
On this article, we are going to discover a number of key concepts across the subjects of correlation and causality, and extra importantly, why it is best to care about this and the way automation may also help us on this regard!
Correlation by probability
If you are interested in information analytics or statistics, you have got most likely come throughout the idea of spurious correlations. This time period has been coined by the well-known statistician Karl Pearson within the late nineteenth century, however has been lately popularized by the Spurious Correlations web site (and guide) by Tyler Vigen, which presents many examples resembling this one:
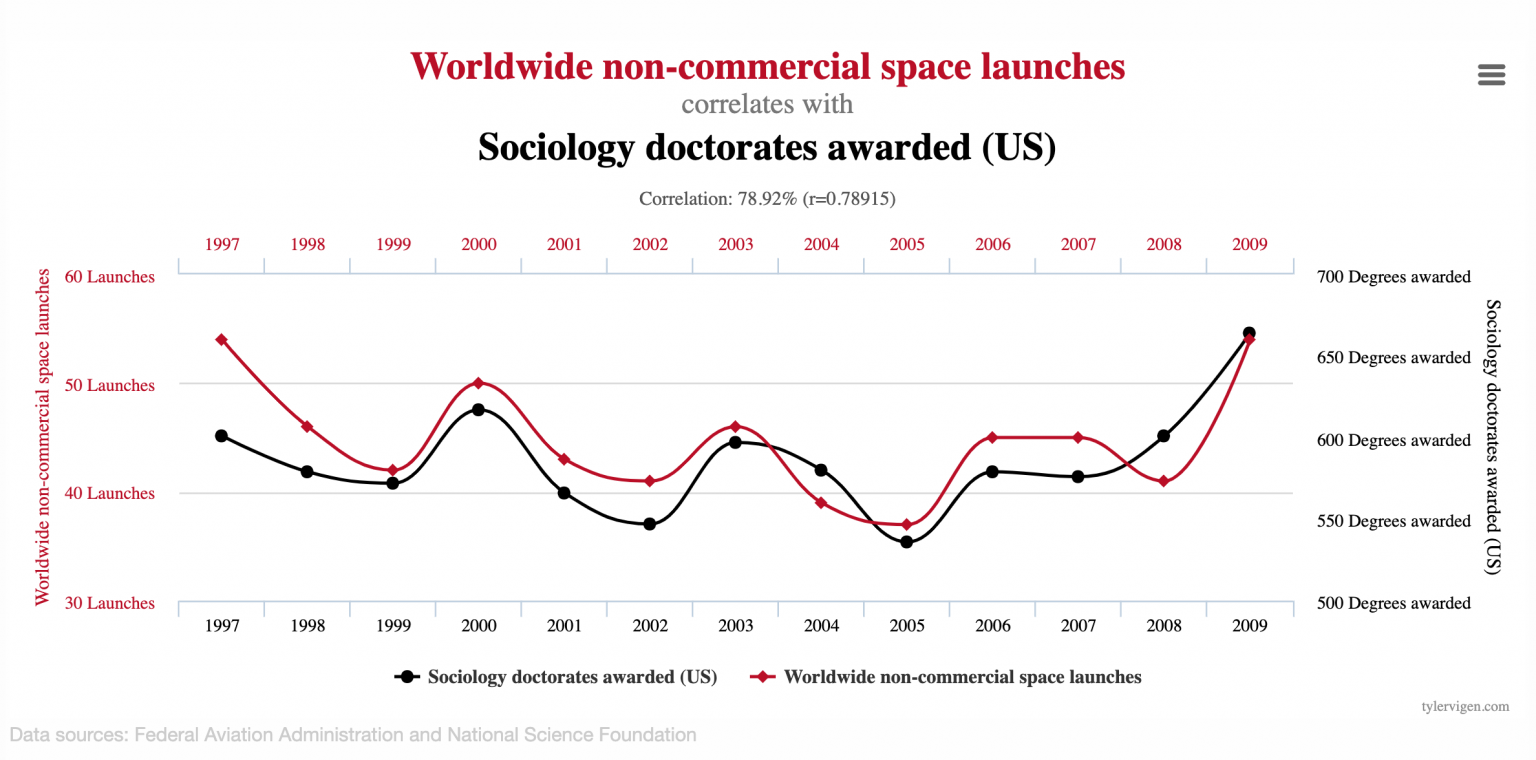
Right here we observe that the variety of non-commercial house launches on this planet occurs to match nearly completely the variety of sociology doctorates awarded within the US yearly (when it comes to relative variation, not in absolute worth). These examples are after all meant as jokes, and this makes us chuckle as a result of it goes in opposition to frequent sense. There isn’t any connection between house launches and sociology doctorates, so it’s fairly clear that one thing is incorrect right here.
Now, examples resembling this one will not be precisely what Karl Pearson had in thoughts when he coined the time period, as a result of they’re the results of probability moderately than a standard trigger. As an alternative, we’re coping with an issue of statistical significance: though the correlation coefficient is sort of 79%, that is primarily based solely on 13 information factors for every collection, which makes the opportunity of correlation by probability very actual. Really, statisticians have designed instruments to compute the chance that two fully impartial processes (resembling house launches and sociology doctorates) produce information which have a correlation no less than as excessive as a given worth: statistical testing (by which case this chance is named a p-value).
I utilized a statistical check for the above instance (see this pocket book if you wish to check it your self and see different examples), and I obtained a p-value of 0.13%. I additionally examined this end result empirically by producing a million random time-series and counting what number of such time-series had a correlation with the variety of worldwide non-commercial house launches larger than 78.9%. No surprises right here, I get roughly 0.13% of my trials falling in that class. This summarized on this determine:

One necessary lesson right here is: by looking lengthy sufficient in a big dataset, you’ll all the time discover some examples of properly correlated examples. Certainly not it is best to conclude that there’s some precise relation between them, not to mention some causation!
Correlation on account of frequent causes
Now, you will be in a state of affairs the place not solely the correlation is excessive, however the pattern depend can also be excessive, and statistical testing will likely be of no assist (that’s, within the above instance, you’d by no means be capable to generate a random time-series extra correlated than your actual information). But, you can not conclude that you’re in presence of an actual state of affairs of causation!
As an example this truth vividly, think about the next (made up) instance that includes two processes: course of A generates a time-series and course of B generates discrete occasions. A realization of those processes is proven beneath:

We observe a scientific construct up of time-series A, adopted by an occasion B. For the sake of the illustration, allow us to assume that we now have a really massive dataset of such time-series and occasion information, they usually all look just about like my diagram. The above instance has a correlation of 27.62% and an infinitesimal p-value, which guidelines out correlation by probability. The construct up of A occurs previous to the occasion B, so it appears clear that it’s a trigger of B, proper?
However what if I advised you that A represents the variety of folks noticed on a platform in a practice station and that B corresponds to the arrival of a practice on this platform? Then all of it is sensible after all. Passengers accumulate on the platform, the practice arrives, and most passengers hop on the practice. Does that imply that the passengers trigger the practice to reach? In fact not! These processes don’t trigger one another, however they share a standard trigger: the timetable!
The subsequent submit on this collection will discover why it is best to care about spurious correlations when coping with networking telemetry, how fashionable AI fall prey to these, and why automation is essential in tackling these limitations.
Wish to obtain Analytics & Automation blogs in your inbox? Subscribe right here!
Share:
[ad_2]

